
Why Generative Video Belongs in a Real Production Workflow
Two years ago, AI video was a demo reel: a few seconds of uncanny motion that impressed people mostly because it existed at all. Today the conversation has moved on. Teams use generative video for product explainers, social cutdowns, animatics, localization, and pre-visualization, and they judge tools by whether those tools survive an actual production schedule. The interesting question is no longer "can a model make a clip?" It is "which model, prompted how, in what order, with what editing pass, produces a finished asset a client will approve?"
That shift changes how you evaluate everything. A model that produces a gorgeous four-second shot but drifts on faces across three consecutive shots is less useful than a plainer model that holds a character steady through a whole scene. A tool with dazzling photorealism that takes eleven minutes per render is fine for a hero shot and unusable for a thirty-shot sequence on a Thursday deadline. Comparison charts that rank tools purely on raw fidelity miss the point, because fidelity is one variable in a chain that also includes continuity, controllability, iteration speed, and how cleanly output drops into an edit.
This guide is a practical framework rather than a scoreboard. It covers the categories of generative video tools, the criteria that actually predict success, how major model families behave differently in practice, and a repeatable end-to-end workflow you can run on a real project.
The Four Categories of AI Video Tools
Most confusion in tool comparisons comes from lumping fundamentally different products together. Before comparing anything, sort your candidates into the category that matches your actual need.
Text-to-video generators
You type a description and receive a clip. This is the most flexible and the least controllable category. Modern engines handle camera language, lighting, and motion reasonably well, but you are always negotiating with the model: what you describe and what it renders are related, not identical. Text-to-video is strongest for b-roll, abstract sequences, mood pieces, and fast concept exploration.
Image-to-video and keyframe animation
You supply one or more still images and the model animates them. This is the workhorse category for professional work, because it splits the problem in two. You control composition, wardrobe, and framing with an image model or a photograph, then you control motion with a short prompt. It also makes style consistency far easier, since every shot can start from a frame you already approved.
Video-to-video and restyling
Existing footage is transformed: relit, restyled, upscaled, or extended. This category gets less attention than it deserves. Relighting a live-action plate, extending a shot by two seconds, or converting a rough edit into a stylized look is often more valuable than generating anything from scratch.
Avatar, lip-sync, and talking-head tools
These specialize in a presenter delivering lines, usually with voice cloning or text-to-speech. They are excellent for localization, internal training, and faceless explainer channels, and they have very different quality metrics: mouth articulation, head motion naturalness, and emotional range rather than cinematic realism.
A stack usually needs two or three of these categories, not just the flashiest one.
The Criteria That Actually Predict Success
Ranking tools by visual quality alone produces recommendations that fall apart in week two. These are the variables that matter when you are shipping.
Temporal consistency and character continuity
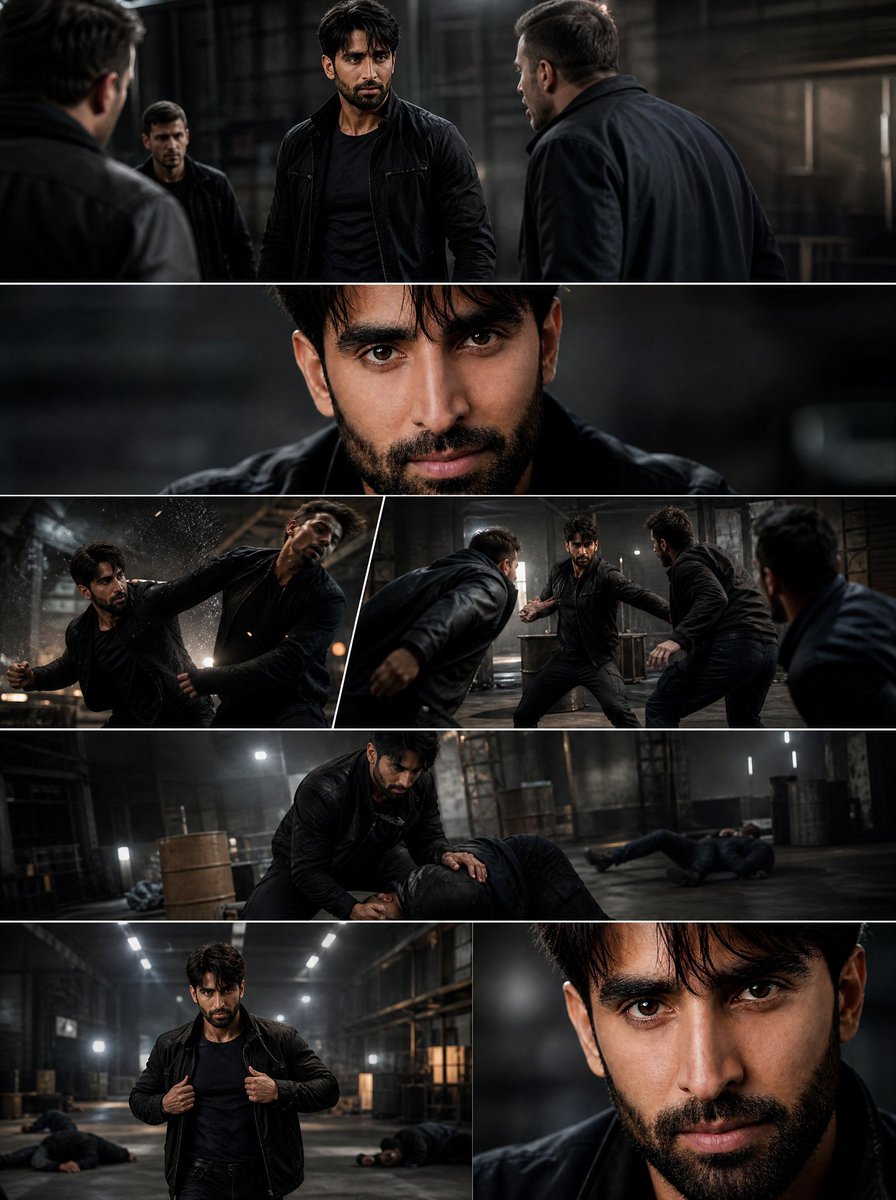
Consistency has three levels. Within a shot, does the face, clothing, and background stay stable for the full duration? Across shots, does the same character look like the same person? Across a scene, does lighting and grade stay coherent? Ask any tool you test to produce three shots of the same person in different settings. Many impressive models fail immediately at this.
Prompt adherence and controllability
A model that follows 70 percent of your instructions precisely is often more useful than one that improvises beautifully 100 percent of the time, because you can plan around known behavior. Look for support for camera directives, negative prompts, motion strength controls, seed locking, and region-specific guidance.
Duration, resolution, and aspect ratio
Native clip length matters more than people expect. If a tool gives you five-second clips, your editing rhythm will be built from five-second blocks. Consider whether you need vertical, square, and widescreen from the same source, and whether upscaling is built in or a separate step you must budget for.
Iteration speed and predictability
Time per render multiplied by average number of attempts equals your real cost per usable shot. A fast model with mediocre output can beat a slow model with excellent output on a sequence with forty shots. Track how many generations it takes to get one keeper; that ratio is the single most honest performance metric.
Post-production fit
Does the tool export clean frames, alpha channels, or depth passes? Does it preserve enough detail for color grading? Can you get a version without baked-in motion blur? Tools that ignore the edit suite create rework.
How the Major Model Families Differ in Practice
You do not need to memorize model names, but you should understand the behavior patterns, because they map to different jobs.
Cinematic realism engines
These prioritize physical plausibility: gravity, cloth, water, lens behavior, believable skin. They are the right choice for hero shots, lifestyle sequences, and anything meant to feel photographed. The tradeoff is usually latency and cost per second, plus a tendency to over-dramatize simple prompts. If you ask for "a person walking," you may get a person walking through a storm at golden hour.
Motion-first and stylized engines
These lean into animation, 2D aesthetics, exaggerated camera moves, and effects-heavy transitions. They are faster, more forgiving, and produce highly shareable results. They struggle with subtle realism, but for social content, explainers, and stylized branding that is irrelevant.
Open-weight image models feeding an animation pipeline
A large share of professional output does not come from a single video model. It comes from a strong open-weight image generator creating keyframes, which a video engine then animates. This approach gives you maximum control over composition, brand palette, and character design before a single frame moves. It also lets you build a reusable library of approved frames.
Specialist utilities
Upscalers, frame interpolators, background removers, matting tools, and audio generators fill the gaps. Budget workflow time for them, because they are frequently what separates an amateur result from a polished one.
A Repeatable End-to-End Workflow
The following sequence works for short-form social, product videos, and explainer content. Adapt timings to your project size.
Step 1: Script and beat sheet
Write the script first, in plain text, with one visual idea per line. Then convert it into a beat sheet: shot number, duration, subject, action, camera, and audio cue. This document becomes your generation checklist and your edit decision list. Skipping it is the number one cause of wasted generations.
Step 2: Storyboard and keyframes
Generate or photograph a still for every shot. Approve the frames before animating anything. Fixing composition at the still stage costs seconds; fixing it after you have animated thirty clips costs hours. Keep a character reference sheet with face, hair, wardrobe, and color palette in the same folder.
Step 3: Animate shot by shot
Animate in small batches, not one giant queue. Generate two or three variants per shot, review immediately, and note which prompt phrasing worked. Keep a prompt log: the seed, the model, the motion strength, and the result. Consistency improves fast when you can see what changed between attempts.
Step 4: Assemble the rough cut
Drop clips into your editor in beat-sheet order before you polish anything. Watch it end to end with sound off. You will immediately spot pacing problems and shots that do not earn their place. Delete ruthlessly; generative footage tempts people into overlong scenes.
Step 5: Sound design and voice
Add scratch voiceover, then music, then effects. Most perceived quality in AI video comes from audio, not pixels. A slightly soft shot with crisp sound and confident pacing reads as professional, while a pristine shot with hollow audio reads as a demo.
Step 6: Grade, finish, and export
Apply a consistent grade across all shots to unify model differences. Add grain or subtle texture if the generated look is too clean. Export separate masters for each aspect ratio rather than cropping a single file, and check captions and safe areas on mobile.
Character Consistency: The Hardest Problem
If one issue derails more AI video projects than any other, it is a character who changes face between shots. There is no magic toggle for this; consistency comes from process.
First, lock a reference: a single high-resolution image, or ideally a set of four views. Second, use image-to-video rather than text-to-video for every shot featuring that character. Third, describe the character identically in every prompt, in the same word order, and avoid adding new adjectives mid-project. Fourth, keep wardrobe and lighting similar between adjacent shots, because models resolve ambiguity by inventing detail. Fifth, if the tool supports it, use a character or subject reference feature rather than relying on text alone.
When consistency still fails, restructure the scene. Cut away to hands, over-the-shoulder angles, or environmental shots. Audiences accept far more discontinuity than editors assume, especially with a soundtrack driving attention.
Prompt Craft for Motion
Motion prompts work differently from image prompts. Images reward detail; video rewards clarity about what moves and how.
Describe motion in physical terms: "slow dolly in," "hand reaches toward the cup," "hair moves in light wind." Avoid stacking contradictory instructions such as a static camera plus sweeping movement. Specify one primary action per clip; two actions usually produce mushy results. State what should stay still when it matters, and use negative guidance for artifacts you keep seeing, like warped hands or flickering text.
Length also affects quality. Short prompts often produce cleaner motion than long poetic ones, because the model has fewer constraints to satisfy. Build a small library of prompt templates for your recurring shot types, then vary only the subject and action.
Common Mistakes and How to Fix Them
Generating before planning. Producing fifty clips and then trying to find a story wastes the main advantage of these tools. Fix: write the beat sheet first and generate against it.
Chasing maximum realism on every shot. Not every clip needs to look photographed. Mixing styles intentionally often produces a better video than a homogenized, slightly uncanny one.
Ignoring resolution mismatches. Mixing 720p generations with 4K plates creates visible softness. Fix: upscale consistently or standardize your timeline resolution to the lowest common denominator.
Over-reliance on long clips. Long generations accumulate errors. Fix: build sequences from shorter clips with deliberate cuts.
No version control. Without a naming convention, promising takes vanish into a downloads folder. Fix: name files shot-number-variant-date and archive the prompt alongside.
Skipping the audio pass. Fix: never present a cut without at least scratch audio.
Choosing a Stack: A Decision Matrix
If you need speed and volume for social, prioritize fast motion-first generation plus a template-based editor. If you need brand-safe product shots, prioritize image-to-video with a strong open-weight image model feeding it. If you need a presenter or localization, prioritize avatar and lip-sync tools with reliable voice cloning. If you need cinematic b-roll, prioritize a realism engine and accept longer render times. If you need pre-visualization for a live shoot, prioritize low-cost iteration over final quality, because the animatic only has to communicate.
Most teams end up with two generators, one image model, one upscaler, and one audio tool. Resist adding more until a specific, repeated failure demands it.
FAQ
Do I need a powerful local GPU? Only if you run open-weight models locally. Cloud generation removes hardware requirements but adds latency and ongoing spend.
How long should an AI-generated clip be? For most platforms, two to five seconds per shot, assembled into thirty to ninety-second pieces. Shorter clips give you more control.
Can I use generated video commercially? Usually yes under most providers' terms, but check each tool's license and your client's policy, and keep documentation of how assets were made.
Why does my output look plasticky? Likely over-smoothing, excessive sharpening, or a mismatch between generated and live footage. Add grain, unify the grade, and avoid mixing codecs carelessly.
How many attempts should a good shot take? Two to four with a locked keyframe and a clear prompt. If it takes fifteen, the shot is probably too complex and should be split.
What about text inside videos? Models still struggle with legible typography. Render text in your editor as an overlay instead.
What to Prepare For Next
Generative video is becoming less about spectacular single clips and more about reliable sequences, controllable characters, and integration with editing and audio pipelines. The teams that benefit most are not the ones chasing every new release, but the ones that built a workflow: a beat sheet, a keyframe library, a prompt log, a consistent naming convention, and a finishing pass that treats generated footage like any other rushes.
Start small. Pick one real deliverable, run the six-step workflow end to end, and measure how many generations each usable shot required. That number, more than any feature list, will tell you which tool deserves a place in your stack.
