
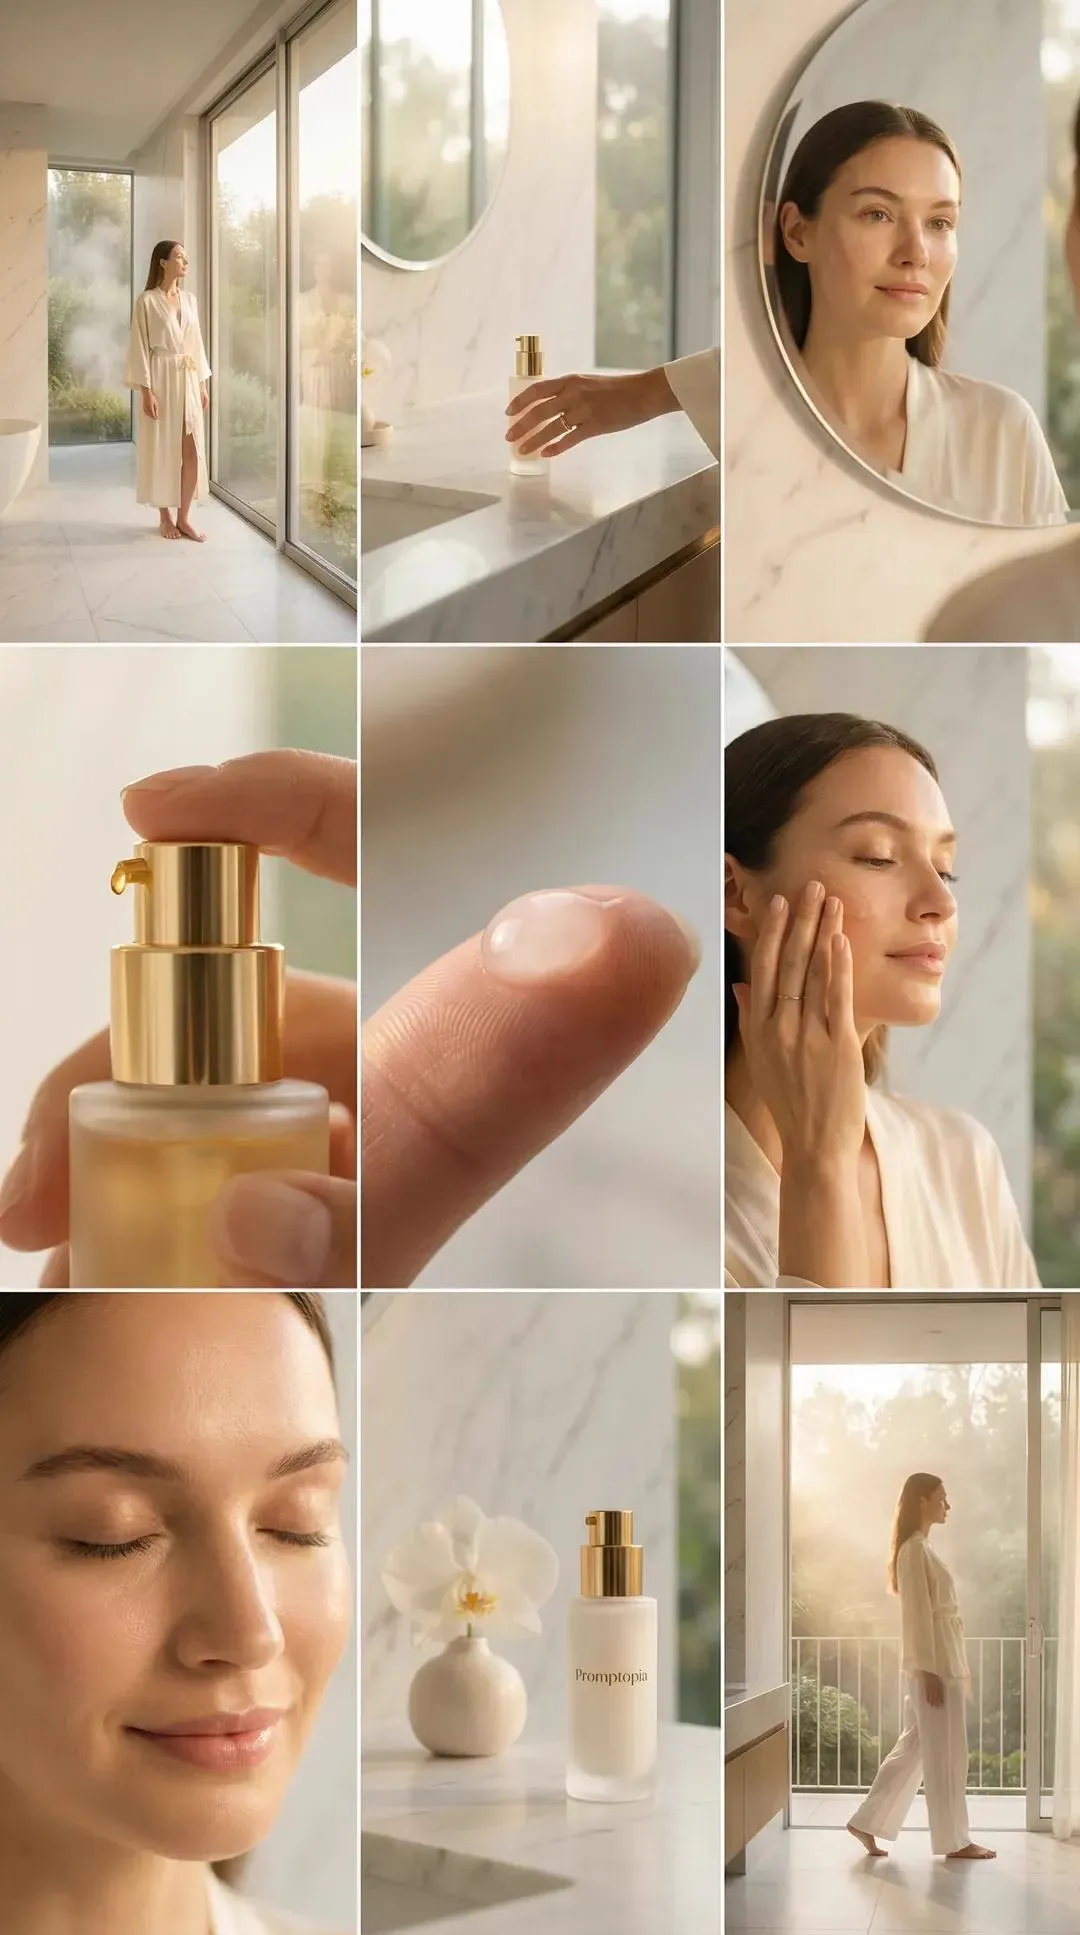
AI Video Is Now a Production Layer, Not a Novelty
A few years ago, generating a few seconds of coherent motion from a sentence felt like a magic trick you showed people at parties. Today it is closer to a utility. Text-to-video, image-to-video, and motion-transfer engines have crossed the threshold where a careful operator can produce footage that survives an edit, holds up on a phone screen, and increasingly holds up on a large display as well.
The interesting consequence is that the bottleneck has moved. Rendering is no longer the scarce resource; judgment is. The teams getting the most out of generative video are not the ones with the longest prompt libraries. They are the ones who treat the model as one department inside a normal production pipeline: script, shot list, look book, generation, consistency pass, sound, edit, grade, delivery.
That framing changes what you optimize for. If you optimize for the coolest single clip, you get a demo reel. If you optimize for footage that cuts together into a story, you get work you can publish, hand to a client, or run as a paid ad. This guide is deliberately engine-agnostic. Specific models rise and fall every few months; the workflow below survives all of them.
Pick the Model by Shot Type, Not by Hype
Every generative video engine has a personality. Some are strong at photorealistic environments but drift on faces. Some nail stylized animation but struggle with realistic skin. Some are excellent at short, punchy camera moves and fall apart past a certain duration. The practical skill is not memorizing benchmarks; it is learning to match a shot to the engine most likely to deliver it on the first three attempts.
Text-to-video, image-to-video, and video-to-video
Text-to-video is the most flexible and the least controllable. You describe a scene and accept whatever interpretation comes back. Use it for establishing shots, landscapes, abstract transitions, atmosphere, and anything where exact composition does not matter.
Image-to-video starts from a frame you already approved. This is the workhorse of narrative work, because you can lock composition, wardrobe, and lighting in a still image, then let the model add motion. If a shot needs a specific product, a specific face, or a specific logo placement, this is almost always the right entry point.
Video-to-video takes existing footage and restyles or extends it. It is the fastest route to a consistent look across shots, because the motion and framing are inherited from real footage you already trust. It is also the best way to add effects that would be expensive practically: weather, time-of-day changes, era changes, stylization.
A simple model-fit checklist
Before generating, run the shot through five questions:
- Does the shot require a specific identity? If yes, start from an image rather than a prompt.
- Does the shot require an exact camera move? Check whether the engine supports camera direction or motion strength controls. If not, consider generating a wider shot and reframing in the edit.
- Does the shot contain legible text, a logo, or a screen UI? If yes, plan to composite it in post. Generative engines still mangle typography, and fixing it in an editor is faster than re-rolling.
- How long does the shot need to be on screen? Most engines perform best in short bursts. A four-second generated clip can carry a six-second edit if you trim, slow, or cut on action.
- What happens if it fails? If a failed generation wastes an hour of your day, restructure the shot into something simpler before you start.
Pre-Production: Script, Shot List, Look Book
Generative video punishes improvising. The cost of a bad decision is not a reshoot; it is a stack of unusable renders and a loss of visual continuity. The cheapest place to solve problems is on paper.
Turning a shot list into prompts
Write the shot list first, in plain language, exactly as you would for a live-action crew. Then translate each line into a structured prompt. A reliable prompt order is: subject, action, environment, camera, lens and framing, lighting, mood, and texture reference.
For example, instead of "a woman walks through a city at night," write something closer to: "A woman in a charcoal wool coat walks toward camera through a rain-slicked side street, neon signage reflecting in puddles, medium shot at eye level, 35mm lens, shallow depth of field, cool blue key with warm practical highlights, cinematic, fine grain."
The second version tells the engine what matters: wardrobe, direction of movement, framing, light temperature, and finish. It also gives you a checklist to vary deliberately rather than accidentally.
Camera vocabulary that models actually understand
Most engines respond well to a small vocabulary: static tripod, slow push in, dolly out, crane up, orbit around subject, handheld follow, rack focus, aerial pullback, slow motion. Keep it to one or two moves per prompt. Stacking three camera instructions usually produces mush, because the model averages them into a drift.
Equally important is what to leave out. Avoid vague adjectives like "epic" or "award-winning" unless you have tested that they change output in a useful direction. They mostly consume attention that could be spent on concrete detail.
Consistency: The Hardest Problem in AI Video
Ask any working generative filmmaker what actually limits them and you will hear the same answer: keeping a character, a location, or a prop stable from shot to shot. Resolution and realism are solved problems compared with continuity.
There are five techniques that do most of the work:
Build a character sheet. Generate a set of still images of your character from multiple angles, in consistent lighting, before you animate anything. Approve one. Then drive every shot featuring that character from that approved reference, not from a fresh text prompt.
Lock the descriptive string. Decide once whether your character is described as "cropped dark hair, olive skin, silver ring on the right hand" and reuse that exact phrasing everywhere. Paraphrasing creates a new person.
Control the environment the same way. Generate wide establishing stills of each location and reuse them. If the room changes between shots, the audience reads it as a mistake even if they cannot name why.
Cut around the hard parts. If hands or profile turns are unstable, block the shot so they are off-frame or out of focus. This is not cheating; it is the same instinct that makes live-action directors use inserts and reaction shots.
Fix in the edit, not in the render. A subtle mismatch between two shots often disappears when you cut on a motion beat, add a transition, or place a close-up between them. Re-rolling twenty times to fix continuity is almost always slower than solving it in the timeline.
Sound, Dialogue, and Lip Sync
Generative video engines produce pictures. Sound is still your job, and sound is what makes an AI-generated sequence feel professional rather than synthetic. Audiences forgive imperfect motion far more readily than they forgive bad audio.
Start with ambience. Every location has a bed: room tone, traffic, wind, fluorescent hum. Layering a consistent ambience under a sequence is the single highest-return audio task you can do.
Then foley. Footsteps, fabric, doors, and object handling give weight to movement. If a generated shot has a character walking, the absence of footstep sound makes the motion feel floaty no matter how good the render is.
Dialogue is where most pipelines break. Write short lines. Two to six words per shot is plenty. Long monologues amplify every lip-sync error. When sync is unreliable, choose framing that hides it: over-the-shoulder shots, profile angles, reactions, hands in front of the mouth, cutaways to the listener.
Music does the emotional heavy lifting. Pick a track before you generate, not after, because tempo determines shot length. Cutting generative footage to a beat masks small continuity errors and makes a sequence feel intentional even when the shots came from different attempts.
The Finishing Workflow: Edit, Upscale, Grade
Resist the urge to polish every clip. The efficient order of operations is: rough edit first with low-resolution generations, then finish only the shots that survive the cut.
Assemble a story cut. Place your generated clips in order with rough timing. You will usually discover that a third of your shots are unnecessary, and that some sequences need a shot you have not generated yet. Finding this out before upscaling saves hours.
Upscale selectively. Only shots that made the cut deserve the time and processing. Upscaling tools vary in how they handle motion; test on a single difficult shot before committing a whole sequence, and watch for the plastic, over-smoothed look that comes from aggressive sharpening.
Handle frame rate deliberately. If you interpolate to a higher frame rate for smoothness, do it after the edit, and check for warping around fast motion and edges. Many cinematic projects look better staying at the native frame rate with motion blur than being interpolated to something hyper-smooth.
Grade for unity. Generative shots often arrive with slightly different black levels, color temperature, and contrast. A simple grade that matches blacks, warms or cools the highlights, and adds a consistent grain layer does more for perceived quality than another round of generation. Grain is especially useful: a uniform grain pass hides texture differences between engines and between generated and real footage.
Common failure modes and their fixes
Morphing anatomy. Fingers, ears, and teeth drift. Fix by shortening the shot, cutting earlier, or reframing. Do not try to prompt your way out of it.
Texture flicker. Surfaces shimmer frame to frame. Fix with a light temporal denoise, or reduce grain and detail in the grade. Reducing micro-detail usually reads as cleaner, not worse.
Background drift. Architecture quietly rearranges. Fix by generating from a locked reference image and keeping the camera move minimal.
Identity shift mid-shot. The face changes at the halfway mark. Fix by trimming to the first two seconds and cutting away before the drift, or by splitting the action into two shorter shots.
Garbled text and screens. Fix in post with a tracked graphic overlay. This is faster and cleaner than any regeneration strategy.
Impossible physics. Objects pass through each other, liquids behave oddly. Fix by removing the interaction from the shot, or by replacing that beat with a reaction shot or a sound cue.
Planning Time and Cost Without Locking Yourself In
Generative video is metered, so treat it the way a film producer treats stock and lab time: assume waste, budget for it, and reduce it where you can.
A realistic planning ratio is three to eight generation attempts per usable shot, depending on complexity and how strict your continuity bar is. Simple landscape establishing shots might land on the first or second attempt. Shots with a specific face, a specific action, and a specific camera move might take a dozen.
Keep a shot ledger. For every shot, record the approved reference image, the exact prompt text, the engine used, and the settings. When a client asks for a revision three weeks later, that ledger is the difference between a twenty-minute fix and a full rebuild.
Generate selection passes at lower resolution and only finalize what makes the cut. This is the single biggest practical saving available to most creators, and it also speeds up iteration because low-resolution attempts return faster.
Finally, avoid architectural dependence on one engine. Keep your prompts written in plain, portable language rather than in the syntax of a single platform. Keep your reference images and project files in neutral formats. The model landscape changes quickly, and the teams that stay flexible can adopt a better engine for a specific shot type without rebuilding their whole pipeline.
Quality Control Checklist Before You Publish
Run this pass on every finished piece:
- Continuity: Do wardrobe, hair, props, and location match across cuts?
- Screen direction: If a character moves left to right in one shot, do they keep that direction in the next?
- Eyeline: Do over-the-shoulder shots point the right way?
- Motion: Is there any unintended drift, jitter, or speed ramp?
- Audio: Is there continuous ambience under the whole sequence, with no sudden silence?
- Sync: Do mouths match words on every speaking shot?
- Grade: Are black levels and color temperature consistent from first shot to last?
- Titles and text: Is any on-screen typography crisp and readable on a phone?
- Aspect ratio and safe areas: Does the framing survive the crop for the platforms you are publishing to?
- Disclosure: Does your intended platform require labeling for synthetic media, and have you applied it?
FAQ
How many attempts does a usable AI video shot really take?
Plan for three to eight attempts on average. Photorealistic establishing shots often take one or two, because the audience has no strict expectation about what the location should look like. Shots with a recurring character, precise action, or readable props take far longer. Track your own ratio per shot category for a month; it will make your scheduling dramatically more accurate.
Can AI video replace a real camera crew?
For some deliverables, already yes: product teasers, abstract brand sequences, social cutdowns, explainer B-roll, and stylized narrative shorts. For anything requiring performance, precise physical interaction, or documentary credibility, it is better used as a supplement. The strongest results usually come from mixing generated shots with a small amount of real footage, then unifying everything with a grade and grain pass so the seams disappear.
What should I generate first: stills or motion?
Generate stills first, almost always. Stills are cheaper and faster to iterate, and approving a frame before animating it gives you a fixed target. When a shot goes wrong, you immediately know whether the problem is the composition or the motion, which is far harder to diagnose when you are prompting text directly to video.
How long should each generated clip be?
Shorter than you think. Two to five seconds is the sweet spot for most engines: long enough to read as a real shot, short enough to avoid drift. In the edit, you can extend the perceived duration with a cutaway, a slow-down, or a reaction insert. Trying to get ten seamless seconds out of a single generation is where most quality problems begin.
How do I keep the same character across multiple scenes?
Use a reference image rather than a text description as your primary anchor, and pair it with an identical descriptive string for anything the image cannot carry, such as voice, movement style, or habitual gestures. Build a small library of approved angles for each principal character. When continuity still fails, restructure the sequence so the character appears in shorter, more controlled shots rather than long continuous takes.
Is AI-generated video good enough for client work?
The honest answer is that it is good enough for many deliverable types and not for others. The deciding factor is usually tolerance for imperfection in the specific context. A fifteen-second social ad with quick cuts and music will pass almost any review. A two-minute dialogue scene with close-ups on faces will be scrutinized heavily. Match the technique to the tolerance of the format, and be transparent with clients about which shots are generated so expectations stay realistic.
What is the most common beginner mistake?
Promising too much in a single shot. Beginners write prompts that ask for a specific character, a specific action, a specific camera move, and a specific lighting setup all at once, then wonder why the output is chaotic. Professionals decompose the same idea into a sequence of simpler shots, each of which has one job. The edit, not the individual render, is where complexity is created.
