
Why quality is a workflow problem, not a model problem
Most creators who feel disappointed by generated visuals are not using the wrong model. They are using the right model at the wrong stage of a pipeline that has no structure. A single text prompt fired at a state-of-the-art video generator can produce a stunning eight-second clip, but it rarely produces a coherent sequence that a client will approve, a brand will publish, or an audience will rewatch.
The shift that separates hobbyists from working studios is simple to describe and hard to execute: treat generation as one stage inside a production pipeline, not as the entire production. That pipeline has four layers — reference definition, still generation, motion generation, and assembly — and each layer has its own tool choices, its own quality bar, and its own failure modes. When a shot looks wrong, the cause is almost always one layer upstream of where the problem becomes visible.
This guide walks through that pipeline in practical terms. It covers how to choose between model families for different shot types, how to hold visual consistency across a sequence, how to direct camera movement instead of accepting whatever the model offers, and how to build a quality control loop that catches problems before they reach an editor's timeline. It is written for creators, in-house content teams, agencies, and independent producers who need repeatable results rather than one-off lucky renders.
The four layers of a modern AI visual pipeline
Before comparing tools, map the work. Every AI-assisted visual production, whether it is a fifteen-second social ad or a three-minute brand film, moves through the same four layers. Skipping a layer does not save time; it moves the cost downstream where it is more expensive to fix.
Layer 1: Reference and prompt definition
This is where you decide what the shot actually is. Reference definition means collecting stills, mood boards, color swatches, wardrobe notes, lens choices, and lighting references. Prompt definition means translating those references into structured language a model can act on: subject, action, environment, lighting direction, lens character, film stock, color palette, and negative constraints.
The most common mistake here is writing a beautiful paragraph of prose and calling it a prompt. Cinematic language in a prompt is not decoration — each term should map to a visual decision you can verify in the output. If you cannot point at a frame and say which part of the prompt produced it, the prompt is too vague to iterate on.
Layer 2: Still generation and keyframes
Stills are cheap and fast relative to video. Use that asymmetry. Generate ten to twenty candidate keyframes, select the strongest two or three, and refine them before committing to motion. A still that is 90 percent correct can usually be pushed to 100 percent with inpainting, relighting, or a targeted regeneration pass. A video that is 90 percent correct usually has to be thrown away.
This layer is also where you lock the things that must not drift: face structure, hair, wardrobe details, product geometry, logo placement, and the overall color grade. Once those are baked into a keyframe, motion generation has a stable anchor.
Layer 3: Motion generation and extension
Here you convert stills into clips, or generate clips from text and image conditions directly. Modern video models respond to more than a prompt: they accept a starting frame, sometimes an ending frame, motion hints, camera path descriptions, and duration controls. The craft in this layer is restraint. A model asked to animate everything at once produces mush. A model asked to animate one clear action with one clear camera move produces something that cuts together.
Layer 4: Assembly, sound, and delivery
The final layer is conventional post-production: trimming, stabilizing, color matching, sound design, music, dialogue, subtitles, and format delivery. AI generation does not remove this layer. It changes what arrives in it — often more takes, with more subtle variation, and often with small artifacts that need cleanup. Budget time for it. Productions that skip this layer are the ones whose output looks unmistakably synthetic.
Choosing models by shot type
Model choice should follow shot requirements, not brand loyalty. The practical question is always: what does this specific shot demand, and which tool is strongest on that demand right now?
Character-driven narrative shots
Prioritize identity stability and natural facial performance. You want a model that holds a face across a turn of the head, a change in expression, and a shift in lighting angle. Test candidates with the same reference image and three escalating movements: a small head turn, a walk toward camera, and a profile-to-front rotation. Whichever model keeps the eyes and jaw structure intact across all three is your narrative workhorse.
Product and commercial shots
Prioritize geometric fidelity and material realism. Product work punishes any hallucinated detail — a warped edge, an invented button, a logo that morphs. Generate from a real photograph whenever possible, and use motion that is gentle: slow orbits, subtle parallax, light sweeps, shallow depth-of-field racks. Aggressive motion is where product renders fall apart.
Landscape, city, and architectural plates
Prioritize scale, atmospheric depth, and stable horizons. These shots tolerate more generation from text because there is no identity to preserve. Wide establishing shots, drone-style reveals, and time-of-day transitions are strong fits. Watch for structural drift in buildings and repeated textures in crowds or foliage.
Abstract, effects-heavy, and stylized sequences
Prioritize style coherence over realism. Stylized work — clay renders, cel-shaded animation, painterly treatments, liquid simulations — benefits from models with strong style adherence and from generating an entire sequence with identical style tokens so the look does not shift between cuts. Establish a style reference still and reuse it as the anchor for every clip in the sequence.
Consistency: the hardest constraint in AI production
Ask any working team what breaks first on a long project and the answer is consistency. A character's face changes between shots. A jacket changes shade. The sun jumps from left to right across a conversation. Solving this is mostly discipline, with a few technical levers.
Reference images and multi-image conditioning
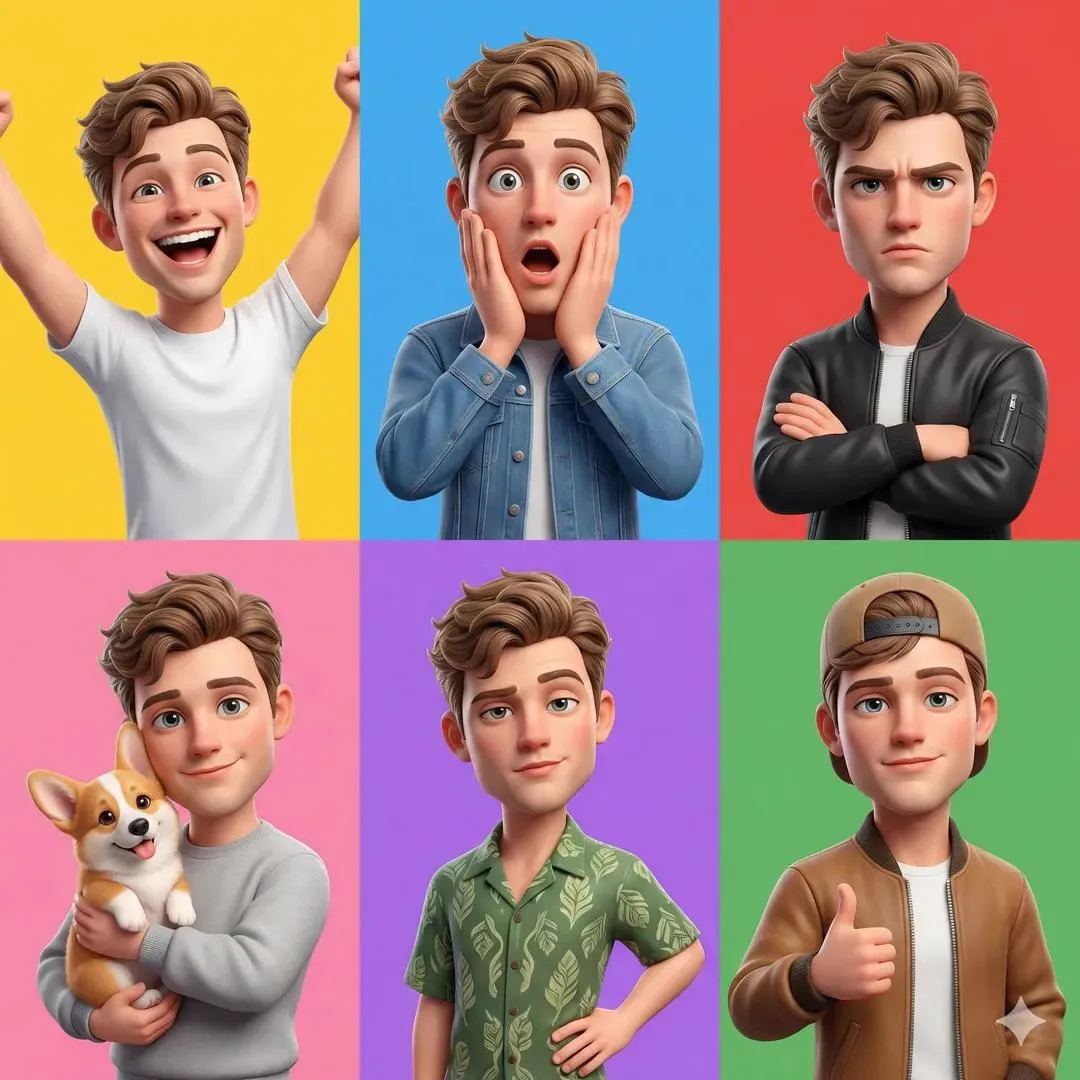
Feeding a model one reference gives you a suggestion; feeding it several well-chosen references gives you a constraint. Assemble a reference sheet per character or product: front, three-quarter, profile, full body, plus two lighting conditions. Keep the sheet small enough that the model can honor all of it — usually four to six images. Then reuse the exact same sheet for every shot in the sequence instead of re-picking references per shot.
Shot continuity and shot-to-shot matching
Generate the sequence in order and use the last frame of shot one as an input condition for shot two wherever the tool supports it. This creates a visual chain. Even when a tool does not support frame chaining directly, you can achieve similar continuity by extracting the final frame of a clip, treating it as a still, and using it as the starting image for the next generation.
Lighting, wardrobe, and color locks
Write lighting into every prompt with the same phrasing, not a synonym. Sunlight from camera left at low angle behaves differently from warm backlight, and models respond to exact terms. Lock wardrobe by describing garments in the same order with the same adjectives every time. Then apply a single show-level color grade in post so that small model-level variations get flattened into a coherent look.
Motion control and camera language
Text-to-video models are far better at rendering motion than at inventing it. If you do not specify movement, you get generic drift: a slow push, a slight float, occasionally a morphing background. Directing motion explicitly is the single highest-leverage skill in this workflow.
Start by choosing one primary camera behavior per shot. Options include locked-off static, slow dolly in, dolly out, lateral tracking, crane up, handheld follow, and orbit. Add one secondary behavior only if the shot needs it. Then specify subject motion separately: what the person or object does, in one sentence, with a clear beginning and end state.
Useful control techniques that apply across most tools:
- Start and end frames. Providing both anchors the clip and prevents drift, especially for transitions.
- Motion strength or intensity settings. Keep them low for realism and high only for stylized work.
- Duration splitting. A ten-second shot is usually better built as two five-second clips joined at a natural cut point than generated as one long take.
- Speed ramps in post. Generate at a consistent pace and create slow motion in editing rather than asking the model for it.
- Camera path descriptions. Terms like slow lateral dolly at eye level, gently rising crane, or subtle handheld follow reliably influence output.
Working in regional and bilingual production contexts
Productions serving Arabic-speaking audiences, Gulf markets, and multilingual brand campaigns add a layer of requirements that generic tutorials ignore. Three of them matter most.
First, cultural and wardrobe accuracy. Men's and women's attire, architectural references, street scenes, and interior design should reflect the actual region rather than a generic Middle Eastern aesthetic assembled from stock imagery. Reference real locations and real garments, and be specific about fabric, cut, and color.
Second, text rendering. Generated on-screen text, signage, and subtitles are unreliable, especially for right-to-left scripts. Generate clean plates without text, then add typography in the edit. This also makes localization far easier when you need the same spot in two languages.
Third, dual-language deliverables. A single visual master with separate subtitle and voiceover tracks costs far less than two separately generated campaigns. Design your shots to be language-neutral: avoid baked-in dialogue mouth shapes, avoid text in frame, and keep product labels either minimal or localized in post.
A practical end-to-end workflow example
Here is how the layers come together on a realistic project: a sixty-second brand film with eight shots, one recurring presenter, a product, and two locations.
- Script and shot list. Break the film into eight shots, each with a duration, a subject action, a camera behavior, and a lighting condition. This one page prevents most downstream confusion.
- Reference sheet. Build a presenter reference sheet with five images and a product sheet with four. Note the exact wardrobe and lighting phrasing you will reuse.
- Keyframes. Generate twelve to twenty stills per shot in the still layer, select the best, and refine it. Expect this stage to take the largest share of your time and to save you the most.
- Motion pass. Generate three to five motion takes per shot at short duration. Keep two per shot. Label files with shot number and take letter so nothing gets lost.
- Continuity pass. Compare every kept take against its neighbors. Fix the outliers first — a single off-model shot is more damaging than a slightly weak one.
- Cleanup. Use inpainting or retouching for warped hands, unstable edges, flickering textures, and unwanted artifacts. Small fixes here are cheaper than regeneration.
- Assembly. Edit to a temp music bed, then lock picture. Add grade, sound design, dialogue or voiceover, and typography.
- Delivery. Export in the required aspect ratios, add burned-in or separate subtitle files as needed, and archive your keyframes and reference sheets for the next project.
Common mistakes and how to avoid them
- Prompting everything in one pass. Split the prompt into subject, action, environment, camera, lighting, and style. Iterate on one variable at a time.
- Skipping the still layer. It feels faster to jump straight to video. It never is.
- Changing the reference between shots. Consistency comes from repetition, not from re-picking the best-looking frame each time.
- Asking for too much motion. One action and one camera move per shot. Everything else is noise.
- Ignoring frame rate and shutter character. If generated footage looks like video-game motion, reduce motion intensity rather than adding effects.
- Baking text into images. Always add typography in the edit.
- No naming convention. Teams lose more hours to file chaos than to any model limitation.
- Treating the first good take as final. Generate options; the second-best take is often the most editable.
- Forgetting sound. Sound design does more for perceived realism than any resolution increase.
- No archive. Save your reference sheets, prompts, and settings. The second project should reuse the first one's system.
Quality control checklist before you export
Run this list on every project. It catches the majority of issues that audiences notice and creators miss.
- Identity stability: face, hair, and body proportions consistent across all shots featuring the same subject.
- Wardrobe and props: no unexplained changes in garment color, cut, or accessory placement.
- Lighting continuity: direction and color temperature of light consistent within a single location and scene.
- Geometry: straight lines straight, product edges undistorted, no invented structural details.
- Motion: no unnatural speed changes, no warping at clip boundaries, no subject teleporting between frames.
- Hands and faces: check them at full resolution; these are the first places artifacts appear.
- Text and signage: intentional or absent, never accidental gibberish.
- Color: single grade applied across the sequence, no visible jumps between cuts.
- Audio: levels balanced, music and voiceover consistent, no clipping at transitions.
- Formats: correct resolution, aspect ratio, frame rate, and subtitle format for each delivery channel.
FAQ
Do I need one model or several?
Several, chosen per shot type. Most working pipelines use one model family for character-driven shots, one for products, one for wide environmental plates, and one for stylized or effects work. The skill is knowing which shot belongs to which tool, not finding a single tool that does everything.
How long does a one-minute AI-assisted film take?
For a team that has already built reference sheets and prompting templates, expect two to five working days for a sixty-second piece with eight to ten shots, including cleanup and assembly. First-time projects routinely take twice as long because the reference and prompt systems are being built from scratch.
What resolution should I generate at?
Generate at the highest native resolution your chosen tool produces reliably, then upscale only after the shot is locked in the edit. Upscaling early multiplies cleanup work and can amplify artifacts.
How do I keep a character consistent across many shots?
Build a fixed reference sheet, reuse the same descriptive phrasing for that character in every prompt, chain shots using last frames as the next shot's starting image, and apply one project-level color grade in post. Four small habits outperform any single setting.
How do I avoid the telltale AI look?
Reduce motion intensity, add sound design, grade the footage consistently, keep shots short, and cut on action. Realism comes from editing rhythm and audio far more than from generation settings.
Can I mix generated shots with real footage?
Yes, and it is often the best approach. Use generated shots for establishing moments, impossible camera moves, and concept sequences, and real footage for close human performance. Match grade, grain, and lens character in post so the two blend.
Where should a small team start?
Pick one shot type, build one reference sheet, and produce a thirty-second piece end to end. Document the prompts and settings that worked. That document becomes your production system, and it is worth more than any single tool subscription.
