
Why Video Lookbooks Are a Different Production Problem
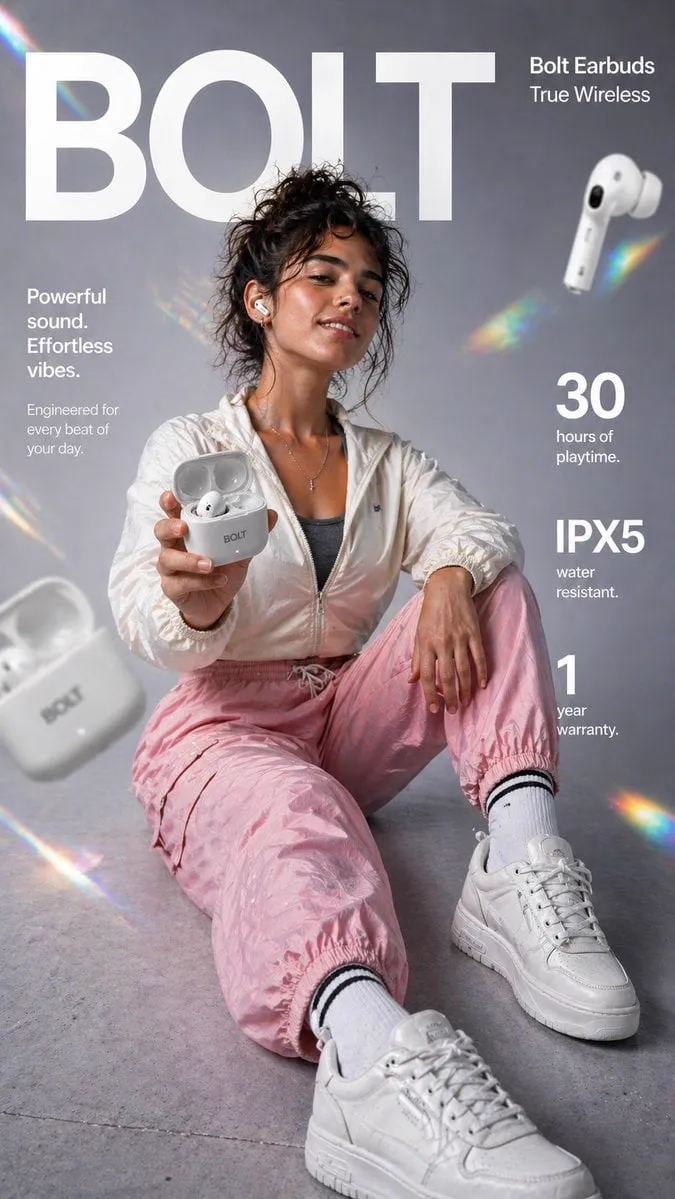
A video lookbook is not a short film with nice clothes in it, and it is not a slideshow with music over it. It sits in a narrow space between advertising and editorial, and it has to do two jobs at once: sell the garments and sell the world they belong to. That double duty is what makes it one of the hardest formats to generate with AI, because the models generating your footage have no idea which details matter to a buyer.
Think about what a viewer actually does with a lookbook. They watch a total stranger walk through a space for sixty to ninety seconds, and within that time they decide whether the fabric looks expensive, whether the silhouette flatters, whether the brand feels aspirational or accessible. Every one of those judgments comes from small signals: the way light wraps a shoulder, the way a hem moves at a turn, whether the skin tone stays believable from shot to shot.
AI video generation is very good at producing beautiful frames. It is far less reliable at producing a coherent sequence where the same person wears the same garment across a dozen shots without the fabric shifting color, the face drifting, or the styling quietly mutating between cuts. The gap between a stunning clip and a usable lookbook is where almost all of the real work lives.
This guide covers that gap. It is written as a production workflow, not a tool review: how to plan, prompt, generate, assemble, and quality-check a lookbook that looks like it came out of a studio rather than a text box.
The Five Layers of an AI Lookbook Pipeline
Before touching any generator, it helps to understand that an AI lookbook is assembled from five distinct layers. Each one can fail independently, and each one needs its own decision criteria.
Layer one: the look bible. The visual and emotional rulebook for the piece: palette, lighting philosophy, movement language, framing, pacing, and the specific garments in play. This is a document, not a prompt.
Layer two: reference assets. Clean product photography, model reference images, location plates, and any brand imagery that must be echoed. These become the anchors your generated video is pulled back toward.
Layer three: generation. Turning the look bible plus references into individual shots using text-to-video and image-to-video models, plus multi-reference tools when a character or garment must persist.
Layer four: audio. Voiceover, diegetic sound, and music bed, arranged so the rhythm of the edit has somewhere to sit.
Layer five: finishing. Edit, color, grain, text, and export variants for different placements.
Most disappointing AI lookbooks skip layers one and two and try to fix everything in layer three with longer prompts. That almost never works. A prompt can describe a look; it cannot remember a look. Memory has to come from your structure.
Pre-Production: Writing a Look Bible That Survives Generation
A look bible is what you would hand a human crew on day one. Keep it to two or three pages and make it brutally specific.
Define the visual thesis in one sentence
Examples that actually work as production guidance:
- Soft northern daylight, no hard shadows, everything shot slightly below eye level, model never rushes.
- High-contrast night exteriors, practical neon sources, handheld energy, camera always moving but never shaking.
- Clean studio cyclorama, one hard key, deep negative space, dead-still camera, only the garment moves.
If your thesis contains the word cinematic with no further qualification, rewrite it. Cinematic is a result, not an instruction.
Lock the garment list with immutable details
For every piece, write down what must never change: exact color name, sleeve length, closure type, print placement, shoe pairing, jewelry. AI models treat small details as suggestions unless you make them explicit and repeat them in every shot prompt.
Choose a movement vocabulary
Lookbook footage lives or dies on how bodies move. Decide in advance: slow walk toward camera, pivot turns, hand-to-collar gestures, fabric swirls, seated cross-legged poses. Write these as a short menu of five to eight approved movements and use only those. Random movement is the fastest way to make a sequence feel generated.
Build a shot-count budget
A ninety-second lookbook typically needs twelve to twenty shots. Under ten feels like a trailer. Over twenty-five feels like a catalogue dump. Decide the count before you generate anything, because it dictates how much generation time you allocate per look.
Shot Planning: Structuring Twelve to Twenty Shots
A structure that consistently works, adaptable to almost any brand:
- Open (2 shots): an establishing frame that sets the world without the model, then a first reveal. Reveal from behind or from a partial crop is stronger than a full frontal walk.
- Look one (3 shots): wide, medium, detail. The detail shot is non-negotiable: cuff, clasp, stitching, heel.
- Transition (1 shot): a movement shot that carries the viewer into the next look. Fabric in motion, a doorway, a turn.
- Look two (3 shots): same wide-medium-detail rhythm but a different energy, ideally a different lighting condition.
- Look three (3 shots): the statement piece gets the most screen time and the most camera ambition.
- Ensemble or styling beat (2 shots): multiple pieces interacting, layering, accessories.
- Close (2 shots): return to a calm frame, then a held final image with space for the logo and call to action.
Two practical notes. First, generate the detail shots as image-to-video from a real macro photo whenever possible; detail fidelity is where AI most often falls apart. Second, keep a spare shot for each look. You will need it.
Prompting for Cinematic Look: Camera, Light, Lens, Texture
The difference between an amateur and a professional AI lookbook prompt is not adjectives. It is the presence of camera and lighting grammar.
Speak in camera terms
Useful, concrete terms that translate reliably: low-angle tracking shot, slow dolly in, static medium close-up, 50mm equivalent, shallow depth of field, over-the-shoulder, wide establishing shot, whip pan transition, top-down flat lay in motion.
Vague emotional words are fine as seasoning but useless as instructions. Slow dolly in tells the model what to do. Elegant tells it nothing.
Describe light as a physical setup
Instead of saying beautiful lighting, say what the light is doing: single softbox at 45 degrees camera left, warm bounce from a beige wall, cold window light with visible falloff, hard sun through blinds creating stripe shadows. Mentioning where the light comes from and what it falls off against fixes more frames than any quality keyword.
Control texture and finish
If you want an editorial finish, name it: subtle 35mm grain, slightly lifted blacks, muted highlights, natural skin texture with visible pores, no digital smoothing. Many generators default to an over-processed, glossy aesthetic. Naming the imperfections is the fastest way to make footage feel shot rather than synthesized.
Keep prompts structured
A repeatable prompt skeleton: subject and garment, action, framing and camera move, lighting setup, environment, film finish, negative constraints. Write it once, then swap only the parts that should change between shots. This is how you preserve consistency without repeating yourself into nonsense.
Use negative constraints deliberately
Common blockers worth declaring: no extra fingers, no text or watermarks, no warped fabric logos, no changing sleeve length, no background people, no fast camera shake. Keep the list short; long negative lists start eroding the things you wanted.
Keeping the Model and Product Consistent Across Shots
This is the technical heart of lookbook production, and it deserves more planning than any other part of the pipeline.
Reference locking beats prompt repetition
Repeating a character description in words across ten prompts produces ten loosely related people. The reliable approach is reference-based: generate or select one strong master image of the model in the garment, then use that image as the anchor for every subsequent shot, letting motion prompts drive the action and the reference drive identity.
The three-anchor method
For each look, prepare three anchors: a full-body master, a three-quarter crop, and a detail macro of the garment. Use the closest anchor for each shot you generate. Generating a close-up from a full-body reference forces the model to invent detail; generating it from the macro anchor keeps fabric weave intact.
Handle fabric drift
If a garment changes hue across shots, the fix is usually not a new model but a tighter reference. Crop the reference so the garment fills more of the frame, add an explicit color name to the prompt, and reduce the amount of competing environment in the input image. Dark fabrics, satin, and fine knits drift first.
Multi-reference workflows
When a shot needs both a face and a garment from separate sources, multi-reference or identity-conditioning features are the correct tool. Use them sparingly, one shot at a time, and inspect the result before generating the next. Batch generating twenty multi-reference shots and reviewing them at the end is how entire sessions get thrown away.
Build a consistency test
Before producing final shots, generate three quick tests of the same look from three different framings. If the model, the garment, and the styling all survive, the setup is safe to scale. If any of the three drifts, fix the anchors before continuing. This ten-minute test saves hours.
Audio: Voiceover, Ambience, and the Rhythm of the Cut
AI lookbooks are often visually functional and sonically dead. Audio is not decoration here; it establishes pacing.
Decide the audio mode first
Three viable modes: silence with only music, music plus light ambience, or music plus a short spoken piece. Spoken voiceovers work best when they are under forty words total and delivered as fragments rather than full sentences: the word for the collection, the fabric callouts, one brand line.
Use synthesized voice carefully
If you use text-to-speech, choose a voice with restrained energy and write for breath. Short clauses, natural pauses, no exclamation. Then time the edit to the voice, not the other way around. A voiceover that fights the cut rhythm sounds like a mistake even when every word is correct.
Build a two-layer bed
The most professional-feeling results come from layering a sparse musical element (a single sustained note, a soft pulse) under a warmer, more melodic layer that enters when the statement look appears. This gives the sequence a clear emotional turn without needing dialogue.
Keep sound effects anchored to motion
Footsteps, fabric rustle, a door, a heel on stone. Align each one precisely to the visible action. Misaligned foley is more distracting than no foley at all.
Editing and Color: Turning Clips Into a Brand Asset
The edit is where a set of nice AI clips becomes something a client would actually publish.
Cut on motion, not on time
Every cut should be motivated by movement: a turn, a hand gesture, a step, a camera push. Hard cuts between two static frames read as slideshow. If a shot has no motion, place it at the start or the very end.
Hold shots longer than feels comfortable
Lookbook footage benefits from patience. One and a half to three seconds per shot for movement shots, up to four for held detail frames. Rushing the cut is the single most common tell of an AI-generated lookbook.
Unify color in post, not in the generator
Even with careful references, clips from different generations will differ in temperature, contrast, and black level. Do the unification in a color tool: match skin tones first, then neutralize the blacks across shots, then apply one shared grade with slight grain. Consistency in the grade does more for perceived production value than consistency in the generator.
Add finishing texture
A light 35mm grain pass, a subtle halation on highlights, and a very gentle vignette read as filmic discipline. Heavy effects read as compensation. Keep every effect at the level where you would have to look twice to notice it.
Export variants deliberately
Prepare at least three ratios: vertical for feeds, square for grid placements, widescreen for site and presentation. Do the reframing per shot, not by blind cropping the finished timeline, or you will lose the detail frames that carry the product.
Common Mistakes That Break the Illusion
Overloading single prompts
If your prompt is four paragraphs long, the model will drop the middle. Split the direction across the look bible and the reference images instead.
Ignoring skin tone continuity
Faces that shift warmth between adjacent shots destroy believability faster than any background artifact. Check skin tone across the whole sequence before checking anything else.
Generating in the wrong aspect ratio
Generate natively in the ratio you will publish. Cropping a widescreen generation to vertical loses the framing decisions you made in the prompt.
Letting the background outshine the garment
A stunning location can make a lookbook about the location. Keep environments quiet, out of focus, and consistent within each look.
Mixing too many distinct looks in one piece
Six looks in ninety seconds gives each look fifteen seconds. Either extend the runtime or cut the look count.
Skipping the detail pass
No macro shots means the viewer has no evidence of quality. Details are the proof.
Treating the first generation as final
Plan for two to three generation passes per shot. Anything that looks right on the first try usually looks better on the second.
A Quality Control Checklist Before Delivery
Run this before you export anything final:
- Character identity holds across every shot of the same look.
- Garment color, print placement, and hardware are identical shot to shot.
- Skin tone is stable from first frame to last.
- Every look has at least one detail shot with visible material texture.
- No shot contains unwanted text, watermarks, or malformed hands.
- Camera movement is smooth in every clip used; shaky clips get replaced, not stabilized.
- The music has a clear turn that lands on the statement look.
- Foley is aligned to visible action.
- Grade is unified and grain is consistent.
- Vertical, square, and widescreen exports all preserve framing intent.
Frequently Asked Questions
How long does an AI lookbook take to produce?
A four-look, ninety-second piece typically takes two to four working days for a single experienced editor: roughly half a day of planning and references, one to two days of generation with review cycles, and half a day of audio, edit, and grade. The planning half-day is what keeps the generation phase from ballooning.
Do I still need a real photo shoot?
If the goal is accurate representation of specific garments for e-commerce, yes, or at minimum high-quality stills to use as references. AI excels at atmosphere, motion, and world-building; it is less reliable at reproducing a specific garment with catalogue accuracy. The strongest results pair real product stills as anchors with generated motion footage.
Which type of model should I choose for which shot?
Use image-to-video with strong reference support for anything involving the model or the garment. Use text-to-video for establishing plates, abstract transitions, and environment shots where no identity needs to persist. Use dedicated multi-reference or identity-conditioning tools only for the shots where a face and a garment must appear together.
How do I stop the face from changing between shots?
Anchor on a single master image, keep the model framing similar between adjacent shots where possible, avoid wide-angle distortion, and check skin tone at the edit stage. If drift persists, generate the shots in a tighter sequence order so each generation can reference the previous frame.
Can I use the same AI output in paid advertising?
That depends on the licensing terms of each model and asset you use, plus any likeness rights for people depicted. Build a simple asset log listing each tool, its license terms, and the source of every reference image. It takes minutes and prevents painful replanning later.
What is the biggest tell that a lookbook was AI generated?
Unstable identity combined with over-smooth skin and a uniform glossy finish. Fix those three and most viewers stop asking the question entirely.
Where to Start Tomorrow
The temptation with AI video is to start generating immediately and hope a sequence emerges. Lookbooks punish that approach harder than almost any other format, because they depend on repetition of the same person and the same garment across many frames.
Start instead with the two documents nobody enjoys writing: the look bible and the anchor reference set. Lock the garments, movements, lighting setups, and shot list. Generate a three-shot consistency test, review it honestly, and only then scale into full production. Do the audio and the grade as deliberate finishing stages rather than afterthoughts.
The tools will keep improving, and the specific models you rely on will change within a year. The production structure will not. A look bible, reference anchors, a disciplined shot list, a rhythm in the audio, and a unified grade are what separate a scroll-stopping lookbook from a folder of attractive clips.
