
Why Asking Which Model Is Best Leads You Astray
Every few months a new video model lands, and the same conversation restarts: is it better than the last one? Teams rebuild their entire pipeline around the answer, then rebuild again when the next release arrives. The pattern is exhausting and expensive, and it usually produces weaker work than a boring, layered workflow would.
The reason is simple. Modern video generation is no longer a single task. A finished thirty-second spot requires concept exploration, look development, character consistency, motion design, iteration, upscaling, and editing. No single model is the strongest at all of those, and the differences between the leaders are narrower than the marketing suggests.
What actually separates a smooth production from a chaotic one is not the logo in the corner of the interface. It is whether you have mapped each stage of your pipeline to a capability, and whether you treat model choice as a modular decision you can swap out without rewriting the whole process.
This guide lays out a model-agnostic workflow for AI video production. It covers the capability layers you need, how to evaluate models fairly, how to manage references so outputs stay consistent, when self-hosted options make sense, and how to control cost without guesswork.
The Four Capability Layers You Actually Need
Instead of ranking models, rank capabilities. Most AI video work draws on four layers, and they rarely come from the same place.
Layer 1: Text-to-video for concepts and B-roll
Text-to-video is the fastest way to explore an idea. Type a scene description, get a few seconds of motion, decide whether the direction is worth pursuing. It is also excellent for atmospheric inserts: rain on a window, traffic at dusk, steam rising off a cup.
Treat this layer as a sketchbook, not a final render. Its job is to answer questions quickly and cheaply. When teams try to use pure text-to-video for hero shots with specific characters and precise camera moves, they burn hours on prompts that were never going to converge.
Layer 2: Image-to-video for locking a look
Once you know what a shot should look like, generate or select a still first. Approve the framing, lighting, wardrobe, and color. Then animate that still.
This single change fixes most consistency complaints. A still image is cheap to iterate on and easy to review with a client. A generated video is neither. Animating an approved frame narrows the model's job from inventing a world to moving one, which it does far more reliably.
Layer 3: Motion and camera control
Some models accept explicit camera direction: dolly in, orbit, crane up, rack focus. Others infer motion from the prompt and hope for the best. If your project depends on a specific move, you need a model that exposes that control, or you need to composite the move in post.
Motion control also covers subject performance. Reference-driven pose transfer lets you drive a character with a source video, which is the difference between a plausible walk cycle and a drifting, weightless shuffle.
Layer 4: Reference-driven consistency
This is the layer that decides whether a series looks professional. Characters must keep the same face, outfit, and proportions across shots. Locations must keep the same architecture and light. Products must keep identical labels and geometry.
Consistency comes from feeding the model structured references, not from writing longer prompts. Character sheets, style frames, and prop libraries matter more here than any prompt trick.
A Model-Agnostic Production Workflow
The following sequence works whether you are using hosted APIs, a browser studio, or local inference. It assumes nothing about which vendor you prefer.
Step 1: Script and shot list. Break the piece into shots with intent: what changes, what the audience should notice, how long it lasts. Two sentences per shot is plenty. This document is your contract with yourself.
Step 2: Look development with stills. Generate or shoot reference stills before any video. Approve palette, lens feel, grain, and lighting direction. Store them in a versioned folder.
Step 3: Animatic. Assemble the shot list with placeholder clips or simple pans across stills, plus rough audio. Timing problems are cheap to fix here and expensive later.
Step 4: Shot generation. Animate approved stills, one shot at a time, using locked references. Generate three to five variations per shot and move on. Do not chase perfection inside a single clip.
Step 5: Continuity pass. Review everything in sequence, not individually. Check eyelines, screen direction, wardrobe, light continuity, and pacing. Flag shots that break the illusion and regenerate only those.
Step 6: Finishing. Upscale, interpolate frame rate if needed, stabilize, color grade, and add sound. Sound design does more for perceived realism than another generation pass ever will.
Step 7: Archive. Save prompts, seeds, reference versions, and settings. When a client asks for a variation three weeks later, an archive turns a day of work into an hour.
Decision Criteria: How to Compare Models Fairly
Vendor comparisons usually devolve into isolated clips chosen to flatter one tool. Use a scorecard instead. For each model, rate the following on a one-to-five scale using your own material, not demo reels.
- Prompt adherence: does the output respect subject, action, and setting?
- Temporal coherence: do objects and anatomy stay stable across the clip?
- Camera control granularity: can you specify a move and get it?
- Reference fidelity: how closely does it follow a supplied character or style image?
- Resolution and duration ceiling: what is the maximum single-clip length?
- Iteration latency: how long from prompt to preview, including queue time?
- Cost per attempt: the real number, including failed generations.
- Editing affordances: extend, inpaint, outpaint, and re-roll support.
- Licensing and commercial terms: can you use outputs in client work?
- Data handling: where do your assets live, and are they used for training?
Weigh the criteria by project type. A social ad campaign cares about cost per attempt and latency. A narrative short cares about consistency and camera control. An internal explainer might only care about duration and licensing.
Run the scorecard quarterly. The frontier moves fast, and a model that scored poorly last season may now be your best option for one specific layer.
Reference Management: The Skill That Decides Output Quality
Most quality complaints trace back to sloppy references rather than weak models. Treat references as production assets with the same discipline you would apply to camera footage.
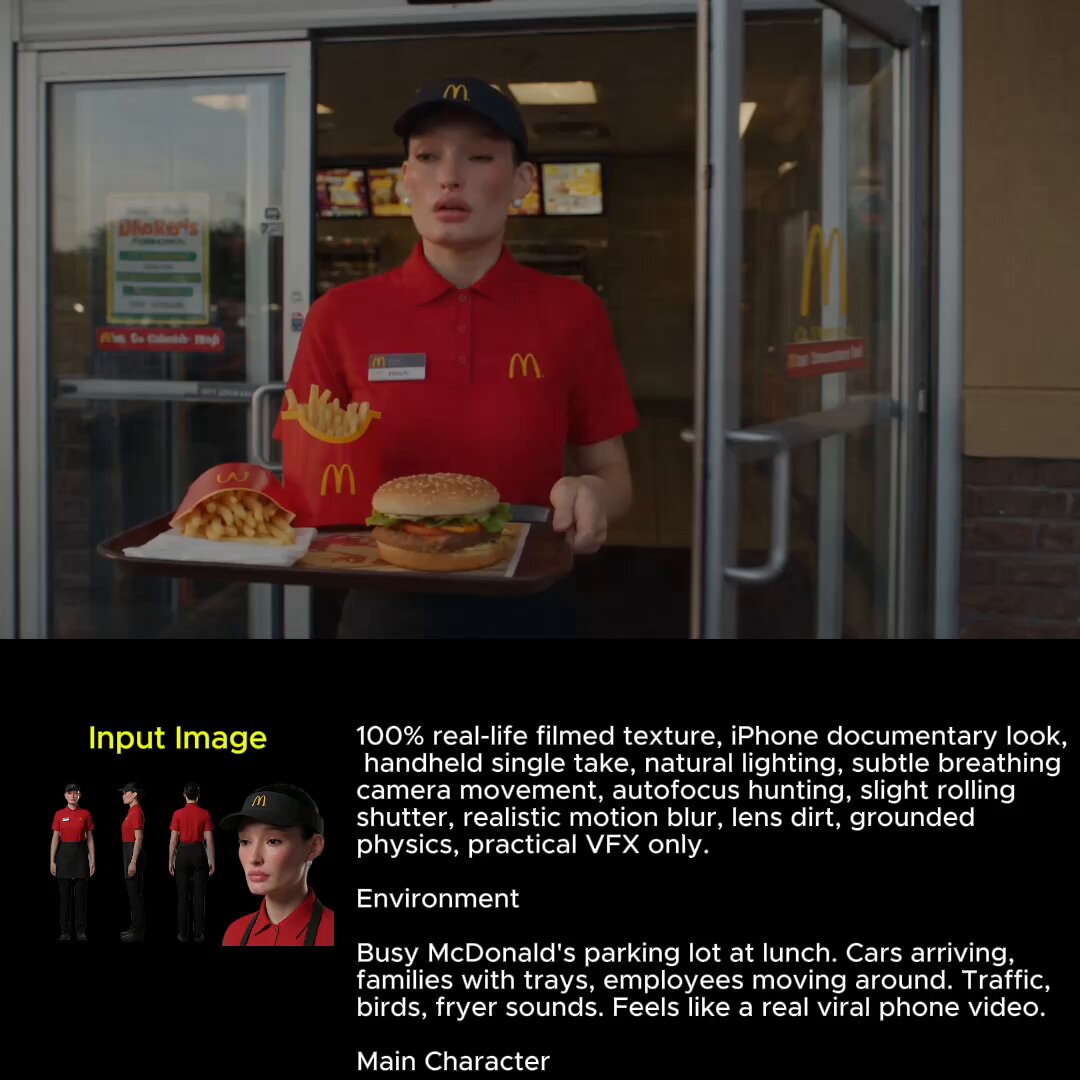
Build character sheets. Front, three-quarter, and profile views, plus a neutral expression and a full-body shot. Keep lighting flat and even so the model learns identity rather than mood.
Separate style from subject. If you feed one image that carries both a face and a palette, the model entangles them. Supply a style frame for look and a character sheet for identity.
Version everything. Reference-v2-final-final is a real problem. Use a naming convention with a date and a short description, and never overwrite a reference that a delivered shot depends on.
Lock seeds when you can. If a model exposes seeds, reuse a seed when iterating on composition. It reduces the number of variables changing between attempts.
Use negative references sparingly. Describing what you do not want works better as a short, concrete phrase than as a paragraph of prohibitions.
Open-Source and Self-Hosted Options: When They Win
Self-hosted video models have moved from novelty to practicality for specific jobs. The trade-off is straightforward: you exchange convenience for control, privacy, and marginal cost.
Reach for local inference when you need:
- Unlimited iteration. Style exploration with hundreds of low-resolution drafts costs electricity, not per-generation fees.
- Confidential material. Unreleased products, medical footage, or client scripts that cannot leave your network.
- Fine-tuning. Training a small adapter on your own character or product is often the only way to get true consistency at scale.
- Batch pipelines. Rendering hundreds of short clips overnight without queue dependence.
Stick with hosted services when you need:
- Peak quality with zero setup. Top-tier models still lead on complex motion.
- Elastic capacity. A launch campaign does not justify a permanent GPU cluster.
- Low maintenance. No drivers, no dependency conflicts, no thermal throttling at 2 a.m.
The pragmatic answer for most teams is hybrid: hosted models for hero shots and difficult motion, local models for drafts, variants, and private material.
Budget and Throughput Without Guesswork
Pricing structures vary wildly, so convert everything into one metric: cost per usable second. Take the total spend on a project and divide by the seconds that survived the final edit. That number exposes inefficiency fast.
A few habits keep it low:
Draft at low resolution. Generate previews at reduced resolution or shorter duration, then re-render only the approved takes at full quality. This alone can cut spend in half.
Set a retry cap. Three to five attempts per shot is a healthy ceiling for most work. Beyond that, the problem is usually the reference or the prompt structure, not luck.
Batch related shots. Grouping shots that share a character and location reduces reference reloading and keeps style drift low.
Track queue time as cost. If a generation takes twelve minutes and you are paying an artist to wait, latency is a budget line item.
Reuse assets. Inserts, transitions, and background plates are reusable across campaigns. Keep a library.
Common Mistakes and How to Fix Them
Characters drift between shots. Cause: inconsistent references. Fix: one canonical character sheet per character, used everywhere, plus a continuity review in sequence.
Hands, text, and props deform. Cause: asking one generation to invent fine detail. Fix: generate props separately, or composite real plates and product photography into the scene.
Every clip looks like a different film. Cause: no shared style frame. Fix: approve one grade and one lens reference, then apply it during generation, not only in post.
Prompts keep getting longer and worse. Cause: compensating for missing references with adjectives. Fix: cut the prompt to subject, action, camera, and light, then supply visuals.
Motion looks floaty. Cause: no motion reference and no frame-rate plan. Fix: use pose or video-driven control, and interpolate deliberately rather than by default.
Clients reject everything at review. Cause: reviewing finished video instead of stills and animatics. Fix: get approvals at the still stage and again at the animatic stage.
Nobody can reproduce a shot. Fix: log prompts, seeds, model versions, and reference file names at the moment of generation, not afterward.
Aspect ratio and frame rate are wrong at delivery. Fix: decide the delivery spec before generating. Regenerating for a different crop wastes whole days.
Quality Control: Build a Small Internal Benchmark
Demos are marketing. Build your own test set instead. Write ten prompts that represent your real work: a character close-up with dialogue-adjacent expression, a product rotation, a walking shot, a crowd scene, a night exterior, a fast action beat, and so on.
Generate each prompt on every model you are considering, three times each. Then score blind, without labels, on consistency, motion realism, prompt adherence, and artifacts. Thirty generations per model is enough to reveal a pattern that a single clip hides.
Re-run the benchmark when a major version ships. Keep the results in a shared document so the whole team can reference past decisions instead of relitigating them.
FAQ
Do I need more than one video model?
For anything longer than a single clip, yes. Even if one model handles most shots, a second option usually wins on either motion control, speed, or cost for a specific layer.
How do I keep characters consistent across many shots?
Use a canonical character sheet, animate approved stills rather than generating from text, keep wardrobe and props identical, and review the sequence in order. Fine-tuning an adapter helps at higher volumes.
Is text-to-video or image-to-video better?
Use text-to-video to explore and image-to-video to execute. The execution stage should almost always start from an approved frame.
How many attempts should a shot take?
Three to five variations is a reasonable target. If you need twenty, the reference set or the prompt structure is the bottleneck.
When is self-hosting worth the effort?
When you need high iteration volume, confidential material, or custom fine-tuning. For occasional hero shots, hosted services remain cheaper once you count maintenance time.
What is the single biggest quality lever?
Reference discipline. Better inputs beat better prompts, and better prompts beat switching tools.
How should I structure a prompt?
Subject, action, camera movement, lighting, and duration. Keep it short and concrete, and let reference images carry style and identity.
Putting the Toolkit Together
The shift in AI video is not from one dominant model to another. It is from buying a monolith to assembling a toolkit. The teams producing the most convincing work are not loyal to a single interface; they have mapped capabilities to pipeline stages, standardized their references, set retry limits, and built a small internal benchmark to guide decisions.
Start small. Pick one project, split it into the four capability layers, and assign each layer the best tool you have available. Approve stills before animating. Cap your attempts. Log everything. After two projects, the workflow stops feeling like improvisation and starts feeling like production.
That is the real alternative to chasing releases: a process that keeps working when the next model arrives.
