
What changes when you move beyond one-shot prompts
Most people meet generative video the same way: type a sentence, wait, and hope. That works for a clip. It falls apart the moment you need twelve shots that look like they belong to the same film, or when a client asks for the same character in a different location, or when your series needs a consistent visual identity across fifty episodes.
The jump from "prompting" to "workflow" is the same jump that happened in photography when people moved from auto mode to manual. You stop being a passenger and start being a director. Two things make that jump possible: a model (or small set of models) you understand deeply, and a repeatable pipeline that turns an idea into a finished sequence without guesswork at every step.
This guide walks through both. We will look at how to choose between off-the-shelf models and a fine-tuned one, how to prepare training data that actually improves output, how to control motion and continuity across shots, and how to build a production pipeline you can run again next week with a different brief. The emphasis is on decisions and repeatability, not on any single vendor.
Decision framework: pre-trained, fine-tuned, or reference-driven
Before you train anything, be honest about which problem you actually have. There are three common situations, and they call for different approaches.
Situation one: you need volume, not identity. You are producing short social clips, ad variations, or B-roll. Style consistency matters less than speed. Use a strong general-purpose text-to-video or image-to-video model, build a prompt template library, and spend your energy on shot planning. Training here is overkill.
Situation two: you need a specific look. Your brand has a distinctive palette, lighting signature, or animation style that generic models keep missing. This is the sweet spot for light fine-tuning or, more cheaply, a reference-driven approach: feed the model curated style frames, lock the seed, and keep the parameters fixed across the whole project. Reference-driven control gets you 70–80% of the way with almost none of the setup cost.
Situation three: you need a repeatable character, product, or motion vocabulary. A recurring mascot, a specific camera move you use as a signature, a product that must look identical in every frame. This is where fine-tuning earns its keep, because you are teaching the model something it will reuse dozens or hundreds of times.
A quick decision test:
| Question | If yes | If no |
|---|---|---|
| Will this style/character appear in 5+ separate pieces? | Fine-tune or build a reference pack | Use off-the-shelf models |
| Do you have 20+ clean, consistent source frames or clips? | Fine-tuning is viable | Collect data first |
| Is the deadline under a week? | Reference-driven control | Consider fine-tuning |
| Does the client review frame-by-frame? | Prioritize continuity tooling | Prioritize speed |
One more consideration: fine-tuning is not permanent. Models update, your data drifts, and a tune that looked perfect six months ago may now be worse than the base model. Treat a fine-tune as a project asset with a review date, not a permanent installation.
Dataset preparation: the part everyone underestimates
Nine out of ten disappointing fine-tunes are data problems, not training problems. The model learns exactly what you show it — including your mistakes.
Shot selection and metadata
Start by defining the scope of the tune in one sentence. "Interior night scenes with practical lighting and slow dolly moves" is a scope. "Cinematic" is not.
Then collect 30–80 examples that all sit inside that scope. Fewer than 20 usually underfits; more than a few hundred is often unnecessary for style adaptation and just slows your iteration loop. Consistency beats quantity: if half your examples are harsh daylight and half are moody interiors, the model learns mush.
For every clip or frame, record metadata:
- Camera move (static, pan, dolly, handheld, crane)
- Subject and framing (wide, medium, close)
- Lighting condition
- Motion speed and direction
- Any artifact you want the model to avoid
This metadata becomes both your caption source and your evaluation rubric later.
Captioning that actually helps
Captions are the bridge between text and pixels. Bad captions describe the obvious; good captions describe the controllable dimensions.
Weak caption: "A woman walking in a city."
Useful caption: "Medium tracking shot, woman in beige coat walks left to right past glass storefront, overcast daylight, shallow depth of field, steady camera, slow walking pace."
The second version gives you levers. When you later write "slow walking pace, overcast daylight," the model knows what that combination looks like. Write captions in a consistent order — shot type, subject, action, lighting, lens, camera movement — so your prompts at generation time mirror your training language.
Avoid captioning things you do not control: emotion words, backstory, brand names, or anything the pixels cannot verify.
Legal and ethical hygiene
Use footage you own or that is properly licensed. Avoid real people's faces unless you have clear rights. Keep a simple manifest listing the source and license for every asset in the dataset. It takes twenty minutes and saves an enormous amount of pain if a client asks where the look came from — and it makes it trivial to rebuild the dataset later if you need to swap out one contributor's footage.
Finally, hold back 10–15% of your data as a validation set. Never train on it. It is the only honest test of whether the tune generalizes or just memorized.
The fine-tuning loop, step by step
Pick a base model that matches your motion style
Start from the closest base you can find rather than from a general model. If your work is character animation, start with something already strong at human motion. If your work is product turntables, start with something that handles reflections and rigid objects well. The closer the base, the fewer examples you need and the less you risk degrading everything else the model knows.
Run small controlled experiments
Change one variable at a time. A practical sequence:
- Baseline run. Generate five outputs with the base model and your target prompt. Save them. This is your reference point.
- Light tune. Train with a low learning rate for a short run. Generate the same five prompts with identical seeds.
- Compare blind. Rename the files so you do not know which is which, then judge.
- Increase only if needed. If style is under-expressed, train longer or add data. If motion has become stiff or colors have drifted, you have overfit — back off.
Keep a simple run log: dataset version, parameter changes, seeds used, and your rating for each output. After four or five experiments you will have a genuine feel for how this model responds, which is worth more than any tutorial.
Evaluate with a rubric, not vibes
"Looks good" is not a measurement. Score each output 1–5 on four axes:
- Style fidelity — does it match the target look?
- Motion coherence — no warping, no limb teleporting, no melting edges?
- Prompt adherence — did it do what you asked, including camera move?
- Artifact rate — how many frames would need repair or re-render?
Total the scores. A tune that gains two points on style but loses two on motion is a wash, and you should know that before you commit a week of production to it.
Controlling motion, continuity, and style across shots
Once you have a model you trust, the work shifts to controlling it at the sequence level. Three techniques carry most of the load.
Seed and parameter locking. Fix your seed, sampler, step count, and motion strength for a whole scene. Variation should come from your prompt and your input frames, not from random settings. The moment you start changing three parameters between shots, you lose the ability to diagnose anything.
Reference frames as anchors. For character work, generate a clean hero frame first — a well-lit, neutral-pose still — then use it as the input for every subsequent shot. This is far more reliable than trying to describe the character in text each time, and it lets you change location and action without changing identity.
Motion vocabulary. Build a short list of named camera moves you use repeatedly (slow push-in, lateral track left, orbit 30 degrees, handheld drift) and describe them in exactly the same words every time. Your model responds to phrasing consistency even more than to cleverness. A team that says "lateral track left" in three different ways gets three different moves.
For longer sequences, break the scene into beats and render them as separate shots rather than asking for one long continuous take. Continuous takes invite drift. Discrete shots give you edit points and let you re-render just the weak beat.
Building the end-to-end production pipeline
A working pipeline has six stages. Skipping any of them pushes the work downstream where it costs more.
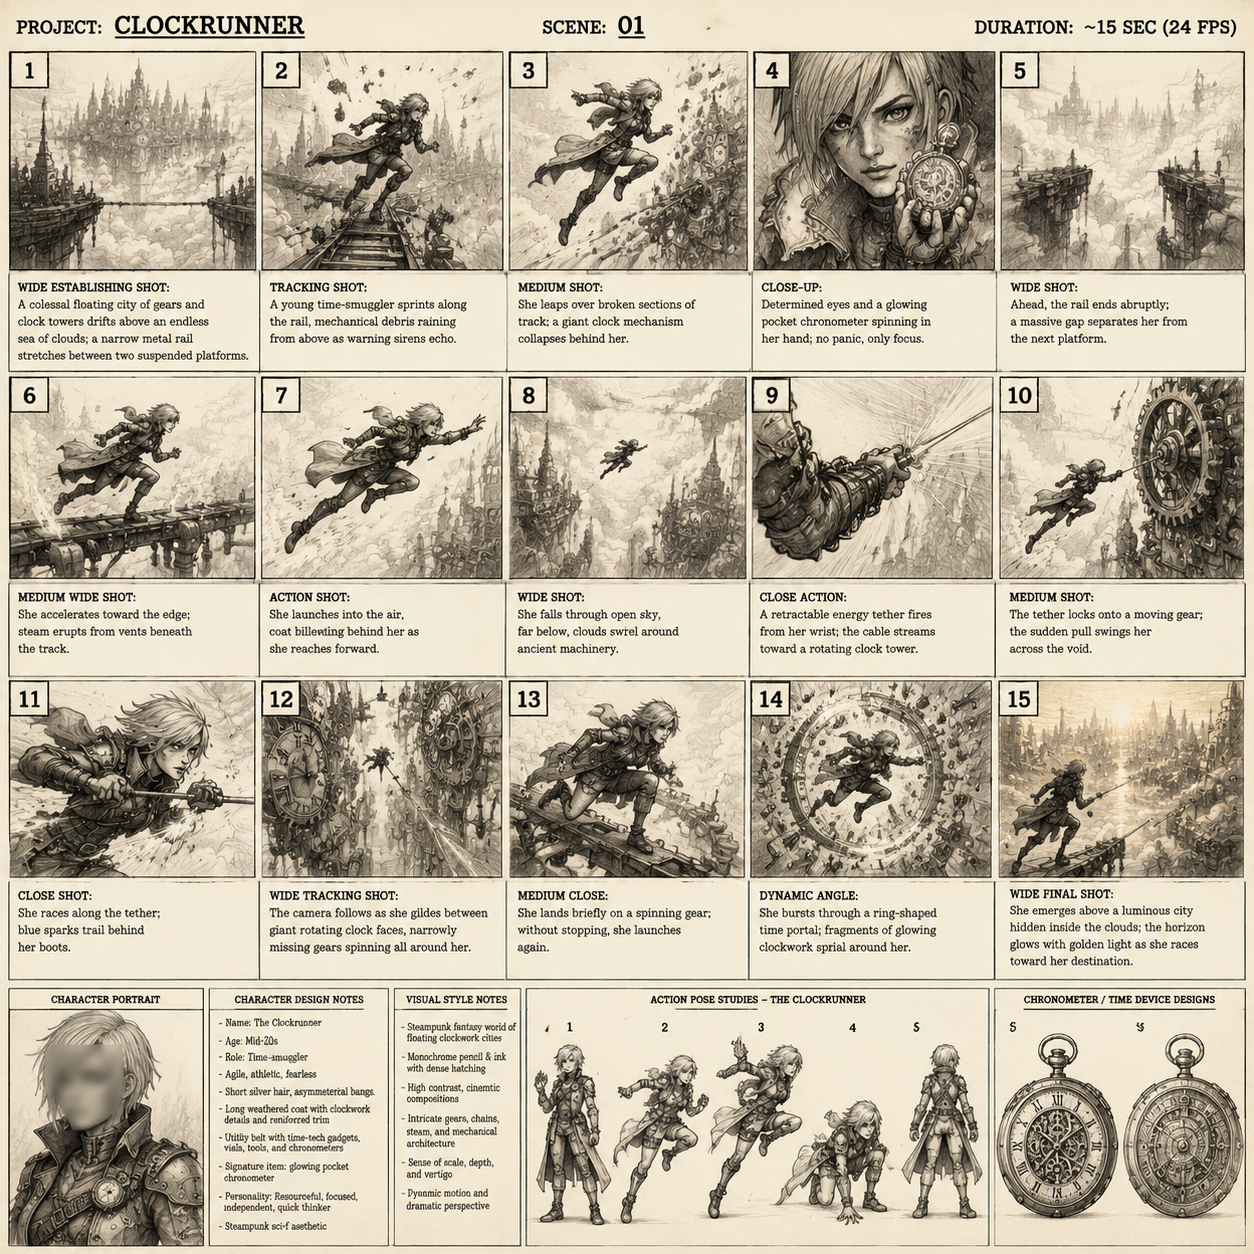
1. Script and beat sheet. Write the sequence as beats: what changes, shot by shot. This is where you catch logic problems, not after rendering.
2. Look development. Generate 5–10 style frames. Get approval on the look before you spend compute on motion. This single gate prevents most rework.
3. Shot list and shot cards. Each card holds: shot type, subject, action, camera move, lighting, duration, and the reference frame if any. These cards become your prompts almost verbatim.
4. Generation. Batch by scene, not by shot, so you keep settings identical. Name files with scene, shot, and version: sc02_sh04_v03.mp4.
5. Assembly and repair. Bring clips into your editor. Expect to re-render 15–30% of shots. Cut around small artifacts, and use a short insert or reaction shot rather than fighting a bad frame.
6. Finishing. Color, sound, captions. Sound design does enormous work in selling AI-generated motion — a confident whoosh or footstep masks small imperfections that the eye would otherwise catch. Add ambience and music early enough that you can judge whether a shot actually works.
One useful habit: keep a "known good settings" document. The moment you find a parameter combination that reliably produces clean output for your style, write it down with the date. You will forget it in three weeks.
Quality control checklist and common mistakes
Run this before you export anything:
- Are all shots inside the same color and contrast range?
- Does the subject's wardrobe, hair, and props stay consistent between cuts?
- Do camera moves follow a rhythm, or is every shot a different speed?
- Are there frames where hands, text, or fine detail break down?
- Do on-screen graphics or captions sit clear of motion?
- Is the audio leading or lagging the cut?
- Does the sequence still make sense with the sound off?
The most common mistakes, in order of how much time they waste:
- Training on too few, too varied examples. Result: a model that does nothing well.
- Chasing a perfect single clip instead of a working sequence. Ten good-enough shots beat one perfect shot with nine missing.
- Never saving a baseline. Without it, you cannot tell whether your changes helped.
- Over-describing emotion and under-describing camera. Models follow mechanics far better than feelings.
- Rendering the whole project before reviewing look. The most expensive mistake on the list.
- Ignoring audio until the end. Bad audio makes acceptable visuals feel broken.
Tooling landscape: where each tool fits
You do not need one tool. You need a small stack, each part doing what it is good at.
Image generation for look development and reference frames. Pick one and learn its style-transfer options deeply.
Video generation for motion. It helps to keep two models available — one that excels at realism, one at stylized or animated motion — and choose per project rather than per shot.
Motion and compositing tools such as After Effects, Fusion, or Nuke for stabilization, tracking, cleanup, and frame repair. A five-second patch in a compositor is often faster than a five-minute re-render.
Editing in something like DaVinci Resolve or Premiere. Resolve's built-in color and audio tools mean you can finish in one place, which reduces round trips.
Upscaling and frame interpolation for final delivery resolution and smoothness. Use interpolation sparingly on shots with fast motion; it can introduce ghosting that looks worse than a lower frame rate.
Voice and audio tools for narration, ambience, and sound design. Generate scratch narration early so you can time your cuts to the words.
Workflow automation for chaining steps — a node-based interface for repeatable render recipes, or a simple script that renames and logs every output. Automation is what turns a one-off project into a service you can deliver repeatedly.
Standardize your export settings across the whole stack: resolution, frame rate, color space, and codec. Mismatched frame rates are the single most common cause of jittery final cuts.
Time, compute, and iteration budgeting
Plan a project in phases with explicit checkpoints, and resist the urge to render everything before review.
A realistic split for a 60-second piece built with custom models:
- Look development and approvals: 20% of effort
- Shot list and reference preparation: 15%
- Generation and re-renders: 40%
- Assembly, repair, and finishing: 25%
Budget more compute than you think for iteration, and less than you think for final renders. The expensive part is not the last pass; it is the fourth attempt at a shot that refuses to cooperate. When a shot has failed three times, stop and change approach: shorten it, reframe it, or replace it with a different beat entirely. Stubbornness at the render stage is the biggest hidden cost in AI video production.
Track two numbers per project: shots rendered versus shots used. If that ratio climbs above roughly 3:1, your prompt discipline or reference frames need work — not more compute.
FAQ
Do I need to fine-tune at all? No. Most projects are better served by strong prompt templates, locked seeds, and reference frames. Fine-tune when a specific style, character, or motion needs to survive across many separate pieces.
How much training data is enough? For style adaptation, 30–80 consistent examples is usually plenty. Below 20, results get unstable. Beyond a few hundred, you gain little and slow every iteration.
Why did my tune make motion worse? Almost always overfitting: too long a run, too high a learning rate, or a dataset dominated by near-identical frames. Add variety in motion and camera angle, shorten the run, and re-evaluate against your baseline.
How do I keep a character consistent across shots? Generate one clean hero frame, reuse it as the input for every shot, lock your seeds, and describe wardrobe and features in identical wording each time. Avoid re-describing the character freely — paraphrasing is drift.
Can I mix models in one project? Yes, and it often looks better than forcing one model to do everything. Keep the color grade and grain consistent in post so the seams disappear.
What is the fastest way to improve output quality? Better input frames. A sharp, well-lit, correctly framed reference frame improves results more than any parameter tweak.
How often should I revisit an older fine-tune? Every few months, or whenever the base model you trained on gets a significant update. Re-run your validation set and compare scores before assuming the old tune still wins.
Where do sound and captions fit? Early. Scratch audio during look development reveals pacing problems, and captions placed over motion need to be checked frame by frame before export.
A durable AI video workflow is not a secret model or a magic prompt. It is a short list of decisions made deliberately: the right base model, clean and consistent data, locked parameters, reference frames as anchors, and checkpoints that stop you from rendering fifty shots of the wrong look. Build that once, document it, and every project after it starts from a position of control rather than luck.
