
Why AI video presentations behave differently from slide decks
A presentation used to mean slides, a projector, and a person talking over bullet points. That format still works in some rooms, but it collapses the moment your audience is watching on a phone, skimming a landing page, or deciding within the first eight seconds whether to keep watching. A video presentation inverts the contract: the visuals carry the argument, the narration supports them, and the edit decides what the viewer feels before they consciously evaluate what you said.
Generative video models changed what is practical here. Producing a three-minute branded explainer with fully custom footage once meant a shoot, a crew, and a post-production budget. Today a small team can assemble something visually coherent from generated shots, stock footage, screen recordings, and animated typography, often in a single afternoon. The bottleneck moved from "can we get the footage" to "can we keep it coherent."
That shift is where most projects fail. Models generate individual shots beautifully and sequences poorly. A shot of a person walking through a lobby looks stunning in isolation; in the next shot, the same person has a different face, a different jacket, and lighting from a different sun. The audience may not name the problem, but they feel it. The video reads as a demo reel rather than a story.
This guide is about closing that gap. It covers the storytelling decisions that should happen before generation, the editing techniques that hold a sequence together, the audio layer most creators rush, and a workflow you can repeat on every project.
Build the narrative spine before you open a timeline
The most common failure in AI-assisted video is technical competence without narrative direction. People start generating shots because generation is fun, then try to assemble a story from whatever they got. The result is a sequence of attractive images that never makes an argument.
Start with one sentence. If a viewer could only remember a single line, what should it be? Write it down and treat it as a contract with your audience. Everything that does not support that sentence is a candidate for deletion, no matter how beautiful the shot is.
From there, build a beat sheet rather than a full script. A three-minute presentation usually needs five to eight beats. A 90-second version needs three or four. Each beat gets a job: establish the problem, show the stakes, demonstrate the approach, prove it works, handle the obvious objection, close with a next step. If a beat does not have a job, cut it.
Once the beats exist, write narration as spoken language, not as documentation. Read it aloud. If you stumble, the audience will too. A comfortable pace for presentation narration is roughly 140 to 160 words per minute, so a two-minute cut supports about 300 words of voiceover. That number is your real constraint. It is far more useful than a shot count.
Finally, assign a rough time budget to each beat before you generate anything. Ten seconds for the opening hook, forty for the problem, thirty for the solution, and so on. Time budgets prevent the classic disaster where the introduction runs 45 seconds and the payoff gets squeezed into eight.
Locking visual consistency across generated shots
Consistency is the single most valuable technical skill in AI video production. It is also the least glamorous. Viewers forgive imperfect realism; they do not forgive a character whose face changes between cuts.
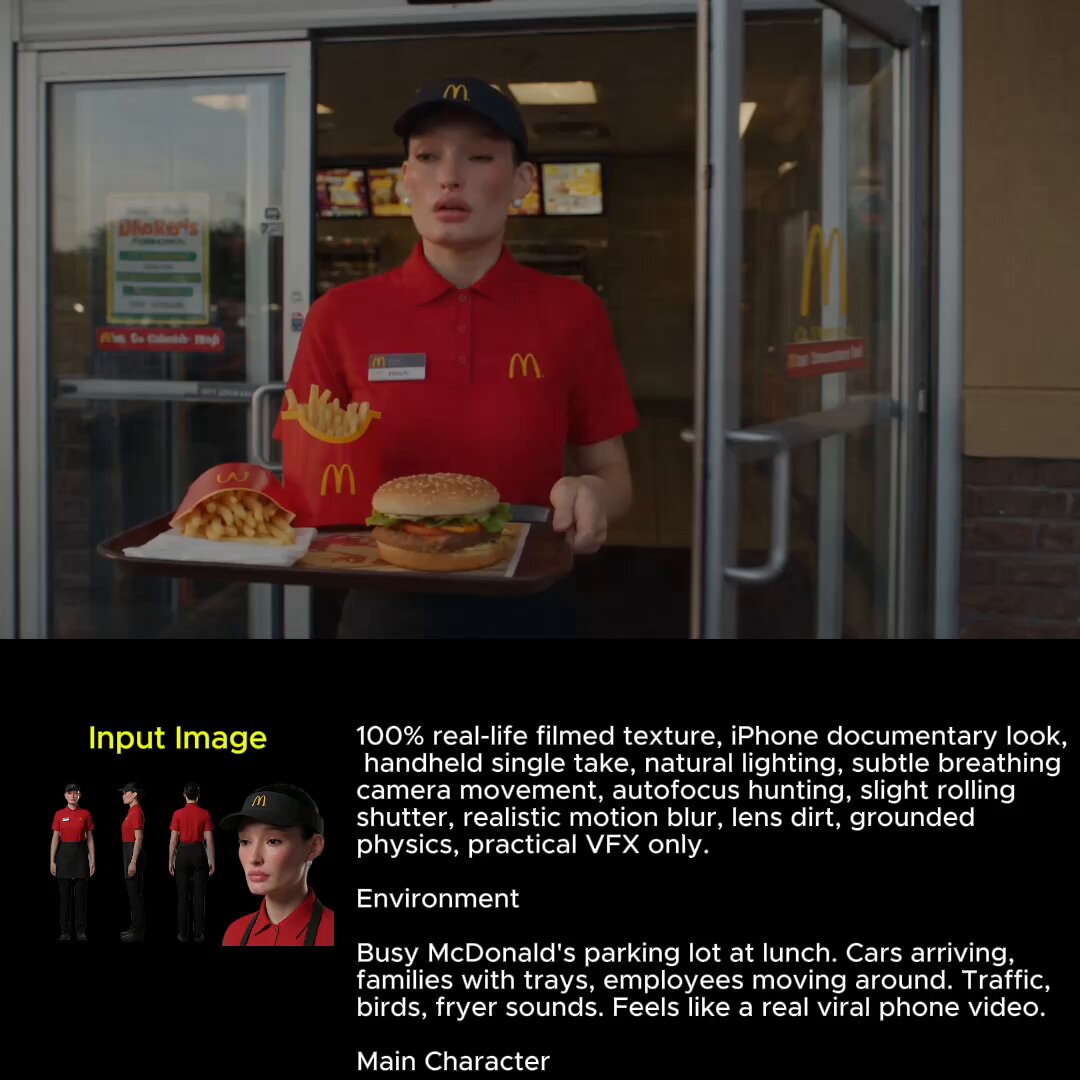
Build reference sheets first. Before generating motion, create still images of your main subject from multiple angles: front, three-quarter, profile, and a wider environmental shot. Generated stills are cheap and fast compared to video generations. Iterate on the stills until the subject feels right, then use those stills as the visual anchor for every subsequent clip. Image-to-video generation, where a still drives the motion, is far more controllable than pure text-to-video for anything with a recurring character.
Fix your style vocabulary. Write down the exact prompt language that produced your preferred look, including lighting descriptors, lens characteristics, color palette, grade, and level of realism. Reuse that language verbatim across every shot in the project. Paraphrasing between shots is how you get a sequence that drifts from cinematic to cartoonish.
Reuse environments deliberately. Instead of inventing a new location for every beat, establish two or three locations and return to them. Repeated spaces read as intentional world-building rather than visual noise. It also saves generation budget, since you can extend, re-angle, or re-light a location you already know how to prompt.
Standardize technical parameters. Aspect ratio, frame rate, and resolution should be identical across clips. Mixing a vertical generation into a 16:9 timeline means either cropping or letterboxing, and both break immersion. Decide the delivery format at the start: 16:9 for embedded presentations, 9:16 for social distribution, 1:1 only if a specific channel demands it.
Protect the grade. Even consistent generations can look like different projects once assembled. Apply one color grade, one LUT, or one adjustment layer across the full timeline. Skin tones should match shot to shot; so should the highlights. A unified grade does more for perceived production value than any individual generation.
Directing the edit: pacing, composition, and camera language
The edit is where a collection of clips becomes a presentation. Three levers matter most: shot length, composition, and camera movement.
Shot length sets energy. Average shot lengths in effective online presentations run two to four seconds during explanatory sections and six to ten seconds during emotional or summary beats. Uniform shot length is the most reliable way to make a video feel robotic. Vary deliberately: a burst of short cuts accelerates attention, then a long held shot lets the argument land.
Cut on action and on meaning. When a subject raises a hand, starts walking, or turns their head, cut at the midpoint of the movement. The motion masks the edit and the sequence feels continuous. Cutting on meaning means changing shots exactly when the narration shifts to a new idea, not three seconds later because the music felt right.
Use J-cuts and L-cuts. Let the audio of the next shot begin before its picture, or let the previous shot's sound linger over the new image. These overlaps smooth transitions between beats and are the single easiest way to make an AI-assembled video sound professionally edited.
Compose for text. Most presentations need on-screen labels, statistics, or chapter titles. Generate or select shots with negative space, usually in the upper-left or lower third, so typography does not fight the image. Busy compositions with faces dead center leave nowhere for text to live.
Respect a camera grammar. Alternating wide, medium, and close shots creates a rhythm the eye understands. A wide establishes the space, a medium carries the action, a close-up carries the emotion. Avoid the temptation of a slow push-in on every clip; when every shot moves, no shot feels significant.
Use transitions sparingly. Hard cuts are the default for a reason. Reserve dissolves for genuine time jumps and wipes for structural chapter changes. Animated transitions in an otherwise restrained presentation read as decoration rather than craft.
The audio layer: voice, music, and silence
Audio carries more perceived quality than most creators expect. A presentation with mediocre visuals and excellent sound will be watched to the end. The reverse rarely happens.
Choose between synthetic and human narration consciously. Synthetic voices are fast, cheap to revise, and perfectly consistent across languages. Human narration carries warmth, humor, and the credibility of a real person. For internal explainers, product walkthroughs, and localization into multiple languages, synthetic narration is usually the right call. For brand films, investor pitches, and anything where trust is the central message, record a human.
Direct the delivery. Whether human or synthetic, narration should breathe. Insert short pauses before key numbers and after conclusions. Add a beat of silence after a rhetorical question. If your voice tool supports it, tune stability, style intensity, and speaking rate rather than accepting defaults.
Duck the music. Background music should sit well below the voice, typically 12 to 18 dB lower in the mid frequencies, and should drop further during dense passages. Use sidechain compression or simple volume automation on the music track. If a viewer notices the music before the words, the mix is wrong.
Add sound design, not noise. A subtle whoosh on a transition, a soft click on a text reveal, or a low room tone under an interior shot all increase the sense that the video exists in a real space. Ten well-placed effects beat a continuous bed of atmospheric clutter.
Mix for the platform. Target around -14 LUFS integrated for web delivery with peaks below -1 dBTP. Check the mix on a phone speaker, not just headphones; most of your audience will watch on one.
Never ship without captions. A large share of viewers watch muted, and captions improve retention and accessibility simultaneously. Burn in captions for social cuts and provide a sidecar subtitle file for embedded players.
A repeatable production workflow
The point of a workflow is that it survives a busy week. Here is a sequence that scales from a 60-second teaser to a five-minute presentation.
Step 1: Script and beat sheet
Write the single-sentence promise, then list the beats with time budgets and narration. Read it aloud and time it. This step takes 30 to 60 minutes and saves hours downstream.
Step 2: Storyboard with stills
Generate or select one still per beat. Arrange them as a contact sheet and look at them in order. If the sequence does not tell the story as stills, motion will not fix it. Revise here, where changes cost minutes rather than hours.
Step 3: Generate and select
Generate two to four variants per shot. Keep a selection folder and delete aggressively; a bloated bin makes assembly miserable. Name files by beat number so the timeline assembles itself logically.
Step 4: Assemble and pace
Lay out the full sequence with rough audio in place. Adjust shot lengths to the narration, not the other way around. Watch the cut once with the sound off to check whether the visuals alone communicate the argument.
Step 5: Sound and polish
Record or generate final narration, add music and effects, apply the unified grade, and place typography. Then watch it three times in a row; pacing problems become obvious on repeated viewing.
Step 6: Captions and export variants
Export the master, then create platform variants: 16:9 for embedding, 9:16 for social, and a silent looping version for autoplay environments. Burn captions into the social cuts.
Quality control and iteration
Before export, run a fixed checklist. It takes five minutes and catches most embarrassments.
- Does the first three seconds contain a reason to keep watching?
- Is the main subject visually identical across every appearance?
- Does the color grade stay consistent from first shot to last?
- Is any on-screen text too small to read on a phone?
- Are narration levels consistent, with no clipping or sudden loud passages?
- Do captions match the spoken words exactly, including product names?
- Is the total runtime justified by the content, with no repeated points?
- Does the final shot include a clear next step?
- Are aspect ratios and frame rates consistent across all clips?
After publishing, measure retention rather than views. The most useful signals are the average percentage watched, the drop-off timestamp, and whether viewers reach the closing call to action. If drop-off clusters at 15 seconds, your hook or your opening pacing is the problem. If it clusters at the halfway point, you have a structural issue: a beat that does not advance the argument. Feed those findings into the next version's beat sheet, which is where real improvement happens.
Common mistakes and how to fix them
Character drift. Fix it with reference stills, image-to-video generation, and a locked prompt vocabulary. If a character still drifts, reduce the number of appearances rather than hoping the model improves.
Every shot the same length. Fix it by mapping shot durations against the energy curve of your narration. Shorten the setup, lengthen the payoff.
Narration that describes the image. If the voiceover says "here you can see a graph showing growth," the image is failing. Narration should add interpretation the visuals cannot carry alone.
A 40-second introduction. Nobody owes you their attention. Get to the promise within the first ten seconds and save the context for after the viewer is invested.
Overloaded typography. Three competing text styles in one video look amateurish. Pick one typeface, one weight hierarchy, and one animation behavior, and apply it everywhere.
Ignoring mobile framing. Text near the frame edges disappears in vertical crops and on player overlays. Keep essential content inside a generous center-safe region.
Music that fights the message. A high-energy track under a serious explanation creates dissonance. Match tempo and instrumentation to the emotional register of the beat, not to your personal playlist.
No version control. Exporting over the same filename means losing the cut your client preferred last week. Use dated filenames and keep project files with linked media in one folder.
Choosing tools and the right generation approach
Tool selection should follow your shot list, not the other way around. Different approaches solve different problems, and most projects need two or three of them.
Text-to-video is best for establishing shots, abstract concepts, backgrounds, and anything without a recurring subject. It is fast and unpredictable; treat early generations as exploration.
Image-to-video is the workhorse for character and product sequences. You control the composition in a still, then add motion. This is where you get consistency.
Avatar and talking-head tools suit training content, announcements, and localization where a presenter must speak on camera but scheduling a shoot is impractical.
Motion graphics and typography templates handle statistics, process diagrams, and lower thirds far more reliably than generated footage. Do not generate what you can design.
Editing suites matter less than people expect. Any timeline with solid audio tools, subtitle support, and color adjustment works. Pick one and learn its keyboard shortcuts; speed comes from fluency, not features.
When comparing options, evaluate four criteria: how many seconds each generation produces, how much control you get over consistency, whether the output resolution and aspect ratio fit your delivery formats, and how predictable the cost is at your expected volume. Preview quality is the least useful comparison, because every modern model looks impressive on a single hero shot and the differences only appear across a twenty-shot sequence.
FAQ
How long should a video presentation be? For a landing page or pitch, 60 to 120 seconds. For internal training, up to five minutes with clear chaptering. For a conference replacement, keep it under eight minutes and add a live Q&A. Length should be justified by information density, not by ambition.
How many generated clips do I need per minute? With an average shot length of three seconds, roughly 20 shots per minute. In practice, generate 30 to 40 candidates and discard a third.
Can I keep the same character across many shots? Yes, if you anchor every shot to a reference still and reuse identical prompt language for wardrobe, lighting, and grade. Expect to regenerate occasionally; build that into your schedule.
Do I need a human voiceover? Only if the message depends on personal trust. Otherwise a well-directed synthetic voice plus careful pacing is indistinguishable to most viewers in an explainer context.
What resolution and aspect ratio should I export? 1080p or 4K at 16:9 for embedding, 1080x1920 vertical for social, and a 1:1 or 4:5 crop for feed placements. Generate at a higher resolution than you deliver so you have room to reframe.
How do I handle client revisions quickly? Keep narration as a separate audio file, keep typography on dedicated layers, and keep all raw generations in a labeled folder. When a line changes, you swap audio and adjust two shots instead of rebuilding the timeline.
Is AI-generated footage safe for commercial use? Policies vary by tool and change over time. Check the terms of each generator you use, avoid recognizable real people and trademarked characters, and keep documentation of what you generated and where. When in doubt, replace a risky shot with stock footage or original motion graphics.
