
Why AI Video Platforms Changed the Production Cycle
For most of the last century, video production followed a fixed sequence: script, budget, crew, shoot, edit, deliver. Each step depended on physical presence and expensive coordination. AI video platforms break that chain in a specific and practical way — not by replacing cameras, but by collapsing the distance between an idea and a watchable clip.
The change is structural rather than philosophical. A solo creator can produce a product explainer, a short film intro, or a social ad in an afternoon. A marketing team can generate twenty localized variants of the same spot before lunch. What used to be a linear pipeline becomes a loop: generate, review, refine, regenerate.
That loop changes the economics of content. When each additional variant costs minutes instead of days, experimentation stops being a luxury. Teams start testing five hooks instead of one, three visual styles instead of a single locked look, and a dozen languages instead of a subtitled English master.
It also changes job descriptions. The bottleneck is no longer the ability to operate a camera or a timeline — it is the ability to direct, to define constraints, and to judge output quickly. The people who thrive in this environment are the ones who can write a clear shot list, describe a visual style precisely, and reject eight mediocre generations without losing momentum.
None of this means traditional production is obsolete. High-budget narrative work, live events, and anything requiring physical authenticity still need crews. But the vast middle of the market — explainers, ads, training content, social video, concept reels — is being rebuilt around generative tools.
What an AI Video Platform Actually Does
A modern AI video platform is less a single tool than an assembly line of specialized components stitched together behind one interface. Understanding the layers helps you evaluate any platform you are considering.
From Prompt to Timeline
The basic pipeline looks like this: you provide text, images, or both; a model generates short clips; those clips are assembled into a sequence; audio is added; the result is exported in one or more formats. Each arrow in that chain is a place where quality can succeed or fail.
Most beginners underestimate the assembly step. Generation is the visible part, but editing, transitions, pacing, and sound design determine whether the output feels like a finished piece or a demo reel.
The Layers Inside a Typical Platform
- Generation layer. Text-to-video, image-to-video, and video-to-video models that produce raw footage from prompts or references.
- Conditioning layer. Reference images, depth maps, pose data, and style embeddings that steer the model toward a specific look or subject.
- Consistency layer. Tools for keeping characters, props, and environments stable across shots — the hardest technical problem in the field.
- Audio layer. Voice synthesis, music generation, sound effects, and lip-sync alignment.
- Assembly layer. Timeline editing, transitions, captions, aspect-ratio management, and export presets.
- Management layer. Asset libraries, version history, team permissions, and review workflows.
Platforms differ enormously in how much of each layer they expose. Some give you a single prompt box and handle everything else; others let you swap models, inject references, and control sampling parameters. Neither approach is inherently better — it depends on whether you need speed or control.
Where Human Judgment Still Wins
Models are good at rendering; they are weak at deciding. They will happily generate a technically flawless shot that contradicts your brand, breaks continuity, or buries the message. The director's job is to define intent before generation and to evaluate output against that intent afterward. Everything valuable in an AI video workflow flows from that judgment.
Decision Criteria for Choosing a Platform
Features lists are easy to produce and hard to compare. These are the criteria that actually determine whether a platform fits your work.
Model Access and Routing
Some platforms bundle a single in-house model. Others route your prompt to whichever underlying model handles that task best. Comparative testing matters here: generate the same five-second prompt on two or three platforms and compare motion coherence, subject fidelity, and how well the result matches your description.
Ask two questions. First, can you switch models per shot rather than per project? Second, is there a fallback when a model fails on a specific prompt? Vendors rarely advertise the second answer.
Visual Consistency Controls
If your content features recurring characters, products, or locations, consistency tooling is the single most important differentiator. Look for reference-image conditioning, character tokens or IDs, seed locking, and the ability to reuse a style across a batch of shots.
A useful test: generate six shots of the same character in six different settings. If the face, hair, and wardrobe drift noticeably, the platform will cost you hours of manual repair later.
Audio and Language Support
Check whether voice synthesis is included or requires a separate tool. Verify how many languages and accents are supported, how natural the prosody sounds, and whether you can control pacing and emphasis. For global distribution, ask how the platform handles lip-sync in languages you do not speak — this is where many pipelines quietly fall apart.
Collaboration, Export, and Rights
Team permissions, comment threads, and version history matter as soon as more than one person touches a project. Export options matter at delivery: resolution, frame rate, aspect ratios, alpha channels, and whether captions are burned in or exported as a sidecar file.
Finally, review the licensing terms for commercial use. The rules around generated assets, input images, and voice cloning vary significantly between providers, and they are your responsibility, not the platform's.
A Practical End-to-End Workflow
This is a workflow that works for explainers, ads, training modules, and short narrative pieces. It scales from one person to a small team.
Step 1: Script and Shot List
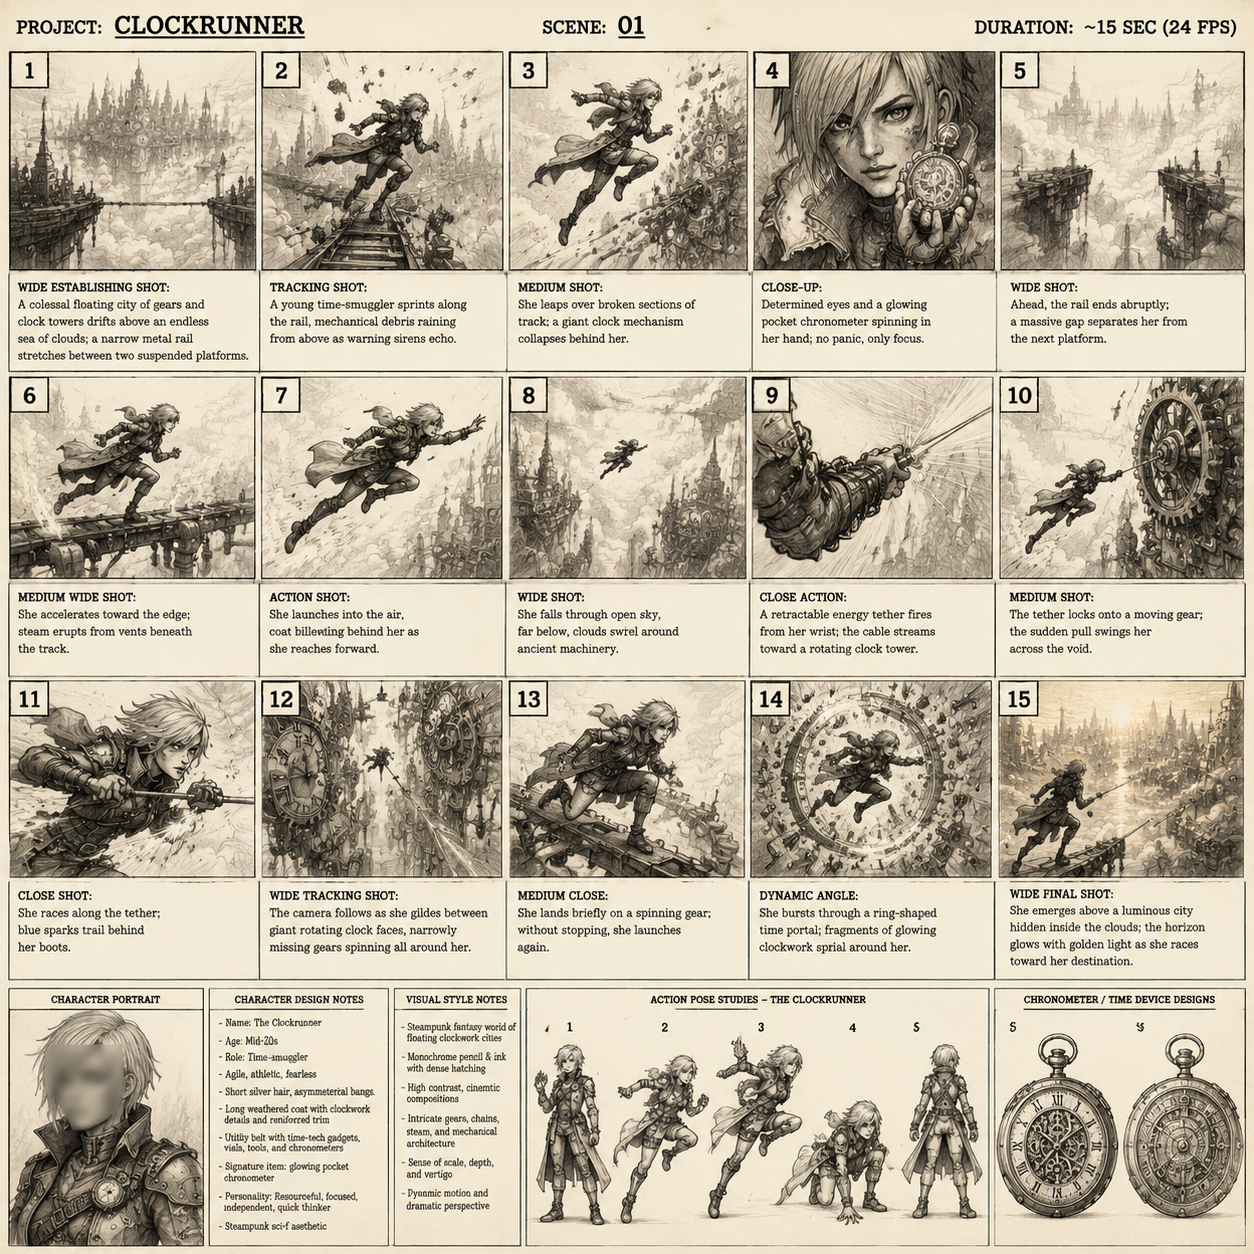
Write the script first, then convert it into a shot list before touching any generative tool. Each line in the shot list should specify the subject, the action, the camera framing, the setting, the lighting, and the duration. Vague lines like "show the product" produce vague footage.
A shot list of eight to fifteen entries is typical for a sixty-second piece. Keep each shot under five seconds unless the model you are using supports longer, stable durations.
Step 2: Build a Style Bible
Collect reference images for every recurring element: character faces, wardrobe, product angles, environments, color palettes, and lighting direction. Store them in one folder and reuse them consistently. This single habit prevents more continuity errors than any parameter tweak.
Write down a short style descriptor — for example, "soft daylight, muted teal and warm beige palette, shallow depth of field, 35mm feel." Paste the same descriptor into every prompt. Consistency in your inputs produces consistency in your outputs.
Step 3: Generate in Shots, Not Scenes
Generate each shot independently, and generate four to six variants of each. Choose the best, then move on. Resist the urge to fix a shot by endlessly rerolling; if three rounds of variants miss, the prompt is the problem, not the model.
Keep a naming convention: shot-03-v2-characterA-daylight. It sounds trivial until you have two hundred clips and no idea which one you approved.
Step 4: Assemble, Score, and Polish
Bring approved clips into a timeline in shot-list order. Cut for pacing first, then add music, then add voice, then adjust timing to the voice. Doing it in this order saves rework, because music has more flexibility than spoken dialogue.
Add transitions sparingly. Generative footage often has subtle motion inconsistencies, and a hard cut hides them better than a flashy transition. Color-correct in a final pass to unify shots generated at different times.
Step 5: Version for Each Channel
Once the master is locked, create variants: vertical for short-form, square for feed placements, horizontal for web. Re-crop rather than regenerating whenever possible, and adjust captions for each aspect ratio. If the platform supports batch export presets, set them up once and reuse them.
Solving Visual Consistency
Consistency is where AI video projects succeed or fail, and it deserves its own process.
Reference Images and Multi-Image Conditioning
The most reliable technique is to condition each generation on one or more reference images. A single reference locks appearance; multiple references — for example, a face plus a wardrobe shot plus an environment — give the model richer context and reduce drift.
Style Transfer and Pixel-Level Control
When you need a specific aesthetic, style transfer or pixel-oriented conditioning beats descriptive prompts. Instead of writing "in the style of a watercolor painting," supply an actual frame and let the model extract the palette and texture. The same logic applies to brand assets: feed the logo, the packaging, the website screenshot.
Fixing Flicker and Identity Drift
If a shot flickers, reduce motion complexity, shorten the duration, or lower the intensity of camera movement. If a character's face drifts across shots, regenerate the drifted shots using a stricter reference set, and avoid extreme angles where the model has less training data.
Practical safeguards: keep wardrobe distinctive, avoid reflective surfaces near faces, and maintain a consistent light direction across a scene. Small production-design decisions have outsized effects on model stability.
Audio, Voice, and Lip Sync
Audio is the second half of perceived quality. Viewers forgive imperfect visuals far more readily than robotic narration.
Voice Synthesis That Sounds Human
Use synthesized voices with deliberate pacing rather than default settings. Short sentences, natural pauses, and slight variation in emphasis do more for realism than any voice model upgrade. If the platform supports it, generate the narration in segments so you can re-record a single line without regenerating the whole track.
Music and Sound Design
Generated music works well as a bed when you keep it low in the mix and cut it to the emotional beats of the piece. Add diegetic sound effects — footsteps, room tone, clicks — even if they are barely audible. Their absence is what makes AI video feel sterile.
Lip Sync in Multiple Languages
If you are localizing, decide early whether you will dub, subtitle, or regenerate lip movement. Each has a cost: dubbing preserves the original performance but risks mismatch, subtitle-only is cheap but reduces engagement on mobile, and regenerating lip sync looks best but requires re-timing the edit for each language.
Common Mistakes and Troubleshooting
Overloading a single prompt. Long prompts with ten requirements produce muddled output. Split complex ideas into multiple shots.
Generating before planning. Teams that skip the shot list end up with beautiful clips that cannot be edited into a coherent story.
Ignoring aspect ratio. Vertical-first content cropped from horizontal footage loses framing. Generate or compose with the target ratio in mind.
Chasing perfection on a single shot. If a shot resists five rounds of iteration, restructure the scene so the difficult element is off-screen or implied.
Skipping version control. Keep approved clips in a separate folder. Never overwrite a good generation.
Neglecting captions. Most short-form video is watched muted. Plan captions as part of the design, not an afterthought.
Assuming one model fits all. Some models excel at realistic humans, others at stylized animation. Match the model to the shot.
Team, Cost, and Scaling Decisions
Generative video changes how you staff a project. A typical small team now consists of a director or creative lead who owns the vision, a prompt and pipeline operator who runs generation and maintains the asset library, an editor who assembles and polishes, and a reviewer representing the brand or client.
One person can cover all four roles on small projects, but the handoff points are where quality drops. Write down who approves a shot and at what stage; ambiguity is expensive when generations are cheap.
Budget planning should focus on iteration volume rather than per-clip pricing alone. The real cost driver is how many variants you generate per approved shot. Teams that plan carefully typically need three to six variants per shot. Teams that improvise can burn through dozens.
When scaling, standardize before you accelerate. A locked style bible, a naming convention, and a fixed export preset list let you add people without adding chaos. Without them, five creators produce five inconsistent looks.
FAQ
Do I need a powerful computer? No. Most platforms run generation in the cloud; you need a stable browser and decent bandwidth. Local tools exist but demand serious GPUs.
How long should a generated shot be? Three to five seconds is the sweet spot for stability. Longer shots often accumulate artifacts.
Can I use generated footage commercially? Usually yes, but terms differ by provider and by input asset. Verify licensing before publishing, especially when real people appear in reference images.
What is the biggest quality bottleneck? Consistency across shots, not raw image quality. Plan for it explicitly.
How do I keep characters recognizable? Use reference images, a fixed style descriptor, seed locking where available, and consistent lighting and wardrobe.
Is it worth generating audio in-platform? Yes when it keeps timing aligned with visuals. Export to a dedicated audio tool when you need fine control.
How many shots for a one-minute video? Twelve to eighteen, depending on pacing. Faster cuts need more shots.
What should I learn first? Shot listing and reference curation. These two skills improve output more than any model upgrade.
Where This Is Heading
The direction of travel is clear: more control, longer coherent sequences, and tighter integration between generation and editing. Expect reference conditioning to become standard rather than a premium feature, and expect audio to be generated alongside video in a single pass.
For creators, the practical implication is that tool-specific knowledge depreciates quickly while workflow knowledge compounds. Learning to write a shot list, build a style bible, evaluate output critically, and assemble a coherent edit will remain valuable regardless of which platform leads next quarter.
The teams that win will not be the ones with access to the most models. They will be the ones with a repeatable process that turns an idea into a finished, on-brand video in hours — and then does it again tomorrow, consistently.
