
Why the gap between an idea and a finished video keeps shrinking
For most of the history of moving images, the distance between a concept and a finished cut was measured in weeks or months. You needed a camera, a crew, a location, lighting, performers, a sound recordist, an editor, and a colorist. The idea itself — the twenty seconds of story that made the whole thing worth watching — was almost the cheapest part of the process.
Generative video has compressed the middle of that pipeline dramatically. A creator working alone can now move from a written beat to a moving image in an afternoon, and from a folder of clips to a watchable cut by the end of the week. That does not make craft irrelevant. It moves the bottleneck: instead of asking whether something can be shot, you ask whether the shot is worth keeping, and whether it matches the eleven shots around it.
This guide is a practical walkthrough of that new pipeline. It is written for people who already make things — short-form editors, brand storytellers, indie animators, product marketers, teachers — and who want a repeatable process rather than a pile of one-off tricks. We will cover how to structure a project, how to choose between model families for different shot types, how to hold a character's face steady across a sequence, how to prompt for believable motion, and how to finish. Nothing here depends on a single platform. The workflow is intentionally tool-agnostic so you can move between engines as they improve.
Mapping the workflow: six stages from concept to delivery
A reliable AI video project is not a single prompt. It is six stages, each with its own deliverable and its own quality gate. Skipping a stage rarely saves time; it usually means re-generating clips later at a much higher cost in effort.
Stage 1 — Concept and creative brief
Write one paragraph: who watches this, what changes for them, and what the final frame should feel like. Then write the constraint line: target length, aspect ratio, delivery platform, and whether dialogue is required. These constraints determine almost every downstream choice, including which models are even viable. A nine-by-sixteen vertical need rules out compositions built for wide landscapes; a dialogue-led scene pushes you toward lip-sync capable tools.
Stage 2 — Script and shot list
Convert the idea into a numbered shot list before generating anything. A useful shot list has six columns: shot number, duration in seconds, subject, action, camera, and audio note. This is the document you will live in. When a clip fails, you return to the row and rewrite it — not to the model's settings panel.
Keep individual shots short. Three to six seconds is the sweet spot for most generative engines, because longer clips accumulate drift in faces, hands, and background geometry. Long takes are assembled in the edit, not generated in one pass.
Stage 3 — Look development
Generate five to eight still frames that establish palette, lighting direction, lens character, and texture. Approve them before you spend time on motion. Stills are fast and cheap to iterate; motion is where the time goes. A locked look also gives you consistent reference images to feed into image-to-video steps, which is the single largest lever on visual continuity.
Stage 4 — Generation
Now produce clips, in shot-list order, with a naming convention that survives the edit. Something like sc03_sh04_take2_v3 beats output_final_really.mp4. Generate two to four takes per shot and stop at the first one that works. Perfectionism in the generator is almost always slower than perfectionism in the edit.
Stage 5 — Assembly and sound
Bring everything into an editor, lay the sequence against temporary music, and cut for rhythm before you cut for picture perfection. Most weak AI video is weak because the pacing is wrong, not because a hand had six fingers for eight frames.
Stage 6 — Delivery and versioning
Export masters at the highest practical resolution, then create platform versions: square, vertical, and widescreen. Keep a project file with ungraded layers so you can re-export when a platform updates its specs.
Choosing the right generation model for each shot type
Different shots need different engines. Treating every shot as a text-to-video problem is the most common source of wasted effort.
Text-to-video
Best for establishing shots, abstract transitions, backgrounds, and any frame where no specific person must be recognizable. It is the fastest way to explore tone. Use it early, during look development, and use it late for inserts.
Image-to-video
This is the workhorse of any project with recurring characters or a defined set. You generate or photograph a strong still, then animate it. Because the first frame is fixed, you control composition, wardrobe, and framing precisely. Most sequences in a narrative piece should be built this way.
Video-to-video, motion transfer, and performance reuse
When you need a specific movement — a dance step, a gesture, a walk cycle — driving motion from reference footage gives far more control than describing it in text. This is also the cleanest path to restyling existing footage without reshooting it.
A comparison framework
When evaluating any engine for a given shot, score it on five axes:
| Criterion | What to check |
|---|---|
| Motion realism | Does movement carry weight, or does it float? |
| Identity retention | Does the face hold across 4+ seconds? |
| Prompt adherence | Does the camera instruction actually land? |
| Texture quality | Is there film grain, or a waxy plastic sheen? |
| Iteration speed | How fast is a take, and how predictable are changes? |
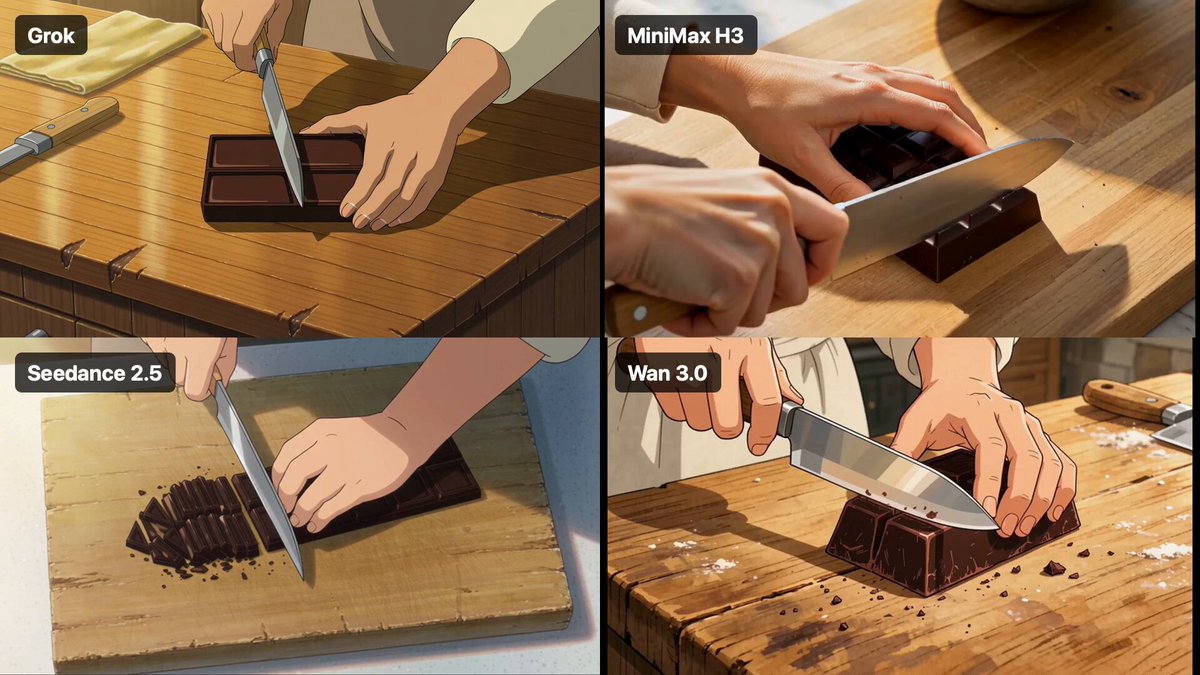
Run the same three-sentence prompt through two or three engines on a test shot before committing a whole project to one. The differences show up fast and they are not subtle.
The hardest problem: character consistency across shots
Ask anyone who has built a narrative sequence with generative tools what broke first, and the answer is almost always the face. Shot four looks like the actor; shot nine looks like the actor's cousin after a long flight.
Build a reference sheet before you generate
Create a canonical reference set: one clean front-facing portrait, one three-quarter view, one profile, and one full-body frame in the hero wardrobe. Neutral background, even lighting, no dramatic shadows. These images become the anchors you feed into every image-to-video step. Consistency starts with a boring, well-lit reference — not with a beautiful, moody one.
Identity locking in practice
Where an engine supports reference images or identity conditioning, use two anchors per shot: the face reference and a wardrobe or environment reference. Keep the reference set fixed for the whole sequence. Swapping references mid-project is the fastest way to create drift, and it is surprisingly easy to do by accident when you are iterating quickly.
Editing your way out of drift
Not every inconsistency needs a regeneration. Cutting on motion, using a close-up of hands or an object, or inserting a reaction shot can hide a face mismatch entirely. Reserve regeneration for the shots where the character's identity is the point of the frame.
When to accept a reshoot
If a shot drifts beyond repair after three takes, change the shot. Convert a medium shot into a wide, or an over-the-shoulder into a detail insert. Rewriting the shot list is usually faster than fighting a stubborn generation.
Prompting for motion: what actually changes the output
Most prompting advice focuses on adjectives. In practice, structure matters more than vocabulary.
Describe the camera, not the feeling
"Cinematic" is a mood word. "Slow dolly in, 35mm, shallow depth of field, eye level" is an instruction. Use both, but lead with the instruction. Specify camera movement, lens feel, framing height, and depth of field as separate clauses.
Keep subject, action, and setting clauses separate
A prompt of the form subject — action — setting — camera — light is easier to debug than a flowing sentence, because when a take fails you can identify which clause caused it. If the lighting is wrong, change the light clause. If the motion is wrong, change the action clause. Do not rewrite the whole prompt.
Negative prompts and what to avoid
Use negative prompts sparingly and specifically: warped hands, text artifacts, extra limbs, flickering. Long generic negative lists tend to hurt more than help. If a specific artifact keeps appearing, name it; otherwise leave the field empty.
Iteration discipline
Change one variable per take. Two changes at once give you information you cannot use. Keep a running log of prompt, seed, and result for at least the hero shots — when a take works at 2 a.m., you will want to reproduce it at 9 a.m.
Audio, voice, and timing
Sound is where AI-assisted video projects most often collapse, because creators treat it as the last ten percent when it is closer to half of perceived quality.
Voice generation and lip sync
Generate dialogue first, then build the shot to it. Writing a line and animating a mouth to match afterwards is possible, but working from the audio gives you natural timing and lets you trim the visual to the performance instead of the reverse. Keep lines short — under twelve words per shot — because long utterances amplify sync drift.
Music and sound design
Lay a temporary music bed before you finish the picture edit. Rhythm dictates where cuts feel right. Add ambience and effects per shot rather than over a whole sequence; a room tone that continues across a scene change is one of the most common tells of an assembled-from-clips project.
The timing trap
Generated clips do not come with handles. If your editor needs two extra frames to land a cut, you may not have them. Generate at least half a second more than you need on every shot, and plan to trim in the edit rather than extend.
Editing and finishing: where clips become a video
The rough-cut pass
Assemble all approved clips in shot order with no transitions. Watch it once at double speed. If the story does not read at double speed, no amount of polish will fix it.
Color, grain, and texture matching
Generated clips from different engines will not match out of the box. Apply a shared base grade — slight contrast curve, consistent white balance, unified saturation — and then a light grain or texture layer over the whole timeline. The grain layer does more for cohesion than any individual shot correction.
Transitions that hide model seams
Cutting on movement, using a whip pan, or briefly pushing to a detail shot are all more effective at hiding a mismatch than a dissolve. Reserve dissolves for genuine time passage.
Delivery specs
Confirm resolution, frame rate, bitrate, and audio loudness targets for each destination before export. Loudness normalization in particular is where otherwise professional sequences fall apart on mobile feeds.
Common mistakes and how to avoid them
- Generating before the shot list exists. The result is a folder of attractive clips with no order.
- Chasing one perfect take. Three good takes beat one heroic take on almost every schedule.
- Ignoring the first frame. In image-to-video, the still is the shot. Fix it before animating.
- Changing references mid-sequence. This is the number one cause of identity drift.
- Skipping temporary audio. Silence makes bad pacing invisible until it is expensive to fix.
- Exporting only one aspect ratio. Re-framing later costs more than planning two exports up front.
- Trusting a single engine for everything. Each has a shot type it handles better.
A practical one-week project plan
Day 1 — Brief and shot list. Lock length, ratio, tone, and a numbered shot list. Nothing gets generated today.
Day 2 — Look development. Produce and approve five stills. Write the prompt template you will reuse.
Day 3 — Reference set and principal photography. Generate the character reference sheet, then work through roughly half the shot list.
Day 4 — Remaining shots and pickup takes. Finish generation and immediately regenerate only the shots that failed hard.
Day 5 — Sound first, then edit. Generate or record voice, lay temp music, build the rough cut.
Day 6 — Finishing. Grade, grain, transitions, loudness, exports.
Day 7 — Review and version. Watch on a phone, a laptop, and headphones. Fix only what a viewer would notice.
This plan assumes a piece in the sixty-to-ninety-second range. Double the generation days for anything over three minutes, and expect the reference and look stages to stay fixed in length regardless of runtime — they are the cheapest insurance in the process.
Frequently asked questions
How many takes should I generate per shot?
Two to four for most shots, more only for hero frames. If four takes fail, the prompt or the reference is wrong, not the seed.
Can I mix engines in one project?
Yes, and you probably should. Keep the reference set identical across engines and unify the grade in post. The grain and color pass is what makes mixed sources read as one piece.
Do I need to draw or photograph references myself?
No, but you need references that are consistent with each other. Four portraits with different lighting will produce four different-looking characters.
How long should a generated clip be?
Three to six seconds for anything with a face or hands. Longer for landscapes and abstract motion, where drift is less visible.
What resolution should I generate at?
As high as your workflow comfortably allows at the time. You can always downscale for delivery; you cannot recover detail that was never generated.
Is a storyboard still necessary?
More than ever. The shot list is what keeps a generative project from becoming a collection of unrelated pretty frames.
How do I keep costs predictable?
Fix the shot list, lock the look, and finish each shot in as few takes as possible. Most budget overruns come from exploring inside the generation stage instead of during look development, where iteration is cheap.
What is the single biggest quality upgrade for a beginner?
Adding a shared grain and color pass over the finished timeline. It costs one adjustment layer and changes how professional the result feels more than any individual clip.
