
Why Consistency Is the Real Bottleneck in AI Video
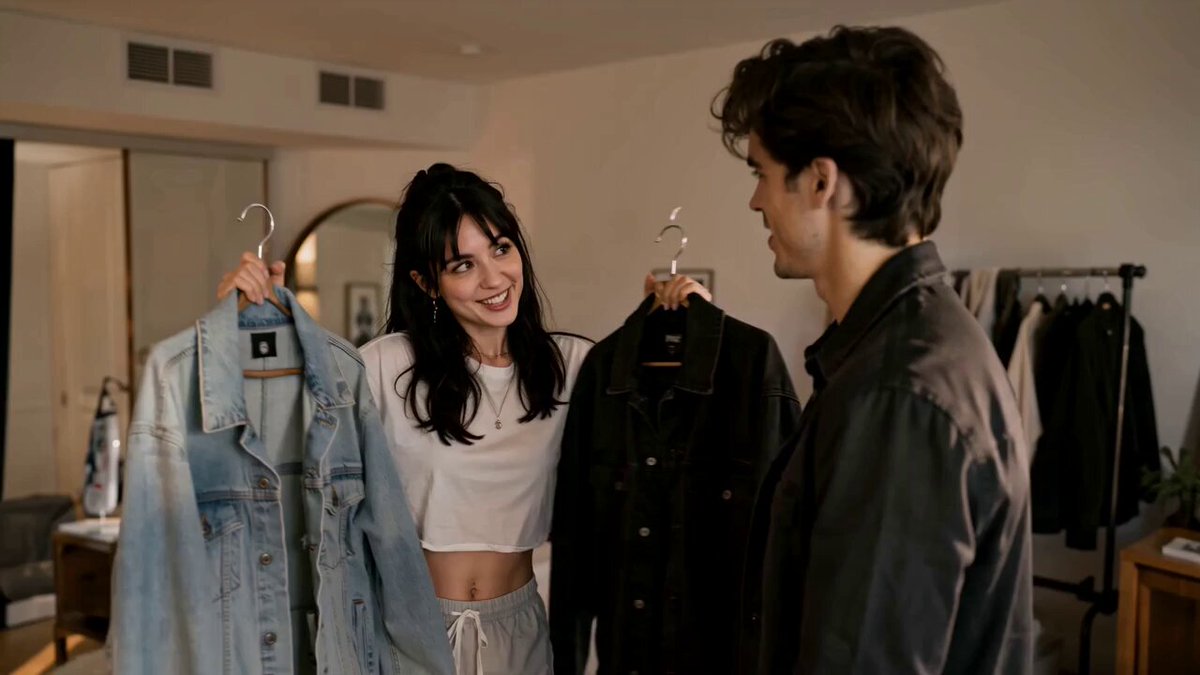
Generating one impressive clip stopped being impressive a while ago. Any modern text-to-video model can produce a striking three-second shot of a lighthouse in a storm or a cyclist in neon rain. What almost none of them can do on their own is deliver the same lighthouse, in the same light, from the same angle, twenty shots later — with the same cyclist wearing the same jacket.
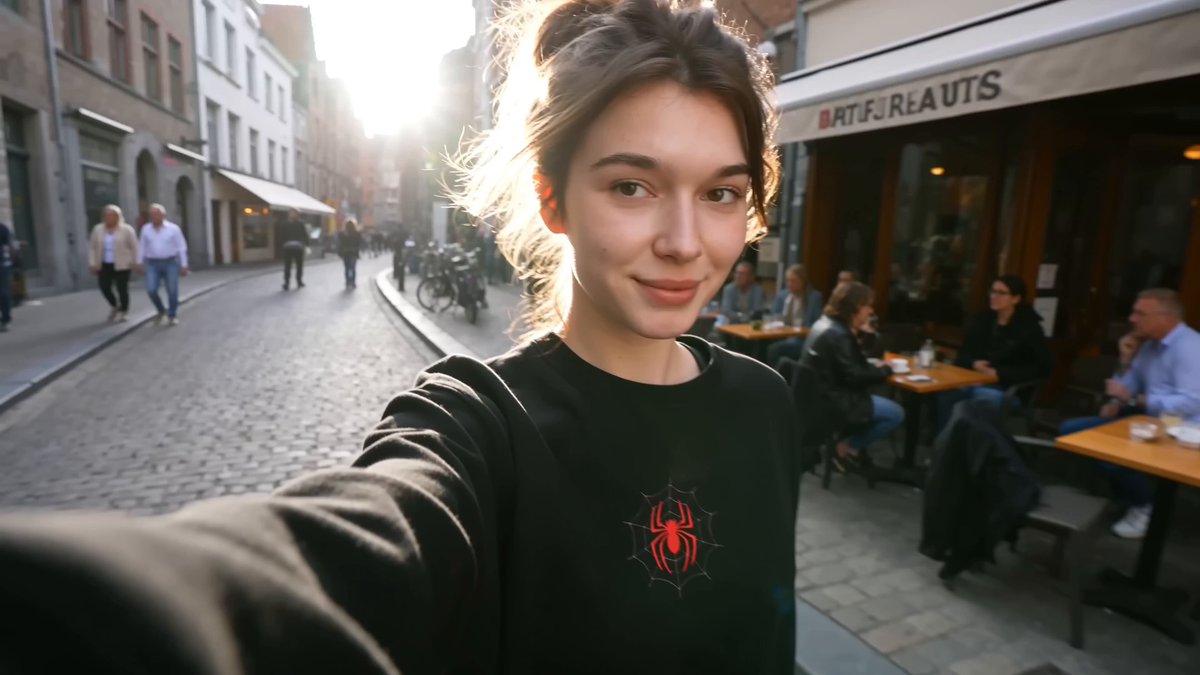
That gap between “a good clip” and “a good sequence” is where most AI video projects die. Viewers are forgiving about resolution, grain, and even slightly uncanny motion. They are not forgiving about identity. If a character’s jawline changes shape between two shots, or the hero jacket shifts from olive to teal, the audience reads it as a mistake, and the perceived production value collapses.
This is why consistency is a systems problem rather than a prompt problem. Diffusion-based video generation samples from a probability distribution on every run. Nothing inside the model remembers your previous output. Continuity exists only if you engineer it: through locked references, controlled sampling, structured shot planning, and a review loop that catches drift before it reaches the timeline.
The practical consequence is a shift in where your hours go. On a poorly planned project, most of your time disappears into re-rolling shots that almost worked. On a well-planned one, the same hours go into writing, shot design, and final polish. The rest of this guide is about moving your project into the second category.
What Consistency Actually Means Across a Shot List
“Consistent” is not one property. It is at least five, each with its own failure mode and its own fix.
Character Identity
Facial structure, hairline, apparent age, skin tone, body proportions, distinguishing marks. The failure mode is gradual drift: each shot is two percent different from the last, and by the end of the sequence you are watching a stranger. The fix is a locked reference set, identity-conditioned generation, and a firm rule that no shot is approved without a side-by-side comparison against the anchor frame.
Wardrobe, Props, and Set Dressing
Zipper direction, logo placement, which wrist carries the watch, the colour of a mug, the number of chairs at a table. These produce silent continuity errors that read as carelessness. Keep a prop and wardrobe inventory and describe items at the level of materials and construction rather than vague adjectives. “Charcoal wool overcoat with horn buttons, collar up” travels much further than “nice coat”.
Lighting, Colour, and Grade
Time of day, key direction, colour temperature, contrast ratio. When these drift, shots look like they belong to different films. Define a lighting grammar per scene, generate a small set of look-up frames, and grade the finished sequence through shared look-up tables so the whole piece lands on one palette.
Camera and Lens Language
Focal length, camera height, framing distance, movement. Random angles never establish geography, and a sequence of unmotivated framings feels amateurish regardless of image quality. Shot cards that explicitly state lens, height, framing, and movement solve most of this before you generate a single frame.
Motion, Pacing, and Physics
Walk cadence, gesture size, clip duration, cut rhythm. Characters who move at different speeds in consecutive shots break the illusion instantly. Describe speed, weight, and direction in the prompt, and keep motion language identical within a scene.
Rank these by how quickly an audience notices them. Identity errors register in under a second. Lighting mismatches take a couple of shots. Wardrobe details often go unnoticed until someone pauses the video — but when they do pause it, those details matter. Spend your effort in that order.
The Core Techniques Behind Stable Generation
Seed Locking and Deterministic Sampling
Most image and video models accept a seed value that fixes the starting noise. The same seed with the same prompt, model version, resolution, and settings reproduces the same output. Change any one variable and the result changes too — so a seed is a bookmark, not a guarantee. The useful habit is a seed family: one seed for the master character look, with small variations for different poses and expressions. Log the seed, model version, and resolution next to every approved shot.
Reference Images and Multi-Image Fusion
This is the highest-leverage technique available. Instead of describing a character in words, you supply images and let the model blend identity features across them. A strong reference set usually contains a neutral front-facing portrait, a three-quarter view, a profile, a full-body shot, and two or three expression variations — all in similar lighting, with clean backgrounds and consistent crop. Contradictory references (different hairstyles, heavy shadows in one image, strong stylisation in another) confuse the blend and produce a face that resembles all of them and none of them.
Style Frames and Look-Up Decks
Generate and approve still frames before generating motion. Six to ten approved frames that define palette, contrast, texture, and composition become a visual contract for the scene. When a later shot drifts, you have something concrete to compare against instead of a memory.
Motion Transfer and Temporal Conditioning
Controls such as pose, depth, and optical flow let you drive a generated shot from a reference performance. First-and-last-frame conditioning is equally valuable: pin the opening and closing images and let the model interpolate the movement between them. Both techniques cut down dramatically on drift compared with pure text prompting.
A Practical Workflow: From Script to Locked Sequence
Step 1 — Break the Script Into Shots
Write a shot card for every beat before generating anything. A useful card has eight fields: shot number, target duration, subject, action, camera (lens, height, movement), lighting, background, and audio cue. This single document eliminates most ambiguity later and gives you a checklist for review.
| Field | Example | Why it matters |
|---|---|---|
| Lens | 40mm, eye level | Prevents perspective jumps between adjacent shots |
| Movement | Slow push in | Keeps energy consistent within a scene |
| Lighting | Overcast side key, cool | Anchors the lighting grammar |
| Duration | 4s | Controls pacing and cut rhythm |
Step 2 — Build a Character Bible
For each recurring character, write a fixed descriptive block (age range, build, hair, wardrobe, mannerisms), a negative list of things that must never appear, and a folder of approved reference images. Then define wardrobe sets: Set A for the first act, Set B for the second. When a costume changes, generate fresh references for that set rather than typing “now wearing a different jacket” into the prompt — text-only wardrobe changes are the most common source of drift.
Step 3 — Generate Anchor Frames First
Produce stills, not video. Approve a hero frame per character and per location. Work in batches by scene so you can judge a group of images together rather than in isolation. Only once a scene’s stills look like one coherent world should you move into motion.
Step 4 — Produce First-Pass Shots in Priority Order
Start with the shots that establish identity and geography: the first clear look at the protagonist, the establishing wide, the key reaction. These become your reference points. Generate coverage after them, and use image-to-video from approved stills wherever possible. Animating an approved frame is far more controllable than prompting a fresh shot from text.
Step 5 — Review Against the Continuity Sheet
Build a contact sheet of every approved shot and scan it in sequence. Check face shape, hairline, wardrobe, hand props, colour temperature, and horizon lines. When a shot fails, mark it as a re-roll rather than trying to fix it in post — drift is easier to prevent than to repair.
Step 6 — Assemble, Grade, and Stabilise
Edit first, then grade. Cut on motion where possible to hide small imperfections, apply a shared grade across the sequence, add subtle grain to unify texture, and stabilise any handheld-style shots. Temporal flicker is normal in generated footage; a deflicker or motion-blur pass often does more for perceived quality than another round of generation.
Building a Reference Kit That Survives Scene Changes
A reference kit is a reusable asset, not a one-off prompt. Build it once and it will serve every future project with the same character.
- Volume: five to eight images per character. Fewer than four and the model has too little to work with; more than ten usually introduces contradictions.
- Lighting: soft, even, front-facing light. Heavy shadows bake unwanted lighting into the identity.
- Background: plain or very simple. Busy backgrounds leak visual noise into the blend.
- Expression range: one neutral, then subtle variations. Avoid extreme expressions in the core set.
- Resolution and crop: consistent across the whole set, with the head roughly the same size in frame.
- Labelling: name files so the subject, wardrobe set, and view are obvious at a glance.
Keep a plain text file of prompt blocks alongside the images. Copy-pasting a verified paragraph beats retyping a description from memory, and it keeps your language stable across sessions.
Choosing Tools Without Locking Yourself In
No single tool wins everything, and the honest answer is that most serious projects use three or four together. Instead of chasing brand names, evaluate tools against capabilities you actually need.
| Capability | Why it matters | How to test it |
|---|---|---|
| Reference image input | Identity control | Feed a character sheet, check face retention |
| First/last frame control | Predictable action | Pin two frames, judge the interpolation |
| Seed control | Reproducibility | Re-run with identical settings |
| Clip length | Fewer seams | Generate one long shot, look for drift |
| Resolution and upscaling | Delivery quality | Stress-test close-ups |
| API or batch access | Volume work | Automate a ten-shot batch |
| Export and licensing terms | Commercial safety | Read the fine print before launch |
The broader landscape splits into a few categories worth understanding. Text-to-video models are fastest for exploration and weakest for continuity. Image models are best for anchor frames and look development. Controllable pipelines — pose, depth, and identity conditioning wired together in a node-based interface — give the most control but require setup time. Post-production tools handle deflicker, stabilisation, upscaling, and grading, and they are non-negotiable for anything longer than thirty seconds.
A practical strategy is to keep generation modular: approve stills in one tool, animate in another, finish in a third. Locking your entire workflow to a single platform makes consistency easier in the short term but harder to recover when a model version changes underneath you.
Common Mistakes and How to Fix Them
Prompt-Level Mistakes
- Describing instead of referencing. Words cannot carry a face. Supply images.
- Overloading the prompt. Five subjects, three actions, and a camera move in one sentence produces mush. Split the shot.
- Inconsistent adjectives. “Cinematic” in one shot and “moody documentary” in the next guarantees a tonal break. Standardise your vocabulary.
Pipeline-Level Mistakes
- Mixing model versions mid-project. A version update can shift faces noticeably. Finish a sequence on one version where possible.
- Generating video from text when a still would do. Image-to-video is almost always more stable.
- Ignoring aspect ratio. Reframing after generation softens detail and crops composition you already approved.
Review-Level Mistakes
- Approving shots in isolation. A face that looks right alone may not match the one before it. Always review in sequence.
- Fixing in post what should be re-rolled. Colour corrections cannot restore a changed nose.
- No continuity sheet. Without a written record, you are relying on memory, and memory fails around shot twelve.
Quality Control Checklist Before Publishing
Run every project through the same gate before you export.
- Face and body match the anchor frame across all shots.
- Wardrobe, accessories, and props are consistent within each scene.
- Colour temperature and contrast are uniform across the sequence.
- Camera height and lens feel stable between adjacent shots.
- Motion speed and direction do not jump at cuts.
- No visible flicker, warping, or limb artefacts in close-ups.
- Audio, if present, matches the pacing of the cut.
- The opening three seconds establish the character clearly.
- Exports meet the platform’s resolution and aspect ratio requirements.
- A fresh viewer watches it once without pausing and reports no confusion.
FAQ
How many reference images do I actually need per character?
Five to eight is the sweet spot. Three is workable for a single shot but fragile across a sequence. Beyond ten, contradictions between images tend to blur identity rather than sharpen it.
Can I keep a character consistent across different locations?
Yes, and it is easier than most people expect — provided you change only one variable at a time. Keep the reference set and the prompt block fixed, then alter the location description. If identity drifts when the background changes, your reference images likely contain too much environmental detail.
Why does my character look right in stills but wrong in motion?
Motion models add temporal layers that reinterpret identity. Generate the still in the same model family you will animate with, and use first-frame conditioning so the clip starts from the approved image rather than a fresh interpretation of the prompt.
Do I need a different seed for every shot?
No. Start from a single master seed for the character and vary it only when a pose or expression demands it. Log every variation so you can return to a known-good state.
How do I handle a wardrobe change mid-story?
Treat it as a new character state. Generate a new reference set for the outfit and label it clearly, rather than describing the change in text. This one habit prevents the most common continuity error in AI video.
Is it worth learning a node-based pipeline?
If you produce episodic or client work at volume, yes. The setup cost pays back within a few projects. For one-off social clips, simpler tools with strong reference support are usually sufficient.
How long should a generated shot be?
Keep most shots between two and five seconds. Longer clips accumulate drift, and shorter clips cut on motion more easily, which hides small imperfections.
Key Takeaways
Consistency is engineered, not prompted. Approve stills before motion, lock references and seeds, describe wardrobe and props as fixed assets, review in sequence rather than in isolation, and finish with a shared grade. Do those five things and your AI-generated sequences will hold together the way an audience expects a real production to — which is exactly what separates a demo from a deliverable.
