
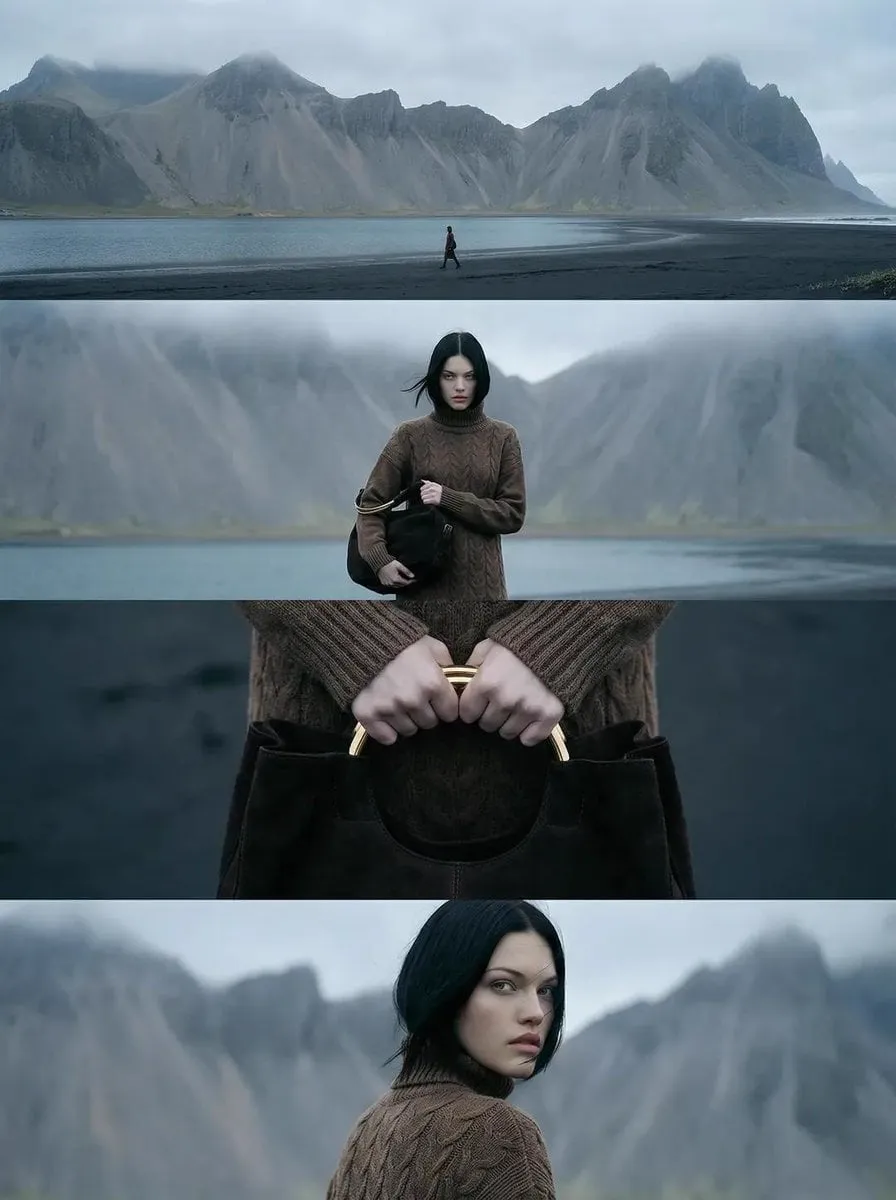
AI video generation has moved from novelty to daily practice. The interesting question is no longer whether a model can turn a sentence into moving pixels, since it clearly can. The real question is which model, prompted how, edited where, and for which shot. Teams that treat model choice as one permanent decision hit a ceiling fast. Teams that treat it as a workflow decision ship work that looks deliberate rather than generated.
This guide is deliberately tool-neutral. It covers how to evaluate model families, how to combine several of them inside one timeline, how to prompt for motion instead of appearance alone, and how to repair the failure modes that appear again and again in AI video production.
The shift from one model to a stack
Early AI video work meant one model and one output. You typed a prompt, waited, and accepted whatever came back. The result could be striking in isolation and completely unusable inside a sequence, because nothing matched: lighting drifted, faces changed between cuts, and the camera language reset every few seconds.
Modern practice looks more like a small production pipeline. A thirty-second scene might use a photoreal model for the establishing shot, a stylized model for a dream sequence, an image-to-video pass to lock a specific face, and a motion-transfer pass to drive a walk cycle. Each tool does what it does best, and the editor stitches the results into something coherent.
Three consequences follow. First, fit matters more than benchmark scores, because the highest-rated model on a leaderboard can still be the wrong model for a talking-head shot. Second, prompting becomes a translation skill: the same idea has to be expressed in cinematography language for one tool and in plain descriptive prose for another. Third, continuity becomes your main engineering problem, and most of it gets solved outside the generator, in the edit.
Treat your available models like a lens kit. You would not shoot an entire film on a wide-angle lens just because it looks impressive.
Four levers that decide AI video quality
Before comparing tools, it helps to separate the four things that actually determine whether a clip works. Most disappointed creators blame the model when the real problem sits in one of the other three.
Model family and training bias
Every model carries a bias. It has seen a certain kind of footage during training and it reproduces that look by default. Some families excel at cinematic realism with shallow depth of field. Others are stronger at illustration, anime, or studio product lighting. Choose the family whose default output already resembles your target look, because that decision saves hours of correction later.
Prompt specificity
A prompt is not a wish, it is a specification. Vague prompts produce generic motion: slow push-ins, drifting crowds, hair moving in a breeze that nothing else in the frame responds to. Specific prompts name the subject, the action, the camera behavior, the light direction, and the pacing. The gap between a woman walking in a city and a woman in a grey coat walking left to right through a rain-slicked crossing at dusk, camera tracking at hip height, neon reflections on wet asphalt, is the gap between stock footage and a shot.
Motion handling
Motion is where models separate. Some produce smooth camera movement but collapse on articulated human motion such as hands, fingers, and running. Others handle complex body movement well but wobble on slow, precise camera work. Test both extremes before you commit to a tool for a full project.
Post-production resilience
The final lever is how well a clip survives editing. A take that looks impressive full-screen can fall apart under a slight zoom, a color grade, or a speed ramp. Generate with headroom: extra space in the frame, a little extra duration at both ends, and a resolution above your delivery target.
A repeatable model-selection workflow
Guessing wastes more time than testing. Use the same short loop for every project.
1. Write the shot brief before opening any tool
List every shot with five fields: subject, action, camera, lighting, and duration. Keep it in a plain text file. This becomes both your testing checklist and the raw material for your prompts.
2. Classify each shot by motion type
Label shots as camera-led, subject-led, or effect-led. Camera-led shots are pans, dolly moves, and orbits. Subject-led shots involve bodies walking, talking, dancing, or fighting. Effect-led shots are transformations, explosions, weather, and abstract transitions. Different model families win different categories, and the label tells you where to test first.
3. Run a three-take test
For each new shot type, generate three takes with the same prompt across two or three candidate models. Do not judge still frames. Judge only motion at full speed. Watch each clip twice: once for what you asked for, and once for what the model invented on its own, which is usually a tell about where it will break under pressure.
4. Keep a results log
Record the model, the prompt, the seed if one is available, and a one-line verdict. After a few projects you will have a personal map of which tool handles which shot, and your first-take hit rate will climb sharply.
Matching shots to model strengths
Here is a practical mapping that holds across most current tools. Treat it as a starting hypothesis rather than a law, because model updates shift the balance every few months.
- Photoreal people and environments: prefer models with strong temporal consistency and realistic skin shading. Test hands and teeth early, since those are the first things to fail.
- Stylized and animated looks: prefer models trained on illustration or animation, and write prompts in art-direction vocabulary rather than photographic vocabulary.
- Product and tabletop shots: prefer models that hold object geometry and reflections steady. These shots need restraint in motion, so keep prompts minimal and camera moves tiny.
- Motion transfer and performance capture: drive the generation with a source video rather than text, and keep the framing of the driver close to the framing of the target.
- Image-to-video and keyframe control: use this when a specific composition or face must be preserved. Generate a strong still first, then animate it slowly.
The common thread is simple: never ask a model to do something it was not built for just to avoid learning a second tool.
Prompting patterns that survive across tools
Once you work with several models, you want prompts that transfer. A reliable structure is a five-part sentence: subject and wardrobe, action and timing, camera and lens, light and atmosphere, style and grade. Models that ignore one part usually still respond to the others, so the shot degrades gracefully instead of failing entirely.
Describe motion with verbs the model can visualize. Tracking, orbiting, craning, pushing in, pulling out, handheld drift, and static lock-off are all useful. Avoid stacking two camera moves in one clip; pick one and let the edit carry the rest.
Keep one action per clip. A character can walk or turn or open a door, but asking for all three in four seconds produces mush. When you need a complex beat, split it into two clips and cut between them, which is what a real editor would do anyway.
Use negative instructions sparingly and concretely. Saying no text overlays or no extra fingers works better than a long list of prohibitions that muddies the main subject. Finally, when a model supports seeds or reference images, reuse them. A consistent seed plus a stable written description is the cheapest continuity tool you have.
Handling continuity across multiple clips
Continuity is where AI video projects live or die. A viewer will forgive an imperfect frame, but they will not forgive a character whose jacket changes color between cuts.
Start by locking a reference. Generate one strong still of each main character and each main location, then use image-to-video for every shot featuring them. Keep the written description of wardrobe, hair, and props identical across prompts, word for word. Changing a synonym changes the output more often than you would expect.
Cut on motion whenever possible. A cut placed during a turn, a step, or a hand gesture hides small inconsistencies because the eye is following movement rather than detail. Match cuts, where a similar shape or action bridges two shots, work even better.
Insert coverage. A close-up of hands, a shot of a phone screen, or a wide establishing frame buys you several seconds and resets the viewer's attention before the next character shot. This is standard film grammar, and it solves AI continuity problems almost for free.
Finally, use the grade as glue. Applying one color grade, one grain pass, and one consistent contrast curve across every clip makes footage from different models feel like it came from the same camera.
Where post-production does the heavy lifting
AI video rarely arrives finished. The edit is not a cleanup step, it is where the work becomes believable.
Stabilization and retiming fix most motion artifacts. A clip with a slight jitter often looks perfect at eighty-five percent speed. Frame interpolation can smooth a choppy take, and light grain hides the plastic smoothness that gives generated footage away.
Color grading unifies mixed sources. If you generated shots from three different tools, a shared grade is what makes them a scene rather than a collage. Keep it simple: a base contrast curve, a slight color shift toward one temperature, and a subtle vignette.
Sound design matters more than most creators expect. Footsteps, cloth movement, room tone, and a low music bed convince the ear, and the ear convinces the eye. A silent AI clip feels fake even when the pixels are excellent. Add ambience first, then effects, then music, in that order.
Finally, expect to mask. Removing a stray limb, painting out a warped background element, or rotoscoping a subject for a background replacement is normal finishing work, not a sign of failure.
Common mistakes and how to avoid them
- Chasing maximum realism on every shot. Realism is one style, not the goal. A slightly stylized look is often more forgiving and more memorable.
- Judging stills instead of motion. A frame can look gorgeous while the clip wobbles like a boat.
- Over-prompting. Long prompts dilute the important instruction. Lead with the subject and the action.
- Loyalty to a single model. Every tool has a weak category. Keep at least two options ready.
- Forgetting headroom. No extra frames and no crop space means no room to fix anything.
- Ignoring audio. Silent AI video reads as a technical demo, not a story.
- Unrealistic durations. Ask for four to six seconds of clean action rather than a twelve-second epic that collapses halfway.
- Skipping the brief. Without a written shot list, every generation becomes a random experiment.
- Ignoring rights. Check the licensing of any input image, face, or voice you use before publishing.
Building your own stack over time
You do not need dozens of tools. You need a small, well-understood set with clear roles.
A workable stack has four slots. One generalist model for fast iteration and storyboards. One photoreal specialist for hero shots. One stylized model for visual variety and transitions. One image-to-video or motion tool for anything that must match a locked reference. Add a dedicated upscaler and a grain or grade tool, and you can produce work that competes with far more expensive setups.
Review the stack periodically rather than constantly. Test one new model per month against your existing hero shots, and only replace a slot when the improvement is obvious at full playback speed. Chasing every release leads to tool churn and inconsistent output.
Keep a private test reel. Sixty seconds of your best shots, labelled by tool and shot type, is the fastest way to make decisions on a deadline. When a client asks for a rainy street at night, you already know which tool delivers it in two takes.
FAQ
How many models do I actually need for a typical project?
Two or three is usually enough: one generalist, one specialist for the dominant shot type, and one image-to-video tool for continuity. More than that adds consistency problems without adding much quality.
Is text-to-video or image-to-video better?
Text-to-video is faster for exploration and for shots where exact composition does not matter. Image-to-video is better whenever a character, product, or location must stay consistent, because the still anchors everything that follows.
Why does my generated footage look artificial even when it is sharp?
Sharpness is not realism. The usual culprits are missing grain, no camera imperfection, mismatched audio, and overly smooth motion. Add grain, slow the clip slightly, and layer in ambience.
How long should each generated clip be?
Four to six seconds is the sweet spot for most tools. Longer generations drift in appearance and motion. Build longer sequences by cutting between several clean short takes rather than stretching one.
Can I mix footage from different tools in one video?
Yes, and most professional AI work already does. Unify the results with a single color grade, consistent grain, and matching sound design. The edit hides the seams far better than any single model could.
What is the fastest way to improve my results?
Write a shot brief before generating anything, run three-take comparisons on new shot types, and log the results. This removes guesswork and typically doubles your usable output within a week.
Do I need expensive hardware?
Only if you plan to run models locally. Most hosted workflows need nothing more than a stable connection and a browser, and the heavy processing happens elsewhere. Spend the saved budget on storage and a reliable editing setup instead.
