
Why AI Video Workflows Break Down Before the First Render
Most AI video projects do not fail at the render stage. They fail in the quiet hours before anyone presses generate, in the gap between a loose creative idea and a shot plan a model can actually execute. A team writes a beautiful treatment, pastes a paragraph into a text-to-video tool, receives something visually impressive but dramatically inert, and concludes the technology is not ready. The technology was fine. The workflow was not.
Generative video is a probabilistic medium. Every prompt is a small experiment, and experiments need constraints. Professional AI video work borrows its discipline from animation and visual effects pipelines: lock the story first, define the visual language, break the script into shots, generate the simplest version of each shot that proves the idea, then escalate complexity only where the story demands it.
There is also a psychological trap worth naming. Because generation feels fast, teams skip preparation. But a ten-second mistake in pre-production costs an hour of regeneration, and an hour of regeneration costs a day of editing when the shots do not cut together. Slowness at the front buys speed at the back.
The rest of this guide is a neutral, tool-agnostic workflow you can run with any generation stack, whether you are producing a thirty-second social spot, a product explainer, or a short narrative piece.
Mapping the Pipeline: From Idea to Locked Cut
Treat AI video like any other production and you immediately gain leverage. Three phases, each with a clear exit condition, keep a project from drifting.
Pre-production: script, shot list, style bible
Write the script as plain text before you think about visuals. Then convert it into a shot list with one row per shot: duration, subject, action, camera movement, lighting, and the emotional beat it serves. Shots that do not serve a beat get cut here, where cutting is free.
The style bible is a single page. It records aspect ratio, frame rate, colour palette, lens character, grain, and two or three reference stills. Every prompt written later inherits from it. This page is the single most valuable document in the project, because it converts taste into instructions.
Generation: keyframes, motion, and iteration loops
Generate stills first. An image-to-video pipeline gives you far more control than pure text-to-video, because you approve composition before motion enters the equation. Once a keyframe is approved, animate it with a short, narrow motion instruction.
Work in loops rather than in one long push: generate two or three candidates, review them, adjust exactly one variable, regenerate. Changing one thing at a time is the only way to learn what a given model actually responds to.
Post: assembly, sound, colour, delivery
Assemble in an editor, not inside the generation tool. Add sound design, music, and dialogue, then grade. Name generated clips by shot number so relinking stays trivial when you inevitably move files between folders.
The exit condition for each phase is simple: nothing moves forward until the previous phase is approved by whoever owns the final cut. On solo projects that is you, which makes the rule even more important.
Choosing the Right Generation Model for Each Shot
No single model wins every category. Some produce gorgeous establishing shots and fall apart on faces. Others handle dialogue-adjacent performance well but struggle with fast camera moves. Build a small internal shortlist and match it to the shot type.
Text-to-video, image-to-video, and video-to-video
Text-to-video is best for exploration and for shots where atmosphere matters more than precise subject placement. It is fast and cheap to iterate, and it is a good way to discover a visual direction you had not imagined.
Image-to-video is the workhorse for controlled work. Because the first frame is fixed, you can compose with intent, reuse approved character designs, and reduce the number of failed takes dramatically. If a project has any continuity requirements, this should be your default.
Video-to-video, including restyling and motion transfer, is valuable for matching a reference look, changing a season or time of day, or extending an existing clip. It is also the most fragile of the three, so budget extra review time.
General models versus specialised ones
The practical rule is to start general and specialise only where you see repeated failure. If faces drift across five shots, move to a model known for identity retention. If backgrounds wobble, choose one that handles parallax and camera movement well. Keep a short note file describing which model you used for which shot, so that a reshoot later is a lookup rather than an archaeology project.
Cost and speed matter, but they should be the third and fourth criteria, not the first. A fast model that produces unusable motion costs more than a slow model that produces a keeper on the second attempt.
Prompting and Camera Control That Holds Up
Prompt quality is not about length. It is about the ratio of constraints to decoration. A prompt with five precise constraints beats a prompt with fifty adjectives.
Camera language and motion verbs
Use a consistent vocabulary for camera behaviour: static, slow push in, pull back, pan left, tilt up, handheld drift, orbit, crane down. Pair each with a speed qualifier such as slow, steady, or subtle, and avoid stacking two movements in one shot unless the model is known to handle compound motion.
Describe the subject action with a single dominant verb. "She turns to the window and exhales" is easier to execute than "she turns, smiles, picks up a cup, and walks away." If a beat needs four actions, it needs four shots.
Style consistency across shots
Lock a style phrase and reuse it verbatim across every prompt in a sequence. Changing "soft morning light" to "warm sunrise glow" mid-scene will shift the grade enough to break continuity. Keep a prompt library for the project: one canonical block for style, one for the subject, one for the environment, and vary only the action and camera lines.
Negative instructions help, but sparingly. Listing twenty things you do not want often introduces them. Target the two or three failures you actually observed.
Building a Consistency System for Characters and Scenes
Consistency is the hardest part of AI video and the one that separates a demo from a deliverable. Solve it with process, not luck.
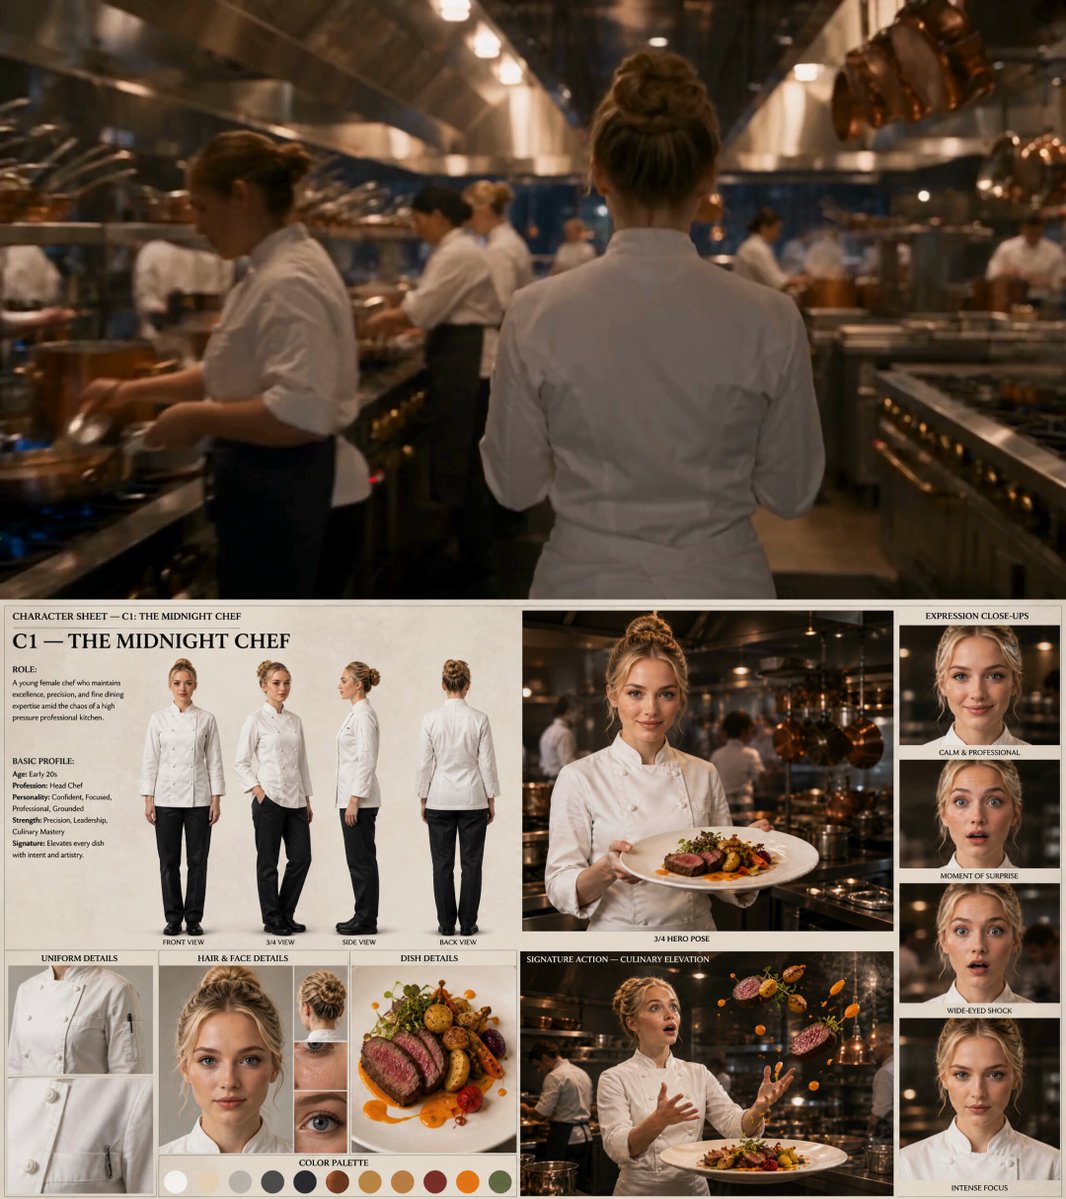
Start with a character sheet: front view, three-quarter view, profile, and a neutral expression, all generated from one approved base image. Keep the seed, prompt block, and reference image together in one folder. When you need a new angle, generate from the reference rather than from text.
For environments, build a location plate first: a wide, empty version of the space with clear lighting direction. Every subsequent shot in that location references the plate. This prevents the classic problem where a room rearranges itself between cuts.
Wardrobe and props deserve the same treatment. A signature jacket, a specific mug, a distinctive car: describe them with the same phrasing every time, and include them in the style block rather than in the action line.
Finally, accept controlled imperfection. Audiences forgive small AI artefacts far more readily than they forgive broken continuity or a shot that does not advance the story. Spend your regeneration budget on narrative clarity before surface polish.
Audio, Dialogue, and Sound Design in AI Video
Sound is where most AI video projects quietly lose credibility. Silent clips with music beds feel like moodboards. Adding three layers of sound transforms the same footage into something that reads as finished.
Layer one is ambience: room tone, wind, traffic, the hum of a space. Layer two is hard effects: footsteps, fabric, doors, impacts, all synced to visible action. Layer three is music. Only after these three exist should you consider whether generated dialogue is needed at all.
If you are using generated voice, keep sentences short and write for speech rhythm rather than for reading. Record or generate each line separately so you can adjust timing without re-rendering whole scenes. Slight breath and pause imperfections sound more human than a flawless, breathless read.
For lip-sync work, generate or select the visual performance first, then match the audio to it, not the other way around. Matching visuals to an existing audio track is possible but consumes far more attempts.
Quality Control: A Practical Review Checklist
Review each generated clip against the same short list, every time. Consistency of process catches inconsistency of output.
- Motion integrity: no melting limbs, no objects that dissolve, no unexplained camera snaps.
- Identity: faces, hair, and wardrobe match the approved reference.
- Continuity: lighting direction, time of day, and set dressing match the location plate.
- Framing: subject sits in the intended part of the frame with correct headroom and lead room.
- Usability: the clip has handles at both ends so it can be trimmed into the cut.
- Resolution and frame rate: matches the project settings so it does not need rescaling.
Score each clip pass, maybe, or fail. Maybe-clips go into a holding folder and get revisited only if the edit demands them. This keeps decision fatigue out of the review session.
Common Mistakes and How to Fix Them
Generating before writing. The most expensive error. Fix it by refusing to open a generation tool until the shot list exists.
Changing too many variables at once. When a render fails, teams rewrite the prompt, change the model, and swap the reference image. Then they learn nothing. Change one variable per attempt.
Overloading a single shot. If a shot needs two camera moves, three characters, and a costume change, split it. Short, simple shots cut together better and fail less.
Ignoring the edit until the end. Assemble a rough cut with placeholder clips early. Timing problems are far cheaper to solve with placeholders than with finished renders.
Chasing perfection on unimportant shots. An establishing shot that appears for one second does not need six regeneration passes. Spend that time on the hero moment.
No naming convention. Files called final_v2_really.mp4 are a symptom of a broken pipeline. Adopt shot numbering from day one.
Scaling the Workflow and Handing Off to a Team
When more than one person touches a project, the workflow needs an interface. Keep three shared artefacts: the shot list, the style bible, and the prompt library. Anyone joining the project should be able to produce an on-brand shot after reading those three documents and nothing else.
Assign ownership by phase rather than by shot. One person owns pre-production and the shot list, one owns generation and maintains the prompt library, one owns assembly and sound. Handoffs happen at phase gates, not continuously, which prevents version collisions.
Track simple metrics so you can improve: attempts per approved shot, average review time per clip, and percentage of clips that survive to the final cut. If attempts per shot climbs above roughly four, the problem is usually upstream in the shot list or style bible, not in the model.
For longer projects, archive approved assets separately from working files. Approved keyframes and location plates are long-term assets you will reuse on the next project; the failed takes are not.
FAQ
How long should an AI-generated shot be?
Aim for two to five seconds for most cuts, and generate eight to twelve seconds so you have handles to trim. Longer generations tend to drift in motion and identity.
Do I need a different model for each type of shot?
Not necessarily, but most workflows end up with two or three models: one for controlled image-to-video work, one for atmospheric exploration, and occasionally a specialist for faces or stylised looks.
How do I keep characters looking the same across shots?
Generate a character sheet from one approved base image, reuse the same seed and style block, and always start new angles from the reference image rather than from text alone.
Is text-to-video or image-to-video better for beginners?
Start with text-to-video to learn how the model behaves, then move to image-to-video as soon as you need continuity. Most frustrating beginner experiences come from trying to control composition through text.
What is the fastest way to improve output quality?
Add sound. A well-designed audio layer makes average footage feel intentional, and silent footage makes excellent renders feel unfinished.
How many attempts should a shot take?
Two to four is a healthy range. If you routinely need more, simplify the shot or improve the reference material instead of rewriting the prompt endlessly.
Can I mix AI footage with real footage?
Yes, and it is often the strongest approach. Match frame rate, resolution, and grade early, and use real footage for anything that requires precise human performance.
The through-line in all of this is unglamorous: plan more, change less per attempt, and finish in an editor. The teams producing consistently good AI video are not using secret models. They are running a disciplined pipeline and letting the tools do what they are actually good at.
