
Why Vertical Short-Form Video Rewards a Different Workflow
Short-form vertical video is watched on a phone, frequently muted, frequently while the viewer is doing something else. That single fact changes almost every production decision. A horizontal cinematic scene can afford a slow reveal; a vertical clip has roughly a second and a half to earn attention, and it has to survive being watched with the sound off.
AI generation fits this format unusually well, but only when the workflow is built around the format instead of retrofitted to it. Three constraints shape everything else:
- Framing. A 9:16 frame crops away most of the horizontal field, so subjects need to sit near the center third, and captions or interface elements have to stay clear of the top and bottom safe zones.
- Motion. Big camera moves read as chaos on a small screen. Small, deliberate movement, such as a slow push-in or a drifting handheld, holds attention better than a sweeping crane shot.
- Duration. Generated clips are short, so the edit carries the story. Six to twelve clips of two to five seconds each is a normal rhythm for a thirty-second piece.
The practical consequence is that you are not making a film and cutting it down. You are designing a sequence of small, legible moments, then letting an editing rhythm tie them together. Once that mental model is in place, the tooling decisions become far easier to reason about.
Plan the Story Before You Touch a Generator
Most disappointing AI video output starts as a vague idea typed into a prompt box. The fix is unglamorous: write the story first, in text, at the length of the final piece.
A workable pre-production pass looks like this:
- One-sentence premise. If you cannot state the point of the video in a single sentence, the generation stage will produce attractive but meaningless footage.
- Beat sheet. Break the premise into four to eight beats. Each beat is one visual idea: a hand opening a box, a character turning toward a window, a product rotating on a table.
- Shot list. Convert beats into shots with a subject, an action, a camera behavior, and an environment. This is the document you will actually work from.
- Voice and caption script. Write the spoken or on-screen text separately from the visuals. Trying to generate visuals that literally illustrate every sentence produces a slideshow rather than a video.
A useful discipline is to decide, for each beat, whether the viewer learns something, feels something, or sees something surprising. If a beat does none of the three, cut it before you spend time generating it. Trimming in the script stage costs nothing; trimming after generation costs hours.
Choosing the Right Model for Each Shot
There is no single best video generation model, only models that suit specific shot types. Treating them as interchangeable is the most common source of wasted effort.
Text-to-video versus image-to-video
Text-to-video is fast for exploration and mood boards, but it gives you limited control over a specific character or product. Image-to-video, where you supply a still frame and let the model animate it, is usually the better choice for anything that must match a previous shot. A practical split is to explore with text-to-video, then lock the final look with stills you control, generated or photographed.
Matching model strengths to shot types
- Atmospheric establishing shots. Models with strong environmental texture and natural lighting do well here, because there is no precise subject to keep consistent.
- Character performance. Look for models that handle faces, lip movement, and micro-expressions. Test with a short clip of someone speaking before committing to a full scene.
- Product and object shots. Favor models that preserve geometry and material detail, especially for reflective or transparent surfaces.
- Abstract transitions. Stylized, effects-heavy models are ideal for the connective tissue between scenes, where realism matters less than energy.
Evaluation criteria that actually predict usable output
When comparing options, ignore demo reels and test with your own material. Score each model on:
- Temporal coherence. Does the object stay the same object across the clip, or does it melt and re-form?
- Prompt adherence. Does it respect the camera instruction, or does it default to a generic orbit?
- Motion quality. Are limbs and hands plausible, or do they smear?
- Aspect ratio support. Native vertical output avoids a lossy crop later, though cropping a wider frame is sometimes acceptable for static-ish shots.
- Iteration speed. A model that returns a usable clip in forty seconds earns more experimentation than a slower one, even if its peak quality is higher.
- Licensing and commercial terms. Confirm usage rights before you build a campaign around a clip.
Keep a small test set of five prompts, including one face close-up, one hand interaction, one product rotation, one walking shot, and one abstract transition. Run every new model against that set and keep the results in a folder. Your notes will be more reliable than any ranking list.
Building Visual Consistency Across Scenes
Consistency, not raw quality, is what makes AI-assisted video feel professional. A viewer forgives a slightly soft frame but instantly notices when a character's jacket changes color between cuts.
Character and product reference sheets
Build a reference sheet for anything that appears twice: front, three-quarter, and profile views; two lighting conditions; and a clear note on wardrobe, hair, and distinguishing marks. If you generate the reference images yourself, keep the seed and prompt that produced the version you liked. Reproducing a previous look is far easier when you have documented how you made it.
Keyframe anchoring and first/last frame control
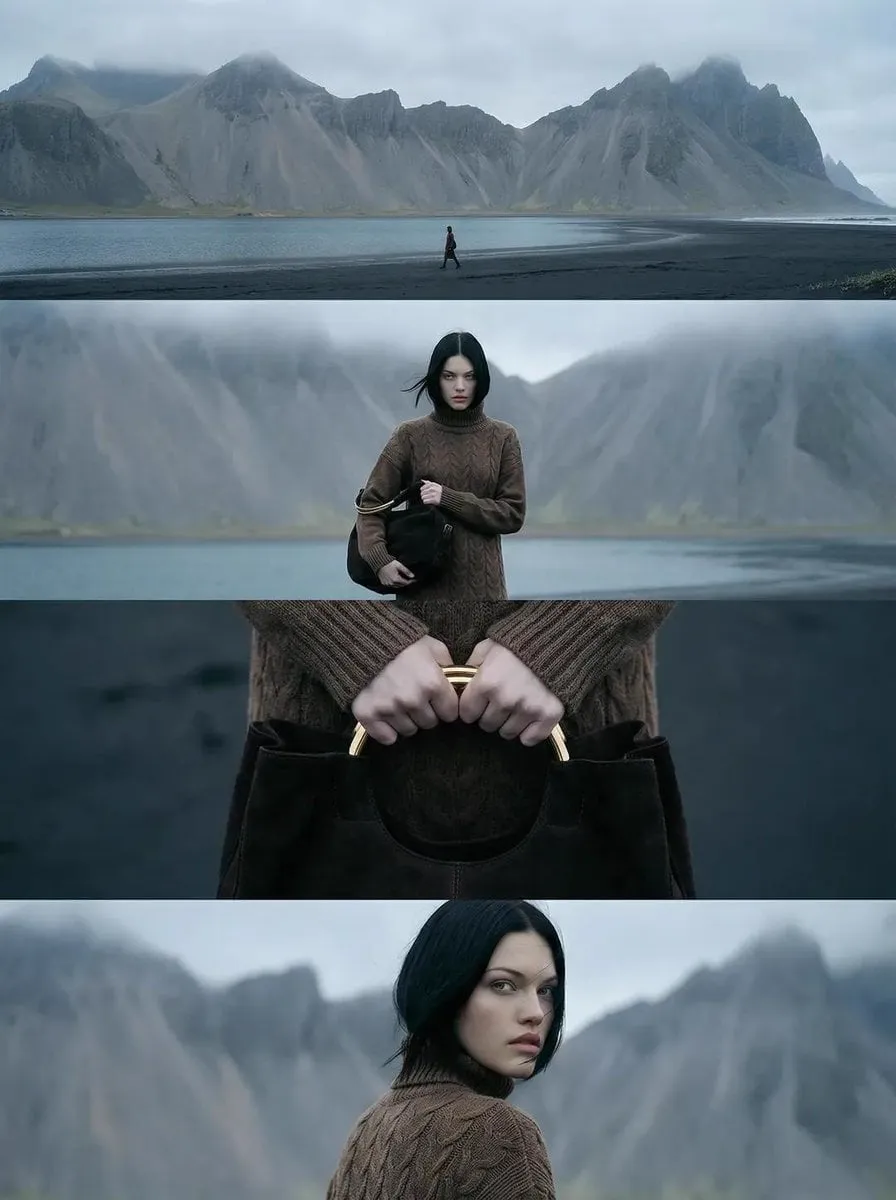
Many modern generators let you supply a starting frame, an ending frame, or both. This is the single most powerful consistency tool available. Generate a still of the character in the exact pose you want at the start of the shot, animate from it, and where supported, define the final frame so the clip lands precisely where the next shot begins. This also solves continuity problems in the edit, because you already know what the last frame looks like.
Locking the look: lens, light, and palette
Write a short visual style block and paste it into every prompt in a project:
35mm lens, shallow depth of field, soft window light from camera left, muted teal and warm amber palette, gentle film grain, handheld at shoulder height.
Reusing one style block across a project does more for cohesion than any amount of per-shot tweaking. Vary the subject and action, not the grammar of the image.
A Step-by-Step Production Pipeline
Step 1: Beat sheet and shot list
Spend twenty minutes here and you will save hours later. Number every shot, and write one line describing the desired outcome, including the emotion you want the viewer to feel.
Step 2: Prompt construction
A reliable prompt template has five parts, in this order: subject, action, environment, camera, and style. For example: a woman in her thirties, lifting a ceramic mug, in a sunlit kitchen, slow push-in from chest height, warm morning light with soft grain. Resist the temptation to add adjectives for atmosphere; prompt length past a certain point dilutes the important instructions.
Step 3: Generation and selection
Generate in small batches of three to six variants per shot, and never more than one shot at a time. Watch each clip on a phone screen at actual size before judging it, because what looks subtle on a monitor can be invisible on a phone. Keep a simple selection rule: if a clip needs a paragraph of explanation to be acceptable, discard it.
Step 4: Assembly, sound, and captions
Drop selected clips into an editor in shot order. Use hard cuts for energy and reserve short dissolves for time jumps. Add captions that are legible at arm's length, then build the sound: a music bed, a few tactile sound effects, and any voiceover. Sound is not decoration in this format; it is what makes a sequence of unrelated clips feel continuous.
Post-Production Details That Sell the Illusion
A few small edits do most of the heavy lifting:
- Speed ramps. Slight speed variation on generated clips hides the characteristic uniform motion that gives AI footage away.
- Micro-cuts. Cutting a clip in half and reversing the second half creates seamless looping movement.
- Frame-level trim. Start and end clips on frames where motion is minimal, and the cuts feel intentional.
- Grain and texture. A light grain pass unifies clips from different sources.
- Color matching. Apply one grade across the whole timeline rather than grading each clip separately.
Keep captions inside the middle eighty percent of the frame vertically, and test on two devices before publishing. Also check how the first frame reads as a thumbnail, since that frame often determines whether the video is opened at all.
Common Mistakes and How to Fix Them
- Inconsistent subjects. Cause: generating each shot from scratch. Fix: reuse reference stills and anchor with first-frame images.
- Muddy motion. Cause: prompts that ask for too much simultaneous action. Fix: one clear action per clip.
- Unnatural hands and faces. Cause: small subjects in a wide frame. Fix: frame tighter, so the model has more pixels to work with.
- Story that goes nowhere. Cause: writing prompts instead of writing a script. Fix: return to the beat sheet and cut a beat.
- Overlong intro. Cause: saving the payoff for the end. Fix: put the most striking image in the first second and explain later.
- Audio that fights the edit. Cause: choosing music before the cut rhythm exists. Fix: rough-cut to silence, then score the timeline.
Scaling Into a Repeatable Content System
Once a format works, the goal shifts from one good video to a reliable stream of them. That means templating. Save a prompt template, a style block, a caption style, a music shortlist, and an export preset. Build a recurring series with a consistent opening frame and title treatment, because repetition is what turns casual viewers into followers.
Batch related work: write five scripts in one sitting, generate all stills in another session, then animate. Context switching is the hidden cost in AI production, and grouping similar tasks is the cheapest productivity gain available. Keep a simple log of which prompts produced usable clips, and prune the list monthly so it stays useful.
Tool Categories and Decision Criteria
Rather than chasing a single winner, assemble a small stack by category:
- Exploration models for mood boards and rough ideas, judged on speed.
- Hero models for the shots that carry the video, judged on character and motion fidelity.
- Image models for reference sheets and keyframes, judged on consistency and control.
- Editors with strong captioning, vertical presets, and fast export.
- Audio tools for music, voice, and cleanup.
Decide based on three questions: does it accept vertical output natively, can it accept a starting frame, and how long does one iteration take? Everything else is secondary. When two tools are close, pick the one that keeps you iterating faster, because volume of experiments, not peak capability, is what improves your final output.
FAQ
How long should a generated clip be?
Two to five seconds is the sweet spot. Longer clips tend to drift in appearance, and shorter ones rarely show enough motion to register.
Do I need a script if the video has no dialogue?
Yes. A shot list is still a script. Without it you are generating attractive footage with no reason for the viewer to keep watching.
How do I stop characters from changing between shots?
Use a reference sheet, generate a starting frame for every shot, and reuse one style block verbatim. Consistency comes from controlled inputs, not luck.
What aspect ratio should I export?
Match the platform: 1080x1920 for vertical feeds. Keep a square or 16:9 master if you plan to reuse the footage elsewhere.
How many generations does a finished clip usually take?
Plan on three to six attempts per shot, and accept that some shots will resist. If a shot fails after eight tries, redesign it rather than keep generating.
Is AI video good enough for brand work?
For short-form social content, yes, provided the subject repeats consistently and the sound design is deliberate. For longer narratives, use it as part of a mixed pipeline with real footage.
Where should a beginner start?
Start with one model, one style block, and a ten-second video of three shots. Finish it, publish it, and only then expand your stack. Finishing small projects teaches more than testing every new tool.
