
Why Interactive Learning Video Is Being Rebuilt Around AI Pipelines
Learning teams are stuck in a familiar bottleneck. Subject-matter experts write excellent material, instructional designers turn it into a storyboard, and then production takes weeks per module. By the time a course ships, the product screenshot is outdated, the compliance language has changed, and the audience has moved on. Video is the format learners actually finish, and it is also the format that is hardest to update.
Generative video tooling changes that equation, but not in the way most marketing pages suggest. The real shift is not that a single prompt produces a finished lesson. The shift is that the expensive, repetitive parts of production — b-roll, avatar framing, voice pickup, caption timing, localization, and version management — can now be generated, regenerated, and re-cut on demand. That turns video from a one-time asset into a maintainable document, closer to a slide deck you can edit than a film you must reshoot.
This guide walks through a working pipeline for interactive educational video built on AI tools. It covers scripting for machine-readable structure, choosing the right visual approach per lesson type, locking character and brand consistency, handling voice and accessibility, layering in quizzes and branching, running quality control, and scaling across dozens of modules without losing your mind.
What Automation Actually Means in an Education Content Stack
Automation in learning content is often mis-sold as "press a button, get a course." In practice, the useful version is narrower and far more valuable: automate the steps that are mechanical, and keep humans on the steps that carry judgment. A well-designed pipeline automates generation, timing, formatting, and duplication. It does not automate the decision about what learners need to be able to do at the end of the lesson.
The four layers of a viable AI video pipeline
- Source layer. Your curriculum outline, learning objectives, SME notes, transcripts, and existing slide decks. Everything downstream is derived from this, so messy inputs produce messy video.
- Generation layer. Script drafting, storyboard beats, image generation, video clip generation, voice synthesis, and music beds.
- Assembly layer. Timeline editing, captioning, motion graphics, lower thirds, and interactive overlays.
- Delivery layer. LMS packaging, SCORM or xAPI events, versioning, translation tracks, and analytics.
Most failed AI video projects skip the source layer and leap straight into generation. The result is attractive footage that does not teach anything measurable.
Where automation genuinely saves time
- Draft scripts from objectives. A model can turn "the learner will identify three causes of hydraulic failure" into a two-minute scripted segment with a hook, three explanations, and a recap.
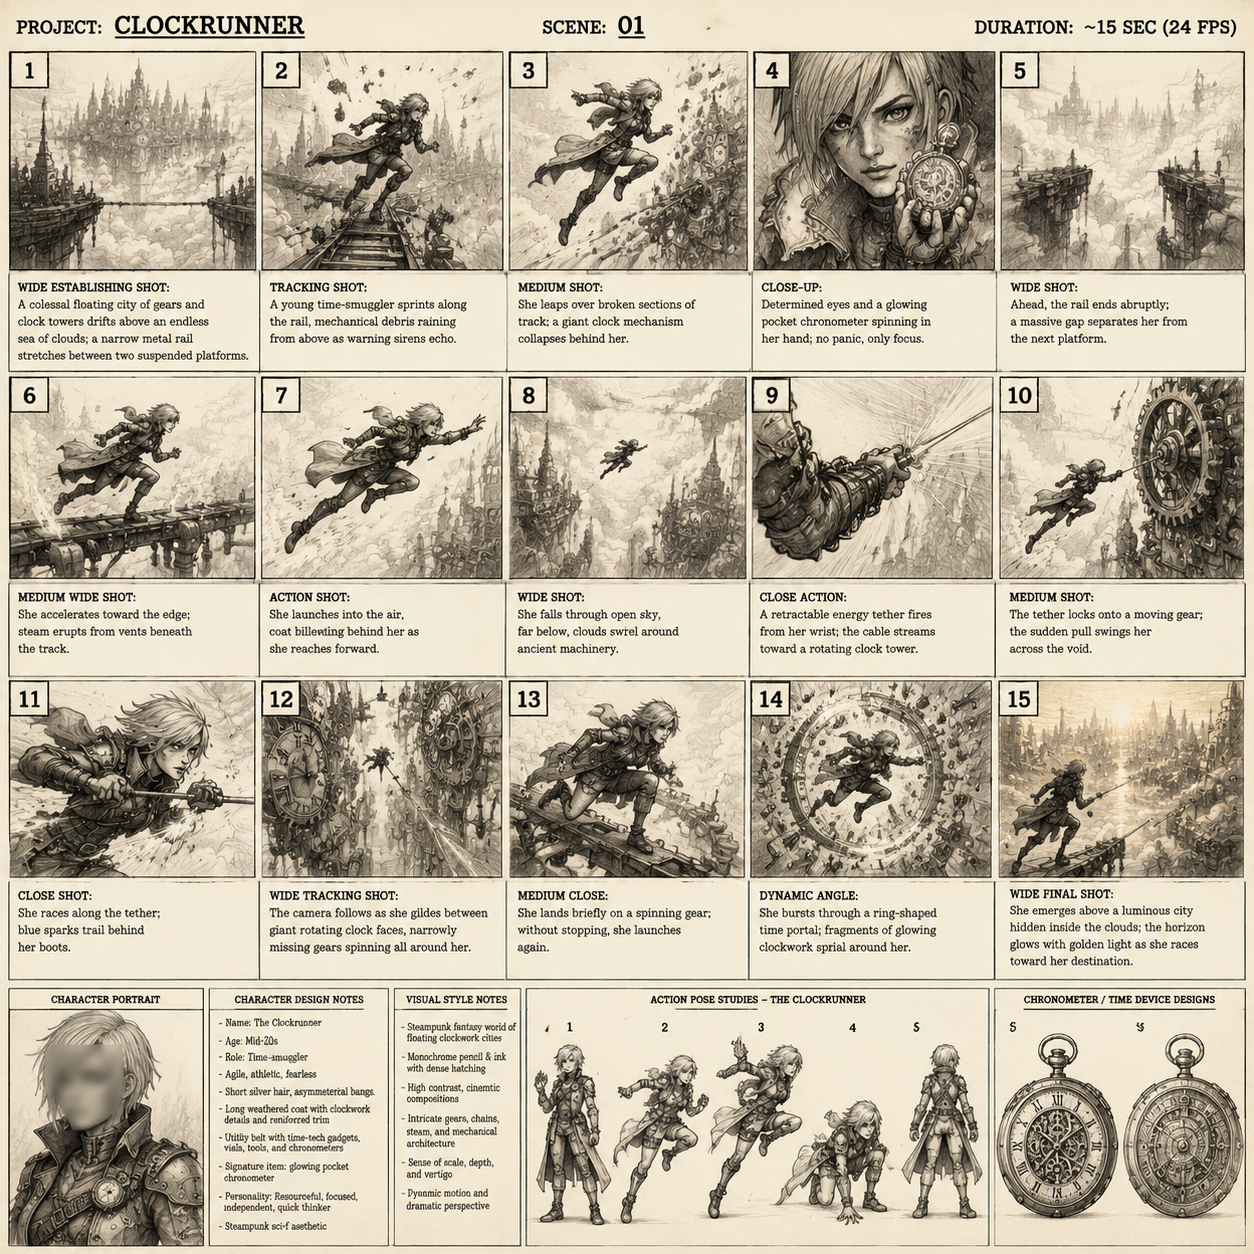
- Shot lists and beat sheets. Instead of a designer hand-writing 40 storyboard panels, generate a beat list at 5–8 second granularity and edit it.
- B-roll and environment shots. Abstract concepts, process flows, and "a technician in a warehouse" scenes no longer require a shoot day.
- Voice pickup and revision. Changing one sentence means regenerating one audio line, not rebooking a narrator.
- Caption and translation passes. Word-level timestamps make localization a batch operation rather than a manual one.
Where automation actively hurts
Automating assessment design, scenario logic, or the final editorial pass usually backfires. Quiz items generated without objective alignment tend to test recall of trivia rather than the skill you set out to teach. Similarly, letting a model decide the pacing of a safety-critical procedure removes the deliberate pause that gives learners time to process risk. Treat automation as a production accelerator, not an instructional designer.
Step 1: Turn Curriculum Into a Shot-Ready Script
The transition from curriculum document to script is where most of the quality is won or lost. Write for the ear, then break the script into beats that a video tool can actually execute.
Writing for the ear, not the page
Educational prose is dense. Spoken narration needs shorter sentences, concrete nouns, and explicit signposting. Three habits make the biggest difference:
- One idea per sentence. If you need a comma splice to finish the thought, split it.
- Say the number, then show the number. "Latency drops by roughly half" lands better when a chart animates at the same moment.
- Front-load the payoff. State what the learner will be able to do in the first fifteen seconds, then earn it.
Segmenting a lesson into 5–8 second beats
Generative clip tools work best with short, self-contained prompts. A beat is a single visual idea: "close-up of hands tightening a valve," "animated bar chart comparing two throughput figures," "instructor gesturing toward a whiteboard diagram." Build your beat sheet in a spreadsheet with columns for timestamp, narration line, visual description, on-screen text, and asset status. That single artifact becomes the interface between your script, your asset generation, and your editor.
Drafting the script with a model, then editing hard
Ask for a first draft structured as a table with a narration column and a visual column. Then rewrite the narration yourself — or have a senior designer rewrite it. Model-drafted narration is usually grammatically clean and pedagogically flat. It states facts; it does not create the small tensions that keep attention. Add a question, a mildly counterintuitive example, or a mistake learners commonly make. That is the difference between a video people finish and a video people skip.
Step 2: Choose the Right Visual Approach for Each Lesson Type
Not every lesson should look the same way, and not every lesson should use the most expensive generation mode. Matching visual approach to content type controls both cost and comprehension.
Talking-head and presenter-led segments
Use an avatar or a recorded presenter when the value is in the explanation itself: introductions, framing, transitions, and motivational content. These are cheap to generate and easy to revise when the script changes. Keep the framing consistent — same shoulder line, same eyeline, same background family — so the learner is not re-orienting every thirty seconds.
Demonstration and process shots
Hands-on procedures benefit from generated b-roll: a tool being used, a screen being navigated, a machine cycle running. These shots do not need to be photoreal, but they do need to be accurate. Always have an SME verify that a generated procedure shot is not teaching a wrong physical action. A visually perfect clip that shows the wrong grip is worse than no clip at all.
Abstract concept visualization
Diagrams, motion graphics, and stylized 3D sequences are where generated video shines brightest. Inventory, network topology, financial flows, and biological processes all benefit from visual metaphor. Generate several options, then pick the one that a learner could redraw from memory.
A practical decision table
| Lesson content | Best visual approach | Revision cost | Typical risk |
|---|---|---|---|
| Framing and motivation | Presenter or avatar, minimal b-roll | Low | Feels generic |
| Software walkthrough | Screen recording plus callouts | Low | Outdated UI |
| Physical procedure | Generated b-roll plus slow-motion inserts | Medium | Incorrect technique |
| Abstract model | Motion graphics or stylized 3D | Medium | Over-decoration |
| Compliance scenario | Branching live-action-style scenes | High | Tone deafness |
| Data interpretation | Animated charts with narration sync | Low | Misread scale |
Step 3: Lock Character and Brand Consistency
Character drift is the fastest way to make an AI-assisted course look cheap. A presenter whose face, hair, and wardrobe change between segments breaks the illusion of a single continuous lesson.
Reference sheets, seeds, and style locks
Build a reference sheet for every recurring character: front, three-quarter, and profile views, plus two wardrobe variants and one neutral expression. Keep the same seed or reference image across generations, and document the prompt fragments that produce the canonical look. Store this in a shared folder named after the character, not after the project — you will reuse it across modules.
Wardrobe, lighting, and camera rules
Write down three rules and enforce them ruthlessly:
- Wardrobe. One outfit per course, with a documented alternative for scenario role-play.
- Lighting. A single described setup, such as soft key from the left with a cool rim. Consistency in lighting sells consistency in character more than facial detail does.
- Camera. Fixed lens language — for example, 35mm medium shot for explanation, 50mm close-up for emphasis. Do not let the model improvise camera moves in a lecture segment.
Brand system, not just brand colors
Extend the same discipline to your visual identity: lower-third position, caption font and size, transition style, and the exact shade of your primary color. Create a short style guide with six to eight frames as visual examples. Anyone generating assets — human or automated — should be able to match it without asking.
Step 4: Voice, Captions, and Accessibility
Accessibility is not a final checklist item. It changes how you script, how you pace, and how you export.
Voice selection and pacing
Synthesized narration has improved dramatically, but pace still matters more than timbre. Aim for roughly 140–160 words per minute for instructional content, slower for procedural steps. Leave a deliberate two-second pause after any instruction the learner must perform. If you are localizing, choose a voice per language rather than dubbing one voice across all of them — accent mismatches are distracting in ways that a simple voice change is not.
Caption workflow
Generate captions from word-level timestamps, then correct them against the script rather than against the audio. Proper nouns, product names, and technical terms are misheard constantly. Burn-in captions are popular for social clips, but for LMS delivery always ship a separate caption track that the learner can toggle and restyle.
An accessibility checklist that actually gets used
- Captions are accurate to at least 99% and include speaker identification when more than one voice appears.
- A transcript is downloadable and searchable.
- On-screen text has a contrast ratio of at least 4.5:1 and stays on screen long enough to read at a comfortable pace.
- No meaning is carried by color alone in charts or diagrams.
- Audio description exists for any visual-only sequence longer than a few seconds.
- Interactive elements are keyboard navigable and have text alternatives.
Step 5: Add Interactivity Without Breaking the Edit
Interactivity is what separates a recorded lecture from a learning experience. The trick is to design it so the video still works as a linear asset if the interactivity layer fails to load.
Embedding questions without wrecking flow
Place knowledge checks immediately after the concept they test, not at the end of the module. Keep them to one or two items and give immediate, explanatory feedback — not just right or wrong, but why the distractor is tempting. Pause the timeline during the question so learners cannot skip past it while the narration continues.
Branching scenarios for procedure and compliance
Branching works best when the decision is genuinely consequential and the wrong path has a believable, non-punitive consequence. Script the failure branch as a learning moment: show what happens, explain the mechanism, then return the learner to the decision point. Two levels of branching is usually enough; deeper trees multiply maintenance cost without proportional learning gain.
Hotspots, overlays, and chaptering
Hotspot overlays let learners explore a diagram, a dashboard, or a piece of equipment. Chapter markers with descriptive labels turn a twelve-minute module into a reference tool that people return to. Both are cheap to add and disproportionately improve completion and re-visit rates.
Step 6: Quality Control and Common Failure Modes
A consistent QA pass catches the errors that audiences notice instantly and producers somehow miss.
The three-pass review
- Accuracy pass. An SME checks every factual claim, procedure, and number against the source material. Do not let a generalist do this pass.
- Continuity pass. Check character appearance, wardrobe, on-screen text, lower thirds, and audio levels across segment boundaries.
- Comprehension pass. Watch it once as a learner with no context, at normal speed, without pausing. If you get lost, they will too.
Common failure modes and their fixes
- Visual drift between clips. Fix by locking reference images and documenting prompt fragments.
- Narration that outpaces the visuals. Fix by cutting narration, not by speeding up the animation.
- Uncanny hands and tools. Fix by reframing to medium shots or cutting away before the detail becomes visible.
- Generic stock-feeling b-roll. Fix by adding a specific prop, location, or artifact from your own environment.
- Captions that lag by half a second. Fix by re-timing on the sentence level, then checking the longest words.
Scaling With Templates, Localization, and Versioning
Once one module works, the goal is repeatability. Treat each module as an instance of a template rather than a bespoke project.
Build a template library
Create named templates for the five or six segment types you use most: cold open, concept explanation, worked example, procedure walkthrough, knowledge check, and summary. Each template includes a duration range, a beat structure, and the corresponding prompt set. New modules then become an assembly exercise.
Localization as a batch operation
Export your script plus timings as a structured file. Translate the script with human review for terminology, regenerate narration in the target language, and re-time captions automatically. Keep a glossary of locked terms — regulatory language, product names, and safety vocabulary — so translators and models use identical phrasing every time.
Versioning and update paths
Tag every asset with a module ID and a version number. When a policy changes, you should be able to identify the affected beats, regenerate only those clips and audio lines, and re-export. This is the single largest long-term advantage of an AI-assisted pipeline: a two-year-old course can be refreshed in hours instead of being scrapped.
Tooling Map, Cost Planning, and FAQ
Which tools fit which stage
- Scripting and structure: a general-purpose assistant for drafting, plus a spreadsheet for the beat sheet.
- Image and clip generation: text-to-video and image-to-video tools for b-roll, environments, and stylized sequences.
- Presenter segments: avatar video platforms for consistent talking-head delivery.
- Voice: dedicated text-to-speech services with per-language voice libraries.
- Assembly: any nonlinear editor with strong caption and timeline tooling, plus motion graphics for overlays.
- Interactivity and delivery: an authoring layer that supports xAPI or SCORM events and publishes to your LMS.
Planning time and spend
Estimate per finished minute rather than per module. A reasonable target for a well-templated pipeline is two to four hours of production time per finished minute for the first module of a series, dropping to under an hour once templates and reference assets exist. Generation costs scale with clip count and resolution, so storyboard discipline is the primary cost lever — every beat you cut from the plan is money you do not spend.
Frequently asked questions
How long should an interactive learning video be?
Three to six minutes for a single concept, with a knowledge check at the midpoint and the end. Longer content should be split into chapters or separate modules.
Can AI-generated video replace an on-camera instructor?
For explanation, framing, and procedural content, yes, especially where consistency and localization matter. For high-stakes motivational content or executive messaging, a real presenter still carries more weight.
What is the biggest mistake teams make?
Automating production before fixing the source material. If the learning objectives are vague, no amount of generation quality will save the module.
How do I keep characters consistent across dozens of clips?
Reference sheets, fixed seeds, documented prompt fragments, and a written wardrobe and lighting rule set. Consistency is a documentation problem more than a model problem.
Will learners accept AI narration?
Most will, if pacing is natural and captions are accurate. Acceptance drops sharply when the voice mispronounces technical terms, so build a pronunciation list early.
How do I keep courses from going stale?
Version every asset and keep the beat sheet in a shared, editable format. Updates then become targeted regeneration rather than full re-production.
Where to start this week
Pick one existing module that is expensive to maintain. Rewrite its script for the ear, build a beat sheet, and generate only the b-roll and voice. Leave the presenter and interactivity layers alone for now. Once you can produce a convincing three-minute segment in a day, templating and scaling will follow naturally — and you will have a production pipeline your team can actually maintain.
