
Why Image-to-Video AI Changed Visual Storytelling
For most of the history of moving pictures, motion had to be either captured or constructed. You pointed a camera at something that moved, or you built a rig, painted in-betweens, and rendered frames one at a time. A single illustration was a dead end: beautiful, finished, and frozen. Image-to-video generation broke that assumption. Today a photograph, a concept sketch, a product render, or a painted character portrait can be extended into seconds of believable motion without a 3D pipeline, a motion-capture stage, or a team of animators.
That shift matters less because it is novel and more because it removes a bottleneck that shaped entire workflows. Storyboard artists no longer have to stop at a static frame and describe motion in text or arrows. Marketers can test a moving version of a hero image in the time it used to take to brief a motion designer. Documentary editors can add gentle parallax to archival photographs that would otherwise sit motionless on screen. Educators can bring diagrams to life. The same underlying capability serves all of them, and the differences between a good result and a bad one come down to how you prepare the input, how you describe motion, and how you assemble the output.
This guide is about that craft rather than about any single product. The tools change quickly, the principles do not. If you understand what these models actually do, how to steer them, and where they reliably fail, you can move between platforms without relearning your job.
How Image-to-Video Generation Actually Works
Most modern image-to-video systems are built on latent diffusion architectures adapted from still-image generation. Instead of denoising a static canvas, the model denoises a sequence of latent frames while a temporal module enforces that consecutive frames stay related. The result is a short clip that inherits the composition, palette, and lighting of the source image while introducing movement.
Motion priors, not full animation
A key mental model: these models do not understand physics. They understand statistical patterns of how pixels tend to move in the footage they were trained on. That gives them strong priors for certain kinds of motion — hair drifting, water rippling, crowds shifting, camera pushes, fabric folding, smoke rising — and weak priors for anything requiring precise physical logic, like a hand rotating an object without deforming, or two characters whose limbs must interlock correctly.
The practical consequence is that you should ask for motion the model has seen a thousand times rather than motion that requires reasoning. "Slow push in, coat flapping in wind, subtle head turn" is a request inside the model's comfort zone. "Character picks up the cup, drinks, and sets it down" is a request that will usually produce a melting hand and a cup that teleports.
The conditioning inputs you actually control
The levers available in nearly every serious tool are consistent:
- The source frame. Resolution, sharpness, aspect ratio, and how much empty space surrounds the subject all influence the result more than most users expect.
- The motion prompt. A short natural-language description of what changes and what stays still.
- Duration. Most systems generate two to six seconds natively; longer clips are usually stitched from overlapping segments.
- Motion strength or intensity. A single slider that trades stability for movement. Low values produce near-still footage with subtle life; high values produce dramatic motion and more artifacts.
- Camera controls. Separate controls for pan, tilt, zoom, and roll, which are far more reliable than describing camera movement in the prompt.
- Seed and randomness. Fixing a seed lets you iterate on one variable at a time instead of gambling each run.
Understanding which of these is responsible for which failure saves enormous time. If the whole frame warps, the motion strength is too high. If nothing moves, the prompt is descriptive rather than kinetic. If the camera lurches, you have probably mixed prompt-based camera language with explicit camera controls.
Choosing the Right Model for the Shot in Front of You
Different models have different personalities. Some prioritize photorealism and camera realism; others excel at illustrated or painterly styles; a few specialize in human faces and body motion. Rather than committing to one, build a small bench of three or four that cover your common cases and test each new source image against two of them.
Portraits and character close-ups
Faces are where viewers are most sensitive to error and where models differ most. Look for tools that offer explicit face or identity preservation, and keep motion conservative. A portrait that blinks, breathes, and turns slightly reads as alive; a portrait that swings its head will read as wrong within two frames. Reduce motion strength, keep the framing tight, and avoid prompts that imply large rotation.
Landscapes, architecture, and product shots
Wide, detailed scenes tolerate much more motion because there is no single focal point for the eye to interrogate. These are the shots where slow push-ins, drifting clouds, moving water, and light shifting across a surface look genuinely cinematic. Product shots benefit from a controlled camera orbit or a rack of light rather than any internal motion of the object, which keeps branding and geometry intact.
Stylized art and illustration
Illustrated sources are forgiving in a different way. Line art, watercolor, and comic styles hide small inconsistencies that would be obvious in a photograph. The risk runs the other way: models trained heavily on photography may try to add photoreal texture to a flat drawing, muddying it. Choose a model with a style-transfer or illustration-aware setting, and describe motion in the language of the medium — "cape billowing, ink lines holding steady" — rather than in cinematic terms.
A simple decision rule: pick the model whose training data most resembles your source. Photoreal source, photoreal model. Anime source, animation-oriented model. Mixed abstract source, a stylized or experimental model. Testing takes minutes; fighting the wrong model takes hours.
A Step-by-Step Workflow: From One Still to a Finished Clip
Step 1: Prepare the source still
This is the highest-leverage step and the one most often skipped. Upscale the image so the shorter edge is at least 1080 pixels, because low-resolution inputs produce smeared detail the moment anything moves. Crop deliberately: leave visual room in the direction of the intended camera move, and avoid cutting limbs at the frame edge, since the model will invent whatever it thinks should be there. Remove obvious compression artifacts and any text that should not shimmer later. If the image contains a face, make sure it is sharp and evenly lit; soft, noisy faces produce the worst results.
Step 2: Write a motion prompt
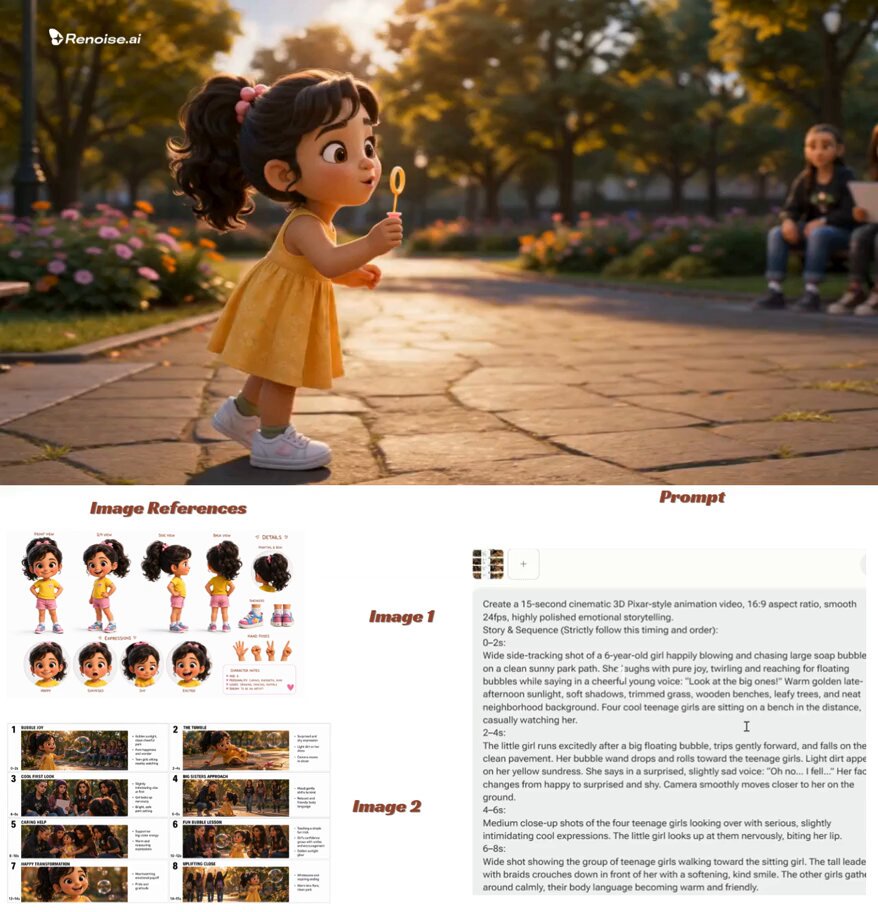
Describe change, not content. The model can already see what is in the image; what it needs to know is what should move and what should stay anchored. A reliable template is: subject motion + secondary motion + camera move + stability constraint. For example: "woman turns her head slightly toward camera, hair drifting in a light breeze, slow push in, background stable." Keep it under forty words. Long prompts dilute the signal and often contradict themselves.
Step 3: Tune duration and motion strength
Start at the shortest native duration your tool offers — usually two to three seconds — and the lowest motion strength that produces visible movement. Short clips are dramatically more stable, and you can always extend a good clip by generating a continuation from its final frame. Build the habit of earning length rather than requesting it up front.
Step 4: Generate variations, not a single take
Run the same settings three or four times with different seeds. Image-to-video output is stochastic; two runs from identical inputs can differ wildly in quality. Treating generation as sampling rather than as a single attempt is the single biggest quality upgrade available, and it costs nothing but patience.
Step 5: Assemble and edit
A single generated clip is rarely the deliverable. Import your best takes into a normal editor and do the work that makes generated footage feel intentional: trim to the moment of strongest motion, cut on movement so transitions feel motivated, slow the footage to 60–80 percent to smooth micro-jitter, add a subtle zoom or drift so the frame is never perfectly static, and layer in sound. Sound design does more for perceived realism than any generation setting, and it is the step most AI-first creators skip.
Prompt Patterns That Produce Clean, Believable Motion
Once you have run a few dozen generations, patterns emerge. The following approaches consistently outperform vague instructions:
- Anchor the background explicitly. Phrases like "background static," "only the flag moves," or "no camera movement" prevent the slow global drift that ruins otherwise good clips.
- Name one dominant motion. Two simultaneous motions compete, and the model usually botches both. Give a clip a single job.
- Use speed words. "Slow," "gentle," "gradual," and "subtle" measurably reduce artifact rates. "Fast," "rapid," and "dramatic" invite warping.
- Separate camera from subject. Use dedicated camera controls when available and keep camera language out of the text prompt.
- Describe atmosphere for depth. "Light haze drifting, dust motes rising" adds richness without touching the geometry of the subject.
- Match the medium. A paper-collage source wants paper-like motion; a photograph wants optical motion.
Also worth internalizing: negative phrasing works inconsistently. Saying "no distortion" is weaker than describing a state that excludes it, such as "stable framing, consistent geometry." Write toward what you want.
Troubleshooting: Common Failures and Their Fixes
The same handful of problems account for most disappointing output. Here is how to diagnose each one quickly.
Everything melts or warps. Motion strength is too high, the prompt implies a large subject movement, or the source resolution is too low to support motion. Halve the strength, simplify the prompt to one action, and upscale the input.
Nothing moves at all. The prompt describes a scene instead of a change. Rewrite it around a verb and raise motion strength slightly.
Faces drift, eyes slide, teeth smear. Extremely common with medium and full-body shots. Crop tighter so the face occupies more of the frame, enable identity preservation if available, drop motion strength, and prefer head turns under about twenty degrees.
Flicker or pulsing brightness. Often a symptom of very high detail in the source or of an aggressive stylization setting. Add a slight blur to the source, reduce detail-heavy texture, or stabilize luminance slightly in post.
Unwanted camera movement. The prompt includes ambiguous words like "sweeping" or "dynamic." Remove them and lock camera controls to zero.
Limbs bend unnaturally. Hands and elbows are the weakest region for these models. Hide them behind props, keep them outside the crop, or choose a composition where the body is largely still.
Text and logos shimmer. Never rely on a model to hold small typography steady. Animate the plate and composite the text on top afterward.
Keeping Characters and Style Consistent Across Shots
A single animated image is a demo. A sequence of them is a story, and sequences demand consistency. Three habits make this manageable.
First, define a style anchor: a short reusable description of the medium, palette, and lighting that you paste into every generation for a project, so nothing drifts toward generic photorealism halfway through.
Second, reuse the reference frame backward. If you need a new angle of the same character, generate a still of that angle first, approve it as a canonical image, and animate from that approved frame rather than from the animated output. Chaining generations multiplies degradation.
Third, hold a shot list with locked settings. Record the model, seed, motion strength, duration, and prompt that produced each accepted clip. When a director asks for a reshoot of shot four, you can reproduce its conditions instead of guessing, and when you hand a project to a collaborator, the look survives the handoff.
Audio, Pacing, and Post-Production Polish
Generated clips look more convincing the moment they are treated as footage rather than as final output. Practical steps that consistently help:
- Cut on motion. Trim so the clip begins a beat before the movement peaks and ends as it settles.
- Vary shot length. Uniform three-second clips read as machine output; alternating short and long shots read as editing.
- Add parallax and grain. A gentle depth-based move plus a light grain layer glues generated frames to the rest of your timeline.
- Design sound deliberately. Room tone, a matching foley pass, and music with a strong downbeat make motion feel purposeful.
- Consider frame interpolation if a clip was generated at a low frame rate and looks choppy, but apply it after trimming so it does not smooth away your cuts.
Building a Repeatable Pipeline
If image animation is becoming a regular part of your work, standardize the boring parts. Keep a project folder with subfolders for approved source stills, generated takes, selected clips, and exports. Store prompts in a plain text or spreadsheet shot list so they are searchable. Name files by shot number and version so nobody has to open a clip to identify it.
Plan compute realistically. Generating at 1080p and above is the slowest part of the loop, so batch your runs and do other work while they finish. When you can choose, prioritize resolution over duration: a crisp three-second clip can be extended, but a soft six-second clip is simply soft. Finally, keep a small library of source images you know work well — a portrait, a landscape, a product render, a stylized illustration — to test new tools against a controlled baseline instead of evaluating them on whatever happens to be on your desk.
Common Mistakes to Avoid
- Requesting complex choreography instead of a single dominant motion.
- Animating from a low-resolution or heavily compressed source and blaming the model.
- Chasing a single perfect generation instead of selecting from several takes.
- Letting the camera drift because the prompt was vague about the frame.
- Animating text-heavy graphics inside the model rather than compositing afterward.
- Forgetting licensing and consent. If a source image depicts a real person, a brand, or third-party artwork, confirm you have the rights to use the generated result, and check the terms of the specific tool you are using.
- Delivering raw generations with no sound design, no trim, and no grade.
FAQ
Can AI animate any still image?
Most images can be animated to some degree, but results depend heavily on quality. Sharp, well-lit, reasonably high-resolution sources with a clear subject work best. Heavy blur, dense text, extreme wide shots with tiny figures, and very noisy images produce poor motion.
How long should an AI-animated clip be?
Two to four seconds per generated segment is the sweet spot. Longer requests tend to introduce drift and warping. Extend by generating a continuation from the last clean frame rather than by asking for a single long clip.
Do I need an expensive computer?
Not necessarily. Many tools run in the browser or through a hosted API, which means the heavy computation happens remotely. Local generation requires a capable GPU, but it is optional rather than mandatory for most workflows.
Why do faces look wrong?
Because faces contain the most fine-grained detail in any frame, and any small inconsistency is immediately visible. Tighten the crop, reduce motion strength, keep head rotation small, and enable identity preservation when your tool offers it.
Should I animate a photograph or an illustration?
Photographs benefit from cinematic motion and a photorealistic model; illustrations benefit from stylized motion and a model that understands drawn media. Match the model to the source, and describe motion in the language of that medium.
Can I use the results commercially?
That depends entirely on the specific tool's terms and on the rights attached to your source image. Read the license for the platform you use, and be careful with images of real people, trademarks, and third-party artwork.
What is the fastest way to get better results?
Generate fewer, better-prepared inputs and more takes per input. Preparation and selection beat parameter fiddling almost every time.
How do I keep a series looking consistent?
Lock a style description, reuse approved stills as the starting point for new angles, and keep a shot list recording the exact settings behind every accepted clip.
