
Why Blender Skills Are a Starting Point, Not a Destination
Blender is still the most generous piece of software in the visual effects world. It hands independent creators modelling, sculpting, shading, rigging, simulation, and a production-grade renderer without a licence fee. That generosity has a hidden cost: every photorealistic frame has to be earned through geometry, materials, lighting, and render time. A convincing close-up of a human face can demand subsurface scattering, micro-detail textures, hair grooming, and hours of sampling before anyone has animated a single beat of the story.
Generative video does not remove the need for craft. It relocates the craft. Instead of building the wall, you describe the wall, choose the light, define the lens, and then judge the result the way a director judges a take. The creators who get the strongest results from AI video tools are usually the ones who already understand composition, motivated lighting, and continuity, because those instincts are what separate a random clip from a deliberate shot.
Treat Blender tutorials as a foundation rather than a ceiling. What you learn about orthographic blocking, key-to-fill ratios, focal length, and edit rhythm still applies. What changes is where you spend your hours: less time pushing vertices, more time directing, selecting, and finishing. This article lays out a realistic workflow for combining both worlds so your output looks like it came off a set, not out of a slot machine.
What Ultra-Photorealism Actually Means in Practice
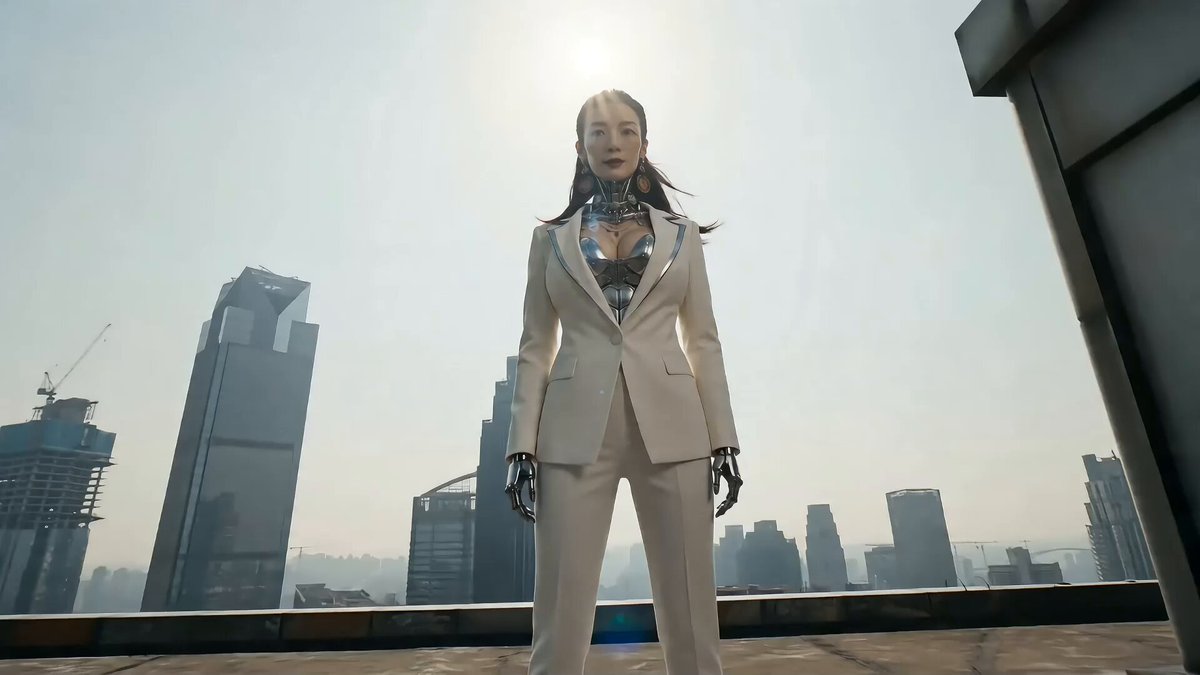
The phrase gets used loosely, so it is worth being precise. Ultra-photorealism is not resolution, and it is not sharpness. It is a bundle of perceptual cues that your eye checks in under a second, and any one of them failing will break the illusion no matter how many pixels you render.
Skin, fabric, and micro-surface detail
Human skin is translucent, oily in patches, unevenly textured, and covered in fine hair. Fabric has weave, weight, and drape. Metal has micro-scratches; painted surfaces have orange peel; glass has smudges. Generative models trained on real footage often nail these details automatically, which is precisely why they can outperform a rushed 3D render where the roughness map was left at a default value.
Light behaviour and lens realism
Photorealism is largely a lighting problem. Real footage has soft falloff, bounce from nearby surfaces, and highlight roll-off that never quite clips to pure white. Camera lenses add their own signature: slight chromatic fringing at the edges, gentle vignetting, a shallow depth of field that falls away in a curve rather than a hard line. When a generated shot feels plasticky, the cause is almost always lighting that is too even, too hard, or too bright for the scene.
Temporal coherence
A single beautiful frame is easy. A hundred and fifty frames that hold the same face, the same wardrobe, and the same shadow direction is the hard part. Coherence is what makes motion feel filmed rather than synthesised, and it is the first thing experienced editors scan for when evaluating generated footage.
Where Traditional 3D Pipelines Still Win
Before you move your entire pipeline, be honest about the shot types where Blender remains the better tool:
- Product accuracy. If a client needs a specific model of shoe, camera, or appliance, measured geometry beats interpretation every time.
- Exact camera moves. Matchmoves, locked-off tracking shots, and hero reveals that must align to a storyboard frame by frame.
- Text, logos, and interface graphics. Screen content and typography should be authored, not generated, then composited.
- Simulation with specific behaviour. A branded liquid pour, a mechanical rig, or a cloth fold that must behave a certain way.
- Legal and contractual assets. Anything where provenance must be documented internally.
The practical conclusion is not that one approach replaces the other. It is that you should route each shot to the method with the lowest total cost of looking right.
The Hybrid Workflow: Blender Plus Generative Video
This is the workflow most small teams converge on once they stop treating AI as a novelty and start treating it as a camera department.
Stage 1: Blocking and camera language in Blender
Build a rough set, place proxy characters, and animate camera moves at low quality. You are not rendering beauty here. You are solving staging problems: where the light comes from, where the actor stands relative to the window, how long the shot needs to breathe. Export a handful of clean frames as your reference package.
Stage 2: Generating photoreal plates
Take those reference frames into an image-to-video or text-to-video tool and generate the photoreal version. Seed the model with your blocking frame so camera position and subject scale stay honest, then write a prompt covering subject, action, lens, and light. Generate three to five variations per shot rather than one, because you are effectively shooting coverage.
Stage 3: Compositing and finishing
Bring everything into a compositor or editor. Cut between variations to hide weaker moments, paint out small artifacts, add practical elements like dust, flare, and grain, then grade the whole sequence as one piece. This is the step most beginners skip, and it is the reason their footage looks like clips stitched together rather than a film.
Choosing the Right Generative Approach for Each Shot
Not every shot needs the same tool or the same settings. Use these decision points.
Text-to-video versus image-to-video
Choose text-to-video when the shot is atmospheric and you can accept interpretation: establishing shots, weather, abstract transitions. Choose image-to-video when control matters: character close-ups, product inserts, or anything that must match an established frame. As a rule, the tighter your storyboard, the more you should lean on image conditioning.
Motion-heavy versus detail-heavy shots
Fast camera moves and complex body motion eat model attention, and detail suffers. If a shot needs both, split it: generate a wide moving shot for energy, then cut to a slower, detail-heavy insert. Editors have done this for a century for exactly the same reason.
Iteration budget
Ask how many attempts you can afford in time and compute before the shot stops being worth it. If a shot needs more than eight to ten attempts, the prompt is probably fighting the reference image, or the shot is simply better suited to traditional 3D.
Prompt and Reference Craft That Produces Believable Frames
Most disappointing generations come from vague prompts, not weak models.
The four-part shot prompt
Write in this order and keep each part short:
- Subject and wardrobe - a woman in her thirties, damp wool coat, no makeup.
- Action and beat - she turns toward the window and exhales slowly.
- Camera - 50mm lens, handheld, slight drift left, medium close-up.
- Light and grade - overcast daylight from frame right, cool shadows, muted teal highlights.
That structure reads like a shot list, and shot lists produce consistent results.
Reference images and character consistency
Reuse the same reference image for a character across shots, and keep the lighting description identical even when the location changes. Small contradictions, like switching from overcast to direct sun mid-scene, force the model to guess and produce faster drift.
Negative guidance
Name what you do not want: warped hands, plastic skin, oversaturated colours, watermark text, extra limbs, dutch angles. A short negative list is more effective than a long one; if you list twenty exclusions, the model may overcorrect and flatten the image.
Cinematography Rules That Transfer Cleanly to AI
Everything you know about shooting carries over, and this is where trained Blender artists have an actual advantage:
- Motivate the light. Give every source a reason to exist in the scene, whether it is a window, a lamp, or a screen.
- Shoot for the edit. Do not generate one hero shot; generate a wide, a medium, and a close-up so you have cut points.
- Respect the eyeline. In dialogue, keep the gaze consistent across angles or the scene will feel broken.
- Use focal length deliberately. Wide lenses for scale and unease, long lenses for intimacy and compression.
- Add imperfect texture. A little grain, breathing camera motion, and slight exposure variation signal reality.
In Blender you learn these by iterating on renders. In AI you learn them by iterating on takes. The knowledge is the same asset.
Quality Control: Catching Artifacts Before Delivery
Faces, hands, and teeth
Watch these at slow playback. Look for shifting pupils, teeth that change count, earrings that swap ears, and hands that merge with clothing. A ten-second fix in a compositor is better than a reshoot.
Temporal flicker and morphing
Scrub frame by frame at 25 or 50 percent speed. Texture that shimmers, background objects that breathe, and edges that crawl are usually fixable with a stabiliser, a degrain, or a short replacement cut.
Physics, contact, and reflections
Check that feet touch the ground, that footsteps land on the beat, that liquids find a surface, and that mirror reflections match the performer. Contact errors read as fake faster than any texture problem.
Finishing: upscaling, grading, and sound
The last ten percent of quality comes from finishing. Upscale your chosen takes, stabilise where needed, then grade the sequence in one pass so exposure and colour match. Add ambience and a subtle room tone under dialogue; sound sells realism more than most visual tricks. Finally, export at your delivery specifications rather than the model default, and check the result on a phone screen, where most viewers will actually watch it.
Common Mistakes That Sabotage Photorealism
- Chasing resolution instead of light. A 4K clip with flat lighting looks worse than a well-lit 1080p one.
- Generating one take per shot. No coverage means no options in the edit.
- Inconsistent wardrobe and weather. Continuity errors between shots destroy the illusion faster than any artifact.
- Over-prompting. Twenty adjectives pull the image in twenty directions; five strong ones keep it sharp.
- Skipping the edit. Cutting on action and using match cuts hides more model weakness than any setting.
- Grading each clip separately. It turns a sequence into a slideshow of different films.
- Ignoring audio. Silence makes synthetic footage feel synthetic.
- Abandoning fundamentals. If you learned blocking and focal length in Blender, use them.
FAQ
Do I need to learn Blender at all for AI video?
No, but it helps. Understanding framing, focal length, and lighting ratios shortens your learning curve dramatically because you already know what a good frame looks like. If you want one shortcut, practice still photography or study shot breakdowns of films you admire.
How many generations should I expect per usable shot?
For simple atmospheric shots, one or two. For character-driven shots with continuity requirements, budget five to ten. If you are consistently exceeding ten, the reference image or prompt structure is the problem, not the model.
Can AI video replace a full 3D pipeline?
For photoreal environments, people, and atmosphere, often yes. For measured products, exact camera choreography, typography, and simulation with defined behaviour, no. The strongest pipelines route each shot to whichever method gets a correct result fastest.
What resolution and frame rate should I work at?
Generate at the highest practical setting your tools allow, then conform to your delivery target. Most social delivery wants 1080p at 24, 25, or 30 fps depending on region; keep your generation frame rate consistent with your timeline to avoid interpolation artifacts.
How do I keep a character consistent across multiple shots?
Lock one clean reference image per character, reuse the same wardrobe and lighting description, and avoid regenerating the reference. If a shot drifts, regenerate from the reference rather than from a drifted frame, so errors do not compound.
Is it better to fix artifacts in generation or in post?
Try one regeneration first, since a clean take saves time. If the second attempt shows the same flaw, fix it in post. Recognisable patterns, like hands merging with a mug, are usually faster to paint out than to prompt away.
What is the fastest way to improve output quality?
Improve your lighting description and add coverage. Better light language fixes flat, plastic-looking frames, and more takes give you the cut points that make a sequence feel professionally assembled.
Where should a beginner start?
Pick one short scene of ten to fifteen seconds, block it in any tool you know, generate a wide, a medium, and a close-up, then edit and grade them together. Completing that loop teaches more than any single tutorial, because it forces you to confront continuity, pacing, and finishing in one pass.
