
Why Character Consistency Is the Hardest Part of AI Video
A generated clip can look spectacular and still be unusable. The lighting is cinematic, the motion is smooth, the skin detail is convincing — and then you cut it next to the previous shot and the character has quietly become someone else. The jawline is sharper, the hair has shifted from auburn to copper, the jacket lost its collar, and the eyes sit a few millimeters too far apart. Nothing is obviously wrong in isolation. Everything is wrong in sequence.
That is the core problem with AI video today. Image and video models are extraordinarily good at producing a plausible person. They are much less good at producing the same person twice, especially across different angles, expressions, and lighting conditions. Most video models treat every generation as an independent sample. Your text prompt describes a human being in words, and words are ambiguous: "a woman in her thirties with short dark hair" fits millions of faces. The model picks one, then picks a different one on the next render.
Consistency is rarely solved by a single setting. It is a pipeline problem with four layers: a reference pack that defines who the character is, prompts that stay disciplined, keyframes that anchor motion, and an assembly stage that repairs the drift that inevitably creeps in. Get those four layers right and a ten-shot sequence will feel like one film. Skip one of them and you will spend your weekend regenerating faces.
It also helps to define what "consistent" means before you start. There are four things that can drift, and they matter in this order: identity (the face), wardrobe and styling, palette and grade, and performance tone. Identity drift is the one audiences notice instantly. Grade drift is the easiest to fix in post. Know which one you are fighting before you change your workflow.
How Multi-Image Reference Actually Works
When you supply several images of the same character instead of one, you are not just giving the model "more examples." You are giving it a wider slice of the character's identity manifold — the range of ways that face can look while remaining the same face. One photo from one angle under one light is a single point in that space. Four or five images from different angles create a shape the model can navigate.
Different tools implement this in different ways, and it is worth knowing which family you are working with:
- Prompt-only conditioning. The model receives a text description and nothing else. Fastest and cheapest, weakest consistency. Useful for background extras and one-shot clips.
- Identity conditioning. Reference images are encoded into embeddings that guide generation, often through adapter layers that inject identity features into the denoising process. This is the mainstream approach for character work right now.
- Fine-tuned adapters. You train a small adapter on 15–40 images of your character. Highest fidelity and best cross-shot stability, but it takes preparation time and locks you into one model family.
- Post-process face replacement. Generate the shot however you like, then map a reference face onto the result. Reliable for static or slow footage; breaks down with fast head turns and heavy occlusion.
There is a failure mode specific to multi-image conditioning: conflicting signals. If four of your references show the character with glossy skin and one shows them with matte skin and heavy contouring, the model averages the two looks and produces something that is neither. Reference packs are not improved by volume. They are improved by agreement. Five images that describe the same lighting logic and the same makeup beat nine images that fight each other.
Building a Character Reference Pack
The shots worth including
Aim for six to twelve images, and treat them as a coverage sheet rather than a photo album. The most useful set usually looks like this:
- A clean frontal portrait at eye level, neutral expression, even light. This is the anchor.
- A three-quarter view turned roughly 45 degrees. This teaches the model how the cheekbones and nose behave in perspective.
- A profile. Profiles are where identity errors become obvious; giving the model one prevents it from inventing a silhouette.
- A slight low angle and a slight high angle, both mild. Extreme angles distort proportions and teach bad habits.
- Two or three expressions — a smile, a serious look, a mid-speech frame. Expressions change muscle positions, and the model needs to know which changes are allowed.
- A full-body or three-quarter-body shot if wardrobe matters, so the outfit is defined beyond the shoulders.
- One environmental shot in the palette you plan to shoot in, so the model associates the character with that color temperature.
What to leave out
Cut anything with strong color casts, dramatic rim lighting, sunglasses, hair covering the face, heavy motion blur, or heavy beauty filters. Also cut near-duplicates: nine frames from the same burst add nothing. And be ruthless about consistency inside the pack itself. If you are generating reference images rather than photographing a real person, generate them in one session with one consistent style string so their lighting logic matches.
File and folder hygiene
Name files by purpose rather than date: hero_front.png, hero_profile.png, hero_smile.png. Keep a character_bible folder per character with the reference pack, the canonical text description, the wardrobe notes, and the model or adapter settings that worked. When a project runs for weeks, this folder is the difference between resuming work and restarting it. Store your final description as a reusable text block — an 80–150 word paragraph covering age range, ethnicity or skin tone, hair length and texture, eye color, bone structure, build, signature wardrobe, and default expression. That block becomes the spine of every prompt you write.
Writing Prompts That Hold a Face Stable
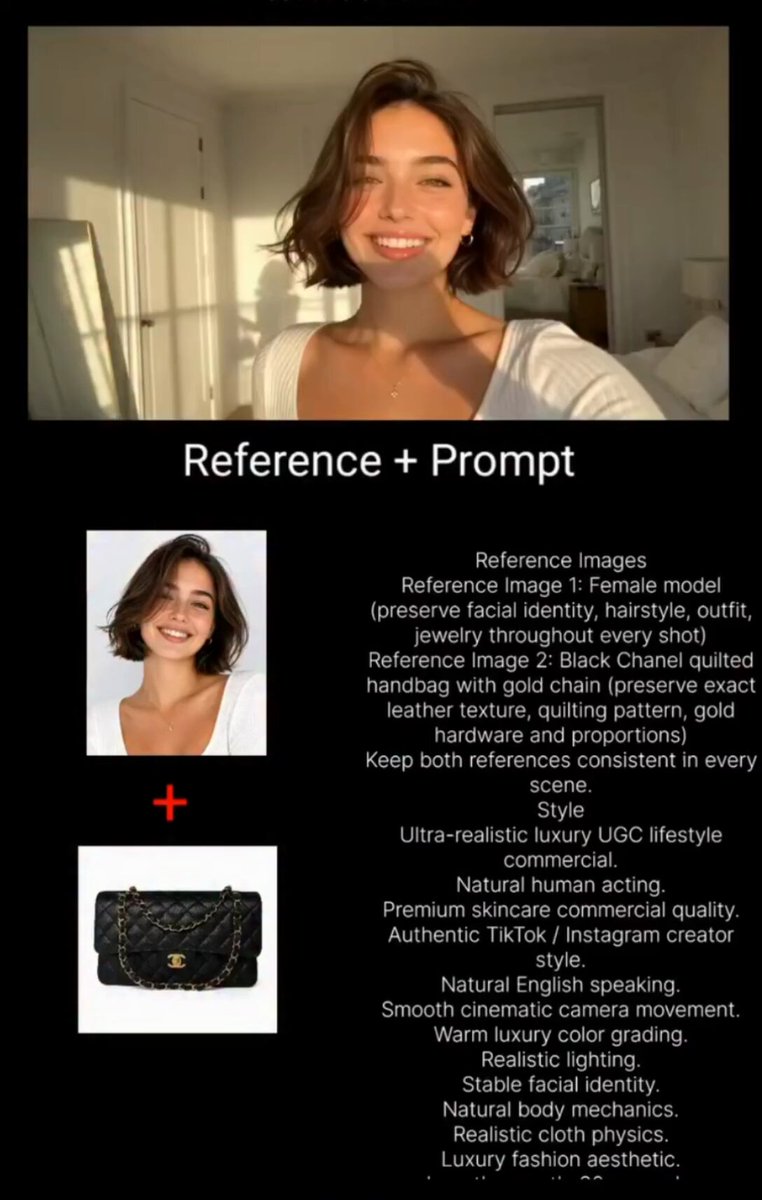
Prompt discipline is the cheapest consistency upgrade available. The rule is simple: describe the scene, not the person — because the person is already defined by your references. Every time you re-describe the face in detail, you invite the model to re-interpret it.
A workable prompt structure looks like this:
[shot type] + [character name from your bible] + [action] + [environment] + [lighting] + [camera and lens] + [mood] + [negative constraints]
For example: "medium close-up, Mara, turning to look over her shoulder, rooftop at dusk, soft directional key light from camera left, 50mm shallow depth of field, quiet tension, no costume change, no makeup change."
Three habits matter more than any keyword list. First, keep a fixed character token — a name or short handle — and use exactly the same words for it in every prompt. Second, keep wardrobe and lighting language identical across consecutive shots so only the action changes. Third, put your constraints in the negative space: no hats, no glasses, no wet hair, no dramatic shadows across the face. Most drift is caused by the model ignoring your character and satisfying a competing instruction instead.
Finally, resist the temptation to "improve" a prompt that worked. Save the exact string that produced your best shot and treat it as a template. Consistency is repetition, not iteration.
Keyframes, Shot Lists, and Continuity
Video generation is far more stable when you give it the first frame. Instead of asking a video model to invent a character and animate them, generate or select a still keyframe that already has the correct face, then animate from it. The model's job narrows from "create a person and make them move" to "move this person," which is a much easier task.
This changes how you plan. Build a shot list before you generate anything, and for each shot note four things: the shot size, the action, the start frame, and the end state. Then generate your keyframes as a batch, in one session, using one style string. Review them as a contact sheet and fix the ones that drift before you spend time animating.
For multi-shot sequences, keep these continuity rules in mind:
- Match on action where you can. Ending shot A with the character mid-turn and starting shot B from the same pose hides small inconsistencies.
- Change one variable per cut. If the angle, the wardrobe, and the time of day all change at once, the audience re-evaluates identity from scratch.
- Prefer shorter shots. Three-to-five-second clips drift less, and cutting on motion masks the seam.
- Reuse the last frame. Export the final frame of a clip and use it as the start frame of the next one. Chain four clips this way and the character stays locked even if each individual render has small errors.
Shot lists also make the work reviewable. A producer can approve a storyboard of stills in minutes; they cannot meaningfully approve ten finished clips they have to scrub through.
A Practical End-to-End Workflow
Stage 1 — Lock the character bible
Write the canonical description, assemble the reference pack, and generate test renders from three different angles before you commit to a script. If the character does not survive three angles in a still image, no video model will save you. Once you have a front, three-quarter, and profile render that read as the same person, freeze the settings and archive them.
Stage 2 — Generate in matched blocks
Do not generate shot by shot across different days with different prompts. Generate all keyframes for a scene in one sitting with one style string. Then generate all the video clips for that scene using the same motion vocabulary — the same words for camera movement, the same pacing descriptors. Blocks keep the model's internal state as similar as possible between renders, which is exactly what consistency needs.
Stage 3 — Assemble and repair
In your editing tool, assemble the sequence first with raw generations. Watch it end to end and mark every frame where identity slips. Then repair selectively: regenerate only the failing shot, or stabilize it with a face-consistent pass. Add grade and grain across the whole sequence last, because a unified grade makes small identity differences far less visible. A single LUT applied to the entire timeline can rescue a sequence that felt broken in isolation.
Choosing the Right Model for the Job
Model choice should follow the shot, not the other way around. Talking-head shots benefit from models with strong lip-sync and identity conditioning, because the face occupies most of the frame and viewers scrutinize it. Action and environment shots tolerate weaker identity retention — the face is small, moving, and partly obscured.
Practical decision criteria:
- Does the tool accept multiple reference images? If it only takes one, pair it with a fine-tuned adapter or a face-consistency pass.
- Does it support image-to-video with a start frame? This is the single biggest lever on stability.
- How long can one clip be before drift accelerates? Test it. Most systems hold well for a few seconds and degrade noticeably beyond that.
- How is aspect ratio handled? Re-framing after generation can crop heads and change perceived proportions.
- What does the iteration loop cost in time? A tool that renders in forty seconds lets you test five variations; a tool that takes ten minutes pushes you into one-shot gambling.
Pick two tools and go deep rather than sampling six. Depth produces working prompts; breadth produces frustration.
Common Mistakes and How to Fix Them
Over-describing the character in every prompt. Fix: move identity into references and the character bible, then keep prompts scene-focused.
Building a reference pack from mismatched sources. Fix: regenerate references in one session with one style string so lighting and grade agree.
Generating shots days apart. Fix: batch by scene, and save the exact prompt strings you used.
Ignoring wardrobe. Fix: define a signature outfit and reference it explicitly. Viewers use clothing as an identity cue as much as faces.
Fixing drift in post instead of at the source. Fix: identify whether the failure is identity, wardrobe, or lighting, then regenerate with a corrected reference rather than masking the problem.
Judging shots in isolation. Fix: always review in sequence, at speed, on a normal-sized screen. Individual frames lie; sequences do not.
Quality Control Checklist Before You Publish
Run this pass on every finished sequence:
- Watch it once at full speed with no pausing. Note the exact timestamps where your eye catches something.
- Freeze on the first frame of each shot and compare faces side by side.
- Check hair length and color at shot boundaries — this is where drift shows up first.
- Check wardrobe continuity, including collars, sleeves, and accessories.
- Confirm light direction matches between adjacent shots in the same scene.
- Confirm the grade is uniform, and that no single clip is noticeably cooler or warmer.
- Verify eye line and screen direction so characters do not flip orientation between cuts.
- Watch once on a phone. Small screens reveal whether consistency errors are structural or cosmetic.
FAQ
How many reference images do I actually need? Six to twelve strong, mutually consistent images. Beyond that, returns flatten and conflicting lighting starts to hurt more than extra coverage helps.
Can I keep a character consistent without training a custom model? Yes. Multi-image identity conditioning plus start-frame video generation plus disciplined prompts handles most short-form work. Training becomes worth it when you need a recurring character across many episodes.
Why does my character look right in stills but wrong in video? Motion models add temporal information you did not condition. Anchoring with a start frame and keeping clips short usually resolves it.
Should I generate the face and the environment together? Prefer generating the keyframe first with the correct character, then animating it. Environment and face in a single text-to-video pass is the least stable configuration.
How do I handle two characters in one shot? Generate them separately against matching backgrounds, then composite, or use a model with per-subject reference conditioning. Single-pass multi-character generation is still the weakest link in most pipelines.
What is the fastest fix when a shot drifts? Regenerate it with the previous shot's final frame as the start frame. Chaining frames solves more drift than any prompt rewrite.
Does resolution matter for consistency? Indirectly. Higher resolution preserves fine facial detail that the model can reuse as an identity anchor, but upscaling after generation does not recover identity that was never generated. Generate at the resolution the model handles best, then upscale.
How long should I budget for a ten-shot sequence? Plan on roughly an hour of generation, review, and assembly time per finished shot when you are learning the workflow, and considerably less once your character bible and prompt templates are reusable. The upfront investment in references and prompts is what makes later sequences fast.
