

Why Character Consistency Is the Real Bottleneck in AI Video
Ask anyone who has spent a weekend generating clips and they will tell you the same story. The first shot looks incredible. The lighting is cinematic, the face is expressive, the wardrobe is exactly right. Then you generate shot two, and your protagonist has quietly become a different person. The jaw is wider. The eyes sit lower. The jacket changed from charcoal to navy. Nothing is broken in an obvious way, and that is precisely what makes it so frustrating.
This is the cliff that almost every AI video project falls off. Raw generation quality has improved dramatically. Motion is smoother, hands are less cursed, and camera language is more controllable than it was even a short while ago. But a film is not a collection of beautiful shots. It is a sequence in which the audience believes they are watching the same people move through the same world. The moment identity drifts, the illusion collapses, and viewers start noticing the seams instead of the story.
So the practical question for creators is not "which model makes the prettiest frame?" It is "which workflow lets me hold a character steady across ten, twenty, or fifty shots without hand-correcting every one?" That is a workflow problem more than a model problem, and it can be solved with a disciplined approach to reference assets, keyframes, and scene planning.
This guide walks through the whole system: how reference-driven rendering works, how to build a character kit that survives scene changes, how to sequence your generation so mistakes are cheap to fix, and what to do when a shot inevitably comes back wrong.
The Core Problem: Every Scene Is a New Roll of the Dice
Text-to-video models are, at heart, probabilistic. Give the same prompt twice and you get two different people, because the model is sampling from a vast space of plausible faces rather than retrieving a stored one. A written description like "a woman in her thirties with short dark hair and a green coat" narrows the space, but it never closes it. There are millions of faces that satisfy that description.
This is why prompt engineering alone plateaus quickly. You can add detail — freckles, a scar above the left eyebrow, a specific coat cut — but each added detail is another chance for the model to interpret something differently in the next render. Prompt drift compounds. By the fifth shot, small deviations have accumulated into a different-looking character, and no amount of negative prompting brings them back.
Two other forces push in the same direction:
- Scene context override. When you place a character in a rainy night market, the model prioritizes matching that environment. Lighting, color grade, and even facial structure get pulled toward the scene's visual logic.
- Motion blur and angle change. A face seen at a three-quarter angle under motion blur carries far less identity information than a clean portrait. The model fills the gaps with plausible invention.
The fix is to stop treating the character as text and start treating them as an asset — a fixed reference the model must reconcile with, rather than a description it merely reads.
How Reference-Driven Image Fusion Actually Works
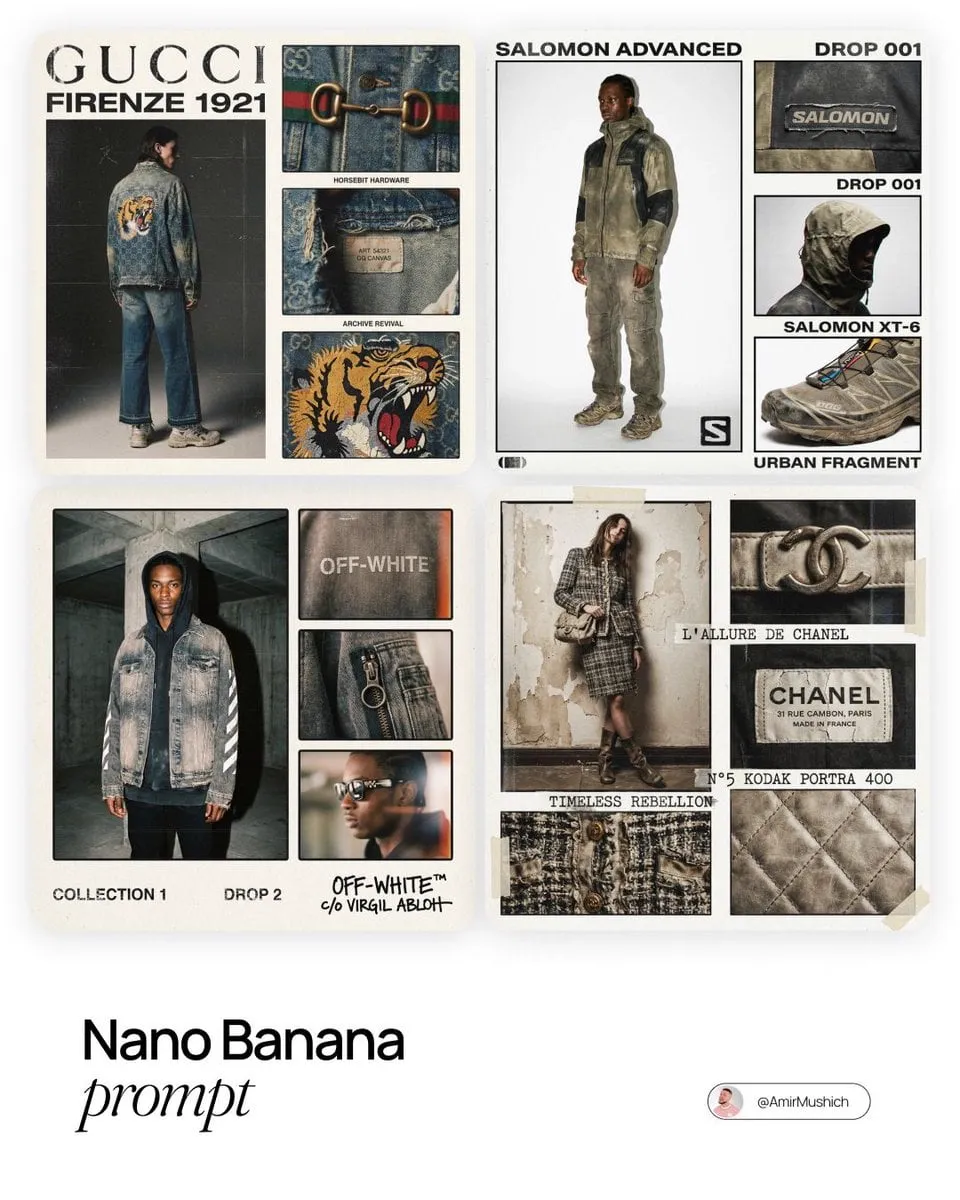
The idea behind reference-driven generation is simple: instead of describing the character, you show the model what the character looks like and instruct it to place that identity into a new scene. The identity comes from images; the scene comes from the prompt.
Under the hood, most modern systems handle this in a few layered ways.
Identity Tokens and Embeddings
Some approaches train a lightweight adapter on a handful of images of your character. That adapter learns a compact representation of the face and clothing, then injects it into the generation process. It is powerful but rigid — the trained identity is locked to a specific look, so asking for the same character in a different outfit or twenty years older requires retraining or blending.
Direct Reference Images
A newer and more flexible approach skips training entirely. You supply one or more reference images at generation time, and the model attends to them while building the frame. This is where the term "image fusion" becomes useful: the pipeline merges your reference identity with a scene description and outputs a frame that satisfies both.
In practice, a good fusion pipeline does three things:
- Isolates identity features — facial geometry, hair, skin tone, signature accessories — and treats them as constraints.
- Applies scene features — lighting direction, color palette, environment, camera lens — as the surrounding context.
- Reconciles conflicts — for example, keeping the identity stable while shifting skin tone responsively so a character under a warm tungsten lamp looks warm rather than pasted in.
Keyframe Control and Scene Continuity
References solve identity across scenes. Keyframes solve continuity within a scene. A keyframe is a still image that fixes the composition at a given moment; the model animates between or away from it. If you generate a clean, on-model frame of your character in a specific pose, that frame becomes the anchor for the motion shot. The result keeps the same face, same wardrobe, same framing logic, and adds believable movement.
Combining references with keyframes is what turns a pile of clips into a coherent sequence. References say "this is the character." Keyframes say "this is where they are and how they are framed right now."
Building a Character Reference Kit
Before you generate a single scene, invest an hour in reference assets. This is the highest-leverage work in the entire pipeline; every downstream shot inherits its quality.
Step 1 — Collect clean source images
Aim for six to twelve images, not one. A single portrait gives the model almost no information about how the character looks from other angles, and it will invent the rest. Cover:
- A straight-on neutral portrait with even lighting
- Two three-quarter views, left and right
- A profile view
- One full-body shot showing silhouette and proportions
- One shot in the costume they will wear for most of the project
- One expressive shot — laughing, frowning — to capture how the face deforms
Avoid: heavy filters, extreme stylization, sunglasses, hair covering the face, or dramatic single-source lighting. You want evidence, not mood.
Step 2 — Lock a hero shot
Choose the single best image and treat it as canonical. Every ambiguous decision — does the character have a widow's peak? is the coat belted or open? — resolves in favor of the hero shot. When two references disagree, the hero wins. Consistency beats completeness.
Step 3 — Write an identity brief
Keep a short plain-text block you paste into every generation: character name, age range, hair, wardrobe, and any immutable marks. This sounds redundant when you are supplying images, but it helps the model resolve conflicts and gives you something to diff against when a shot looks off.
A Repeatable Multi-Scene Workflow, Start to Finish
The most common failure in AI video is generating scenes in narrative order and hoping consistency holds. Reverse the logic: lock identity first, then build outward.
Phase 1 — Script to shot list
Break the script into shots, and for each shot note four things: location, time of day, camera framing, and which characters appear. This forces you to see how many times each character must render. A ten-scene short with two leads is not ten renders; it is twenty plus retries.
Phase 2 — Generate the anchor scene first
Pick the scene with the best combination of clear lighting, a clean framing, and high importance. Generate it fully, iterating until the character is perfect. This scene becomes your visual standard — your reference for color grade, lens feel, and costume detail. Export a few stills from it and add them to the reference kit.
This step is where most of your iteration budget should go. Getting one scene exactly right is worth more than getting five scenes approximately right, because the correct scene can seed the rest.
Phase 3 — Extend with keyframe-driven scenes
For each remaining scene, work in this order:
- Generate a still keyframe of the character in the new location and pose, using the reference kit.
- Inspect it at full resolution against the anchor. Check face, hairline, wardrobe details, and color temperature.
- Regenerate the keyframe until it passes.
- Only then animate it, using the approved keyframe as the first frame or as a control image.
This "still before motion" discipline saves enormous time. A bad keyframe costs seconds to detect. A bad animated clip costs minutes to render and is much harder to diagnose.
Phase 4 — Assemble, review, and repair
Cut the sequence together early, even rough. Watch it at normal speed, then at double speed, then frame by frame through the transitions. Human perception is most sensitive to identity shifts at cuts, so pay special attention to the first three frames after every edit.
When a shot breaks, resist the urge to regenerate blindly. Classify the failure: identity drift, wardrobe drift, lighting mismatch, motion artifact, or framing issue. Each has a different fix.
Choosing the Right Model and Mode for Each Shot
Different models excel at different things, and mixing them is not a compromise — it is a strategy, as long as your reference kit travels with you.
| Shot type | What to prioritize | Practical approach |
|---|---|---|
| Character close-up | Facial fidelity, skin texture | Reference-driven image generation, minimal motion |
| Dialogue scene | Lip sync, micro-expression | Keyframe anchor plus short clip length |
| Action beat | Motion coherence, camera energy | Shorter clips, more cuts, less identity dependence |
| Establishing shot | Environment, scale | Text-to-video is fine; character may be off-screen |
| Insert / detail | Texture, object continuity | Image generation, then subtle animation |
A useful rule: the more the shot depends on the audience recognizing your character, the more you should constrain the generation. Close-ups demand references. Wide establishing shots can be looser. Inserts of hands or objects need almost no identity control but do need continuity of wardrobe and props.
If a model produces gorgeous environments but wobbly faces, use it for environments and a different one for character work. Consistency across a project comes from your reference kit and edit, not from staying inside a single tool.
Changing Style Without Losing the Face
A common early frustration: you want the same character in a different art direction — photoreal in one scene, stylized in another, or aged across a decade. Aggressive style changes usually drag the face along with them.
The solution is to separate identity strength from style strength. When you push a strong style (anime, painterly, high-contrast noir), increase identity reference weight at the same time and, if the tool allows it, blend two references: the hero portrait for identity and a style frame for look. Let the system resolve both constraints rather than asking one image to do two jobs.
For aging, do not attempt a single giant jump. Generate intermediate stages — five years older, then ten — and use each as the reference for the next. Small steps preserve facial structure; large ones invite invention.
For wardrobe changes on the same character, keep the face references constant and swap only the costume reference. This is where a modular kit pays off: face set, wardrobe set, style set, and you recombine them per scene.
Common Failure Modes and How to Fix Them
The face slowly morphs across a sequence. Usually caused by chaining generations — using the output of the previous clip as the input for the next. Error accumulates. Fix by always referencing back to the hero shot, never to the last output.
The character looks correct but lit incorrectly. The reference image carried its own lighting. Fix by choosing references with neutral, even light so the model is free to apply scene lighting, and by describing light direction explicitly in the prompt.
Wardrobe drifts. Fabric details are low-priority for most models. Fix with a dedicated wardrobe reference image and explicit description of color, material, and fasteners.
The clone problem. Two characters in frame start looking like siblings because the model blends references. Fix by rendering them separately where possible, or by describing them with strongly contrasting features — hair, height, silhouette, color of clothing.
Identity collapses during fast motion. Motion blur destroys detail. Fix by shortening clips, cutting around the fastest moments, or placing the character slightly further from camera during heavy movement.
Every generation takes forever because you keep re-rolling. This is usually a sign that your keyframe is wrong, not your video settings. Fix the still, then animate.
Consistency for Series, Episodic, and Brand Content
Multi-scene consistency becomes a business problem the moment you produce more than one video with the same character. A recurring mascot, an episodic series, an explainer character used across a course — all of these need a character that survives months, not hours.
Treat your character like a small brand asset. Maintain a folder with the hero portrait, angle set, wardrobe sets, style frames, and the identity brief. Version it. Note which reference images produced which results. When a new project starts, the setup cost is minutes rather than days, and the character still looks like themselves.
For episodic work, also lock a small visual bible: three to five shots that define the look of the series. Every new scene should feel like it belongs in that set. This is not about limiting creativity; it is about giving the audience a stable world to relax into.
A Practical Pre-Render Checklist
Run through this before committing to a long render:
- Reference kit assembled and hero shot chosen
- Identity brief written and pasted into the prompt
- Keyframe approved at full resolution
- Wardrobe and prop continuity checked against the previous shot
- Lighting direction described in text, not inherited from the reference
- Clip length kept short enough to avoid motion artifacts
- Exported stills added back into the kit for future scenes
- Sequence cut roughly to check identity at the transitions
Most consistency failures trace back to a skipped item on this list.
FAQ
How many reference images do I really need?
Four is a workable minimum: one straight-on portrait, two three-quarter angles, and one full-body. Six to twelve is better if the character will appear in varied poses and environments. Beyond a dozen, returns diminish and contradictory images can confuse the model.
Can I keep a character consistent without training a custom model?
Yes. Direct reference-image approaches handle most character work without any training step. Training is useful when you need extreme fidelity and are willing to lock a single look, but for projects with costume changes and varied scenes, reference-driven generation is usually more flexible.
Why does my character look different in wide shots?
In wide shots, the face occupies few pixels, so identity information is thin. Push identity reference weight higher for these shots, keep the character's silhouette and wardrobe distinctive, and accept that the audience reads costume and posture more than facial detail at that distance.
Should I generate all scenes in one sitting?
You can, but only after the anchor scene and keyframes are approved. Generating narrative order before locking identity is the single most expensive mistake in AI video production.
How do I fix a shot that is almost right?
Change one variable at a time. If the face is right and the lighting is wrong, fix lighting only. Adjusting multiple parameters at once makes it impossible to tell which change helped, and you will regress without noticing.
Is a keyframe always necessary?
No. Establishing shots, inserts, and environment plates rarely need one. Use keyframes wherever the audience must recognize a specific character, and skip them where the shot is purely atmospheric.
Where to Go From Here
The gap between a good AI video and a forgettable one is rarely the model. It is whether the audience believes the same person walked through every scene. Fix that, and everything else — pacing, music, color — starts working the way it should.
Start small. Build a reference kit for one character. Generate one anchor scene and get it genuinely right. Then extend to three more scenes using approved keyframes. You will learn more from that exercise than from a month of scattered experimentation, and you will end up with a reusable asset library that makes every future project faster and more consistent than the last.
