
Why Cinematic AI Video Became a Production Skill
Generative video used to be a demo genre. You typed a dreamy sentence, waited, and received a six-second clip with melting faces and drifting architecture. Novelty carried it. That phase is finished. Current video models can hold a face across a camera move, resolve skin texture at close range, and produce footage that survives a 4K timeline without immediately falling apart.
What changed is not just model quality. What changed is that skilled people started treating generation as one step inside a pipeline instead of the entire pipeline. Pre-production, reference management, shot-by-shot model selection, sound, and grading now matter as much as the prompt. The creators producing genuinely cinematic results are not using secret prompts. They are running a disciplined workflow.
This guide walks through that workflow end to end. It is written for directors, editors, brand teams, and solo creators who want footage that reads as intentional filmmaking rather than as an AI artifact. Every section includes decision criteria you can apply on your next project, plus the failure modes that waste the most time.
What Separates Cinematic Footage From Generic AI Clips
Before optimizing anything technical, it helps to name what actually makes footage feel cinematic. The difference is rarely resolution. It is almost always three things: physical light, deliberate composition, and motivated motion.
Light behaves physically
Generic AI clips tend to be lit evenly and brightly, as if a soft panel were pointed at everything at once. Cinematic light has direction, contrast, and falloff. A face lit from a window on one side, with the other side falling into shadow, reads as real instantly. When you write prompts, specify the source, the direction, the quality, and the ratio: low sun from camera left, hard rim light behind the subject, practical lamps visible in frame with a cool ambient fill. Models respond well to these physical descriptions because they map to patterns in real footage.
The frame is composed, not filled
Amateur framing centers the subject and fills the frame edge to edge with detail. Cinematic framing uses negative space, foreground occlusion, layered depth, and off-center placement. You can request these deliberately: subject in the lower third, out-of-focus foreground railing, deep background with a second character walking away. Composition instructions cost nothing and change perceived production value more than any upscaler.
Motion has intent
AI clips often move because movement looks impressive. Film moves because the movement means something: a slow push as a character realizes something, a lateral track that reveals a second figure, a handheld drift that signals unease. Decide what each shot is doing dramatically before you decide how the camera moves. One motivated move beats four decorative ones.
Pre-Production: Shot Lists, Look Bibles, and Format Locks
The single biggest predictor of a bad AI video project is starting with prompts. Prompts are cheap, so people generate hundreds of clips and then try to assemble a story from the wreckage. Professional workflows invert this.
Write the shot list before you write prompts
Start with a lean shot list: ten to twenty shots for a short piece, each with a one-line purpose. Something like: establishing city at dawn, protagonist enters frame from left, insert of hands opening a letter, reaction close-up, wide reveal of empty apartment. Purpose first, visual second, prompt last. If a shot has no narrative job, cut it before you spend compute on it.
Build a one-page look bible
A look bible is a short reference document that keeps every generation aligned. Include:
- Two or three reference films, photographers, or painters for tone.
- A palette of four to six colors with rough hex values.
- One sentence on contrast and saturation behavior.
- One sentence on grain, texture, and era feel.
- The lens language: wide and wide, or telephoto and compressed.
- The rule for camera movement: locked off, slow push, handheld, or none.
When a generated shot feels wrong, the look bible usually identifies why in seconds.
Lock format early
Aspect ratio, frame rate, and resolution should be fixed before generation, not after. Vertical social cuts, 2.39:1 anamorphic-style framing, and 16:9 broadcast all demand different compositions. Generating in one ratio and cropping to another destroys the framing you paid for. Decide delivery targets up front and generate the hero format natively, then produce alternate crops as a separate pass with adjusted composition prompts.
Choosing the Right Generation Model for Each Shot
There is no single best video model. There are models that excel at different shot types, and mixing them deliberately is a legitimate craft decision. Match the tool to the shot, not the other way around.
Text-to-video for establishing shots and atmosphere
Text-to-video is strongest when nothing needs to be identical to anything else: landscapes, cityscapes, weather, abstract transitions, texture plates, smoke, water. These shots tolerate variation because the audience has no expectation of continuity. Use your most cinematic descriptive language here, and accept a lower success rate in exchange for a higher ceiling.
Image-to-video for character and product work
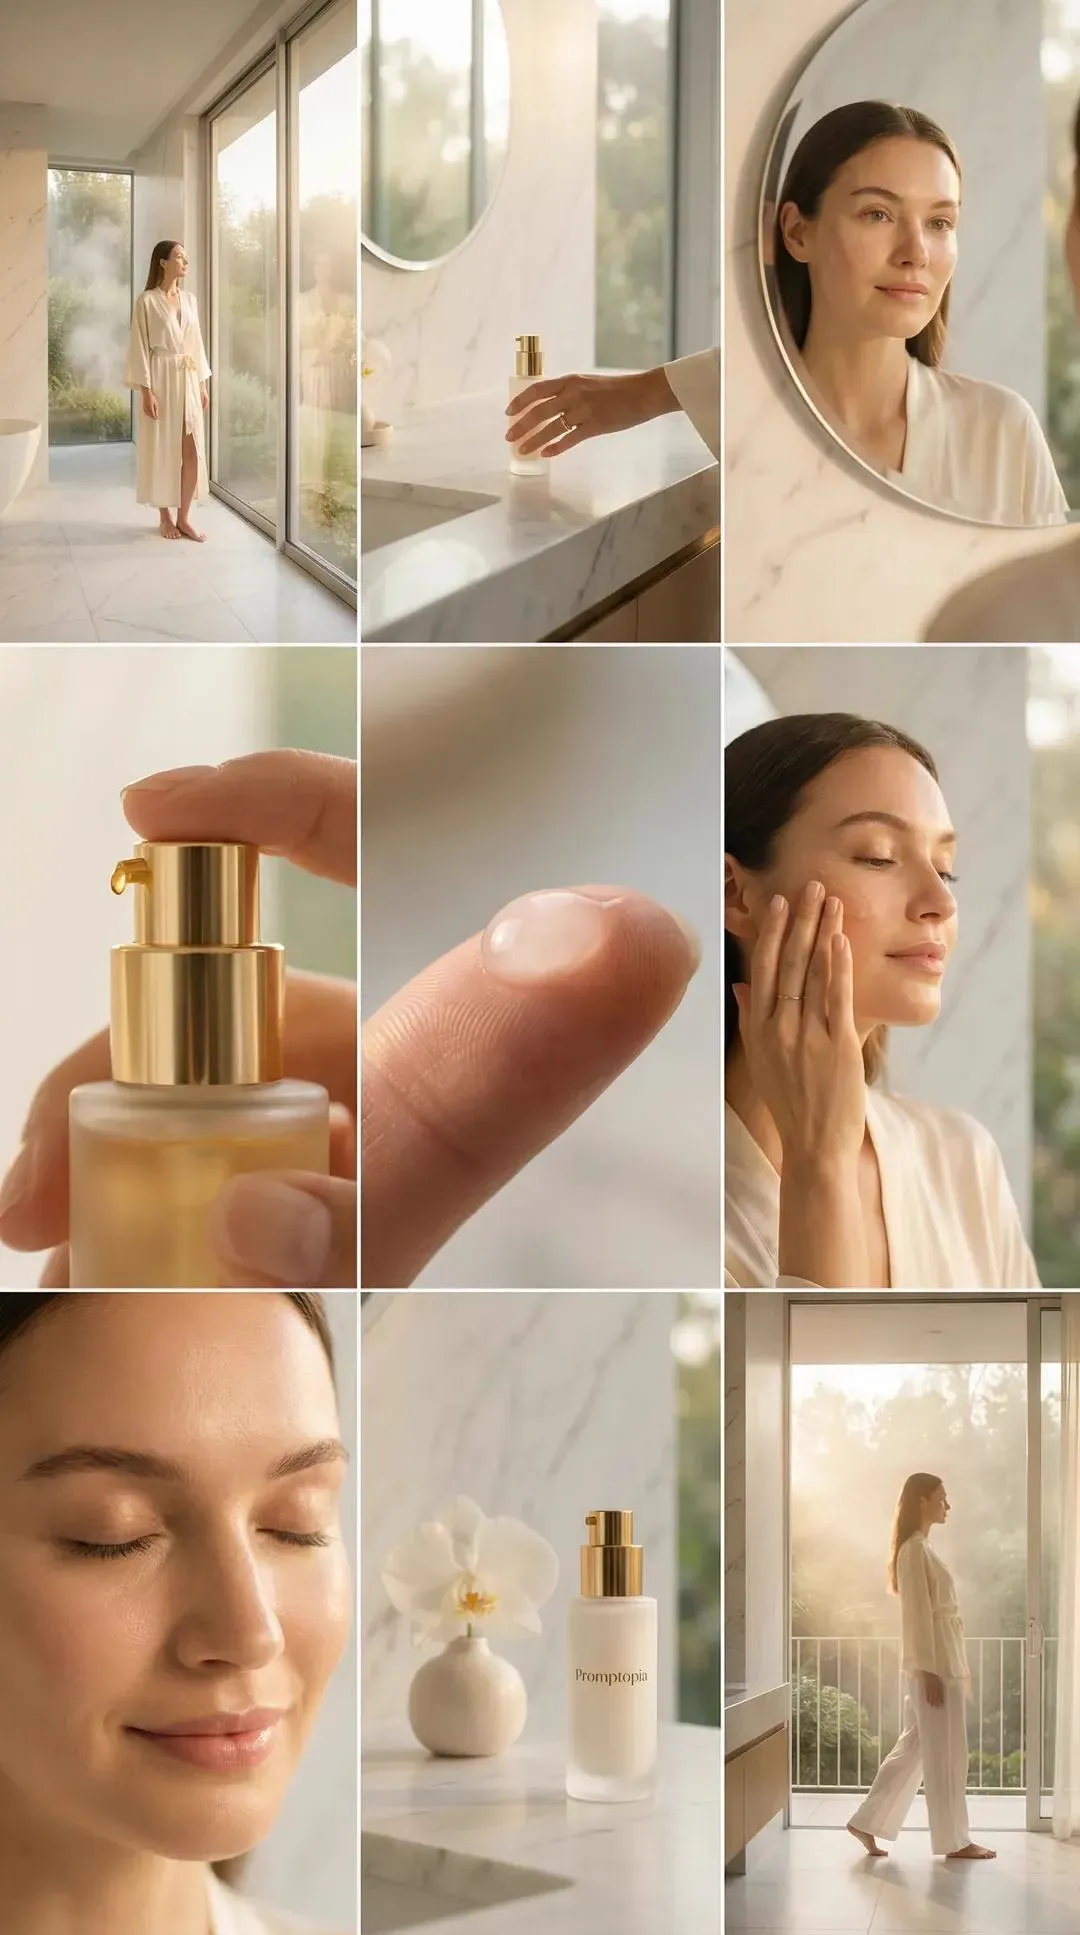
When continuity matters, generate or photograph a still first, approve it, then animate it. This separates two hard problems: getting the look right, and getting the motion right. Image-to-video also gives you precise control over framing, wardrobe, and expression before a single frame moves. Most cinematic AI sequences are built this way, with a hero still as the anchor.
Video-to-video and motion transfer for performance
If you need a specific gesture, walk cycle, or dance move, record a reference performance and transfer the motion. This is the most reliable route to believable human movement, and it is also the fastest way to fix the stiff, gliding quality that plagues purely text-driven clips.
Practical selection criteria
- Continuity requirement: high means image-to-video.
- Motion complexity: high means motion transfer or video-to-video.
- Duration needed: longer shots usually mean generating in segments and stitching.
- Cost per usable second: track this, not cost per generation. A cheap model with a 5 percent hit rate is expensive.
Prompting Like a Director: Structure and Specificity
Long, poetic prompts do not correlate with better footage. Structured prompts do. The most reliable pattern is a fixed slot order that you reuse for every shot, so you can debug one variable at a time instead of rewriting the whole prompt.
The six-slot prompt skeleton
- Shot type and lens: wide establishing shot, 24mm, low angle.
- Subject and action: a cyclist in a wool coat pedals slowly toward camera.
- Environment: wet cobblestone street, closed shopfronts, autumn morning.
- Light: overcast daylight, soft top light, cool shadows, warm window glow.
- Camera behavior: slow dolly forward, subtle handheld sway, shallow depth of field.
- Texture and finish: fine 35mm grain, natural contrast, muted teal and amber palette.
Reuse this order across every shot. When something breaks, you know whether to blame the subject description, the light, or the camera line.
Negatives and known failure modes
Name what you do not want. Common negative terms include warped hands, extra limbs, text artifacts, watermark, jitter, flicker, facial morphing, oversaturated colors, distorted background geometry, and unnatural gliding motion. Keep the negative list short and specific. A long list of vague negatives dilutes the prompt and can flatten the image.
Iterate one variable at a time
Change the light, keep everything else. Change the camera move, keep the light. This sounds slow, but it converges faster than rewriting full prompts, and it teaches you how each model interprets vocabulary. Keep a running log of prompts and results for the project. Within a week that log becomes the most valuable asset on your machine.
Consistency Across Shots: Characters, Props, and Locations
Consistency is where AI video projects usually collapse. A face drifts, a jacket changes color, a room gains a window. Solving it is a matter of anchoring everything that repeats.
Identity anchors
Create one approved reference for each recurring character: neutral expression, front-facing, even light, clean background. Use it as the source for every image-to-video generation featuring that person. If you must vary the angle, generate the new angle as a still first, compare it against the anchor, and only animate once it matches. Save multiple anchors: front, three-quarter, profile, and one full-body.
Prop and wardrobe consistency
Props drift just as much as faces. A red thermos becomes orange, then disappears. Lock props by describing them identically every time, including material and wear: scuffed steel thermos with a dented lid, matte finish. Where possible, generate a prop plate and composite it rather than relying on the model to reproduce it.
Location and palette locking
For recurring locations, choose a single establishing frame and treat it as canon. Describe that location with the same noun phrase and the same three light details in every prompt. Then enforce a shared grade in post so that small color differences between generations disappear.
When to stop fighting and cut instead
If a shot refuses to match after five or six serious attempts, restructure the sequence. Put a cutaway between the mismatch, change the angle dramatically so the audience resets, or replace the shot entirely. Editors solve continuity problems on real productions the same way.
Camera Language and Motion Control
Camera vocabulary is the most direct lever you have over perceived production value. Models understand a surprisingly wide range of traditional terms, but they handle some better than others.
Lens and distance vocabulary
Wide, medium, close-up, extreme close-up, and insert all work reliably. Focal lengths are interpreted loosely but usefully: 18mm and 24mm read as wide and distorted near the edges, 85mm and 135mm read as compressed with shallow focus. Specify aperture behavior when depth matters: shallow depth of field, background bokeh, focus on the eyes.
Movement verbs that hold up
Reliable: slow push in, dolly out, lateral track left, crane up, tilt down, orbit around subject, handheld follow. Less reliable: complex compound moves, whip pans with a stop, fast reframing mid-shot, and anything requiring a precise end position. If a move must land exactly, split it into two shots and cut.
Duration and rhythm
Short generations of two to five seconds cut together with more energy than one long drifting take. Build a sequence from many short, purposeful shots, then extend only the shots that genuinely need room to breathe. Rhythm is created in the edit, not in the model.
Sound, Voice, and Editorial Rhythm
Audiences forgive imperfect images far more readily than imperfect sound. Silent AI footage feels like a tech demo; the same footage with ambient design and a music bed feels like a film.
Layered ambience
Build every scene with at least three sound layers: a room tone or environment bed, mid-level detail sounds tied to visible action, and a sparse high-frequency accent for texture. Footsteps on wet stone, a distant tram, a radiator ticking. Sound designers call this worldizing, and it sells the image more than any sharpening pass.
Voice and dialogue
If you need spoken lines, generate or record cleanly and treat the audio as a separate production. Write shorter lines than feels natural, because AI-generated speech loses nuance over long sentences. Keep music out from under dialogue, and use room reverb on the voice to match the visual space. A close-up in a small tiled room should not sound like an open field.
Music and tempo
Choose the music before the final edit if you can. Cutting to a tempo produces far better pacing than cutting first and hoping a track fits. Map your key beats to musical accents, then let the ambient bed carry the moments between them.
Post-Production: Upscaling, Grading, and Final Polish
This is where generated clips become a coherent film. Post-production is not optional cleanup; it is where the cinematic identity is actually applied.
Detail recovery and upscaling
Upscale selectively. Tools like Topaz Video AI or comparable models can recover detail and reduce compression artifacts, but aggressive settings produce a plastic, over-processed look. Upscale at moderate strength, then add grain back to restore organic texture. Compare frames at 200 percent before committing to a whole timeline.
Grading and unification
Generated clips from different models will not match by default. Bring everything into a grading tool such as DaVinci Resolve and normalize first: exposure, white balance, contrast. Then apply the look from your look bible as a shared node structure or LUT. Subtle grain, slight halation on highlights, and a gentle vignette unify mismatched shots faster than any other technique.
Cut points and pacing
Cut on motion, on a look, or on a sound accent. Avoid cutting in the middle of a slow drift, which reveals that the shot was generated rather than filmed. When a generated shot has a weak first half-second, trim it and start on the strong frame. Nobody in the audience knows what you removed.
A finishing checklist
- Frame rate conversion completed, no judder on movement.
- All clips share a single grade and grain pass.
- Titles and lower thirds use one typeface family and consistent weight.
- Loudness normalized across the whole piece.
- Delivered in the correct aspect ratios without stretched crops.
Common Mistakes, Troubleshooting, and FAQ
Mistakes that break the illusion
The most frequent problems are predictable. Generating before planning, which produces disconnected pretty shots. Over-prompting, which flattens images into generic beauty. Ignoring sound until the end, which is the single fastest way to make good footage feel amateur. Refusing to cut, which forces weak shots into the final piece because they took effort to make. And skipping the grade, which leaves every shot with a different color signature.
Troubleshooting quick reference
- Faces morph on camera moves: switch to image-to-video with an identity anchor.
- Everything looks flat: add directional light and contrast language, and reduce the number of competing details in frame.
- Motion looks like gliding: use motion transfer from a reference performance.
- Clips do not match: grade them together, cut away between them, and consider regenerating one with a shared location phrase.
- Output looks over-sharpened: lower upscale strength and reintroduce fine grain.
Frequently asked questions
How long should a single generated shot be?
Two to six seconds is the practical sweet spot. Longer generations drift, lose coherence, and cost more to fix than to replace. If a scene needs twenty seconds, build it from four purposeful shots.
Do I need different tools for different shots?
Usually yes. Most successful sequences combine text-to-video for atmosphere, image-to-video for characters, and motion transfer for performance. The skill is knowing which tool suits which shot, not finding one tool that does everything.
How do I keep a character recognizable across a whole video?
Approve one still as canon, generate every angle from it, and grade all appearances together. Reuse the identical descriptive phrase for the character in every prompt. Consistency is a process, not a setting.
Is AI video good enough for client work?
For short-form brand films, product sequences, mood pieces, and social campaigns, yes, provided the sound and grade are handled professionally. For long narrative dialogue scenes, a hybrid approach with real footage still produces better results.
What should I learn first if I am starting out?
Shot lists and editing. Understanding why a cut works and how a sequence builds means you will get usable results from any tool. Prompt vocabulary is easier to learn once you know what you are trying to build.
Building a Repeatable Cinematic Workflow
The shift from generating clips to producing films is mostly organizational. Plan the shot list, define the look, anchor your characters, match the model to the shot, design the sound, and finish with a unified grade. None of those steps is exotic, and together they explain the visible gap between footage that looks like a demo and footage that looks like a film.
Start small: a thirty-second piece with eight to ten shots, built with a strict pipeline from beginning to end. The lessons you take from finishing one coherent short are worth more than a hundred isolated generations. Once that workflow is in your hands, longer projects stop being intimidating and start being a matter of scheduling.
