
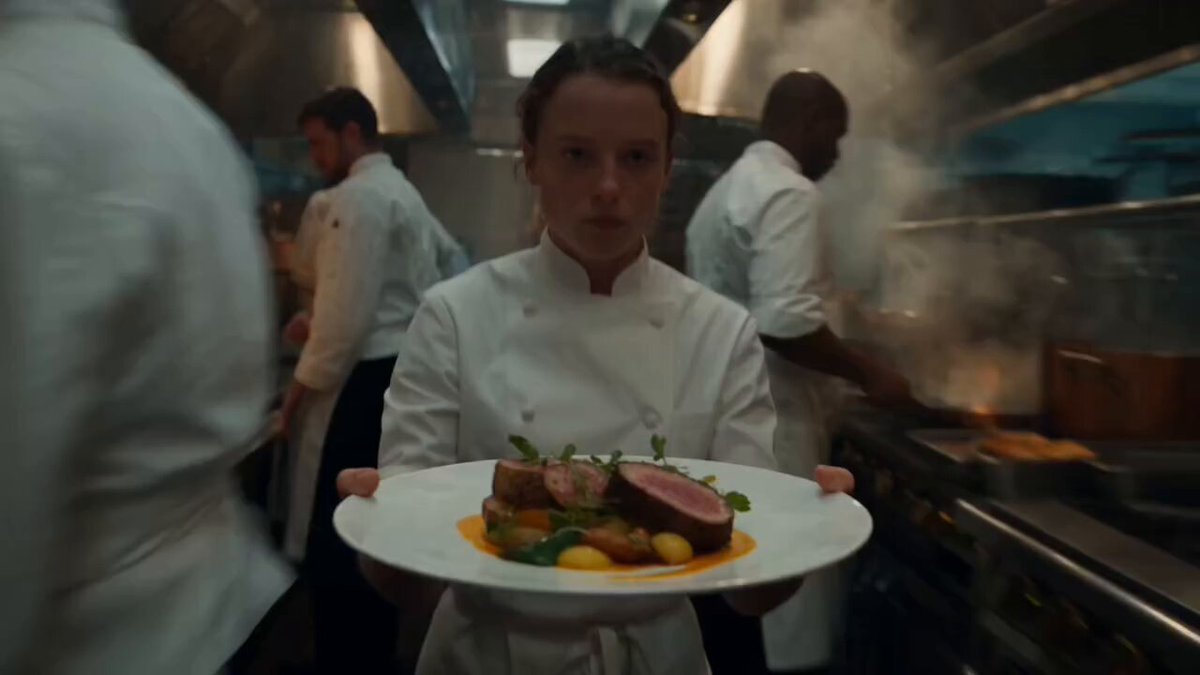
What "Cinematic" Actually Means in Generated Footage
Most people use "cinematic" to mean a color palette: teal shadows, warm highlights, shallow depth of field, anamorphic flares. That is the surface layer. The deeper meaning is a set of continuity contracts that a viewer's brain checks without being asked.
A shot reads as cinematic when four things hold together: the subject stays recognizably the same person or object, the camera moves the way a physical camera would, the light behaves as if it came from a real source in a real space, and the cut rhythm respects the audience's attention. Generated video fails most often on the first and second contracts. Foreheads widen between frames, a dolly turns into a drift, a jacket changes from charcoal to navy mid-turn.
That is why the interesting work in AI video is not model selection. It is building a workflow that protects continuity while still letting the model invent texture, atmosphere, and micro-performance. Think of the generator as a very fast, very literal cinematographer with no memory of the previous shot. Your job is to be the memory.
The Four Control Layers of a Cinematic AI Shot
Every generated shot can be decomposed into four layers that you control separately. Mixing them into a single prompt is the most common reason output feels generic.
Layer 1: Composition and framing
Decide the shot size, lens feel, and staging before writing any prompt. "Medium close-up, 50mm-equivalent, subject at left third, background compressed" is a composition instruction. "Beautiful woman in a city" is a wish. Composition instructions survive generation far more reliably than adjectives, because they constrain geometry rather than taste.
Layer 2: Motion and time
Describe what moves, how far, and over how long. A five-second shot can hold roughly one primary action and one secondary motion. Ask for more and the model averages everything into a muddle. If you need a character to stand, turn, and walk toward camera, either extend the shot or split it into three shots joined by match cuts.
Layer 3: Identity and wardrobe
This is where reference conditioning earns its keep. Feed the model a small, consistent reference set: one clean frontal, one three-quarter, one profile, and one full-body frame under the same lighting. Wardrobe should be described by material and construction — "quilted olive field jacket with brass zipper" — not by brand or vague mood words, because material words give the model something physical to render.
Layer 4: Light and grade
Light is the cheapest way to make unrelated shots feel like one scene. Pick a source logic and keep it: single window at camera left, practical lamps behind subject, overcast top light. Then commit to one grade direction — a print-film emulation with slightly lifted blacks, for example — and apply it uniformly in post rather than asking each generation to nail the look.
Building a Shot Plan That Survives Generation
A shot plan for AI video is not a screenplay excerpt. It is a continuity document. For each shot, record: shot number, duration, shot size, camera move, subject action, wardrobe state, light logic, and the reference images attached. This turns generation into a repeatable process instead of a slot machine.
Start with a scene inventory. Write the scene in plain prose, then split it into beats. A beat is a change in information: someone notices something, someone decides, someone leaves. Each beat becomes one or two shots. Most 40- to 60-second AI scenes land cleanly at six to nine shots of four to seven seconds each.
Worked example: a 45-second scene in seven shots
Imagine a short scene: a courier waits in a rain-soaked alley, checks a package, hears footsteps, and walks out of frame.
- Shot 1, 6s, wide, slow push-in, courier enters alley, hood up. Establishes light logic: single sodium lamp at frame right.
- Shot 2, 5s, medium, static, courier crouches and opens the bag. Wardrobe anchor: olive jacket, wet shoulder.
- Shot 3, 4s, insert, static, hands lift a wrapped parcel. Hands are the risk area — generate this as a short, low-motion shot.
- Shot 4, 5s, close-up, slight handheld, courier looks off-screen left. Reaction beat.
- Shot 5, 4s, over-shoulder, static, empty alley mouth in the background. Creates the off-screen threat.
- Shot 6, 7s, medium-wide, lateral tracking, courier steps away from the wall and moves left.
- Shot 7, 6s, wide, static, courier exits frame; hold two seconds on the empty alley, rain continuing.
Notice what the plan does. It gives the model short, single-purpose actions. It repeats the same light source. It keeps wardrobe in one state. It uses inserts and reactions to hide the places where generated anatomy and physics are weakest. And it ends on an empty frame, which is the easiest thing in the world for a generator to render convincingly.
Identity and Character Consistency Across Shots
Character consistency is the hardest problem in generated video, and it is largely a data problem rather than a prompt problem.
Build a character bible with five to eight reference images. Include at least two lighting variations, because a model trained to expect one lighting condition will drift when you change the scene. Crop tightly on the face for identity conditioning and separately keep a full-body plate for wardrobe and proportion. When a shot involves a new angle — a low angle, a back view, a profile — generate a still of that angle first, approve it, and use it as the conditioning frame for the video.
Expect drift, and plan for it. Identity weight tends to fall off as motion increases. If a character must turn their head fully, split the turn across two shots with a match on movement rather than asking for one long rotating shot. Long continuous action is where faces melt.
Two more practical habits help enormously. First, lock wardrobe early: once a shot is approved, export the frame and reuse that exact garment description with no paraphrasing. Second, avoid introducing new characters in the same shot as an existing one unless you have clean references for both; two-conditioned-identity shots are where models start blending features and producing an uncanny middle face.
If consistency still fails, reduce ambition rather than adding prompt words. Fewer moving elements, shorter duration, tighter framing, and stronger reference plates almost always beat longer descriptions.
Camera Language, Physics, and Motion
Generated motion tends to fall into three categories: motion the model understands well (parallax, drift, handheld sway, rain, smoke, hair, cloth), motion it understands partially (walking, turning, sitting), and motion it understands badly (complex hand interaction, contact-heavy actions, crowds, fast sports). Build your shot list so the story lives in the first category and merely visits the others.
When specifying camera movement, use film vocabulary and include magnitude. "Slow dolly in" is better than "moving camera"; "slow dolly in, roughly half a meter over five seconds" is better still, because it gives the model a rate. Add stabilization intent: "locked-off tripod" and "subtle handheld" produce visibly different results and both are reliable. Whip pans, snap zooms, and crash zooms are unreliable — a whip pan's blur can be simulated in editing with a two-frame directional blur on a cut, which looks cleaner than a generated pan.
Physics simulation matters most in contact and weight. If a character sets down a heavy crate, the model needs to convey weight through timing: a slight pause, a bend, a settle. You cannot ask a generator for force directly, but you can ask for the visible consequences — flexed arms, a slower descent, a small bounce as it lands. Phrase physics as observable behavior.
Where the shot requires precise articulation, cheat. Use a cutaway, an insert of the object alone, a shadow on a wall, a hand entering frame and leaving. Cinematic grammar has always hidden difficulty; generated video simply makes that instinct mandatory.
Prompting and Frame Control for Temporal Coherence
A video prompt is a schedule, not a description. Write it as a sequence of events with a camera instruction attached.
The four-part prompt skeleton
- Subject and wardrobe, one clause.
- Action verb with direction and rate, one clause.
- Camera move with magnitude, one clause.
- Light and atmosphere, one clause.
Keep it around 25 to 45 words for a five-second shot. Long prompts do not add control; they add competing instructions, and the model resolves the conflict by averaging.
Describe motion with verbs, not adjectives. "She turns her head toward the window" beats "she looks contemplative." Internal states should be expressed through physical cues: a swallow, a blink, a shift of weight, an exhale in cold air.
Keyframes, extensions, and loops
First-and-last-frame conditioning is the most powerful control surface available to most creators. Generate or select two stills — the start and end state — and let the model interpolate. It reduces identity drift because both ends are anchored, and it makes match cuts trivially easy: end shot A on the same composition that begins shot B.
For extensions, generate three to four seconds at a time and stitch. Overlap by a few frames at each junction and cut on motion, ideally during a camera move or a moment of occlusion, so the splice hides. Loops work best with ambient motion: rain, drifting smoke, slow camera creep, a flickering sign. Seamless loops require the first and last frames to be nearly identical, so crop your loop point to a moment of minimal change.
Finally, generate more takes than you need and keep a shot bin. The best take for shot 4 sometimes comes from take 11, and having a bin means you can swap a weak moment without regenerating an entire scene.
Editorial Finishing and Quality Control
Sound design is half the illusion
Sound is where AI video stops looking like a demo. Add a continuous room tone under the whole scene — rain, HVAC hum, distant traffic. Layer spot effects on action: cloth movement, footsteps, a zipper, a footstep splash. If dialogue exists, record or synthesize it separately and place it in the mix rather than relying on lip-sync generation for anything longer than a short line. Even two seconds of accurate ambience makes a mediocre shot read as intentional.
Pacing and grade
Cutting on action is more important with generated clips than with photographed ones, because generated frames have subtle instabilities at rest. Motion hides instability. Keep most shots under seven seconds, and let one or two shots breathe longer if they are slow and stable.
Grade at the end, uniformly. Apply one look to the assembled timeline rather than per-clip, add a small amount of grain or film emulation to unify texture, and match black levels across shots. If a shot is noticeably softer or sharper than its neighbors, a slight sharpening or softening pass in the edit will do more for continuity than regenerating it.
A shot review checklist
Before a shot is approved, check: does the face hold identity through the full duration; do hands stay anatomically plausible; does the background stay structurally stable; does the light direction stay consistent with the scene logic; does motion start and end cleanly; is there any texture boiling or shimmer; does the frame hold up when paused. A shot that fails two or more of these is cheaper to regenerate than to salvage.
Common Failure Modes and How to Fix Them
Identity drift. Cause: too much motion, weak references, or lengthy duration. Fix: shorter shots, stronger reference plates, split the action across two cuts.
Melting hands and fingers. Cause: small, high-articulation detail at low pixel coverage. Fix: crop hands out, use insert shots, keep hands outside the frame during dialogue, or reduce motion to near-static.
Texture boiling and shimmer. Cause: high-frequency detail such as foliage, crowds, or fine patterns under camera motion. Fix: reduce camera movement, soften the background with depth of field, or replace the background entirely with a plate.
Warping architecture. Cause: long lens moves through complex geometry. Fix: use locked-off shots for interiors and reserve movement for simple spaces, or mask and track a real plate behind generated subjects.
Ghosting and double limbs. Cause: conflicting motion instructions or an interpolated frame that contains two states. Fix: simplify to one action per shot, and check extension junctions frame by frame.
Over-smoothing. Cause: aggressive stylization or heavy upscaling. Fix: add grain, reduce denoise strength, and avoid stacking multiple enhancement passes.
Jitter at cut points. Cause: mismatched stabilization between shots. Fix: apply one stabilization and one grade across the timeline, and cut on movement rather than on stillness.
Choosing Tools by Constraint, Not by Hype
Model quality changes every few months, so pick tooling based on constraints you actually have.
Ask these questions. What is the maximum reliable shot length? Does the tool support first-and-last-frame conditioning and image references? Can it accept multiple character references at once? What resolution and aspect ratios does it output natively? How long is a typical render, and how much iteration can you afford per shot? Is there an API for batch work? What are the licensing terms for commercial use? Does it preserve a consistent style when you reuse the same prompt family?
Then map tools to tasks rather than picking a single winner. Some generators are excellent at atmospheric establishing shots and struggle with faces. Some are strong at identity and weaker at large camera moves. Some are fast and cheap enough for rapid storyboard previews, and those previews are genuinely valuable: a rough animatic of your seven-shot plan tells you whether the pacing works before you spend hours on final generations.
A practical stack looks like this: still-image generation for reference plates and keyframes, a video generator with reference conditioning for hero shots, a fast generator for previews and background motion, and a standard editing suite for assembly, sound, and grade. Keep your scene continuity document open beside the timeline. When something drifts, the document tells you which layer broke.
Frequently Asked Questions
How long should each generated shot be?
Four to seven seconds is the sweet spot for most workflows. Shorter shots are easier to control and cut together well; longer shots accumulate drift. If you need a long take, build it from overlapping generations cut on motion.
Do I need reference images, or can I rely on text descriptions?
Text alone can produce a beautiful single shot, but it cannot hold a character across a scene. If your video has a recurring protagonist, reference conditioning is not optional.
Why does my character look right in stills but wrong in motion?
Because identity conditioning weakens as motion increases. Reduce the complexity of the action, shorten the duration, and anchor both the first and last frames with approved stills.
What framerate should I work in?
Choose one and stay consistent. A filmic cadence suits narrative work; a higher cadence suits screen-content and product footage. Converting between the two introduces artifacts, so decide before you generate.
Should I generate the whole scene and then cut, or generate shot by shot?
Shot by shot, always. Generate each shot against your continuity document, approve it individually, then assemble. Generating a long sequence and hunting for usable fragments is slower in practice and rarely produces a coherent scene.
How do I hide the places where generation is weakest?
Use classical film grammar: inserts, reaction shots, silhouettes, off-screen sound, shallow depth of field, and cuts on movement. Obstruction and implication are not workarounds — they are how cinema has always handled difficult action.
What is the most common beginner mistake?
Overwriting prompts. Long prompts create competing instructions, and the model resolves conflict by producing something average. Write four short clauses, generate, evaluate against the checklist, and change one variable at a time.
The throughline across all of this is simple: be the continuity brain for a system that has none. Plan shots for the model's strengths, protect identity with references, describe motion as a schedule, hide weak articulation with cinematic grammar, and unify everything in the edit with sound and grade. Models will keep improving, but the workflow discipline is what makes footage look directed rather than generated.
