
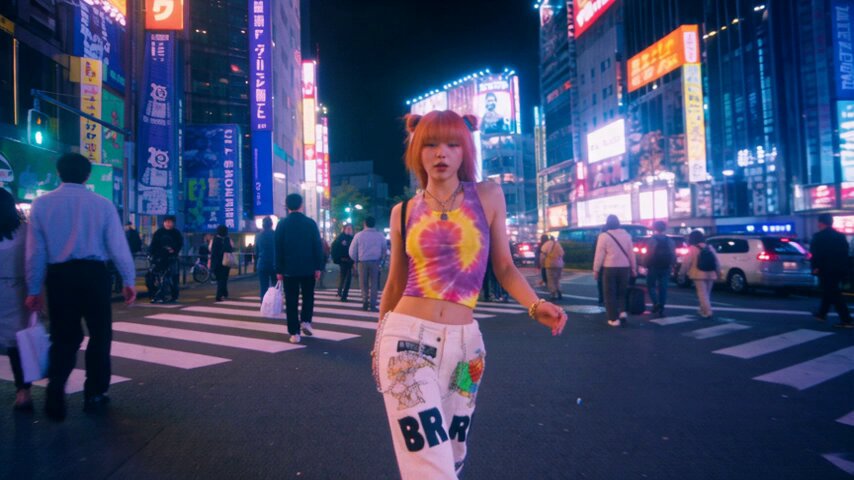
Cinematic short-form video used to be a contradiction. Film language — long lenses, shallow depth of field, motivated lighting, deliberate pacing — was expensive and slow. Instagram demanded speed, volume, and a vertical frame. Generative video tools collapsed that tradeoff. A solo creator with a laptop, a shot list, and a decent prompt vocabulary can now produce nine-second clips that genuinely read as cinematic, provided they understand where automation ends and craft begins.
This guide walks through a complete AI video workflow for Instagram Reels and comparable vertical formats: choosing models, writing prompts that behave like direction, holding characters consistent across shots, framing for 9:16, shaping rhythm in the edit, layering sound, and finishing with color and grain. The point is not to press a button and hope. It is to build a pipeline you can run every week without starting from zero.
Why Cinematic Shorts Became the Default Format
Short vertical video stopped being a downgrade. Audiences now watch trailers, product films, fashion campaigns, and narrative fragments in the same feed, on the same screen, at the same length. That flattening means a nine-second clip competes directly against studio-produced content. If your video looks like a phone recording from a bad angle, it loses — not because the idea is weak, but because the production signal is weak.
The economics changed at the same time. Traditional cinematic production requires a crew, permits, gear, and post-production bandwidth. AI-assisted production compresses those costs into compute time. What it does not compress is decision-making. You still have to choose the shot, the lens, the light, the performance, and the cut. The difference is that every one of those decisions is now expressible as text and image input rather than a call sheet.
There is also a distribution argument. Vertical video is discovered through retention, and retention rewards density: something visually interesting every second, no dead frames, no slow ramp. Cinematic technique — contrast, motion, depth, deliberate framing — is exactly what keeps a thumb from moving. Short-form and cinematic are not opposites anymore; they are the same discipline applied at different scales.
What "Cinematic" Actually Means in a Short Clip
Most creators use "cinematic" to mean "looks expensive." That is the outcome, not the mechanism. In practice, cinematic quality comes from a small set of controllable variables:
- Depth separation. A subject that sits clearly apart from its background reads as intentional. Shallow depth of field, atmospheric haze, backlight, or foreground occlusion all create that separation.
- Motivated light. Light should appear to come from somewhere in the scene — a window, a neon sign, a practical lamp, a sunset. Unmotivated flat lighting is the single fastest way to make an AI clip look synthetic.
- Controlled motion. Camera movement should have a reason: a slow push to increase tension, a lateral track to reveal, a handheld drift to add intimacy. Random drifting cameras are the most common artifact in AI video.
- Restrained palette. Two or three dominant colors, plus skin tones kept honest. Rainbow grading reads amateur.
- Negative space and pacing. Cinematic frames are not always full. Empty space gives the eye somewhere to rest and gives captions room to breathe.
Write these criteria down and score every generated clip against them. A take that fails on depth separation and motivated light will not be rescued by a good edit, and regenerating it is almost always faster than trying to grade your way out.
Building Your AI Video Workflow Stack
A reliable pipeline separates four jobs: image generation, video generation, enhancement, and assembly. Mixing them inside one tool feels convenient but limits quality, because each stage has different strengths.
Image generation and reference frames
Starting from a still image instead of text alone gives you far more control over composition, wardrobe, and lighting. Image models such as Midjourney, Flux, Ideogram, or Stable Diffusion variants work well here. Generate your hero frame first, then treat it as the visual contract for every video model call in that scene. When a shot looks wrong, you can often trace it to a weak reference frame rather than a weak video model.
Video generation: text-to-video versus image-to-video
Text-to-video is fast for exploration and B-roll. Image-to-video is the workhorse for anything with a character or a specific composition. Tools in this space include Runway, Kling, Luma Dream Machine, Pika, Veo-class models, and Sora-class models, with new entrants appearing constantly. The useful mental model is not "which one is best" but "which one is best at this shot type."
Build a small personal benchmark before you commit. Take one reference image and one eight-second prompt, then run it through three or four models. Compare four things: how well the subject's face holds, whether hands and limbs behave, how stable the camera is, and whether the motion follows your direction or the model's default drift. Twenty minutes of testing saves weeks of frustration.
Enhancement and interpolation
Raw generation often lands at resolutions or frame rates that feel thin for vertical delivery. Upscaling and frame interpolation tools — Topaz Video AI, and the built-in upscalers inside many generation suites — can push a clip to 1080x1920 at 30 or 60 fps. Interpolation is powerful but not free: it can introduce warping on fast motion, so apply it selectively and always review frame by frame on shots with hands, hair, or quick turns.
Assembly
You need one editor you know deeply. DaVinci Resolve, Premiere Pro, Final Cut, or CapCut all work. Resolve is the strongest option if you care about grading and want a free professional path. The key is to stop treating assembly as an afterthought; the edit is where generated clips become a film.
Writing the Shot List: Prompts That Work Like Direction
A prompt is a brief, not a wish. The difference between a weak prompt and a strong one is specificity across six axes: subject, action, environment, lens, light, and motion.
Weak: A woman walks through a city at night, cinematic.
Strong: Medium close-up, 50mm equivalent, a woman in a charcoal wool coat walks toward camera along a wet Tokyo side street at night; neon signage reflects on asphalt; key light from a red storefront on her left cheek; slow handheld push-in; shallow focus, background bokeh; cool teal shadows with warm practical accents.
Notice that the strong version contains no emotional adjectives. It describes what a camera would see. That is the translation layer: think in shots, not in moods.
The six-part prompt template
- Shot type and framing — extreme wide, wide, medium, medium close-up, close-up, insert.
- Lens and depth — 24mm for environmental scale, 50mm for neutral perspective, 85mm for compression and flattery, macro for texture.
- Subject and wardrobe — one or two distinguishing details beat a paragraph of description.
- Action — one clear verb. Two actions in an eight-second clip usually produce mush.
- Environment and time of day — the strongest lever on mood, and the one models respect most.
- Light and motion — motivated source, direction, quality, plus camera movement and speed.
Handling common artifacts in the prompt
Some failures are predictable and can be pre-empted. "Slow" and "subtle" reduce warping and camera drift. "Static camera" eliminates the model's urge to orbit. "Face visible, looking at camera" improves facial stability compared to profiles and extreme angles. "Wide shot, silhouette" is a reliable workaround for complex crowd scenes where faces will inevitably melt.
Also keep a negative list in your own notes — not necessarily as a model parameter, but as a review checklist: extra fingers, duplicated limbs, text on signage, shifting clothing patterns, morphing backgrounds. If two takes in a row show the same flaw, change the prompt rather than rerolling.
Consistency: Keeping Characters and Worlds Stable Across Shots
Consistency is the hardest problem in AI video and the one that separates a watchable series from a collection of disconnected clips. There are three layers to solve: face, wardrobe, and world.
Face and identity
Character reference features — image prompts that carry identity, multi-image blending, or dedicated character-training options in tools like Kling, Runway, and others — let you anchor the same face across takes. The practical rule: build a reference sheet first. Generate eight to twelve images of your character from different angles, distances, and lighting setups. Pick the three strongest. Use only those as references for every subsequent shot, and never mix references from different generations, because micro-changes in the face compound.
Wardrobe and props
Describe wardrobe in exactly the same words every time. "Charcoal wool coat with a matte black leather belt" will hold. "Dark coat" will drift into a bomber jacket by shot three. Props work the same way — if the character carries a red umbrella in shot one, that phrase belongs in every prompt for the scene.
World and palette
Locations drift too. Fix a scene's look with a compact palette statement you reuse verbatim: for example, teal shadows, warm amber practicals, wet asphalt, 35mm film grain. Repeat it in every prompt for that location. This is effectively your scene's grade note, and it does more for continuity than any post-processing trick.
The continuity log
Keep a simple text file: shot number, prompt used, model, seed if available, reference images, and result rating. It sounds administrative, but it saves hours. When shot seven fails, you can rebuild the exact conditions of shot six in under a minute instead of guessing.
Vertical Framing and Composition
A 9:16 frame is not a cropped 16:9 frame. It is a portrait canvas with its own logic, and prompts generated for widescreen compositions frequently produce results that fall apart once verticalized.
Center-weight your subjects. A vertical frame has narrow horizontal tolerance. Off-center compositions work, but the subject should still sit within the central third. When prompting for image-to-video, generate the reference at 9:16 natively rather than cropping later.
Use verticality as a feature. Stairs, ladders, doorways, skyscrapers, falling rain, rising smoke, tunnels, and corridors all exploit the tall frame in ways a wide frame cannot. Lean into upward and downward camera moves; they read better vertically than lateral tracks.
Reserve the safe zones. Instagram's interface covers roughly the top 10–14 percent and bottom 20 percent of the frame. Keep faces out of the top strip and keep captions clear of the bottom UI. Generate with headroom and negative space, and plan your text placement before you shoot, not after.
Test the crop. Before committing, preview the clip inside the actual app at phone size. Details that read clearly on a monitor — small text, fine fabric patterns, distant faces — vanish on a five-inch screen. If a shot only works on a desktop, it does not work.
Editing Rhythm, Color, and the Finish
The edit is where a pile of generated clips becomes a film. Start with a music bed or a scratch track and cut to its rhythm rather than to your own sense of timing. Short-form viewers reward density: aim for a visual change every one to two seconds, where a "change" can be a cut, a camera move, a lighting shift, or a subject entrance.
Cut on motion. Cutting mid-action hides the seams of AI generation, because the eye is following movement rather than inspecting pixels. Cutting on stillness exposes artifacts.
Hold the money shot. Dense cutting earns you the right to hold one frame longer at the emotional peak. That contrast is what makes a short feel directed rather than assembled.
Grade for consistency, not for drama. Your first grading job is matching shots, not stylizing them. Balance exposure and white point across every clip before you touch a look. Then apply a restrained look: crushed but not clipped blacks, slight lift in shadows, skin tones protected, and one accent color.
Add grain and texture. Clean digital generation often feels plasticky. A light 35mm grain overlay, subtle chromatic aberration at the frame edges, and a touch of bloom on highlights go a long way. Keep it subtle — heavy grain on a vertical phone screen just looks like compression noise.
Sharpen last. Apply sharpening after scaling to final resolution, and keep it modest. AI upscalers amplify artifacts; over-sharpening makes fabric and hair crawl.
Sound, Voice, and Captions
Sound contributes more to perceived production value than most creators expect — and it is the layer AI helps with least automatically.
Design in three layers. A music bed for emotion, ambience for place (rain, traffic, room tone, wind), and spot effects for action (footsteps, cloth movement, a door, a lighter). Ambience alone makes a generated clip feel shot on location rather than rendered.
Voice and narration. Text-to-speech tools like ElevenLabs and comparable engines produce strong narration if you direct them: specify pace, warmth, and whether the read should be conversational or documentary. Short-form narration should be slower than you think, with deliberate pauses between ideas.
Captions are not optional. A large share of viewing happens muted. Burn in captions with strong contrast, one or two lines maximum, positioned above the bottom UI. Avoid animated word-by-word styles if your content is narrative; they fight the cinematography. Use them for talking-head or explainer formats instead.
Mix to a target. Aim for dialogue or narration around -6 dB peak with music sitting 12–15 dB below it, and check the final mix on a phone speaker. If it only sounds good on headphones, it is not finished.
Testing, Iteration, and Common Mistakes
The final discipline is treating each post as a test. Publish consistently, then examine retention curves rather than like counts. A clip that loses viewers in the first second usually has a weak opening frame; one that drops at four seconds often has a slow middle; one that holds to the end but does not get rewatched has a weak payoff.
Common mistakes worth avoiding:
- Generating without a reference frame. Text-only generation for character shots wastes time and produces drift.
- Too many actions per clip. One clear action per take, then cut.
- Ignoring the first frame. It is the thumbnail, the hook, and the composition all at once. Design it deliberately.
- Over-relying on one model. Different models excel at different shot types; a two-model rotation usually beats loyalty.
- Grading before matching. Fix consistency first, style second.
- Skipping the phone test. Everything looks better on a large monitor.
- Chasing perfection on a single shot. Iterate on the sequence; a mediocre shot surrounded by strong ones disappears, but a stalled pipeline kills momentum.
Build a small asset library as you go — reusable character references, palette statements, grain overlays, ambience beds, caption templates. The library, not the model, is what makes your tenth video faster and better than your first.
FAQ
How long should a cinematic AI short be?
Seven to fifteen seconds for a single scene, twenty to forty seconds for a mini-narrative of three or four shots. Length should follow the number of ideas, not a target runtime.
Do I need image-to-video, or is text-to-video enough?
Text-to-video is fine for establishing shots, landscapes, and abstract B-roll. Any shot with a recurring character or precise composition should start from a reference image.
How do I stop faces from changing between shots?
Lock three things: a small approved reference set used for every shot, identical wardrobe phrasing, and the same scene palette line. Regenerate references rather than reusing degraded ones.
What resolution and frame rate should I export?
1080x1920 is the safe standard. Export at 30 fps for most content, 60 fps only if you have genuine fast motion and interpolation artifacts are under control.
Is interpolation worth it?
On slow, controlled shots, yes. On fast motion, hands, or hair, it often introduces warping that is harder to fix than the original judder.
How many takes should I generate per shot?
Budget three to five. If none work, the prompt is wrong, not the model. Change one variable at a time — usually motion or framing — and rerun.
Can I build a series reliably?
Yes, if you treat it as a production system: fixed references, fixed palette, a continuity log, and a consistent export pipeline. Consistency across episodes is what converts casual viewers into followers.
