
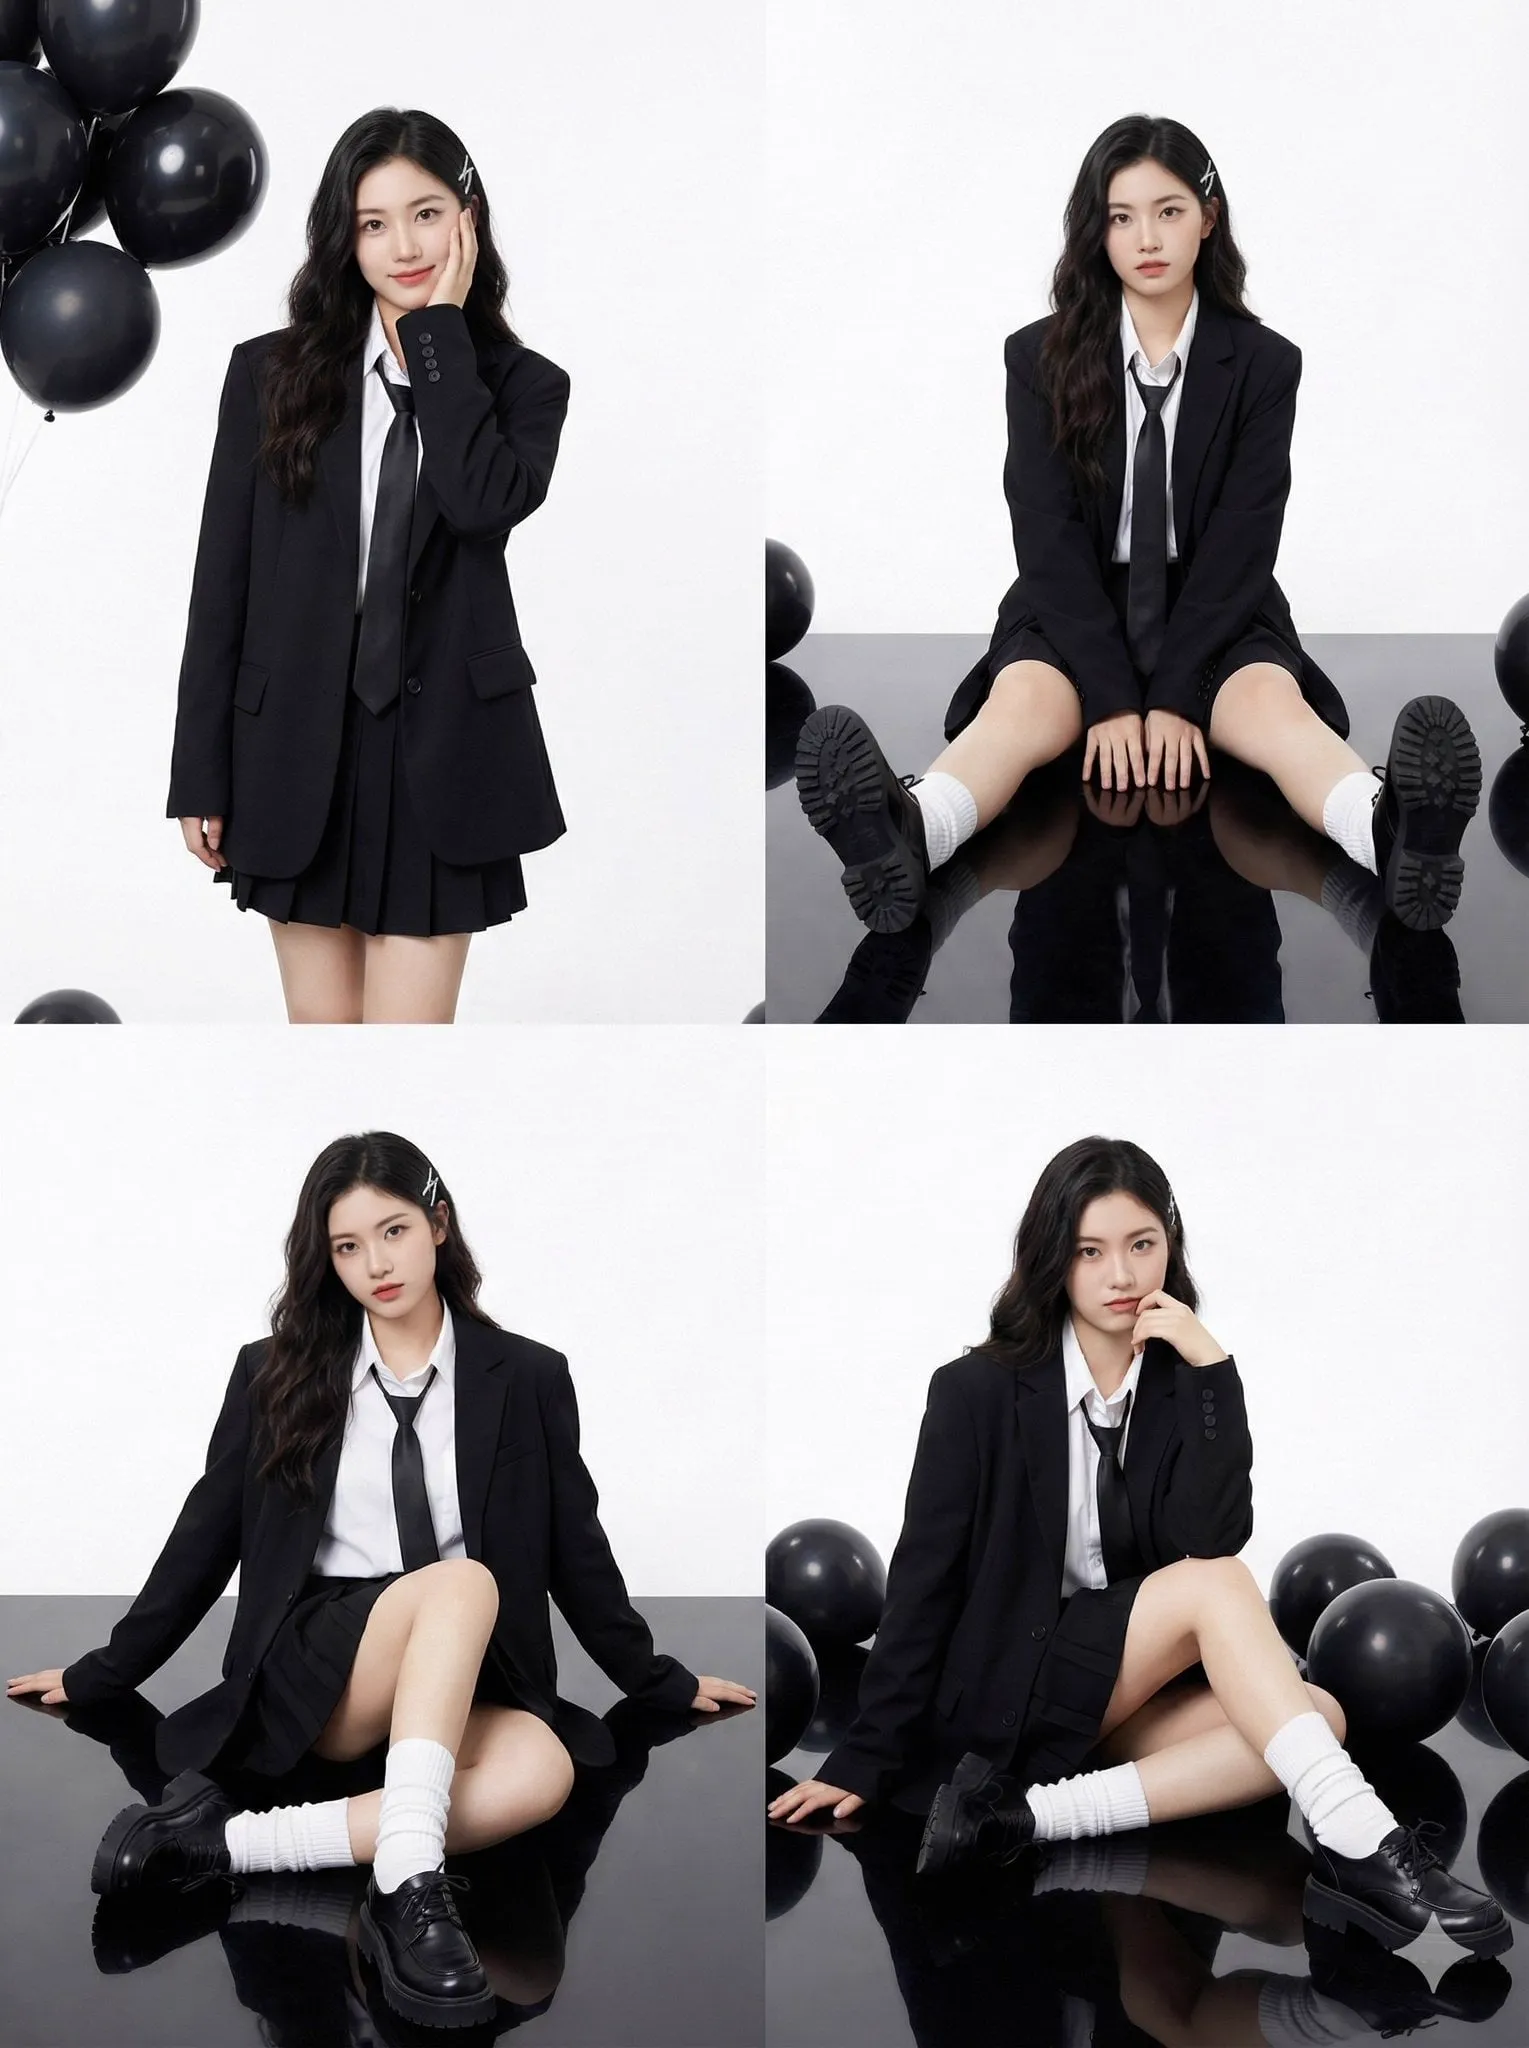
Why Character Consistency Is the Hardest Problem in AI Video
Every shot in an AI video is generated independently. The model starts from fresh noise, and a face is one of the most information-dense objects in the frame: shift the eye spacing by a few pixels or soften the jaw line and the audience registers a different person, even if they cannot explain why. A slightly wrong background reads as style. A slightly wrong face reads as a mistake.
That turns consistency into a production cost rather than a cosmetic detail. Without a reusable identity, every new angle means another round of generation, another batch of rejects, and a timeline that grows faster than the story. For episodic series, recurring ad characters, or a host who appears in dozens of clips, drift forces reshooting, heavy editing, or a quiet recast that viewers notice immediately.
The creators who avoid this treat a character the way a studio treats a cast member: a locked reference package, a documented prompt pattern, and a repeatable merge process. The rest of this guide covers how that system works and how to build it from scratch, whether you are producing a single short film or a long-running series.
How Multi-Image Referencing Actually Works
Multi-image referencing — often described as multi-image merging — conditions a single generation on several images at once instead of one portrait. You supply a small set that describes the character from several angles, expressions, and lighting conditions, and the model folds them into one identity signal that steers the rest of the render.
The advantage is triangulation. A single photo is ambiguous about depth: the model has to guess the side profile, the back of the head, the chin seen from below. Five well-chosen photos remove most of that guesswork, so the resulting face stays stable when the camera moves, the character turns, or the scene lighting changes dramatically.
What the Model Actually Reads
Models do not recognize a person the way a human does. Practically, each reference image contributes several distinct kinds of signal:
- Geometry: face proportions, eye spacing, nose bridge, jaw shape, forehead height.
- Texture: skin tone, freckles, beard density, hair strand pattern.
- Silhouette: hairstyle volume, shoulder line, body proportions.
- Palette: wardrobe colors, accessory shapes, distinctive marks such as scars or tattoos.
- Quality: sharpness, grain, and compression, which quietly influence the render style of the output.
When your references contradict each other — a soft studio portrait mixed with a harsh phone flash shot — the model averages the contradiction, and the result looks like neither input.
From a Reference Set to a Reusable Identity Vector
Most modern pipelines extract an identity representation rather than pasting pixels. Each reference is encoded by a vision encoder, the embeddings are pooled into one vector, and that vector is injected during selected denoising steps. Three approaches dominate in practice:
- Reference-conditioned generation. Fast, flexible, no training required. Works well when you need dozens of shots and the character keeps the same costume and hairstyle.
- Lightweight fine-tuning. You train a small adapter on a curated reference set. Slower to set up, stronger lock, best for long-running series where the same face appears in every episode.
- Prompt-only description. Cheapest to start and the weakest at holding a face. Useful for background characters, distant crowds, or stylized animation where exact likeness matters less.
The decision criteria are simple: how many shots, how much variation, and how much time you can spend per character. Two to five shots call for a reference-conditioned workflow. Twenty-plus shots, or a recurring series, justify a fine-tuned adapter.
Naming, Storage, and Versioning
Treat references like source code. One folder per character, subfolders for each approved version, and filenames that state angle and lighting (ava_front_neutral.jpg, ava_profile_soft.jpg, ava_three_quarter_warm.jpg). If you work with a team, keep a small table — character ID, asset paths, which reference set produced which approved look, and a note about what changed — in a relational store such as PostgreSQL or a managed option like Supabase. The point is not the tool. The point is that three months later you can reproduce the exact face you shipped, and explain why it looked that way.
Building a Character Bible Before You Generate
A character bible is the document that ends arguments. It holds the reference sheet, the locked prompt pattern, wardrobe rules, and the list of shots already approved. Write it once and every future generation starts from a known state instead of a guess. It also makes handoffs painless: a collaborator can pick up the project without reverse-engineering your prompt history.
The Five-Shot Reference Sheet
Start with five images:
- Front, neutral expression, even light, plain background.
- Three-quarter view, the most common cinematic angle and the one that drifts most often.
- Profile, to pin the nose, chin, and hair silhouette.
- Emotional close-up — a smile or a frown — to anchor expression range.
- Full body, to lock proportions and default wardrobe.
Generate or shoot them with the same lighting, similar crop, and no hair occluding the face. Consistency in your inputs is what allows consistency in your outputs. If a reference looks slightly off next to the others, discard it; a mediocre reference does more damage than a missing one.
A Prompt Template That Locks Identity
Write the prompt once, as a template with slots, and reuse it for every shot:
[identity block] + [action] + [emotion] + [camera] + [lighting] + [style] + [negative]
A filled example:
same woman, mid-30s, oval face, dark brown wavy shoulder-length hair, hazel eyes,
small scar above left eyebrow | walking through a rainy market street | tired but calm |
medium tracking shot, eye level | overcast daylight, soft shadows | cinematic realism,
shallow depth of field | no face morphing, no identity change, no extra people
Keep the identity block frozen word for word. Change one variable at a time. When something works, save the exact string rather than a paraphrase of it, because paraphrases quietly change what the model sees.
A Multi-Image Merging Workflow, Step by Step
Step 1: Clean and Normalize the Inputs
Crop every reference to a similar head size, remove distracting backgrounds where possible, and upscale anything below the resolution floor of your model. Mismatched crops are one of the most common causes of a face that looks almost right and never quite lands.
Step 2: Weight Your References
Not all references deserve equal influence. Give the front neutral shot the highest weight, the three-quarter shot slightly less, and any dramatic expression the least. If your tool exposes only a single reference strength control, test three values — low, medium, high — on the same prompt and compare the outputs side by side.
Step 3: Merge Pose With Identity
Generate the pose first with a body or motion reference that carries no face, then merge the identity reference into that pose. Mixing both in a single pass often produces a hybrid face that belongs to neither input, which is hard to fix in post.
Step 4: Separate Lighting From Identity
When a scene needs dramatic lighting, lock identity first in flat light, then restyle. Asking one pass to invent a character and light them cinematically at the same time splits the model's attention and softens the likeness. Two calm steps beat one ambitious step almost every time.
Step 5: Verify With a Test Grid
Before committing to a full sequence, render a grid: front, three-quarter, profile, wide, and close-up from the target script. If the face survives all five, the reference set is ready. If it drifts in profile, your profile reference is too weak or too stylized; regenerate it and repeat the test.
Pose, Emotion, Lighting, and Wardrobe Continuity
Pose and Emotion Control
Pose is easier than identity. Use a motion reference, a skeleton overlay, or an image-to-video pass where the first frame is already approved. Emotion is a controlled offset: define two or three states — neutral, engaged, stressed — and describe them consistently in every prompt instead of inventing new adjectives per shot.
The riskiest moment is always a strong expression. A wide open-mouth laugh changes a face more than any camera move. Approve a laughing reference early, or keep the strongest expressions for wide shots where the face occupies fewer pixels and small deviations are invisible.
Lighting and Wardrobe
Build a small lighting vocabulary and reuse it: soft daylight, overcast, golden hour, practical interior, low-key night. Consistency in the vocabulary produces consistency in the grade, which in turn makes minor identity drift far less visible to an audience.
Wardrobe should change on purpose. If the character changes clothes, change only the garment description and leave the identity block untouched. Never let a costume change alter hair, face, or skin tone in the prompt — that is exactly how a cast member quietly becomes a different person halfway through a scene.
Switching Between Video Models Without Breaking the Cast
Different models handle identity differently. Some favor short clips with strong prompt adherence; others allow longer takes but drift more across frames. Rather than committing to one tool forever, build a model-agnostic character specification and then render a single test shot per model: same prompt, same references, same duration, same seed when available.
Keep a golden frame for each model — the clip where the likeness is strongest — and use it as your comparison baseline. When you switch tools for speed, cost, or a specific capability such as longer clips or better camera control, you only need to verify that the new output matches the golden frame, not that it matches your memory of the character. Cross-tool consistency is a checklist, not a talent.
One more habit helps: note which model handled which shot type best. Many teams end up using one model for dialogue close-ups and another for wide environmental shots, then cutting them together in the edit. That is fine as long as the identity package and the grading match.
Composition and Story Continuity
Coverage makes drift obvious. Generate your wide master shot, then a medium, then a close-up, and check the identity at each distance. Faces survive better in close-ups; bodies and wardrobe survive better in wide shots. Plan a sequence so the most expression-heavy beats land in coverage where identity is easiest to hold, and save the most forgiving angles for the shots you generate late in the day.
Cut on motion, match eyelines, and keep the direction of travel consistent across shots. Viewers forgive a great deal when the scene logic is coherent, and they spot identity problems fastest when the edit is already disorienting. Continuity of story and continuity of face reinforce each other.
Common Mistakes and How to Fix Them
- Too many references. Cut down to five strong images. More inputs rarely mean more consistency; contradictory inputs get averaged into a stranger.
- Contradictory lighting. Match references to one lighting setup, lock identity, then restyle for the scene.
- Rewriting the identity block. Freeze it and edit only action, emotion, camera, lighting, and negative slots.
- Judging by a single frame. Watch motion. Drift is a temporal artifact, and a still can look perfect while the clip flickers.
- Mixing stylized art with photo references. Keep a realistic set and a stylized set separate, then choose per project instead of merging them.
- No versioning. Name files clearly and log which reference set produced which approved shot. Future you will be grateful.
- Chasing perfection on unimportant shots. For background extras and distant figures, accept small variation and spend your effort where the audience is actually looking.
An End-to-End Workflow You Can Repeat
- Write the character bible: five references, frozen identity block, wardrobe rules, lighting vocabulary.
- Render a test grid in flat lighting before any production work begins.
- Approve a golden frame and store it alongside the reference version number.
- Generate each shot changing a single variable per pass, keeping the rest identical.
- Merge pose and identity in separate steps for difficult angles and dramatic expressions.
- Restyle lighting and color only after the likeness is confirmed.
- Build a contact sheet of one frame from every shot and review the faces side by side.
- Regenerate only the shots that fail comparison rather than the entire sequence.
- Archive the approved references, prompts, and seeds with the final edit so the character can return in the next project.
FAQ
How many reference images do I actually need? Four to six is the practical range: front, three-quarter, profile, one expression, one full body. Additional images only help when they add genuinely new angles or lighting conditions.
Can a single reference image be enough? Sometimes, for short clips and forgiving camera angles. It breaks down as soon as the head turns significantly or the lighting changes drastically.
Why does the face shift between shots that use the same prompt? Because generation is stochastic and each shot starts from different noise. Lock the seed when you need near-identical results, and accept small variation when you need natural motion.
Should I train a dedicated character model? Only for long-running series with dozens of shots or a recurring brand character. For one-off projects, reference conditioning plus a strict prompt template is faster and nearly as stable.
How do I keep a character consistent in a different art style? Maintain two reference sets — one realistic, one stylized — and never mix them in a single generation. Style transfer on top of a locked identity works far better than asking one pass to invent both.
What is the fastest way to check consistency? Build a contact sheet of one frame per shot and view them together. Drift is much easier to spot in a grid than in a running timeline.
How do I handle multiple characters in one scene? Give each one a separate reference package and describe them in clearly separated identity blocks, ideally with distinct silhouettes and wardrobe palettes. If the model blends them, generate each character separately and composite the shots in the edit.
