
Why character consistency is the hardest part of image-to-video
Ask anyone who has shipped a multi-shot AI video and they will tell you the same thing: generating a beautiful single clip is easy, but keeping the same person recognizable across eight clips is where projects fall apart. Image-to-video models are not designed to remember. Each render is a fresh interpretation of your reference, weighted by motion, lighting, and camera language you introduce in the prompt.
The result is drift, and drift has four recognizable flavors:
- Facial drift — cheekbones soften, eyes widen, jawline shifts, and after a few shots your hero looks like a cousin rather than the same person.
- Wardrobe drift — a jacket changes cut, a scarf changes color, a logo quietly vanishes.
- Style drift — a cinematic grade slides into flat daylight, skin texture becomes plastic, or grain appears in one shot and disappears in the next.
- Identity bleed — in two-character scenes, features merge, and both characters end up sharing one face.
None of these are model bugs you can prompt away with a single magic sentence. They are structural problems, and they are solved structurally: with a reference system, disciplined keyframes, motion prompts that respect anatomy, and a review loop that catches failures before you render a final sequence.
This guide walks through a repeatable production workflow. It assumes you are working with any modern image-to-video model and any editor or node-based pipeline. The principles transfer everywhere; the tool names change, the discipline does not.
The four-layer consistency stack
Think of consistency as a stack of four protective layers, ordered from most permanent to most temporary. Every layer you skip increases the odds that the shot above it fails.
Layer 1: the character bible
This is a text document, not an image. It records the fixed facts: age range, face shape, eye color, hair length and texture, skin tone, distinguishing marks, height and build, default wardrobe, accessories, and voice or speech cadence if the character speaks. Add two or three sentences about posture and personality, because body language influences how models interpret motion prompts.
Keep the bible short enough to paste into prompts — ten to fifteen lines is ideal. If it runs two pages, you will never use it consistently, and unusable documentation is worse than none.
Layer 2: the reference sheet
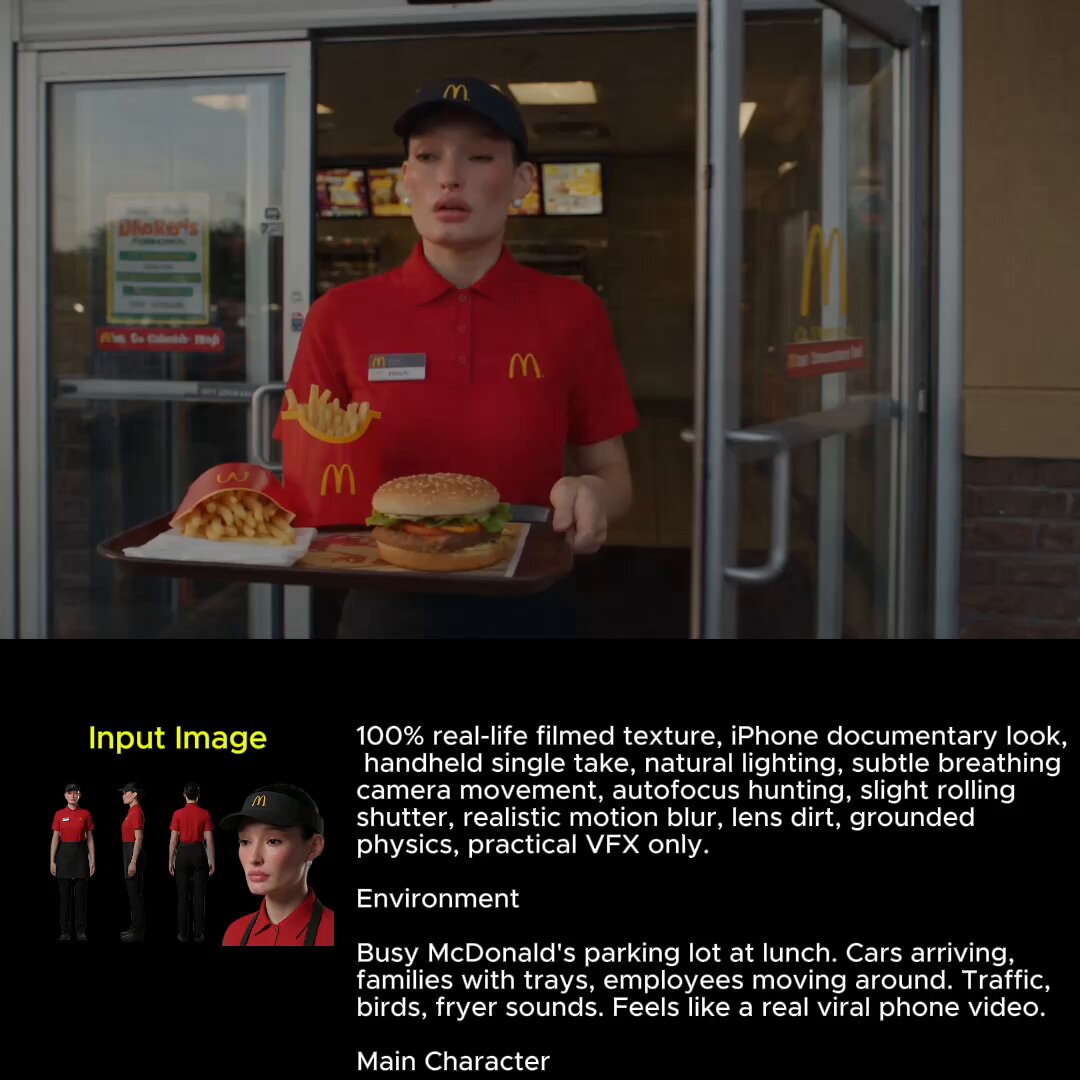
A single portrait is not enough. You need a small set of images covering angles, expressions, and lighting conditions. We will build this in detail below.
Layer 3: keyframes and motion control
Instead of asking a model to invent a shot from one still, define the first frame, and where possible the last frame, of every clip. Keyframes anchor identity at both ends and constrain what the model can invent in the middle.
Layer 4: locked style tokens
Style is a consistency variable too. Decide on a fixed look — lens, grade, contrast, film grain, color temperature — and describe it identically in every prompt. Vague words like "cinematic" produce a different result every time. Specific words like "35mm lens, soft contrast, cool shadows, fine grain" produce repeatable results.
When something drifts, diagnose top-down. If the bible is vague, no amount of reference images will save the shot.
Building a character reference sheet that survives rendering
Most consistency failures trace back to weak reference material. A selfie with harsh overhead light and a smiling, head-tilted pose is a terrible anchor: the model has to undo the expression and the angle before it can animate anything.
Aim for six to ten images with these properties:
| Image | Purpose | Notes |
|---|---|---|
| Neutral front portrait | Primary identity anchor | Relaxed face, even lighting, eyes to camera |
| Three-quarter view | Depth and cheekbone structure | Same wardrobe as portrait |
| Profile view | Nose, jaw, and hair silhouette | Critical for turning shots |
| Full body, standing | Proportions and wardrobe head-to-toe | Neutral stance, arms slightly away from body |
| Expression set | Emotional range | Happy, serious, surprised, tired |
| Lighting variants | Environment adaptability | Warm indoor, cool daylight, low key |
Practical rules that matter more than people expect:
- Keep resolution moderate. Extremely high-resolution references often get downscaled anyway, and very large files slow iteration. Consistency comes from clarity, not megapixels.
- Match aspect ratio across references. Mixed ratios nudge the model toward reframing, which changes apparent face geometry.
- Avoid heavy beauty filters. Smooth skin destroys the texture cues the model uses to lock identity.
- Keep the background simple. Busy backgrounds bleed into renders as ghost textures or unwanted props.
- Name files systematically.
hero_ref_front_neutral_v3.pngbeatsIMG_4471.pngwhen you are sixteen shots deep at midnight. - Version everything. When you change the reference sheet, you have effectively created a new character. Label it and re-render the shots that came before.
Step-by-step: from one portrait to a consistent five-shot scene
Here is the workflow in the order it should actually happen.
Step 1: Lock the character sheet before generating any video
Generate or select the reference set first, then stop. Do not start animating while you are still unsure which portrait is "the" face. Every clip you render against a provisional reference is a clip you will redo.
Step 2: Storyboard in keyframes, not in words
Write the scene as five beats, then generate a still image for the first frame of each beat. If you can, generate the last frame too. A five-shot scene with two keyframes per shot gives you ten anchors and dramatically reduces drift.
Review the stills as a contact sheet. Do the characters look like the same people at thumbnail size? If not, fix it now — that check costs seconds, while a re-render costs an evening.
Step 3: Choose the mode that matches the shot
Different shot types need different generation strategies. A slow push-in on a talking character is a very different problem from a running chase. Match the tool to the motion, not to habit.
Step 4: Write a motion prompt that respects the anchor
Describe movement, camera behavior, and lighting continuity — not appearance. The reference image is already carrying the appearance. Repeating "a woman with brown hair and green eyes" in every prompt invites the model to reinterpret those features.
Step 5: Render short, review hard, then extend
Generate clips of three to five seconds. Review them in sequence at full speed and frame by frame. Only after a shot passes review should you extend it or move on.
Step 6: Run a quality-control pass over the whole sequence
Before any final render, check the assembled timeline for:
- Face shape consistent at frame 1, midpoint, and final frame of every clip
- Wardrobe details unchanged, including accessories and closures
- Consistent color temperature and contrast between adjacent shots
- Hair length, part, and silhouette stable
- Hands and fingers plausible during motion
- No identity bleed in two-character frames
- Screen direction and eyelines that hold across cuts
Prompting for identity retention without killing motion
Prompts fail in two directions. Too vague and the model invents. Too descriptive and the character freezes, because every token spent restating appearance is a token not spent on movement.
Use a three-part structure:
[Action and performance] + [Camera behavior] + [Lighting and continuity]
A workable example:
She turns from the window toward the table, shoulders relaxing, one hand
settling on the chair back. Slow handheld push-in, eye level, slight
parallax. Warm afternoon light from camera left, soft shadows, fine film
grain, consistent with previous shot.
Notice what is absent: hair color, eye color, clothing description. All of that lives in the reference. What remains is instruction the model actually needs.
Three habits worth adopting:
- Keep a prompt library. Save prompts that produced stable identity, alongside the seed and reference version, so you can reuse a proven formula.
- Use negative constraints sparingly but specifically. Terms like "face morphing, identity change, warping features" help more than long generic ban lists.
- Change one variable at a time. If a shot fails, adjust only the prompt, the model, or the keyframe — never all three at once, or you will never learn what worked.
Keyframe and shot-planning rules for continuity
Consistency is partly craft. Traditional continuity rules prevent the audience from noticing small imperfections.
- Cut on motion. A cut during a turn or a hand gesture hides micro-drift in the face.
- Avoid slow push-ins on faces unless the face is your strongest anchor. Tightening the frame magnifies every imperfection.
- Hold screen direction. If your character moves left-to-right in one shot, do not flip direction in the next without a bridging shot.
- Keep camera height consistent within a scene. Eye-level in one shot and chest-level in the next reads as a different character scale.
- Use insert shots as breathing room. A cutaway to hands, a prop, or a wide environment shot resets the audience's attention and gives you a place to hide weaker renders.
- Limit exposure of the hardest angles. Extreme close-ups and full profiles are the two most failure-prone framings. Use them deliberately, not habitually.
If a scene simply cannot hold consistency at a given framing, restructure the shot. A slight reframe costs nothing; a redone scene costs a day.
Choosing the right tool for the job
There is no single best approach. There are approaches that fit specific constraints.
| Approach | Best for | Watch out for |
|---|---|---|
| Multi-image reference fusion | New characters with no training required | Weaker identity lock than trained models |
| Identity-adapter pipelines | Face-focused shots and portraits | Can over-copy reference lighting |
| Small trained character models | Long-running series, high shot counts | Setup time and dataset hygiene |
| Pose and depth conditioning | Precise body movement and staging | Adds pipeline complexity |
| First-and-last keyframe modes | Controlled, predictable camera moves | Less improvisation, more planning |
| Talking-head and lip-sync tools | Dialogue-driven scenes | Limited body motion range |
Decision criteria, in the order that should drive your choice:
- Shot count. Two shots? Use references. Forty shots across a series? Invest in training.
- Motion complexity. Subtle performance favors reference-based workflows; complex action favors pose conditioning.
- Deadline. Training takes time. If you need shots today, reference fusion plus disciplined keyframes wins.
- Reusability. If the character returns in future projects, an investment in a trained model pays off repeatedly.
A hybrid stack is normal in professional pipelines: reference fusion for establishing shots, a trained identity for close-ups, and pose conditioning for action beats.
Fixing the most common consistency failures
The face melts mid-clip. Usually caused by excessive motion instructions or a clip that is too long. Shorten to three seconds, simplify the action, and add a last-frame keyframe.
Wardrobe changes between shots. Add the garment to your style tokens and describe it once per prompt in generic terms: "dark wool coat, collar up." Do not describe texture, buttons, or stitching — the reference handles detail.
Hair color shifts warmer or cooler. This is a lighting problem, not an identity problem. Lock your color temperature language and check adjacent shots for a consistent grade.
Background props appear that you never requested. Crop the reference tighter or mask the background before animating.
Style shifts halfway through a clip. Motion prompts are overloading the model. Remove abstract style adjectives and keep the look description in a single consistent phrase.
Two characters swap features. Generate them separately whenever possible, or use regional masking so each character is conditioned by its own reference.
Hands and fingers deform during gesture. Reduce gesture complexity, frame the hands lower, or cut before the gesture completes.
Most of these failures are cheaper to prevent than to repair. A two-minute review pass at the contact-sheet stage catches the majority of them.
Scaling consistency across episodes
Once your character works in one scene, the real challenge begins: keeping them consistent across a series, or across a client campaign that runs for months.
Build a lightweight asset system. Each character gets a folder containing the bible, the current reference set with version numbers, four or five approved prompt templates, and a log of seeds that produced stable results. Store the pipeline settings alongside them; model versions change, and reproducing an old shot later may require a pinned configuration.
Adopt a rule: any change to the reference set triggers a re-render of previously approved shots that will appear adjacent to new ones. This sounds expensive, but it prevents the worst-case scenario — a series where episodes visibly drift from one another and the audience loses the thread of who they are watching.
Finally, keep a small "known good" test scene. Before starting a long render session, generate that scene and compare it against your approved version. If it no longer matches, something in your pipeline changed, and you have found out in two minutes rather than two days.
FAQ
How many reference images do I actually need?
Six is a practical minimum: front, three-quarter, profile, full body, plus two expression or lighting variants. Below five, models start guessing.
Should I train a custom character model?
Only if the character will appear in many shots across multiple projects. For one-off scenes, a strong reference sheet with disciplined keyframes is faster and usually good enough.
Why does my character look right in stills but wrong in video?
Because video adds motion weight. The model redistributes attention from identity to movement. Shorter clips, simpler actions, and last-frame keyframes recover most of the lost fidelity.
Do negative prompts help with identity?
Yes, if they are specific. "Face morphing, feature warping, identity change" helps. Long generic negative lists mostly waste prompt space.
How long should each clip be?
Three to five seconds. Drift compounds over time, so several short clips with clean keyframes almost always beat one long clip.
Can two characters share a scene and stay distinct?
Yes, but plan for it. Generate each separately where possible, use masking for conditioning, and keep them apart in the frame so features cannot blend at the seams.
What is the single highest-impact habit?
Locking the reference sheet before animating anything. Nearly every painful re-render traces back to starting too early with a provisional face.
Character consistency is not a feature you switch on. It is a production discipline: define the character, anchor them in a controlled reference set, constrain every clip with keyframes, prompt for motion rather than appearance, and review ruthlessly before you commit to a final render. Do that, and the audience stops noticing the technique and starts following the story — which is the entire point.
