
Why custom video models change the creative workflow
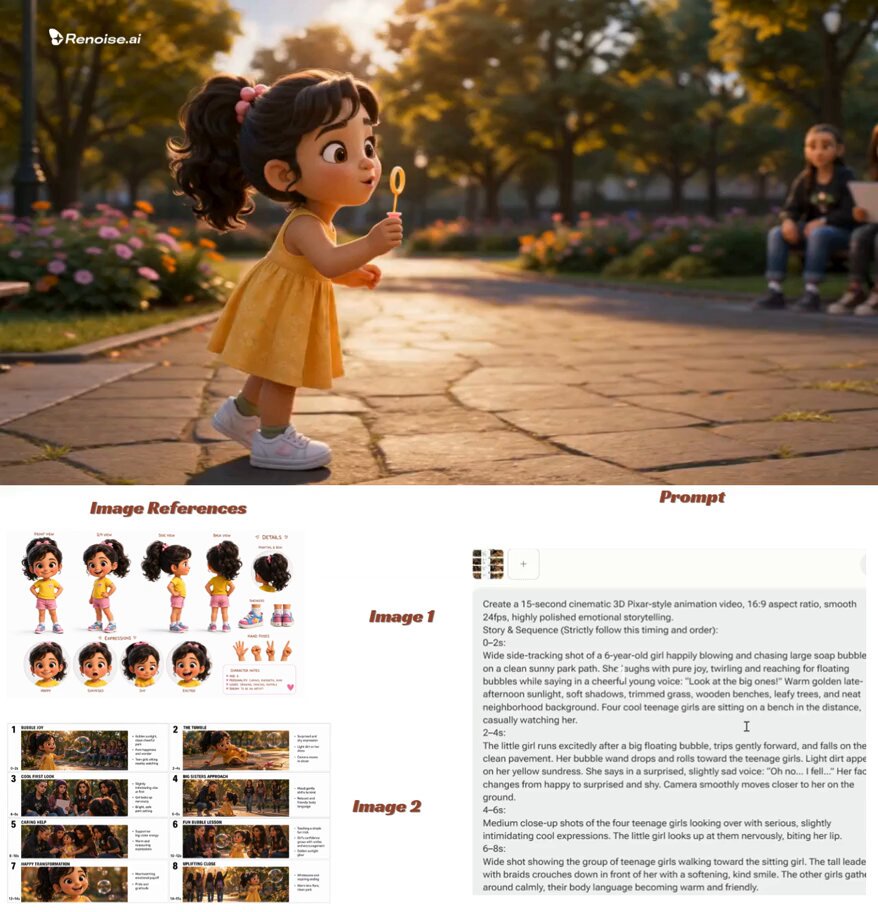
Generic video generators are excellent at producing plausible motion. They are much weaker at producing your motion. If you need a specific lighting signature, a recurring character, a branded camera language, or a house style that survives across dozens of shots, prompting alone will keep drifting on you. Every render becomes a negotiation, and consistency becomes a full-time job.
Training your own model — or more realistically, training a compact adapter on top of an existing base model — solves that drift problem at the source. Instead of describing your look in a prompt and hoping the model interprets it the same way twice, you bake the look into weights. The prompt then only has to describe what happens in the shot, not how the shot looks.
This guide walks through the full workflow: deciding what kind of tuning you actually need, building a dataset that will not poison your results, running a training loop without wasting days of compute, evaluating output with something more rigorous than vibes, and turning a successful experiment into a repeatable production pipeline.
It is written for working creators and small teams — editors, motion designers, indie studios, and solo directors — who want control over their visual signature without standing up a research lab.
What "training your own video model" actually means
The phrase covers at least four very different technical operations, and choosing the wrong one is the single most common reason people waste time and money.
Full fine-tuning
Full fine-tuning updates most or all of a base model's weights on your data. It requires large, well-curated datasets and serious hardware — typically multi-GPU nodes with high memory bandwidth. For most creators this is out of reach, and it is rarely necessary. You would only go here if you are building a foundation model or need a dramatic domain shift that adapters cannot express.
Adapter and LoRA-style tuning
Low-rank adapters insert small trainable matrices into an existing model and leave the base weights frozen. The resulting file is often tens to a few hundred megabytes, trains on a single consumer or prosumer GPU, and can be swapped in and out at inference time. This is the sweet spot for style transfer, character identity, camera language, and product look. If you are reading this to get practical results, start here.
Subject and identity tuning
Identity tuning is a specialized form of adapter training aimed at making one specific subject — a person, a mascot, a car, a piece of packaging — render recognizably across many angles, expressions, and lighting conditions. It is the hardest of the accessible techniques because the model must learn a concept rather than a texture.
Conditioning without training
Before committing to any training run, ask whether conditioning would suffice. Reference-image conditioning, depth or pose conditioning, and structured control inputs can lock down composition and framing without a single gradient step. Training is the tool for persistent style and identity; conditioning is the tool for per-shot control. Most production pipelines need both.
What you need before you start
At minimum: a base model you are legally allowed to adapt, a dataset of 30–200 clean clips for style work, a GPU with enough VRAM to hold the model plus activations, a training framework that supports video (not just image) latents, and a written definition of success. That last item is the one people skip, and it is the one that determines whether the run was worth it.
Step 1: Define the look, then collect the dataset
Write a one-paragraph style brief before you touch a single clip. Include palette, contrast curve, grain or cleanliness, lens character, camera movement vocabulary, pacing, and subject matter. A useful test: could a cinematographer read this brief and shoot something that matches your existing footage? If not, it is too vague to guide dataset selection.
Sourcing and licensing footage
Your dataset determines your model's ceiling. Three sources work well:
- Your own archive. Best case, because licensing is unambiguous and the look is authentically yours. Even a few hundred seconds of strong footage can train a useful style adapter.
- Commissioned or licensed shoot footage. Useful when you need controlled lighting variations the archive lacks. Get explicit permission for model training in the contract — "usage rights" is not the same thing.
- Synthetic references. Generations from a base model, filtered aggressively for quality, can bootstrap a style. This works surprisingly well for texture and lighting, less well for identity.
Avoid mixing wildly different sources in one dataset. A style adapter trained on ten visual languages learns an average of them, which is another way of saying it learns nothing.
Annotation and captioning
Captions teach the model which attributes vary and which stay constant. For style work, keep captions short and consistent: describe action and subject, omit the aesthetic (the aesthetic is what you are training). For identity work, invert the logic — describe everything except the subject, so the subject token absorbs the identity.
A practical pattern:
- Write a caption template with fixed slots: subject, action, camera, environment, lighting.
- Fill the template for every clip, even if that means a tedious afternoon.
- Deliberately vary one slot at a time across the dataset so the model learns disentanglement.
- Add a unique trigger token for style or identity, and keep it out of every other caption.
Poorly captioned data is the top cause of an adapter that works in testing and collapses the moment you change the prompt.
Step 2: Prepare and clean clips
Video preprocessing is heavier than image preprocessing and it is where most of your wall-clock time will go. Do it properly once.
Resolution, length, and aspect ratio decisions
Match your training resolution to the model's native operating resolution — do not train at a higher resolution than you will render at, and do not upscale low-quality source to fake it. For clip length, 2–5 seconds is usually the right window for temporal consistency training; longer clips dilute gradient signal per frame and blow up memory.
Handle aspect ratio deliberately. If your production target is vertical, train vertical. Cropping horizontal footage into vertical introduces framing bias that will haunt every generation.
Handling flicker, compression, and duplicates
Run every clip through a quality filter:
- Compression artifacts. Reject anything with heavy blocking or banding; the model will learn to reproduce them.
- Flicker and exposure pumping. Auto-exposure hunting in source footage trains instability into your model.
- Near-duplicates. Consecutive frames from the same shot stack the dataset toward one composition. Sample every Nth frame or keep only short representative slices.
- Dead footage. Scenes with almost no motion teach the model that your style means stillness.
A reasonable cleaning pass removes 30–50% of a naive dataset. That is normal and it improves results.
Step 3: Choose a training approach that fits your hardware
Adapter training for style
Style adapters train fast: a few hundred to a couple of thousand steps on a dataset of 40–120 short clips is often enough. Rank and alpha control capacity; higher rank captures more detail but overfits faster. Start conservative, evaluate, and only increase capacity if the model is clearly underfitting.
Identity tuning
Identity tuning needs more variety per subject: different angles, distances, expressions, and lighting, but a narrow subject. Twenty to forty well-chosen clips frequently beat two hundred redundant ones. Watch for identity bleed — the subject's clothing or background leaking into unrelated generations is a sign your captions are not describing enough variation.
Motion modules and temporal consistency
If your problem is not "wrong look" but "right look, wrong motion," you are dealing with temporal consistency rather than aesthetics. Motion modules or temporal layers trained on movement-rich clips address jitter, morphing, and frame-to-frame identity drift. Train these separately from style; mixing both objectives in one run usually produces a model that is mediocre at both.
Step 4: Run the training loop without burning time
Hyperparameters that matter most
- Learning rate. Too high and you get burned colors and destroyed structure; too low and you spend four times as long for the same result. Change one order of magnitude at a time.
- Batch size and gradient accumulation. Pick the largest batch that fits, then use accumulation to reach an effective batch size that stabilizes gradients.
- Steps vs epochs. For small datasets, think in steps and save checkpoints frequently; "one epoch" on a tiny dataset is a meaningless unit.
- Noise schedule and timestep sampling. If your framework exposes them, they strongly influence how much low-frequency versus fine detail the adapter learns.
Monitoring and checkpoints
Save a checkpoint every few hundred steps and render a fixed evaluation prompt set against each one. A frozen, small set of prompts — say eight — turns checkpoint selection from guesswork into comparison. Log loss, but do not trust it as a quality signal: loss reliably tells you when training is broken, not when it is good.
Stop when the evaluation renders stop improving. Overtraining looks like saturated color, rigid motion, and prompts being ignored in favor of the training data's exact compositions.
Step 5: Evaluate output with a scoring rubric
Subjective "that looks cool" assessments collapse under deadline pressure. Score each checkpoint on a fixed rubric, one to five per axis:
- Style fidelity. Does it match the brief's palette, contrast, and texture?
- Prompt adherence. Does it do what the prompt asked, not what the dataset usually does?
- Temporal stability. Any flicker, morphing, or identity drift across the clip?
- Motion naturalness. Do objects obey plausible physics and weight?
- Versatility. Does it hold up across prompts outside the training distribution?
- Render cost. Time and memory per second of output.
A checkpoint that scores 5 on fidelity and 2 on versatility is a trap: it will look brilliant in your demo and fail in production. Prefer balanced scores, and keep a baseline render from the untuned base model for side-by-side comparison.
Step 6: Move from test renders to a production pipeline
A working adapter is not a workflow. The transition requires templating.
Prompt templates and shot presets
Build a small library of prompt templates with named slots — subject, action, camera, environment, lighting, lens. Pair each with a locked seed range and a preferred sampler configuration. This is what makes output predictable across a team: two editors using the same template should get visually consistent results.
ComfyUI-style graphs for reproducibility
Node-based pipelines shine here because they make every step explicit and shareable: model loader, adapter loader, conditioning stack, sampler, upscaler, interpolator, encoder. Version-control the graph alongside the adapter file so a render can be reproduced months later.
Upscaling, interpolation, and audio
Generate at the model's native resolution, then upscale in a dedicated pass. Use frame interpolation sparingly — it smooths motion but can introduce warping on fast action or fine detail. Finally, treat audio as a separate discipline: dialogue, foley, and music should be built to the edit rather than generated to match it.
Versioning your adapters
Adapters are assets. Name them with a scheme that encodes base model, dataset version, training run ID, and purpose. Keep a short changelog noting what changed and which evaluation prompts improved. Six months later, this is the difference between reusing a trained model and retraining from scratch.
Common mistakes and how to avoid them
- Training before conditioning. Exhaust reference-image and structural control options first; they are cheaper and often sufficient.
- Dataset maximalism. More clips with inconsistent quality is worse than fewer excellent ones.
- Caption laziness. Copy-pasted captions make the adapter conflate style and subject.
- No held-out evaluation. If every clip in your dataset is a test case, you have no way to detect overfitting.
- Ignoring licensing. Training rights and output rights are separate questions; clarify both before a project depends on the model.
- One giant run instead of iterations. Three short runs with evaluation between them beat one marathon run every time.
- No baseline. Without a base-model render for comparison you cannot prove the tuning helped.
Tooling landscape: what to use for each stage
A pragmatic split by function rather than brand:
- Dataset assembly and QC: a scripting environment plus a frame-accurate player; ffmpeg for transcode, sampling, and clip extraction.
- Captioning: manual templating for small datasets, assisted auto-captioning with human review for larger ones.
- Training: a framework that supports video latents and adapter training, with checkpointing and resumability.
- Generation and pipelines: a node-graph interface for reproducibility; a scripted API for batch work.
- Restoration and finishing: dedicated upscalers, deflicker tools, and frame interpolation used surgically, not by default.
- Asset management: object storage with clear versioning plus a spreadsheet or small database tracking datasets, runs, and results.
The temptation is to chase the newest model release. In practice, a well-prepared dataset and a disciplined evaluation loop will outperform a better base model paired with messy data every time.
FAQ
How many clips do I need to train a style adapter?
For a coherent single style, 40–120 short clips is a practical range. Quality and consistency matter more than volume; 60 well-matched clips beat 300 mixed ones.
Can I train on a laptop?
Adapter training on small datasets is feasible on a high-VRAM consumer GPU with reduced resolution and batch size. Full fine-tuning is not.
How do I know when to stop training?
When your fixed evaluation prompt set stops improving across checkpoints. If fidelity rises but versatility drops, you have gone past the useful point.
Why does my model ignore prompts after training?
Usually overtraining combined with captions that omit important variation. Shorten the run, diversify captions, and re-check with prompts outside the training distribution.
What causes flicker in generated clips?
Often a mix of training data with exposure instability, insufficient temporal modeling, and aggressive frame interpolation applied after generation. Fix the dataset and temporal layers before touching the finishing chain.
Should I train one model or several?
Several small, purpose-built adapters — one for style, one for a character, one for a product — almost always beat one monolithic model. They are easier to debug, cheaper to retrain, and can be combined at inference time.
How do I keep results consistent across a team?
Freeze the templates: prompt templates, seeds, sampler settings, pipeline graphs, and adapter versions. Consistency is an infrastructure problem, not a talent problem.
The bottom line
Custom video model training is not a research project — it is a production capability. The work breaks down into a repeatable sequence: define the look, build a small and ruthlessly clean dataset, train a compact adapter with a conservative budget, evaluate against a fixed rubric, and then freeze the successful configuration into a templated pipeline you can hand to anyone on the team.
Start small. Train one adapter for one clearly defined look. Evaluate it honestly against an untuned baseline. If it wins, version it, document it, and build the next one on what you learned. That loop — not any single model release — is what gives you a durable visual signature.
