
Why Custom Video Models Change the Production Conversation
Generic text-to-video tools are excellent at producing a plausible clip. They are much less reliable at producing your clip — the one with a recurring character, a specific lighting signature, a product that rotates exactly the way your packaging does, or a motion style your audience already associates with your channel. That gap is where custom training enters the picture.
A custom video model is not one artifact. It is a stack: a base model, one or more fine-tuned adapters, a conditioning setup (reference frames, depth or pose passes, camera hints), and a post-processing chain for color, stabilization, and sound. Teams that treat training as a single checkbox tend to be disappointed. Teams that treat it as a pipeline stage get compounding returns, because every improvement to the dataset or the conditioning setup carries forward into every future shot.
This guide walks through a neutral, end-to-end workflow: deciding whether you need a custom model at all, building a dataset that survives real deadlines, running the fine-tune, evaluating output honestly, and slotting the result into a production pipeline that other people can actually use.
What fine-tuning actually changes
Fine-tuning shifts a model's probability distribution toward your reference material. In video, three things improve first: subject consistency across frames, style consistency across shots, and the camera and motion vocabulary the model is willing to use. Prompt following often improves too, but for a narrower slice of prompts — specifically the ones that resemble your captions.
What fine-tuning does not change: the base model's physics understanding, its ability to render text reliably, or its resolution ceiling. If a base model struggles with hands, a fine-tune will make the hands look like your hands while still occasionally being wrong. Plan post-processing, retakes, and shot selection accordingly. A custom model narrows the space of outcomes; it does not eliminate the need for human judgment at the end.
When prompting is enough — and when it isn't
Before collecting a single frame, run a cheap diagnostic. Generate thirty clips with detailed prompts, reference images, and control signals. Then ask:
- Does the failure repeat across attempts, or is it random noise?
- Is the problem identity, style, motion, or composition?
- Can a reference image plus a control pass solve it?
If a repeated identity or style failure survives good references and good prompts, that is a genuine training signal. If clips fail in a different way each time, you have a prompt and control problem, and training will only make those failures more consistent. This diagnostic step takes an afternoon and saves weeks.
Choosing the Right Layer to Customize
Not every problem needs a full fine-tune. Work from cheapest to most expensive, and stop as soon as the failure disappears:
- Prompt and reference engineering. No training time, fast iteration. Solves composition, mood, and general framing.
- Control adapters. Depth, pose, edge, or motion-transfer passes that constrain structure. Solves blocking and camera geometry.
- Lightweight adapters. Small trained weight sets that inject a subject, style, or product. Fast to train, easy to swap, low risk of damaging the base model.
- Partial or full fine-tuning. Retrains a large portion of the model. Highest fidelity for a narrow domain, highest compute cost, hardest to roll back.
- Custom base training. Rarely justified unless you own a large proprietary dataset and a specialized domain.
A practical rule: if you can describe the target in one sentence — our mascot, flat vector style, always walking left to right — a lightweight adapter is usually enough. If the target is an entire visual language, including lighting, grain, lens behavior, and editing rhythm, you are probably looking at partial fine-tuning.
Decision criteria in practice
Ask three questions. How often will this model be used? A monthly one-off campaign rarely repays the training time; a weekly series does. How stable is the reference material? A locked character design trains cleanly, while a brand that redesigns every quarter does not. And who can maintain it? An adapter that only one person knows how to load is a liability, not an asset.
There is also a fourth, quieter criterion: how much of the work is generation versus selection. If your team spends most of its time choosing between dozens of variants, consistency improvements from a custom model pay off twice — better outputs and less time spent sifting.
Building a Training Dataset That Survives Real Production
Dataset quality decides outcomes far more than hyperparameters. A modest, clean set beats a huge, noisy one almost every time. The hard part is not collecting clips; it is resisting the urge to include almost-right material because deleting it feels wasteful.
Curation rules worth enforcing
- Consistency over volume. Fifty shots of the same subject in the same lighting style will outperform five hundred mixed shots.
- Clip length discipline. Two to ten seconds per clip works well for most adapters. Longer clips dilute the motion signal and inflate compute.
- Cover the angles you actually shoot. If your show always cuts to a three-quarter profile, include three-quarter profiles. Models learn what you show them, not what you imagine.
- Remove almost-right frames. Slightly blurry, slightly off-color, or slightly wrong-proportioned frames teach the model to reproduce those flaws.
- Keep a held-out set. Reserve ten to fifteen percent of clips for validation. Without it, every improvement claim is guesswork.
Captioning and metadata hygiene
Captions are the interface between your intent and the model. Write them the way you will prompt later. Decide on an order — subject, action, camera, lighting, style — and keep it identical across the dataset. Include the trigger token you plan to use at inference, spelled exactly the same way every time.
Avoid two common errors: captions that describe everything including background clutter, and captions so sparse that the model cannot separate subject from scene. A useful middle ground is one clause per concept, under roughly twenty words, with a stable vocabulary for motion and camera terms.
File naming matters more than people expect. Encode subject, style, and source in the filename so you can filter a dataset by attribute later without opening a single clip. Teams that do this can rebuild a training run in minutes instead of days.
Splitting train and validation
Split by scene, not by frame. If frames from the same shot appear in both sets, your validation score will be optimistic and your production results will disappoint. Keep a short written log of what each split contains so you can reproduce the run months later, when nobody remembers which shoot supplied which clip.
The Fine-Tuning Workflow, Step by Step
Step 1: Preprocess with intent
Extract frames only when needed. Many video adapters train directly on short clips, which preserves temporal information that frame extraction destroys. When you must extract, sample at a consistent rate and avoid near-duplicate frames — they bias the model toward whatever moment you oversampled.
Normalize resolution and aspect ratio early. Mixed aspect ratios create letterboxing artifacts that are difficult to remove later. If your delivery format is vertical, train vertical, even when the source material is horizontal. Crop deliberately rather than letting the trainer decide for you.
Step 2: Set parameters you can defend
Three parameters matter most: learning rate, training duration, and adapter capacity.
- Learning rate. Too high and the model memorizes your dataset, producing outputs that look like copies with artifacts. Too low and nothing changes. Start conservative and increase only if the loss curve stalls.
- Training duration. Watch validation output, not the loss number. Overfitting in video shows up as motion freezing, repeated camera moves, or a sudden painted texture across the frame.
- Capacity. Small adapters generalize better and recover faster from thin data. Large adapters capture more detail but need more clips to avoid overfitting.
Log every run: dataset version, caption version, parameters, and sample outputs at fixed prompts. Reproducibility is worth more than any single lucky run.
Step 3: Run a checkpoint evaluation loop
Do not wait for the final checkpoint. Save intermediate checkpoints and generate the same five test clips at each one. Compare them side by side with identical seeds and identical prompts. The best checkpoint is often not the last one; it is the one just before the model starts to overcommit to your data.
Step 4: Document and hand off
Write a one-page model card: what the adapter does, what it does not do, the dataset version behind it, the recommended prompt template, and two or three known failure cases. This document is what turns a personal experiment into shared infrastructure. It also prevents the classic situation where a model performs brilliantly for its creator and mysteriously poorly for everyone else.
Evaluating Custom Model Output Before You Commit
Evaluation in video needs a rubric, otherwise every review becomes an argument about taste. Build the rubric before the training run, not after, so nobody is tempted to justify whichever checkpoint they already prefer.
Motion coherence
Watch a clip three times. First for the subject, second for the background, third for the camera. Real problems appear at the seams: a subject that moves smoothly while the background stutters, or a camera move that reverses direction mid-shot. Score motion separately from image quality. A beautiful clip with broken motion is unusable, and a modest clip with believable motion can carry an entire scene.
Identity and style retention
Ask whether a viewer who knows the subject would recognize it without any prompting. Then check style across a batch, not a single clip. Consistency is a distribution property, so judge ten outputs at a time and count how many hold up.
A simple scoring rubric
Score each test clip from one to five on five axes: subject identity, style match, motion plausibility, prompt adherence, and artifact severity. Then weight those axes by how you will use the model. For a character-driven series, identity and motion dominate. For a mood piece or title sequence, style and prompt adherence matter more. Track scores across checkpoints and pick a winner with evidence instead of instinct.
Wiring a Custom Model Into a Production Pipeline
A trained model that lives on one workstation is a hobby. To become production infrastructure it needs a few unglamorous pieces:
- Versioned weights. Store every adapter with its dataset version and a short changelog.
- A standard prompt template. Pair the model with a documented prompt structure so new team members get consistent results on day one.
- Approval gates. Draft generation, review, and final render as separate stages. Cheap drafts first, expensive renders only for approved shots.
- Fallbacks. Keep the base model and a previous adapter available. When a model fails on an unusual shot, switching beats retraining.
- Batch discipline. Generate variations in fixed batches with locked seeds so comparisons stay fair.
Draft-to-final staging
Split generation into a low-cost exploration pass and a high-cost finishing pass. Explore broadly with the custom model at low resolution, pick the takes that work, then re-render only those with full settings and post-processing. This single change often reduces total render time more than any parameter tweak, because it stops you from polishing shots you will never use.
Document the whole chain in one page. The most common failure in creative pipelines is not bad models; it is undocumented setups that only one person can reproduce.
The Tool Landscape: Where to Train, Where to Render
Treat training and rendering as separate decisions. Training favors environments with predictable compute, checkpoint management, and dataset versioning. Rendering favors tools with strong control features and fast iteration — node-based graphs for control passes, hosted generators such as Runway or Sora for quick exploration, and open models like Flux for flexibility and local control.
Practical combinations that work well:
- Explore with a hosted model, train an adapter locally, render through a node graph. A good balance of speed and control.
- Train and render in the same environment. Simplest to maintain, but you inherit its limits.
- Train in the cloud, render on local hardware. Best when datasets are large but delivery deadlines are tight.
What to look for in a training environment
The features that matter most are boring ones: reliable checkpoint saving, the ability to resume an interrupted run, clear logs, and reproducibility from a saved configuration. Evaluation convenience matters too — if generating test clips requires ten manual steps, nobody will do it consistently, and the checkpoint loop that produces quality quietly disappears.
The right answer depends on your team's tolerance for setup work. A slightly weaker model that everyone can run beats a perfect model that only one engineer can launch.
Common Mistakes That Waste Training Runs
- Training before diagnosing. Fine-tuning a prompt problem produces confident, consistent failure.
- Mixed reference material. Multiple lighting setups or character proportions in one dataset teach the model to average them.
- Ignoring validation. Without a held-out set, every claimed improvement is unverifiable.
- Chasing the final checkpoint. Late checkpoints frequently overfit; earlier ones often generalize better.
- No version control. You cannot improve what you cannot reproduce.
- Evaluating one clip. Video quality is statistical; judge batches.
- Skipping preprocessing. Resolution and aspect-ratio inconsistencies surface later as artifacts.
- Forgetting post-processing. Color, stabilization, and sound carry a surprising share of perceived quality.
Managing Compute, Time, and Expectations
Budget time in three buckets: dataset preparation, training iterations, and evaluation. In most real projects, preparation takes the longest, and teams that plan for it finish faster than teams that treat it as overhead. A rough starting split for a first adapter is half preparation, a third iteration, and the remainder evaluation and documentation.
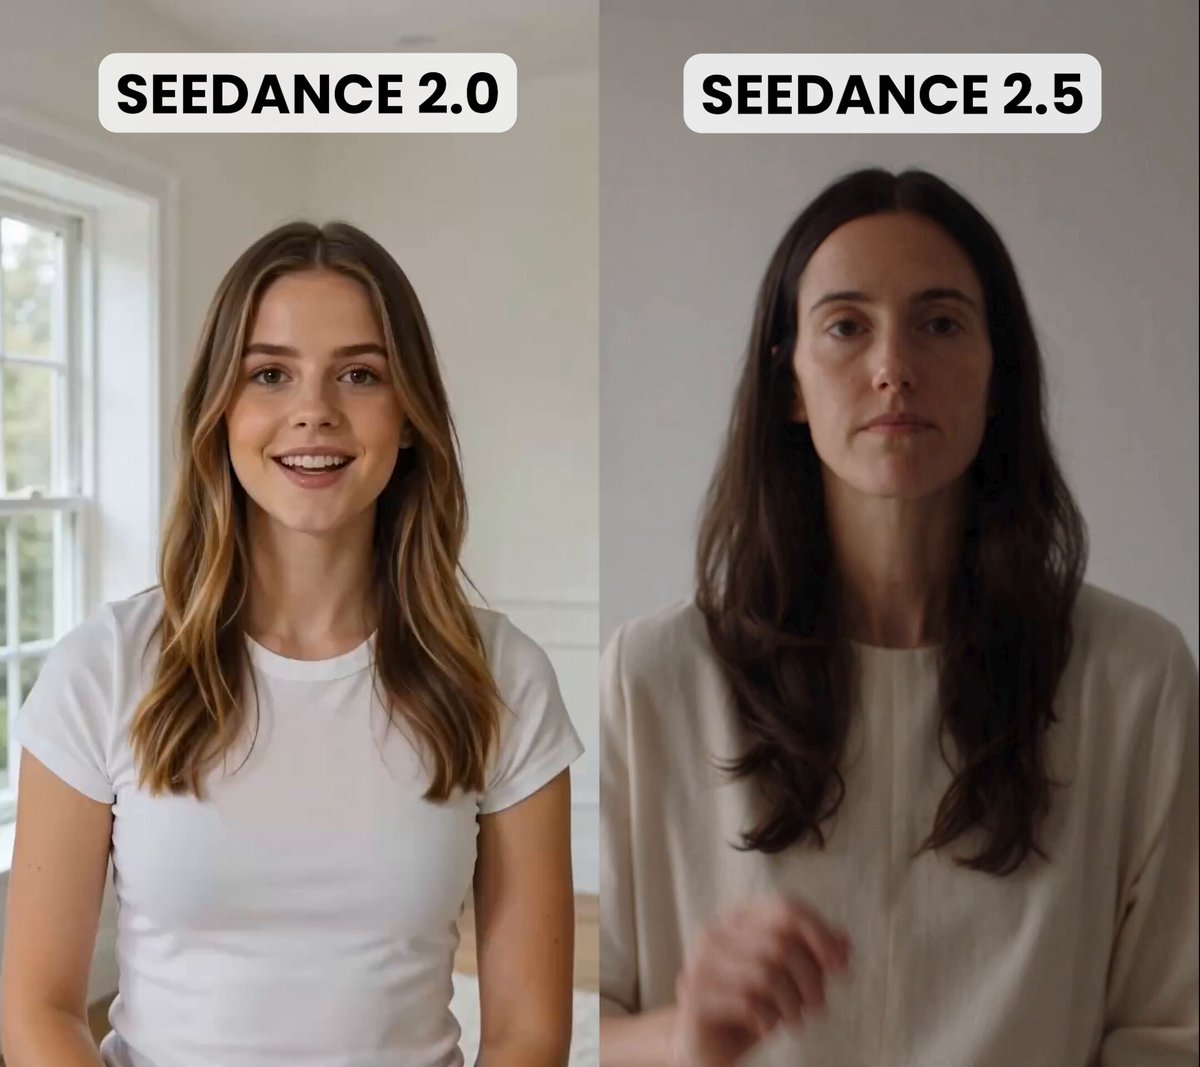
Set expectations early with stakeholders. A custom model improves consistency and style; it does not remove the need for a shot list, an editor, or sound design. Frame it as one stage in a pipeline, and show a before-and-after clip so the improvement is visible rather than described.
Finally, plan for retirement. Models age: base versions update, styles drift, teams change, and datasets become stale. Schedule a review every few months, and be willing to retrain rather than patch indefinitely. A model that everyone quietly stopped using is worse than no model at all, because it hides the real problem.
FAQ
How much footage do I need? For a focused adapter, a few dozen clean clips of consistent length and framing often beat hundreds of mixed clips. Start small, evaluate, then expand where the failures actually are.
Can I train on mixed aspect ratios? You can, but expect artifacts around the edges and inconsistent framing. Normalize before training whenever possible.
How do I know when to stop training? When validation clips at fixed prompts stop improving and start echoing your dataset too literally. Save checkpoints along the way; the best one is often earlier than you expect.
Should I fine-tune or use control adapters? Use control adapters first. They solve structure and blocking cheaply. Move to trained weights when identity or style failures repeat across many unrelated prompts.
Do custom models replace prompt engineering? No. They narrow the space of outcomes. Precise prompts still determine what happens inside that space.
How often should I retrain? When your reference material changes meaningfully, when a base model you depend on updates, or when evaluation scores drift. For an active series, a quarterly review is a reasonable rhythm.
What if my outputs look like copies of the dataset? That is overfitting. Reduce training duration or capacity, add caption variety, and increase dataset diversity rather than adding more identical clips.
Can one model serve multiple projects? Sometimes, when the projects share a visual language. Otherwise, separate adapters are easier to maintain, swap, and retire than one overloaded model doing everything adequately and nothing well.
