
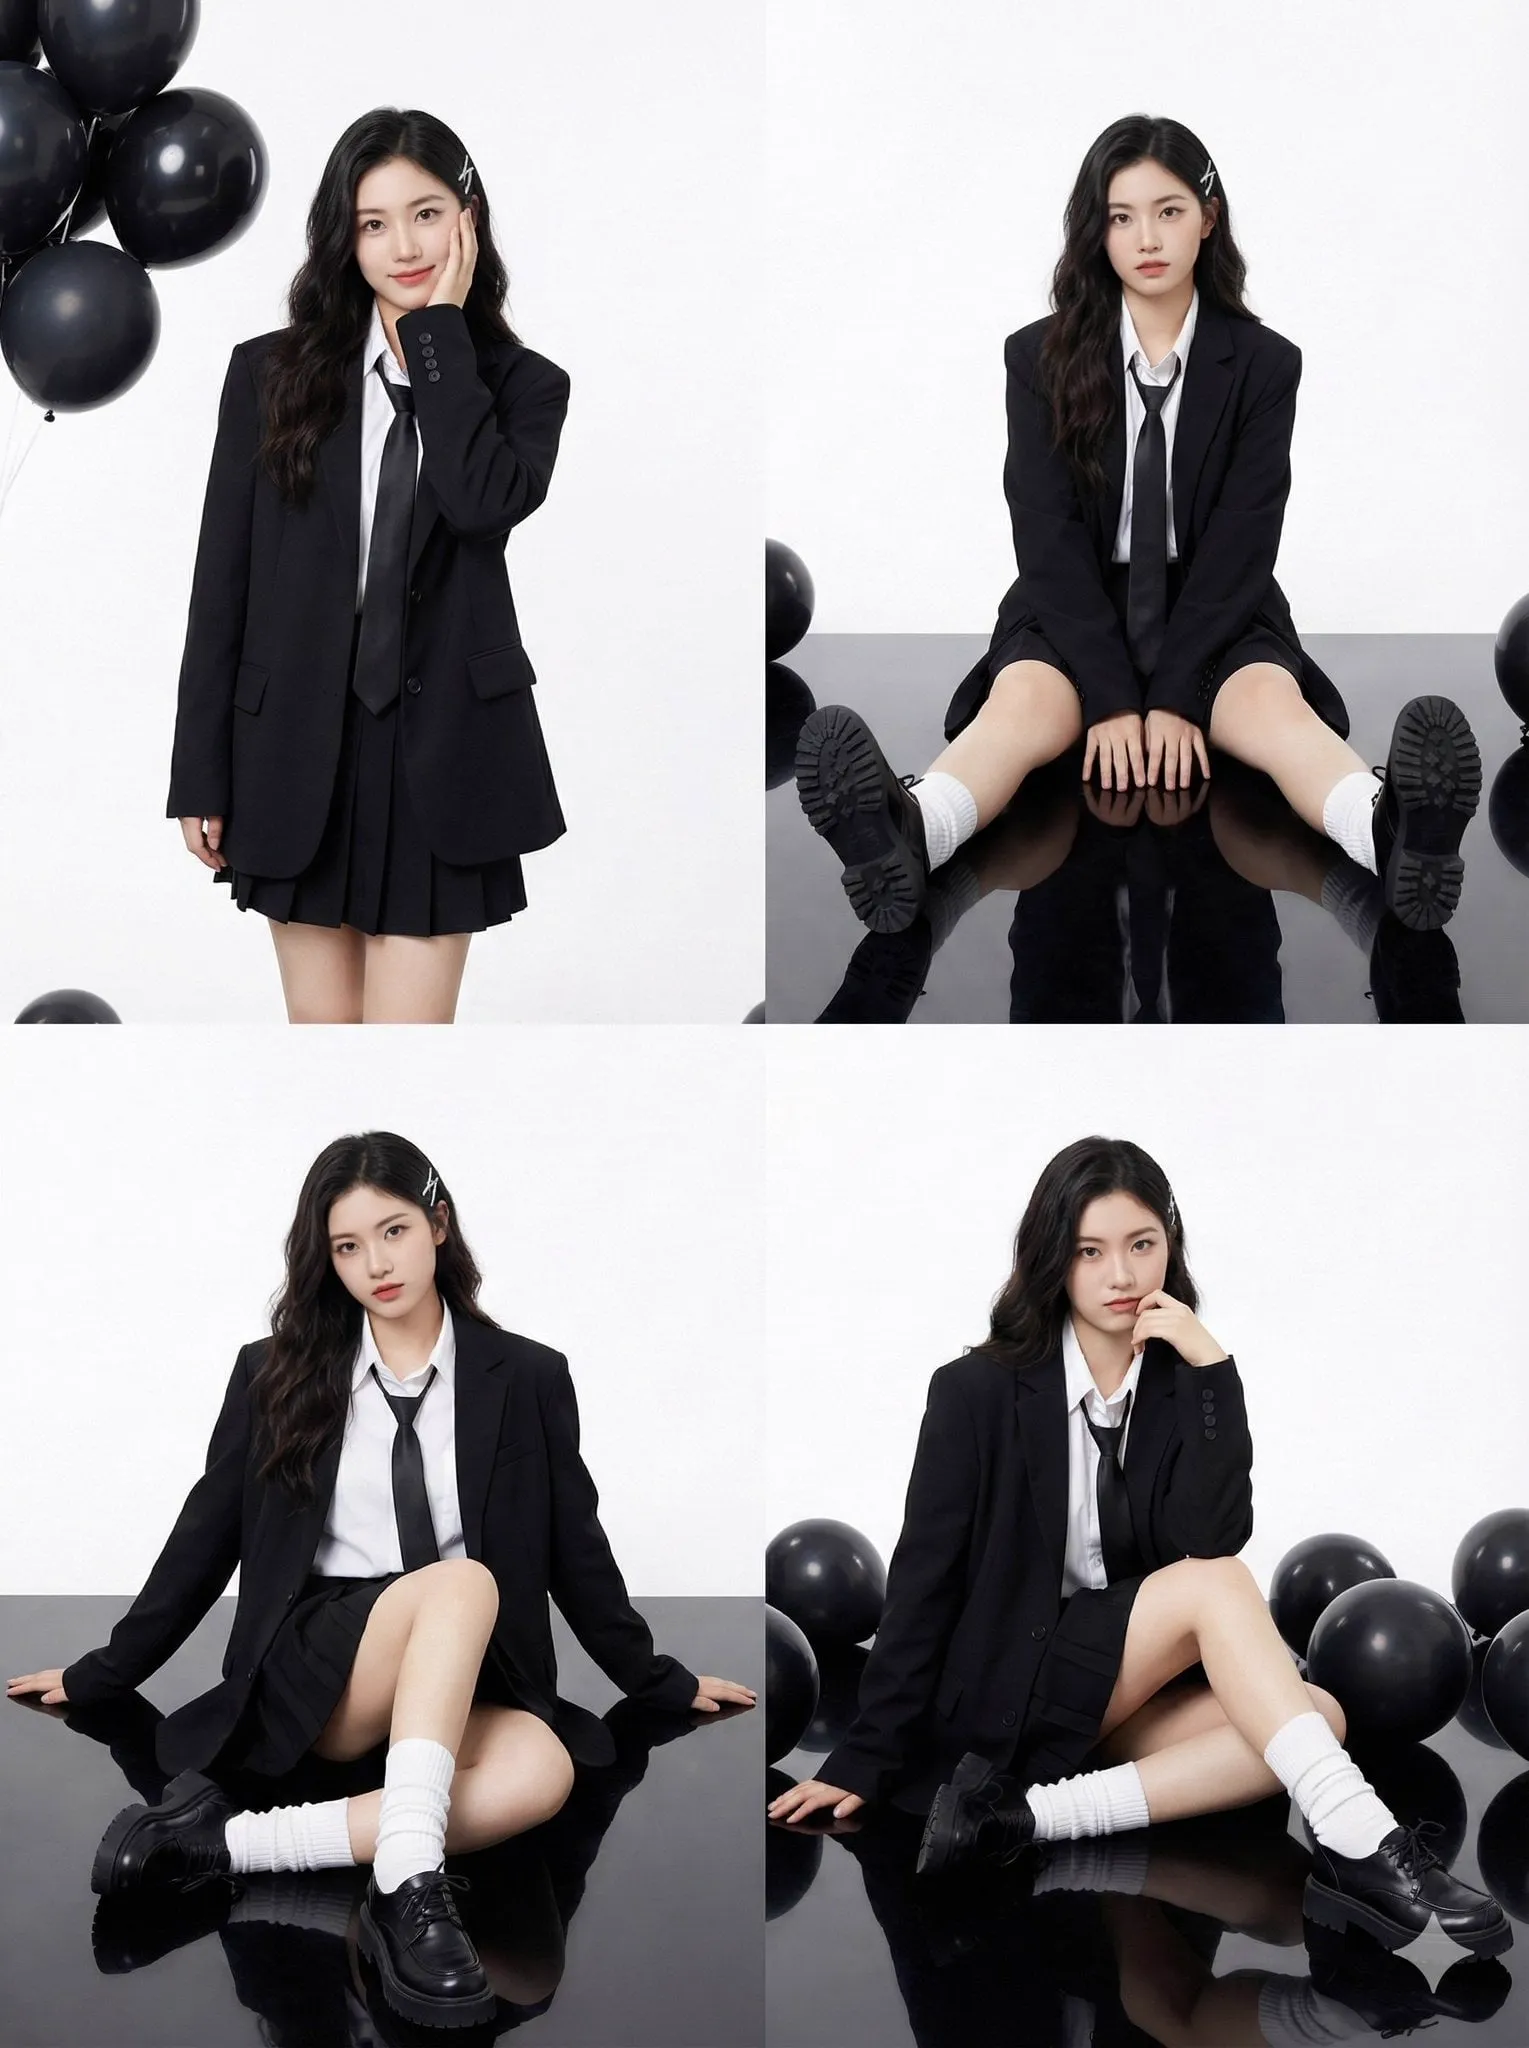
Most AI video projects begin with a prompt and end with a compromise. You describe a character, generate a shot, and get something close — but the face shifts between takes, the wardrobe mutates, and the visual style drifts from moody cinema to flat cartoon in the space of three frames. The usual reaction is to write a longer prompt. That rarely works, because prompts describe, they do not memorize. The reliable fix is to train a small, focused model that already knows what your character looks like and how your visual language behaves.
This guide covers a neutral, practical workflow: assembling a dataset, training a character model, training a style model, combining the two, and finishing a sequence that holds together from first frame to last. It is written for creators working with consumer GPUs, cloud notebooks, or hosted training tools, and it assumes no machine-learning background.
What a custom model actually changes
A base generator knows the world in general. It has seen millions of faces, so it can produce a plausible person — but "plausible" is the enemy of "the same person twice." A custom model narrows that enormous space to a small, specific region: this face, this hairline, this jacket, this lighting response.
The practical difference shows up in four places:
- Identity stability. The character survives a change of camera angle, outfit, and background without morphing into a cousin.
- Shot economy. You stop generating twenty options hoping one lands. Two or three attempts usually produce a usable frame.
- Sequence coherence. Wide shot, close-up, and profile all read as the same person in the same story.
- Style ownership. Once your aesthetic is encoded, every new scene inherits it automatically instead of you re-describing lighting and grain every time.
The trade-off is upfront work. Training a character model takes an afternoon of dataset prep and a training run. That cost is recovered the first time you need ten consistent shots instead of one.
Character identity versus visual style
These are two separate problems, and mixing them into one training run is the most common early mistake. Separating them gives you control: you can restyle a character, or reuse a style with a new cast.
What a character model learns
A character model learns the geometry and surface of a specific person: facial proportions, bone structure, skin texture, hair behavior, and often signature clothing. Its job is to answer "who is this?" independent of where they are standing.
What a style model learns
A style model learns rendering decisions: color grading, contrast curve, lens character, grain, line weight, brush texture, lighting direction, and the overall emotional temperature of the image. Its job is to answer "how does this look?" independent of who is in frame.
When you train both on the same small dataset, the two signals bleed into each other. You end up with a model that produces your character only when the background matches your original photos, and a "style" that is really just one specific face. Keep the datasets separate and the checkpoints separate.
Where they overlap
There is one legitimate overlap: lighting. If your style depends on a very specific key light, some of that will attach to the character model. That is fine. Just be aware that a character trained under hard rim light will look slightly odd dropped into flat daylight until you refine it.
Building a dataset that trains cleanly
Dataset quality decides the outcome more than any training parameter. Twenty excellent images beat two hundred mediocre ones, and a well-curated set of thirty is usually enough for a strong character.
Coverage, not quantity
Aim for this spread:
- Three to five frontal or near-frontal portraits with neutral expression.
- Two or three three-quarter angles, left and right.
- At least one profile.
- Two or three medium shots showing shoulders and torso.
- One or two full-body or wide shots if the character will appear in motion.
- If the character wears a signature outfit, include it in roughly a third of the images rather than all of them, so the model learns the face as primary.
Vary lighting moderately. If every image is shot in the same room under the same lamp, the model will treat that room as part of the identity.
Resolution and crops
Train at the highest native resolution your training tool supports, typically 1024 or 1024-plus. Crop tightly to head and shoulders for portrait-focused models, but do not crop so aggressively that you cut off the chin or the top of the hair — the model needs the full silhouette to reproduce it.
Captioning strategy
Captions tell the trainer what is variable and what is fixed. For a character model, describe everything that should not be baked in:
a woman in a red raincoat standing in a doorway, overcast lighta woman in a grey t-shirt against a white wall, soft studio light
The repeated subject phrase anchors the identity. The varying details teach the model that background, clothing, and lighting are swappable. If you caption every image identically, you accidentally teach the model that the whole composition is the character.
Cleaning checklist
Before training, remove: watermarked images, heavy filters, motion blur, duplicate frames from the same second of video, images with other prominent faces, and anything with text overlays. Each of those becomes noise that the model learns as signal.
A step-by-step training workflow
Here is a sequence that works across most modern training interfaces. The names of parameters differ slightly between tools; the logic does not.
Step 1: Write a reference bible
Before touching any training software, write one page describing your character and your visual style in concrete terms. For the character: age range, face shape, hair color and texture, eye color, distinguishing marks, posture, wardrobe palette. For the style: color temperature, contrast, lens choice, film stock or rendering medium, grain level, and two or three reference films, illustrators, or photographers.
This document keeps you consistent when you are fifty generations deep and tempted to accept a slightly wrong face.
Step 2: Train the identity model
Upload the character set, apply the repeated subject phrase, and start with a moderate learning rate and a step count in the low thousands. Overfitting looks like this: every output is nearly identical to a training photo, including the background. Underfitting looks like this: the face is generically similar but not the same person.
Generate a test grid after each checkpoint — at minimum, a frontal portrait, a three-quarter shot, a profile, and one scene the model has never seen. Pick the checkpoint that holds identity across all four.
Step 3: Train the style model
Build a second dataset from 20–40 images that share your intended look but contain no recurring character. Landscapes, architecture, product shots, and crowd scenes all work. Caption them with content descriptions only.
Because style is easier to overfit than identity, keep the training shorter and watch for one failure mode: the model starts reproducing specific compositions from the training images rather than the aesthetic. If every output is a horizon line at the same height, reduce steps.
Step 4: Combine them in a single shot
Load the character model at moderate weight and the style model at a lower weight than you first expect — often 50–70% of the character's strength. Stacking two strong models at full power produces muddy, over-baked images with harsh contrast and waxy skin.
Generate a short test set: same prompt, three different seeds. If the identity survives and the style reads clearly, you have a working combination. Save those weights as a named preset so you never have to rediscover them.
Step 5: Iterate in small increments
Change one variable at a time: model weight, prompt phrasing, seed, or control input. Document each change in a simple log. After a week you will have a personal recipe that no tutorial can give you.
Holding consistency across different base generators
You will not always want the same base model. Some handle motion better, some handle illustration, some handle photoreal skin. Your character and style models should travel with you, but they will not transfer perfectly.
Practical approaches:
- Test before committing. Before generating a whole scene on a new base model, run a four-shot identity test. If the face softens, increase character weight by 10–15%.
- Use a control image. Feeding a single approved reference frame as a structural guide keeps proportions anchored when you switch bases.
- Keep one anchor shot. Designate one frame as your canonical look — the one you compare everything against.
- Expect drift at extremes. Very wide shots and extreme close-ups stress identity models. Extra reference coverage at those distances helps.
Prompting and control tools that keep a look together
A trained model does heavy lifting, but prompts still steer composition. Structure prompts in a fixed order so results are comparable:
- Subject and action
- Wardrobe and props
- Environment
- Camera angle and lens
- Lighting
- Style and medium keywords
- Quality and detail modifiers
Keep a written prompt template and vary only the slots you need. This turns randomness into a controlled experiment and makes it obvious when a bad frame is a prompt problem rather than a model problem.
Beyond text, several control layers help enormously:
- Pose and depth control to lock a body position across a sequence.
- Reference-image conditioning to nudge a shot back toward a specific look.
- Motion guidance for video, so camera movement is deliberate rather than incidental.
- Frame interpolation and upscaling applied after identity is confirmed, never before.
Editing, motion, and finishing
Training gets you consistent frames. Finishing gets you a watchable sequence.
Start with a shot list. Even a six-shot scene benefits from planning: establishing wide, medium, close-up, reaction, detail insert, and a closing wide. Generate stills for each beat first, approve them, then animate. Animating an unapproved still wastes time and compute.
For motion, keep clips short — three to six seconds — and stitch them in an editor. Long single generations accumulate identity drift, and it is far easier to match two short clips than to repair one long one.
In post:
- Apply a single color grade across all clips so small model-level differences flatten out.
- Add grain as a final layer. It unifies images generated at different detail levels.
- Match audio and ambience early; they do more for perceived continuity than any frame tweak.
- Keep a versioned project folder with your model weights, prompts, and seeds recorded alongside the edit.
Common mistakes and how to fix them
Identity drifts across shots. Overfitting or insufficient angle coverage. Add profile and three-quarter references, then retrain rather than pushing weights higher.
Style overwhelms the subject. Lower style weight, or increase the character weight slightly. If the style model was trained on heavily graded images, reduce contrast in the source set and retrain.
Outputs look plastic. Usually over-training. Reduce steps, lower model weight, and add natural texture words to the prompt.
Every image looks like a training photo. Classic overfit. Reduce steps, add caption variety, and include more background diversity in the dataset.
Character looks right but costumes mutate. The outfit was baked into the identity. Caption clothing explicitly so it is treated as variable.
Style is inconsistent between clips. Check for seed reuse versus seed change, and make sure the same style checkpoint is loaded in every generation session.
Rights, consent, and responsible use
Trained models of real people raise real obligations. Use likenesses only with documented permission, and keep that documentation with the project files. For synthetic characters, generate identities that are not composites of identifiable people. When a character is fully AI-generated, a short disclosure in the description builds audience trust without damaging the work.
Also consider where your dataset came from. Images you do not own or license should not go into training, even for private tests, because trained weights are hard to unlearn. Keep a manifest of source images with license notes.
FAQ
How many images do I need for a character model?
Twenty to forty well-varied images is a strong starting point. Quality and angle coverage matter far more than hitting a specific number.
How long does training take?
On a consumer GPU, a character model typically takes 20–60 minutes. Style models are usually faster because fewer steps are needed.
Can one model handle both character and style?
Technically yes, practically no. Combined training creates entangled results that are hard to adjust independently.
Do I need a powerful GPU?
Not necessarily. Hosted training services and cloud notebooks let you train on rented hardware and download the resulting weights to a local machine.
Why does my character look fine in stills but wrong in motion?
Video generation adds a second consistency problem — temporal coherence. Lock the look in stills first, then animate short clips and match them in an editor.
Will my model work with a different generator?
Often partially. Expect to retest identity and adjust weights by 10–15% when switching base generators.
How do I protect my trained model from being copied?
Keep weights private, avoid distributing raw checkpoint files, and treat the dataset itself as confidential. Note that what you publish as video is publicly visible regardless.
A decision checklist before your next project
Run through these before you spend a day generating:
- Is the character model trained on at least four distinct angles?
- Is the style model trained separately from the character?
- Have I saved the exact weight combination that worked?
- Do I have an approved anchor frame to compare against?
- Is my shot list written before generation begins?
- Are clips short, with motion added after stills are approved?
- Is color grading applied uniformly at the end?
- Do I have documented permission for any real likeness?
Custom models are not a shortcut past craft. They are a way of moving your decision-making earlier in the process — from fifty hopeful generations to one deliberate dataset, one training run, and a consistent sequence you can actually build a story on.
