
Why text-to-video changed the production math
Turning a written idea into moving footage used to require one of three things: gear, a crew, or a compromise. A paragraph of text that becomes a coherent moving shot in under a minute changes how small teams plan, budget, and iterate on content.
The important consequence is that the expensive part of video production moved. Cameras are affordable, editing software is often free, and distribution costs nothing. What used to be scarce was the ability to capture a specific image at a specific moment — the right light, the right angle, the right gesture. Now the scarce resource is judgment: which prompt to write, which tool to route it to, and when a generated clip is good enough to ship.
That last point matters more than it sounds. Free generation tools make it trivially easy to produce fifty mediocre clips and very hard to produce one finished video. The gap between people who get results and people who collect folders of exports is almost never access to better technology. It is process discipline: a repeatable way to move from idea to exported file without endless tinkering.
This guide is for anyone working with free or low-cost generative video tools who wants output that looks intentional rather than accidental. It covers how the technology works at a practical level, how to choose tools, how to build a workflow you can repeat, where beginners quietly fail, and how to troubleshoot the specific artifacts that appear most often.
How text-to-video actually works, in plain language
A working mental model helps you debug bad output instead of guessing at random fixes.
From noise to frames
Most modern video generators are diffusion systems. They begin with random noise and progressively clean it up until an image appears. For video, that cleaning process happens across a stack of frames simultaneously, which is why a single pass can produce coherent motion rather than a slideshow.
Temporal consistency is the hard part
A still image only has to look plausible once. A video has to look plausible in every frame and also agree with the frames around it. Models handle this using learned patterns about how objects, fabric, hair, water, smoke, and cameras tend to move. When a hand melts into a sleeve or a background wobbles, you are watching that learned motion pattern run out of confidence. This is also why some subjects are consistently harder than others: faces and hands have very little tolerance for error, while landscapes and abstract textures hide mistakes well.
Where your time actually goes
A generation run has roughly four stages. Your prompt is encoded into a numeric representation, which is fast but decides a lot. The frames are generated, which is the slow part. Frames get refined and stabilized for temporal smoothness. Finally, resolution and frame rate may be increased.
The practical lesson: it is almost always faster to rewrite a prompt and regenerate than to repair a bad clip in editing software. Post-production can fix color, pacing, and sound. It cannot invent a performance that was never there.
Choosing a free tool: a practical scorecard
No single generator wins every category. The best tool depends on the shot, the deadline, and what you can tolerate.
Six criteria that decide everything
- Clip length per run. Four to eight seconds is typical on free tiers. Anything longer usually means stitching multiple generations.
- Resolution ceiling. Check whether upscaling is included, and whether it is a separate step with its own wait.
- Motion quality on your specific subject. People, animals, vehicles, food, and abstract textures each fail differently.
- Prompt adherence. Does the tool respect composition instructions, or does it drift toward whatever its training data favored?
- Image-to-video support. Essential if you need a consistent character or product across several shots.
- Licensing and export terms. Confirm what you can publish and monetize before you build a campaign around the output.
Model families and what they are good at
General-purpose models handle almost anything acceptably and nothing brilliantly. They are the right default when you are exploring an idea for the first time.
Stylized models are tuned for a specific look — animation, painterly illustration, stop-motion clay, retro film grain. If your project has a strong visual identity, a stylized model beats a general one on the first attempt most of the time.
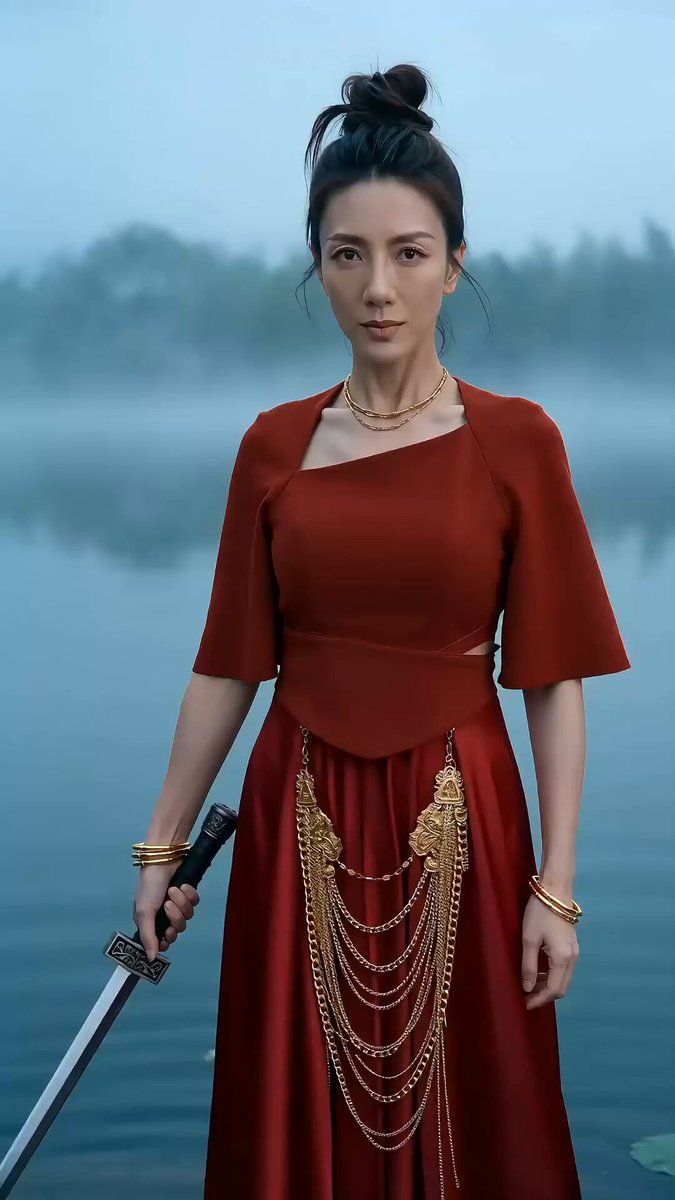
Cinematic and photoreal models prioritize lighting, depth of field, and camera language. They reward detailed prompts and punish lazy ones severely.
Keep a personal scorecard. After twenty clips you will know which tool handles faces, which handles landscape movement, and which one always over-saturates. That private routing table outperforms any published leaderboard because it is calibrated to your subject matter.
Where free tiers quietly limit you
Free access usually constrains three things: queue priority, output length, and control features. The queue is the most underrated. A tool that takes ninety seconds per clip and a tool that takes nine minutes per clip both look free on a pricing page, but only one of them supports iteration. If your workflow depends on generating three variations per shot across twelve shots, queue time becomes the whole project budget.
A repeatable workflow from idea to export
Ad hoc generation is fun once and exhausting forever. This sequence is designed to be repeated.
Step 1: write the logline and shot list
Generated video punishes improvisation. Start with a one-line logline, then break it into six to twelve beats. Each beat should be describable in a single sentence. A wide shot of a rain-soaked alley at night, camera pushing slowly forward. If you cannot describe a shot in one sentence, it is really two shots.
Step 2: build prompts with a fixed architecture
Use the same field order every time so results are comparable. A reliable structure looks like this: subject, action, environment, camera, lighting, style, technical notes.
An example: a lone cyclist pedaling uphill through coastal fog, on a cliff road at dawn, slow tracking shot from the side, soft blue-grey light, 35mm film look, shallow depth of field.
Every field you omit is a field the model fills with its own average. That average is the reason so many beginner clips look strangely similar to one another.
Step 3: generate in controlled passes
Produce two or three options per shot with small variations rather than ten versions of the same sentence. Change one variable at a time — camera angle in one pass, lighting in the next — so you learn what actually moved the result. This is slower on the first project and dramatically faster on the third.
Step 4: lock selects and stop generating
Once you have one acceptable clip per beat, close the generator. Move to the timeline. This is the single discipline that separates finished videos from folders of orphan clips. Assemble the selects, check the rhythm, and only then decide whether any shot truly needs to be regenerated.
Step 5: sound before polish
Add an ambient bed, a music track, and a few punctuating sound effects before you color-correct anything. Generated footage is silent, and silent footage reads as cheap regardless of image quality. Sound also exposes pacing problems that are invisible when you are watching clips individually.
Prompt patterns that reliably produce motion
Motion is the hardest thing to describe and the most important thing to control.
Use verbs that imply physics
Words like walking, drifting, swirling, and settling carry more motion information than adjectives. A busy market is static. Shoppers weaving between stalls while steam rises from a griddle is a shot. Whenever a description feels flat, replace nouns with actions.
Separate camera movement from subject movement
These are two different instructions, and models treat them differently. A dancer spins and the camera orbits the dancer produce very different results. Combine them carelessly and you often get neither. State the subject action first, then the camera behavior, as two clear clauses.
Add speed governors
Terms like slow push, gentle drift, rapid pan, and static locked-off frame act like speed limits. If a clip feels frantic, add a speed word before changing anything else in the prompt.
Anchor the first frame with an image
If you need a precise opening composition, generate a still image first and use it as the starting frame. Text is a weak tool for exact composition. Images are a strong one. This also gives you a stable reference for consistent characters across a sequence.
Use negative space deliberately
Mentioning what should not appear helps more than most beginners expect. Empty street, no crowds, no text overlays, no logos reduces the number of unrelated objects the model tries to insert. Keep negatives short and concrete; long lists of prohibitions tend to confuse rather than constrain.
Keeping characters and products consistent
Consistency is where free workflows get tested, because custom subject training is usually unavailable.
The reference-frame method
Generate one strong still of your character or product. Save it in a dedicated folder. Use that exact file as the starting frame for every subsequent shot. Vary camera angle and environment through the prompt text while keeping the reference constant. This visual anchor survives across clips far better than any written description.
Lock your description blocks
Describe clothing, hair, and accessories in identical wording every single time. A model does not understand that a red jacket and a crimson coat are the same garment. Copy and paste your description block instead of paraphrasing it from memory. Small rewrites create slow drift that is easy to miss while generating and obvious while editing.
Solve the rest editorially
If a consistent close-up is impossible within your tool's limits, cut around it. Use hands, silhouettes, over-the-shoulder angles, reflections, and environmental details. Audiences read these as intentional coverage, and they cost nothing to generate. Professional editors have hidden inconsistencies this way for decades.
Mistakes that quietly ruin free-tier projects
Most failures are not technical. They are habits.
Writing prompts like search queries. City, night, neon, cyberpunk, 4K gives the model no subject action and no camera instruction. Add a person doing something.
Cramming five ideas into one shot. Multiple subjects in a single prompt produce a blurry compromise. One shot, one idea.
Deciding aspect ratio late. Generating everything in landscape and cropping to vertical destroys composition. Choose your delivery format before the first generation.
Chasing perfect motion. Some shots will never stabilize. Replace the shot instead of regenerating endlessly; the tenth attempt rarely beats the third.
Ignoring sound entirely. Silent exports feel unfinished. An ambient layer and one music track raise perceived quality more than a resolution bump.
Never reviewing at full size. Watch every clip at one hundred percent before committing it. Preview windows hide compression artifacts that appear in the final export.
Generating without a shot list. Without a target, you will accept mediocre clips simply because they exist.
Mixing too many tools in one piece. Every tool has its own color science and motion feel. Switching constantly creates a patchwork. Pick one primary generator per project and use others only for specific problem shots.
Forgetting the first three seconds. If nothing interesting happens at the start, viewers leave. Generate a hook shot deliberately rather than hoping an establishing shot will hold attention.
Quality control before you publish
Run the same checklist every time. Consistency in review is what keeps quality from drifting.
- Play the full timeline without pausing. Does the rhythm hold, or does it sag in the middle?
- Watch muted. Does the visual sequence still tell the story?
- Check the opening three seconds. Is there a concrete reason to keep watching?
- Scan for morphing hands, drifting backgrounds, and flickering textures at normal speed rather than frame by frame.
- Verify that any text overlay is legible on a phone screen held at arm's length.
- Confirm the tool's terms allow your intended use, including commercial publication.
- Export the final file and rewatch that file, not the timeline preview.
- Watch it once on a small screen with poor speakers, the way most of your audience will.
Speed, quality, control: splitting work between free and paid
Free tools are never free in every dimension. You are always trading among three variables.
Speed is how fast you get a usable clip. Free tiers often queue, and queue time is real time taken from your project.
Quality is resolution, motion coherence, and prompt fidelity. Higher tiers usually win here, though not by as much as marketing suggests.
Control is how precisely you can direct output. Keyframe specification, motion brushes, and reference conditioning typically sit behind paid access.
A hybrid routing strategy
Use free tools for exploration, storyboarding, and low-stakes social content. Reserve paid capacity for hero shots that anchor a piece — the opening image, the product reveal, the emotional beat. Many creators finish entire projects this way without paying for more than a handful of premium generations.
When upgrading actually pays off
Upgrade when a bottleneck is measurable. If you are spending more time waiting in queues than writing prompts, higher throughput pays for itself. If your only problem is that one character never stays consistent, look for a tool with stronger reference conditioning rather than a broader subscription. Buy the specific capability you are missing, not the tier that sounds most professional.
Troubleshooting specific failures
Melting hands and faces
Reduce motion speed, pull the camera back so the subject occupies less of the frame, or cut to hands in close-up as separate coverage. Adding a speed governor such as slow, gentle movement fixes more hand artifacts than any other single change.
Flicker and texture crawl
Flicker usually comes from high-frequency detail: fine patterns, dense foliage, chain-link fences, striped fabrics. Simplify the background or add slight motion blur. Applying a subtle denoise pass in your editor also helps.
Background drift
If walls, horizons, or architecture slide sideways, the model is treating the background as part of the moving subject. Add explicit camera language, or anchor the shot with a static locked-off camera instruction.
The clip ignores your prompt
Long prompts dilute. Cut the prompt to its essential subject, action, and camera, verify the core idea works, then rebuild detail in layers. If image-to-video is available, a starting frame will enforce composition more reliably than text.
The clip is too static
Models default to minimal movement when uncertain. Add a physics verb, specify a camera move, and describe something entering or leaving the frame. Motion at the edges of a shot is easier to generate than motion in the center.
Audio and lip sync mismatch
If you are adding dialogue, do not attempt to match generated mouth movement precisely. Use reaction shots, over-the-shoulder framing, or narration over b-roll instead. Trying to force lip sync on generated footage consumes more time than restructuring the scene.
FAQ
Do I need a powerful computer to work with generated video?
No. Most tools run in a browser and do the heavy processing on remote hardware. Your machine mostly handles the editing timeline, which is far less demanding. A mid-range laptop with a stable connection is enough for a full project.
How long does it take to produce a thirty-second video?
With a shot list and a fixed prompt structure, expect two to four hours for six shots including generation, assembly, and sound. The first project takes longer because you are learning which tool handles which subject.
Is it better to generate one long clip or several short ones?
Several short clips, almost always. Short generations have fewer opportunities for artifacts, give you more editing flexibility, and let you replace a single bad shot instead of an entire sequence.
What makes a prompt fail most often?
Vagueness about action. Descriptions of places and moods generate pretty, static images. Descriptions of something happening generate video. If a clip looks like a photograph with slight movement, your prompt lacks a verb.
Can I use generated clips commercially?
That depends entirely on the tool's terms, which change frequently. Check the current license before you publish anything commercial, and keep a record of which tool produced which asset so you can prove provenance later.
How do I stop my videos from looking generic?
Constrain the model. Specify lens, light direction, color palette, and time of day. Generic output is the average of everything the model has seen. Specific instructions push it away from that average.
Should I always upscale?
Upscale at the end, not during exploration. Upscaling costs time and can amplify artifacts. Confirm a shot works at base resolution first, then upscale only the selects you actually use.
Start with one thirty-second piece
Pick a project you can finish in a single sitting: six shots, thirty seconds, one music track, no dialogue. Write the logline. Build the shot list. Generate two options per shot. Assemble. Add sound. Export.
The finished video is not really the point. The point is discovering your own routing table — which tool handles faces, which handles landscapes, which prompt structures consistently produce the motion you imagined. That knowledge compounds, and no tutorial can hand it to you.
Once you have one completed piece, repeat the same workflow rather than inventing a new one. Build a small library: a reference-frame folder, a saved prompt template, a sound palette, an export preset. Every subsequent project starts from a higher baseline.
Creators who get consistent results are rarely the ones with the most tools. They are the ones with a process they actually repeat. Start with text, end with motion, and let each finished video teach you the next prompt.
