
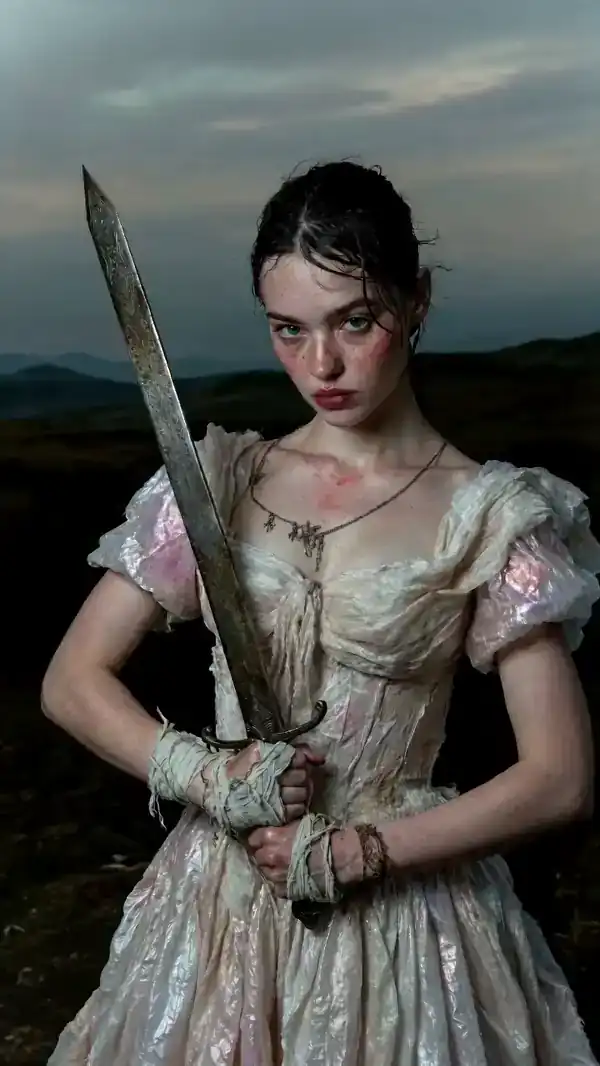
Photorealistic generation has quietly crossed a threshold. Work that once demanded a render farm, a lighting rig, and a week of compositing can now be approximated in a browser tab — but only by people who understand why an image reads as real in the first place. The difference between an AI picture that looks impressive in a feed and one that survives a client review on a 4K monitor is rarely the model itself. It is the pipeline around the model: references, prompt structure, iteration order, motion control, and finishing.
This guide is a working method rather than a list of tools. It explains how photorealism is constructed, how to write prompts that behave like camera notes, how to move from stills to believable video, how to keep characters consistent across shots, and how to catch the failures that give generated media away.
Why Photorealism Is a Systems Problem, Not a Prompt Trick
Most people treat photorealism as a vocabulary problem: find the right magic words and the model produces a photograph. That works occasionally, which is exactly why it is a trap. A single lucky generation teaches nothing, and the same prompt will fail the moment you need a different angle, a different subject, or the same character in a second shot.
The eye is not a passive receiver. It is trained to detect anomalies in a few specific places: human faces and hands, fabric and hair where strands should separate, reflections that should bend with the surface, shadows that should agree with a single light source, and motion that should carry weight. When any of these disagree, the brain flags the image as wrong long before the viewer can articulate why.
That gives you a practical definition of photorealism: consistent light behavior, consistent identity, and plausible motion cadence. Each of those is independent, and each can be controlled at a different stage of the pipeline. Prompting influences all three weakly; references, control layers, shot planning, and post-production influence them strongly.
The consequence is a simple rule. Decide in advance which stage owns which problem. Composition is owned by planning and reference. Identity is owned by reference sheets and control inputs. Light is owned by explicit descriptions plus grading. Motion is owned by clip length, camera instruction, and stitching discipline. When something looks fake, you should be able to name the stage that failed instead of re-rolling the prompt and hoping.
The Four Layers That Make an Image Read as a Photograph
Photorealistic images are built from four overlapping layers. Weakness in any one of them is visible, even when the other three are excellent.
Lens and camera signature
Real photographs carry the fingerprint of optics: a focal length that compresses or widens space, an aperture that decides how much falls out of focus, slight chromatic aberration on high-contrast edges, a touch of vignetting, and sensor noise in shadows. Specify these explicitly — 50mm at f/2 on a full-frame sensor, 85mm portrait compression, 24mm environmental wide — and the output stops looking like an illustration. Leaving the lens unspecified leaves the model to invent a generic, airless look.
Light behavior
Light is the layer beginners skip. Choose one dominant source, define its direction and height, then describe what it does after it lands: bounce from a nearby wall, spill across a table, falloff into shadow. Name the color temperature in plain terms — warm tungsten interior, cool overcast daylight, mixed practicals at dusk. Multiple unattributed light sources are the single most common reason an image feels synthetic.
Material and micro-texture
Skin has pores, uneven tone, and tiny imperfections. Fabric has weave, stretch, and wear. Metal has smudges; glass has dust. Ask for these details directly: visible skin texture, natural pores, slight fabric creases, worn edges on the table. Over-smoothing is what produces the infamous plastic look, and it is easier to prevent than to repair.
Environmental story and depth
Depth comes from overlapping planes, atmospheric haze, and objects that imply use — a half-empty cup, a scuffed chair, a jacket on the back of a door. These small narrative details make a scene feel photographed rather than assembled.
Prompt Architecture: Camera Notes Instead of Adjective Stacks
Strong prompts resemble a shot note written by a director of photography. They move from subject to context to optics to light to texture, and they end with constraints.
A reliable order:
- Subject and identity details — age range, build, wardrobe, expression.
- Action and pose — what the body is doing, where the weight sits.
- Environment — location, time of day, weather, foreground and background elements.
- Camera — framing, focal length, aperture, angle, distance.
- Light — source, direction, quality, color temperature, bounce.
- Material and texture — skin, fabric, surfaces, wear and dust.
- Constraints — what to avoid and what to keep clean.
Replace mood adjectives with physical description
Words like cinematic, beautiful, and stunning carry almost no information. Instead of cinematic lighting, write: single window light from camera left, soft falloff across the face, warm bounce from a wooden floor. Instead of realistic skin, write: visible pores, slight redness on cheeks, fine lines around the eyes, no smoothing.
Keep one variable per iteration
When a generation is close but not right, change exactly one element: focal length, or light direction, or wardrobe. Change three at once and you lose the ability to reproduce the result. Log the prompt fragments that worked in a personal library — a light recipe, a lens recipe, a skin recipe — and recombine them. After a few weeks you are not prompting anymore, you are assembling.
Use negative constraints sparingly but deliberately
Constraint lists help most with recurring artifacts: no extra fingers, no text, no watermark, no heavy sharpening, no plastic skin. Keep the list short. Very long negative lists tend to flatten the image, removing texture along with the problem.
The Image Workflow, Step by Step
1. Block out composition cheaply
Start with a low-detail pass to settle framing, subject placement, and visual hierarchy. Do not chase texture yet. Resolve the composition first; everything downstream depends on it.
2. Generate a controlled batch
Run several variations with a fixed seed or a fixed reference so the differences are meaningful. Evaluate at thumbnail size before zooming: if the image does not work small, it will not work large. Stop when one frame has the right light direction and the right silhouette.
3. Refine locally
Use inpainting and regional edits to fix hands, eyes, hairline, and edges. Work in small regions rather than reprocessing the whole frame, which helps preserve the texture you already earned.
4. Detail pass and upscaling
Upscale with a model that adds plausible detail rather than sharpening edges. A two-step approach works well: a moderate upscale, then a light detail pass focused on eyes, fabric, and surface grain. Watch for halos around high-contrast edges; if they appear, reduce the detail strength.
5. Grade and finish
Add a subtle grade, tiny amounts of grain, and selective depth-of-field if the background reads too clean. Real footage is imperfect in specific, learnable ways — a slight highlight roll-off, a little noise in shadows. Those are the finishing touches that push an image from generated to photographed.
Moving From Stills to Video Without Losing Believability
Video raises the difficulty because the viewer now judges consistency over time. Three decisions matter most: how you start the clip, how long it runs, and how the camera moves.
Image-to-video versus text-to-video
For anything with a specific character or product, start from a still you already approve. Image-to-video inherits the light, wardrobe, and identity of that frame, which removes most of the drift. Text-to-video is best for establishing shots, landscapes, and abstract transitions where identity continuity is irrelevant.
Keep clips short and motivated
Three to five seconds of clear, motivated action beats ten seconds of drifting motion. Give the subject a reason to move — turning to answer, stepping into frame, lifting a hand — and the motion reads as intentional rather than liquid.
Describe camera moves like a camera operator
Slow dolly in, handheld drift, crane down, rack focus from foreground to background. One move per clip. When two moves compete, the frame warps. If you need a complex move, shoot it as two clips and cut between them.
Repair flicker and warping early
Temporal artifacts — texture that crawls, edges that breathe, background details that melt — are cheapest to fix before you commit to an edit. If a clip flickers, shorten it, lower the motion strength, or anchor it to a keyframe. If a face warps, regenerate that clip rather than trying to hide it in the cut; warped motion is the fastest way to break the illusion.
Keeping Characters, Wardrobe, and Locations Consistent
Consistency is the defining craft problem of AI video, and it is solved with assets, not luck.
Build a reference sheet
Create one canonical image per character: neutral expression, even light, full wardrobe visible. Add detail crops for face, hands, and any defining accessory. These images become the anchor for every subsequent shot. Do the same for key locations: a wide view, a reverse angle, and a detail of a distinctive surface.
Lock what should not change
Use the same seed, reference image, or control input for every shot of a scene. Change only framing, camera movement, and pose. That constrains variation to the dimensions you actually want to vary.
Maintain a continuity list
Before generating a sequence, write the shot list with a continuity column: wardrobe state, time of day, props in hand, hair condition, weather. Check each generated clip against the list. Most continuity errors are not model failures; they are memory failures on the production side.
Stitch deliberately
When you assemble clips, cut on motion, match screen direction, and keep the light consistent across the cut. Two gorgeous clips that disagree about light direction will still look wrong together.
Common Failure Modes and Their Fixes
| Symptom | Likely cause | Fix |
|---|---|---|
| Plastic, waxy skin | Over-smoothing in prompt or upscale | Add texture language, reduce detail strength, avoid beauty retouch keywords |
| Melted hands or extra fingers | Small subject in frame | Reframe tighter, inpaint hands separately, add a hand reference |
| Crawling texture in video | Too much motion, too long a clip | Shorten to 3–4 seconds, lower motion, anchor to a keyframe |
| Face drifts between shots | No identity anchor | Use a reference sheet plus fixed seed, start clips from approved stills |
| Halos and crunchy edges | Aggressive sharpening | Reduce detail pass, add mild grain, check at 100 percent zoom |
| Background text is gibberish | Model-generated lettering | Add signage in post or reframe so text is out of focus |
| Shadows disagree | Multiple implied light sources | Specify one dominant source with direction and height |
Two habits prevent most of these: reviewing at delivery resolution rather than preview size, and treating every artifact as a stage problem instead of a prompt problem.
Post-Production: Where Generated Footage Becomes Professional
Generated media rarely ships straight from the model. A short finishing pass closes most of the remaining gap.
- Grade before you judge. A neutral starting point hides problems. Add contrast and a consistent color treatment, then evaluate.
- Match grain and noise. Uniform, clean footage looks synthetic next to real footage. A light grain layer unifies mixed sources.
- Control depth of field. Selective blur separates subject from background and hides minor background artifacts.
- Design sound. Room tone, footsteps, cloth movement, and a music bed do more for believability than another generation pass. Viewers forgive visual imperfection faster than silence.
- Cut on action. Motion hides micro-errors that a static hold exposes.
If your project mixes AI shots with real footage, match the real camera's characteristics first — its grain, its contrast curve, its lens breathing — and bring the generated material to it, not the reverse.
Quality Control, Rights, and Disclosure
Before delivery, run a short checklist:
- View every clip at final resolution and final aspect ratio.
- Check faces, hands, and text at 100 percent zoom.
- Watch the full sequence once with sound and once without.
- Confirm continuity of wardrobe, props, and time of day across cuts.
- Verify that any recognizable person, brand, or location is used with permission or replaced.
- Confirm your disclosure practice matches the platform and the client contract.
On rights: avoid prompts that name living artists or imitate a specific person's likeness without consent, keep documentation of your source references, and be transparent with clients about which shots are generated. Disclosure is increasingly expected for synthetic footage, and hidden generation is a reputational risk that outweighs any short-term gain.
FAQ
How many attempts does a usable photorealistic image take?
With a clear reference and a structured prompt, three to eight variations is typical. If you are past twenty attempts, the problem is almost always upstream — wrong light description, wrong framing, or a missing reference.
Do I need an expensive GPU to do this well?
Not necessarily. Cloud generation handles most of the compute load. A mid-range machine is enough for editing, if you plan for large file sizes and use proxies during editing.
Can AI video pass as real footage?
In short clips with clear camera motivation and good sound design, often yes. In long takes with complex human motion, weaknesses show. The reliable approach is to cut faster, keep shots short, and use motion to cover imperfection.
What is the biggest beginner mistake?
Chasing style words instead of describing physical conditions. Lighting direction, lens choice, and material texture do more for realism than any list of mood adjectives.
How do I keep a character identical across a whole sequence?
Build a reference sheet, lock a seed or reference input, write a continuity list, and start every clip from an approved still rather than from a text prompt.
Should I upscale before or after editing?
Edit at a comfortable working resolution, then upscale the final selects. Upscaling everything first multiplies render time and storage for shots you may cut.
Is it better to fix a bad frame or regenerate it?
Regenerate when the problem is structural — wrong pose, wrong light, warped face. Repair when the problem is local and small — a stray object, a rough edge. Structural problems hide poorly in motion; local ones usually do not.
Photorealism with AI is not a single skill. It is a chain: reference, prompt structure, controlled iteration, motion discipline, continuity tracking, and finishing. Strengthen the weakest link rather than the loudest, and the output stops looking generated and starts looking shot.
