
Why a Single Still Image Is Now Enough to Start a Shot
For most of film history, motion had to be captured. You pointed a camera at something moving, or you animated it frame by frame. Generative video changed the starting point: today you can hand a system one photograph, a painting, a product render, or a character sheet, and get a moving shot back in under a minute.
That shift is not just a convenience. It changes how projects get planned. Storyboards can be shot tests. Concept art can become animatics. A client's product photo can become a five-second ad sequence without a shoot day. Character designs can be animated before a single rig exists.
The practical challenge is that "realistic" is doing a lot of work in that promise. A model can produce smooth motion that still looks wrong — faces warping, hands melting, walls breathing, lighting that shifts for no reason. Getting believable results is less about finding a magic tool and more about understanding what these systems are actually predicting, then feeding them the right inputs.
This guide walks through the full workflow: how image-to-video works, how to pick a model for a specific shot, how to write prompts that describe motion instead of scenery, how to keep characters consistent across multiple clips, and how to troubleshoot the failures you will hit most often.
What Image-to-Video Actually Does Under the Hood
Diffusion, latent motion, and the first frame
Most current video models are diffusion systems trained on huge collections of video clips. During training, they learn two things at once: what a plausible frame looks like, and how pixels tend to move between frames. At generation time you give them a starting image plus a text prompt, and they iteratively denoise a sequence of latent representations into a short clip.
The critical consequence: your input image is not a reference — it is the first frame of the output. The model inherits its composition, color palette, lighting direction, and subject identity. Everything downstream is extrapolation.
That means image quality has an outsized effect on output quality. A soft, low-resolution, heavily compressed source will produce a clip with soft, unstable detail, because the model is trying to invent texture that was never in the input. A clean, high-resolution, well-lit source gives the model far more to work with.
Why the first frame matters more than your prompt
New users typically over-invest in prompt wording and under-invest in the source image. In practice, a mediocre prompt on a great frame beats a great prompt on a mediocre frame almost every time.
Before generating anything, audit your source image against four questions:
- Is the subject clearly separated from the background? Ambiguous edges confuse motion prediction, especially around hair, fur, and translucent materials.
- Is the lighting single-source and consistent? Mixed lighting makes the model guess which direction shadows should travel as the camera moves.
- Is there enough resolution? Match or exceed the model's native output height where possible.
- Is the pose readable? Extreme foreshortening or heavy occlusion gives the model very little to extrapolate from.
If the answer to two or more of these is no, spend five minutes in an editor first. Cropping, upscaling, and light color correction are the cheapest quality upgrades available.
Choosing the Right Model for the Shot
There is no single best image-to-video system, because different models are optimized for different kinds of motion. It helps to sort them into rough families.
Stylized and expressive motion models
Some models excel at exaggerated, character-driven movement: a dancer spinning, hair whipping in wind, cartoon physics, anime-style action. They tend to produce more energetic motion and tolerate stylized input images well. They are the right choice for illustration, mascot animation, and social-first content where personality matters more than physical accuracy.
Cinematic realism models
Others prioritize physics and camera behavior: slow dolly moves, subtle parallax, natural fabric and hair motion, believable depth of field. These are better for product shots, portrait work, architectural visualization, and anything intended to pass as live-action footage. They often move less dramatically per second, which is exactly the point.
When to chain two models in one pipeline
A useful pattern is to split responsibilities. Generate the primary performance with a model that handles character motion well, then run the result through a second pass focused on upscaling, frame interpolation, or detail restoration. Alternatively, generate a slow camera move with a realism-focused model, then cut to a stylized model for a beat of action.
The mistake to avoid is asking one model to do everything. If a shot needs both subtle realism and explosive movement, plan it as two shots.
A Practical Workflow: From One Photo to a Ten-Second Shot
Step 1 — Prepare the source frame
Start with the largest, cleanest version of the image you have. Upscale if needed, but avoid aggressive sharpening, which creates halos the model will animate as shimmering edges. If you need a wider frame than your source provides, extend the canvas with a generative fill tool rather than letting the video model invent the edges.
Also decide on aspect ratio now. Vertical for short-form, horizontal for narrative and product work, square for feeds. Cropping after generation wastes the effort.
Step 2 — Write a motion prompt, not a scene prompt
The most common prompting error is describing what is already visible. The model can see the image. What it cannot see is how you want things to move.
Compare:
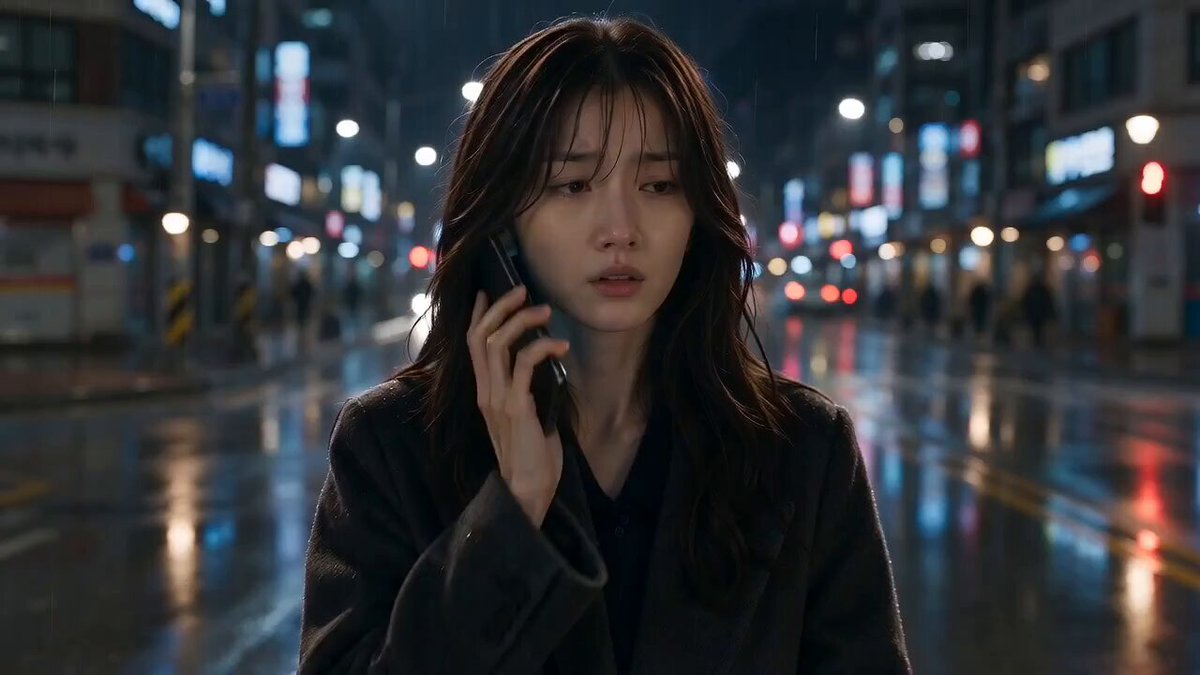
- Weak: "A woman in a red coat standing on a rainy street, cinematic, 4k."
- Strong: "She turns her head slowly toward the camera, coat fabric shifting, rain falling steadily, camera pushes in gently."
The second version gives the model verbs and a camera instruction. It also implies a speed — "slowly," "steadily," "gently" — which is often more important than the subject itself.
Step 3 — Set duration, camera move, and motion strength
Short clips hide flaws. Three to five seconds is usually where realism peaks; beyond eight seconds, drift and identity decay become visible. If you need a longer sequence, generate multiple short clips and cut them together.
Keep camera language simple. One move per clip. "Slow push in" or "gentle left pan" reads as intentional. "Push in while orbiting and tilting" reads as chaos, because the model averages conflicting instructions into a smear.
Motion strength is the dial people forget. High strength gives you drama and artifacts. Low strength gives you stability and a nearly still image. When a shot looks like a photograph someone is gently breathing on, lower it further; when it looks frozen, raise it in small increments.
Step 4 — Generate variations before committing
Run the same prompt and settings several times and pick the best take. Generative output is stochastic; two runs can differ wildly in how hands, eyes, and edges resolve. Reviewing four options for thirty seconds each is faster than engineering the perfect prompt.
Keep notes on which seed or setting produced your winner. If you need a matching shot later, reproducing settings gets you closer than rewriting the prompt from scratch.
Step 5 — Finish in post
Generated clips rarely ship untouched. A standard finishing pass includes:
- Trimming the first and last few frames, where artifacts concentrate.
- Frame interpolation to reach a smooth frame rate if the model outputs something lower.
- Light stabilization on handheld-style shots.
- Color grading to unify multiple clips shot with different models.
- Subtle grain or texture, which does an enormous amount of work in making synthetic motion feel photographic.
Camera Language That Reads as "Realistic"
Realism in moving images is largely a matter of matching what audiences expect from physical cameras. These conventions are worth internalizing:
- Parallax beats motion. When foreground and background move at different rates, the brain reads depth. Static subjects with camera movement often feel more real than moving subjects with a locked camera.
- Slow is credible. Fast moves reveal how little the model knows about occluded geometry. Reserve quick movement for cuts, not continuous takes.
- Weight implies physics. Fabric should lag. Hair should trail. Liquids should slosh. Prompt these behaviors explicitly.
- Locked-off shots are underrated. If the subject performs well, a static camera with strong environmental motion — rain, smoke, drifting light — can be the most convincing option.
- Depth of field does a lot. Shallow focus lets the model hide detail it cannot resolve, and audiences read it as cinematic by default.
A reliable recipe for a first attempt: one subject action, one environmental motion, one slow camera move, five seconds.
Keeping Characters and Objects Consistent Across Shots
Single clips are easy. Sequences are where projects fall apart, because each generation is independent and small identity differences compound.
Build a reference set. Collect five to ten images of the same character from different angles, in consistent lighting. Some workflows accept multiple reference images and blend identity features from all of them. Even one extra reference measurably improves stability.
Anchor on distinctive features. Prompts that mention a specific scar, hairstyle, jacket color, or accessory give the model something concrete to hold onto. Generic descriptions drift toward the average face in the training data.
Reuse the first clip as a reference. Once you have a take you like, use a frame from it as the starting image for the next shot rather than going back to the original still. Chaining frames preserves continuity naturally.
Accept controlled imperfection. Cutting between two slightly different angles reads as normal filmmaking. Cutting between two different faces does not. Design shot lists so that a cut lands where variation is least noticeable — between angles, not within one.
Keep a continuity sheet. Subject description, wardrobe, lighting direction, lens feel, and color palette. Paste it into every prompt. It sounds bureaucratic until you are eleven clips deep and cannot remember which version of the jacket is correct.
Common Failure Modes and How to Fix Them
Melting faces and hands. Usually caused by motion strength that is too high or a source frame where the face is small and low-contrast. Crop closer to the subject, lower motion strength, and add explicit instructions like "head stays still, only eyes and mouth move."
Morphing backgrounds. The model has less information about the background than the foreground, so it invents. Reduce camera movement, mention key background elements in the prompt, or add a subtle depth-of-field so soft background detail is expected.
Flickering textures. Often a symptom of an over-sharpened source image or fine repetitive patterns like brickwork and fabric weave. Soften the source slightly and add motion blur language to the prompt.
Frozen output. Motion strength too low, or the prompt describes states rather than actions. Replace adjectives with verbs: not "windy street," but "leaves blow across the pavement."
Identity drift across a clip. Keep clips short. If you need a long take, generate overlapping segments and cut on action so the audience's attention is on the movement rather than the face.
Everything looks like a slow zoom. Your model is defaulting to its most common camera behavior. Specify a different move — pan, tilt, static — or add a subject action that forces the model out of the default.
Hallucinated objects. Extra fingers, floating props, duplicated architecture. Reduce prompt complexity. Models handle one or two subjects far better than five.
Prompt Patterns You Can Reuse
These templates are starting points. Swap in your own subject and setting, and keep the verbs specific.
Portrait, subtle realism:
"[Subject] blinks and shifts weight slightly, eyes tracking toward the camera, soft window light, dust particles drifting, camera holds static, shallow depth of field."
Product hero shot:
"Slow dolly-in on [product], light sweeping across the surface, reflections moving on glass, background gently blurred, no camera shake."
Environment establishing shot:
"Camera pans slowly right across [landscape], clouds moving, grass bending in the wind, birds crossing the frame in the distance."
Character action beat:
"[Character] raises an arm and takes one step forward, jacket fabric following the motion, hair moving with the turn, camera tracks left at a walking pace."
Stylized animation:
"[Character] dashes across the frame with exaggerated speed lines, cape trailing behind, background blurring with motion, quick camera whip to follow."
Notice that every example names one primary action, one secondary environmental detail, and one camera behavior. That three-part structure is a dependable baseline whether you are working with Pika-style motion models, cinematic systems in the Veo family, or newer entries in the space.
Quality Control Checklist Before You Publish
Run every clip through the same review before it leaves your timeline:
- Watch it at full speed, then frame by frame. Look for warping at the edges of the frame where artifacts hide.
- Check the eyes and hands specifically. These are where audiences look first and where models fail most.
- Mute the audio and confirm the motion reads on its own.
- Watch it on a phone. Small screens forgive a lot and reveal pacing problems immediately.
- Confirm all clips in a sequence share color, grain, and motion character.
- Verify aspect ratio and safe margins for each destination platform.
If a clip fails two or more of these, regenerate rather than repair. Fixing a fundamentally unstable clip in post costs more time than a fresh generation.
FAQ
How long does a typical clip take to generate?
Anywhere from under a minute to several minutes depending on resolution, duration, and the system you are using. Longer and higher-resolution outputs scale up quickly.
Do I need a powerful computer?
Usually not. Most image-to-video work happens in a browser. Local setups exist for specialized pipelines and give more control, but they require a capable GPU.
Can I animate text or logos?
Simple, high-contrast marks can work if you keep motion minimal. Complex typography tends to distort. Render text in an editor afterward and composite it over the generated footage.
What resolution should my source image be?
At least as tall as the video resolution you plan to export, and ideally larger so you can crop. Avoid upscaling artifacts by starting from the original file rather than a screenshot.
Why does the same prompt give different results?
Generation is probabilistic, and some systems introduce randomness deliberately. Generate multiple takes; controlling the outcome entirely is not the goal, choosing the best outcome is.
Is an image or a text prompt more important?
The image sets composition, lighting, and identity. The prompt controls motion and camera. Both matter, but a weak image cannot be rescued by a strong prompt.
How do I get longer sequences?
Generate overlapping short clips and edit them together. Long single generations almost always degrade in the second half, and cutting between well-matched clips is standard practice in professional workflows.
Where to Focus Next
The transformation from still image to believable animation is now a craft rather than a novelty. The tools improve constantly, but the skills that decide whether a shot works are stable: prepare the source frame carefully, describe motion rather than scenery, keep camera moves simple, generate variations instead of chasing one perfect prompt, and finish in post.
Start with a single five-second shot from an image you already have. Prepare it properly, write a three-part prompt, generate four takes, and edit the best one. That one loop teaches more than any list of settings. Once you can reliably produce one convincing clip, sequences, characters, and full pieces follow naturally — and each new model release simply becomes another instrument rather than a new skill to learn from zero.
