
Why Image-to-Video Is the Fastest Route to Short-Form Video
Every short-form feed has the same appetite: something new, every day, in a format that fits a phone screen. That appetite creates a production problem. Filming original footage is slow, stock clips feel familiar, and fully text-to-video generation often drifts away from the specific look you had in mind. Image-to-video sits in the useful middle. You control the frame — the composition, the subject, the palette, the styling — and the model supplies motion, camera movement and atmosphere.
That division of labor matters more than raw novelty. When you start from a still you already approved, you are not gambling on whether the character's face will look right or whether the product will render with correct proportions. You are asking the model to do one job: make an approved frame move. That is a much smaller and much more reliable problem, and reliability is what turns occasional lucky outputs into a publishing schedule you can actually sustain.
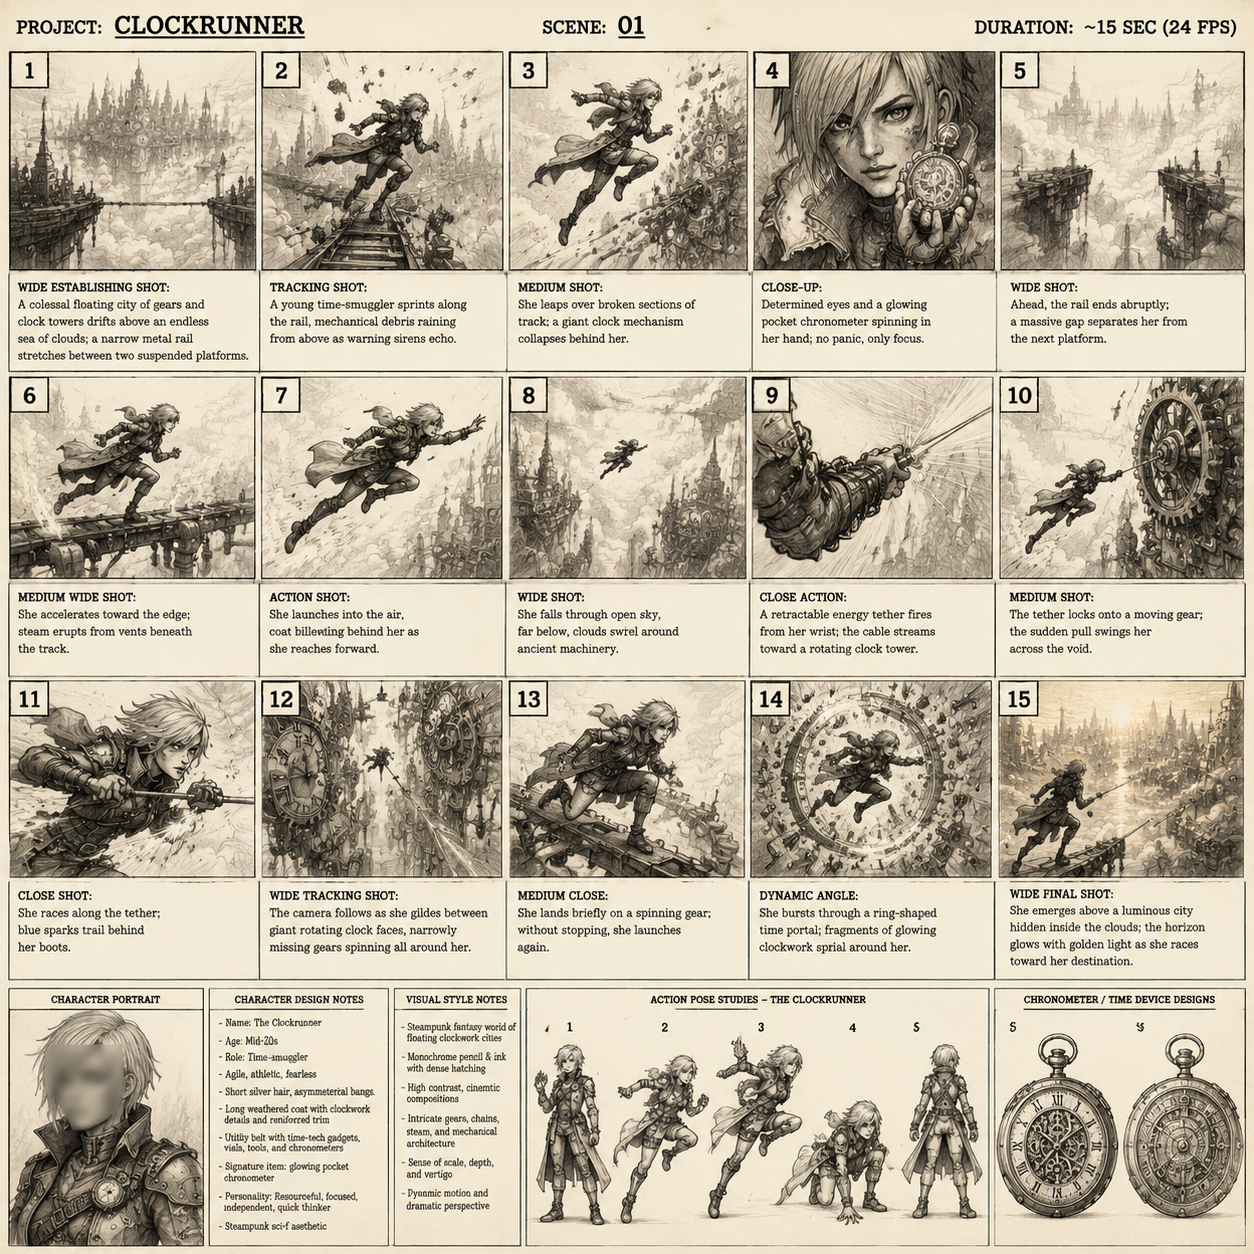
The format also fits the way people plan content. Most creators and small teams think in images first — a moodboard, a product shot, a thumbnail idea, a screenshot of a location. Image-to-video lets that existing visual thinking become the storyboard, so no work is wasted between the planning stage and the export stage.
Where image-to-video shines:
- Product and object shots that need a subtle parallax or light sweep
- Character or portrait stills that need a blink, a turn, or drifting hair
- Landscape and architectural frames that benefit from slow camera push-ins
- Illustrated or stylized artwork that needs a looping ambient motion
- Archived photography that would otherwise never appear on a modern feed
Where it struggles: complex multi-person interaction, readable text inside the frame, hands doing precise work, and fast physical actions where the model must invent contact between objects. Knowing those boundaries in advance saves hours of wasted generations.
What Image-to-Video AI Actually Does
It helps to understand the pipeline at a conceptual level, because most disappointing results are caused by asking the model to solve a problem it was never designed to solve.
Motion inference, not just frame interpolation
Frame interpolation takes two existing frames and invents the frames in between. It cannot create motion that was never there. Image-to-video generation is different: given a single still, the model infers a plausible future for that scene. It estimates depth, guesses which surfaces are foreground and background, decides where light falls, and then synthesizes a sequence of frames that is consistent with the original image.
That inference is why camera movement works so well. A slow dolly across a landscape is essentially a re-projection of an inferred depth map, and depth is something modern models estimate reliably. It is also why articulated motion is harder: a hand closing around a cup requires the model to invent an object relationship and physics that are not visible in a single frame.
Where the models succeed and where they fail
Strong performance: parallax camera moves, drifting particles (snow, dust, embers, pollen), water and smoke, hair and fabric in wind, subtle subject breathing, light flicker and neon pulsing, slow rotations of isolated objects.
Weak performance: reading and holding text, precise hand-object contact, rapid direction changes, crowds where each figure needs consistent anatomy, and anything where the original still is ambiguous about what is in front of what.
A useful rule: if a human viewer could not tell from the still which part is closer to the camera, the model probably cannot either. Fix the ambiguity in the image, not in the prompt.
Preparing Source Images That Animate Cleanly
Source preparation is the highest-leverage step in the entire workflow. A ten-minute cleanup often saves an hour of retries.
Composition and negative space
Models need room to move. If your subject fills every pixel, the only possible motion is a jitter in place. Leave breathing space around the subject — typically 15 to 25 percent of the frame — so a push-in, tilt or parallax has somewhere to travel. Leading lines and clear layers (foreground, midground, background) give the depth estimator an easy job and produce noticeably cleaner movement.
Aspect ratio and resolution
Vertical 9:16 is the default for reels-style feeds, but generating in that ratio from the start is better than cropping later. Cropping a horizontal animation removes the edges where motion blur and parallax are most visible, and it can cut off the moving elements you paid for. Generate at the target ratio, or at least at a ratio that crops down cleanly without losing your subject.
On resolution: extremely large images do not automatically produce better animation. Many models downsample internally, so a clean 1080-pixel-wide image with sharp edges often outperforms a noisy 4K file. If you must use a large source, upscale carefully and denoise first.
Five image mistakes that ruin motion
- Motion blur baked in. A still that is already blurred confuses the model about direction and speed.
- Heavy film grain or compression artifacts. The model animates the noise, and the result crawls.
- Ambiguous depth. Flat lighting with no shadows removes the cues the model needs.
- Text in frame. Letters warp, smear and flicker. Add captions in the edit instead.
- Tiny, distant subjects. Small faces become unstable because the model has too few pixels to hold identity.
Writing Motion Prompts That Behave
A motion prompt is not a description of the image — the model already sees the image. It is a description of what should change between the first frame and the last.
Camera language
Use the vocabulary of a camera crew, because that is roughly how these models were trained to interpret movement:
- Slow dolly in, slow dolly out, push in, pull back
- Pan left, pan right, tilt up, tilt down
- Orbit, arc shot, crane up, handheld drift
- Static camera with subject motion only
One movement per generation. "Slow dolly in while orbiting left and tilting up" produces mush. If you need a compound move, generate two clips and join them in the edit.
Subject motion and physics
Name the specific element that should move and how: "steam rises slowly from the cup," "fabric ripples in a light breeze," "hair drifts to the right," "rain streaks fall across the frame." Specificity beats intensity. "Dramatic explosion of motion" rarely produces anything usable, while "embers drift upward at a slow, steady rate" produces something you can actually cut into a sequence.
Duration and loop logic
Short clips — three to six seconds — are the sweet spot for most short-form work, because they are long enough to establish motion and short enough that drift never becomes obvious. If you plan to loop, ask for motion that begins and ends in a similar state: a slow push that settles, or a drift that returns near its starting position. Loops feel seamless when the last frame visually rhymes with the first.
A Repeatable Production Workflow
The goal is not a single great clip. The goal is a system that produces a great clip every time you sit down. Here is a five-stage version that holds up under weekly deadlines.
Stage 1: Design the hook before you generate anything
The first three seconds decide whether the rest of the video is seen at all. Write the hook as a sentence before you touch an image: "A frozen lake cracks in slow motion," "A perfume bottle rotates as gold light sweeps across it," "A city street empties until one figure remains." Then choose a still that can deliver that sentence in one shot.
When you plan the hook first, you also plan the payoff. A hook that creates a small question — what is behind that door, what is inside that box — gives the rest of the video a reason to exist beyond decoration.
Stage 2: Create or select the still
You have three sources: original photography, generated images, or archival material you have the rights to use. Whatever the source, run the same checklist: clear depth layers, negative space around the subject, no baked-in blur, no critical text, and a crop that already matches your target ratio.
Generate three to five candidate stills rather than one. Variety at this stage is cheap; variety at the animation stage is expensive because each animation pass takes time.
Stage 3: Run the animation pass with variants
Generate two or three variants per still with slightly different motion prompts. Do not micro-tune one clip twenty times. Small prompt variations explore the space faster, and you will usually find that one direction is clearly stronger.
Keep a naming convention from the beginning: project-shot-variant. When you have thirty files open, filenames are the only thing preventing chaos.
Stage 4: Assemble, caption, publish
Cut on motion. A clip should enter while something is already moving and leave before the motion resolves completely — that clipped feeling keeps attention and hides the moments where AI motion gets slightly soft.
Build a simple project structure: hook clip, one or two development clips, payoff clip, end card. Add captions, then a music bed, then export.
Stage 5: Review against a checklist, not a feeling
Before publishing, check: Is the hook visible in the first second? Is any text legible? Does the audio start immediately? Is the crop safe on a phone? Does the loop or ending feel intentional? A five-item checklist catches more mistakes than any amount of re-watching.
Choosing the Right Model for the Job
Different image-to-video models are tuned to different priorities, and choosing well matters more than choosing "best."
Quality-first cinematic options
These produce the most convincing physics, the richest lighting and the most stable identity across the clip. They are slower and more expensive per second. Use them for hero shots: the hook, a product reveal, a paid ad, a portfolio piece. Do not use them to test whether an idea works.
Speed-first options
Fast models are ideal for exploration. When you are deciding between three concepts, generate all three at low fidelity, pick the winner, then re-render the winner at higher quality. This two-pass approach consistently beats trying to perfect a single generation blindly.
Specialist looks
Some models are tuned toward a particular aesthetic — anime motion, hyper-real product renders, painterly 2D animation, subtle documentary-style drift. If your channel has a strong visual identity, matching the model to that identity reduces the amount of editing you need to do afterward, and consistency is a big part of why audiences follow a feed.
A practical decision rule: match the model to the shot's importance, not to the project's importance. A brilliant ad can be built from mostly cheap clips with one or two expensive ones carrying the emotional weight.
Editing, Sound and Captions That Hold Attention
Generated motion is only half of a reel. The other half is rhythm.
Sound design carries more weight than most creators expect. A soft whoosh on a camera push, a low impact on a cut, a subtle ambience under a landscape — these make synthetic motion feel grounded. Add a music track with a clear beat and cut your clips to that beat. Where the beat and the cut align, the video feels intentional even when the underlying motion is simple.
Captions are non-negotiable. Most viewers watch with sound off at least part of the time. Burn in short, high-contrast captions, keep them inside the safe area, and avoid placing them over the part of the frame where the motion is most interesting.
Pace beats perfection. A slightly soft clip cut at the right moment reads better than a flawless clip held two seconds too long. When in doubt, trim.
Color consistency across clips is what makes a sequence feel like one video rather than a slideshow. Apply a light grade or a shared LUT across all generated clips so the palette stays unified.
Troubleshooting Common Failures
The subject melts or morphs. Usually caused by too much movement in the prompt or by a source image without clear anatomical boundaries. Reduce the requested motion, and sharpen the subject's separation from the background.
Everything wobbles. A flat, texture-heavy surface like a brick wall or a crowd can create global jitter. Add a subject with clear edges, or request a static camera with subject-only motion.
The clip drifts away from the source look. Long clips drift more than short ones. Keep the duration tight and avoid prompts that ask for scene changes or new elements entering the frame.
Faces flicker. Faces need more pixels and more stability. Crop closer to the face in the source, avoid fast head turns, and prefer slower camera movement.
The motion looks like a slideshow. You may be seeing interpolation rather than inference, or the prompt may be too vague. Name one concrete moving element and one camera behavior.
Output looks fine but performs badly. This is an editing problem, not a generation problem. The hook is too slow, the captions are unreadable, or the first frame is visually busy. Rework the opening, not the animation.
Scaling the System Without Burning Out
Volume is the easiest way to stall. A few habits keep output steady:
- Batch by stage. Prepare ten stills in one session, animate them in another, edit in a third. Context switching is the real cost.
- Build a prompt library. Save five motion recipes that reliably work for your style — a push-in, a parallax drift, an orbit, an atmospheric particle move, a static-camera breath.
- Reuse structures, not clips. A hook format that worked can support a new subject every week without feeling repetitive.
- Keep a swipe file. Screenshot reels that stop your scroll, then reverse-engineer the camera move and the cut rhythm.
- Set a stop rule. For example: three variants per still, two re-renders maximum, then move on. Without a stop rule, polishing eats the schedule.
FAQ
Do I need to film anything at all?
No. Many effective reels are built entirely from generated stills plus image-to-video animation, combined with sound design and captions.
How long should each clip be?
Three to six seconds is a reliable range. Longer clips drift and become harder to cut tightly.
Why does my animation look like a subtle zoom rather than real motion?
Your source image probably lacks depth cues. Add foreground, midground and background separation, and light the scene so shadows reveal volume.
Can I use the same still for multiple reels?
Yes, and you should. Different motion prompts, crops and captions can produce genuinely different-feeling videos from one source image.
What is the biggest beginner mistake?
Asking for too much motion. Restraint produces believable results; ambition produces melting.
Should I generate at the final aspect ratio?
Yes, whenever possible. Native generation in a vertical ratio avoids the loss of detail and motion that cropping causes.
How many variants should I generate?
Two or three per still, with meaningfully different prompts. That is enough to see which direction works without burning your whole session on one shot.
