
Why image-to-video changed the production pipeline
Static artwork used to be the finish line. Now it is a seed. Image-to-video (I2V) takes a finished still — a character portrait, a product render, a concept keyframe — and animates it, preserving composition and identity while adding motion, camera drift, and atmosphere. That single capability reorders the entire production pipeline: art direction happens first, motion happens second.
This matters because teams that storyboard with stills keep more control than teams that start from a text prompt. A text prompt leaves the model free to invent a face. A keyframe constrains it. When you hand the model a locked image, you are effectively saying "everything about this frame is approved — now move it."
The economic effect is straightforward. Iterating on a still is fast and cheap; iterating on a rendered sequence is slow and expensive. By pushing the expensive approval step earlier, I2V collapses the number of motion passes needed to reach a final cut. But it also introduces a new failure mode that did not exist in the still-image era: a character that looks perfect in shot one and slowly becomes someone else by shot nine.
That is the real technical story behind modern AI video. Motion is largely solved for short bursts. Identity across time is not.
How image-to-video generation actually works
Diffusion, latent space, and motion priors
Most current I2V systems are built on diffusion models operating in a compressed latent space rather than raw pixels. The pipeline typically works in three stages. First, an encoder maps your reference still into latent features that describe structure, color, and texture. Second, a denoising network generates a sequence of latent frames conditioned on those features. Third, a decoder converts the latents back into viewable frames.
Motion comes from a temporal component — often an attention layer or a dedicated motion module that lets each frame look at its neighbors. This is what prevents the output from looking like a slideshow of unrelated images. The model learns typical motion priors from video data: how fabric folds, how hair lags behind a turn, how light shifts when a subject moves through a scene.
Why temporal consistency is the hard problem
If each frame were denoised independently, you would get flicker: tiny random variations in every frame that read as noise to the human eye. Temporal attention solves the obvious flicker, but it does not guarantee semantic stability. The model can produce a perfectly smooth sequence in which the character's nose slowly lengthens, a jacket pattern migrates across a shoulder, or an earring moves from one ear to the other.
This is why prompt engineering alone rarely fixes consistency problems. The model is not confused about what you asked for — it is making locally reasonable decisions that accumulate into globally wrong results.
Detail drift: the symptom to watch for
The failure has a name worth using in production notes: detail drift. It shows up as:
- Facial geometry shifting subtly across a shot.
- Fabric patterns stretching or repeating incorrectly.
- Accessories (glasses, jewelry, badges) changing shape or disappearing.
- Skin tone or hair color warming or cooling across cuts.
- Background elements — signage, furniture — rearranging between shots.
Once you can name it, you can test for it. A quick side-by-side of frame one and the last frame of every shot will expose drift faster than watching the sequence in real time.
Building a character reference kit
What a good reference set contains
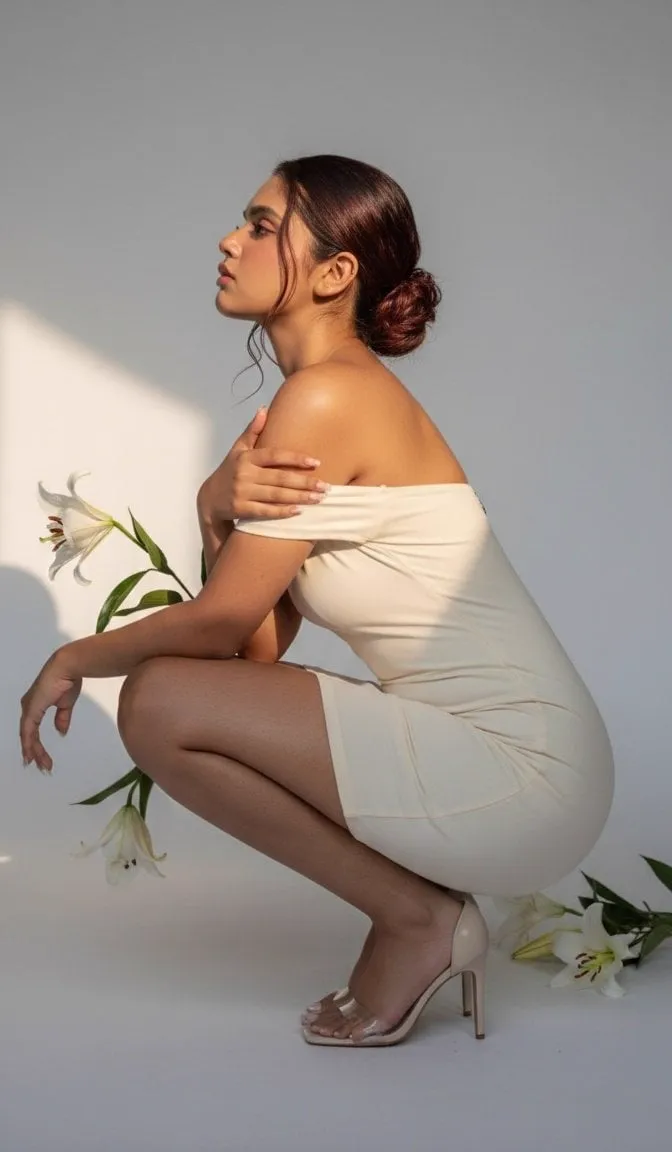
Consistency starts before generation. A character reference kit is the asset library every shot draws from. A solid kit includes:
- A neutral front-facing portrait in even light.
- Two three-quarter views, one from each side.
- A profile view.
- A tight close-up focused on eyes and facial structure.
- A full-body shot showing proportions and default wardrobe.
- Two or three wardrobe or expression variations.
- Optional: a shot in warm light and one in cool light to test color stability.
Keep resolution, aspect ratio, and crop conventions consistent across the kit. Mixed crops confuse identity conditioning more than people expect.
Locking identity with prompts, embeddings, and control signals
There are four practical levers for holding a character steady:
Reused text descriptors. Write one short identity block — age range, build, hair, distinguishing features, wardrobe — and paste it verbatim into every prompt. Do not paraphrase it between shots. Models respond to wording changes as if they were content changes.
Reference image conditioning. Modern pipelines let you attach one or more stills as identity references alongside the keyframe. Attaching the same two or three images across a whole sequence is more effective than attaching a different one per shot.
Trained adapters. If a character appears in dozens of shots, training a small adapter on the reference kit pays for itself. It bakes identity into the model rather than relying on prompt adherence.
Structural control. Depth maps, pose skeletons, and edge maps constrain composition without dictating appearance. They are the cleanest way to keep a performance consistent while the model handles texture and light.
A practical end-to-end workflow
Step 1: Lock the storyboard before generating anything
Storyboard as stills, not as prose. Each shot gets one approved keyframe. If you cannot draw a shot clearly as a still, the model will not invent it for you.
Step 2: Generate the anchor shot first
The anchor is the shot with the clearest, most frontal view of the character. Generate it at higher effort settings and review it frame by frame. Everything downstream inherits its look, so spend your time here.
Step 3: Extend shot by shot, reusing the last clean frame
Rather than starting each shot from scratch, many teams use the final frame of the previous shot as the starting image for the next. This chains continuity naturally. When a hard cut is required, fall back to a keyframe from the reference kit.
Step 4: Keep camera language consistent
Write down your camera rules — lens feel, movement speed, handheld amount — and repeat them in prompts. A shot that suddenly switches from locked-off to sweeping handheld reads as a continuity error even when the character is flawless.
Step 5: Review, repair, and re-render only what broke
Review at 25% speed with a frame counter visible. When a shot drifts, regenerate that shot alone using the last good frame as input. Avoid re-rendering the whole sequence; each pass introduces new variance.
Prompt patterns that hold a character together
A stable prompt is structured, not poetic. A workable template:
[IDENTITY BLOCK] — repeated verbatim every time
subject, age range, build, hair, eyes, wardrobe, signature detail

[SHOT BLOCK]
shot size, camera angle, lens feel, movement, duration intent

[ENVIRONMENT BLOCK]
location, time of day, weather, background elements that must stay fixed

[LIGHT BLOCK]
key direction, color temperature, contrast, practical sources

[STYLE BLOCK]
render style, film grain, color grade
Keep the identity block under about 40 words. Long character descriptions dilute each other. Put emphasis on the two or three features that viewers will actually notice — a scar, a specific jacket, a hairstyle — rather than describing every attribute.
Also avoid negative instructions that fight your reference image. If the kit shows a character with long hair, adding "short hair" to a negative prompt creates a tug-of-war inside the model.
Multi-shot continuity: wardrobe, lighting, and props
Identity is only half of continuity. The other half is everything around the character.
Wardrobe. Decide which garments are locked and which can change. Locked items should be described identically in every prompt and visible in at least one reference image. If a jacket changes color between shots, no amount of face consistency will save the sequence.
Lighting. Shoot your whole sequence under one lighting concept unless the story demands a change. Lighting is the fastest way to make two shots of the same character look like two different productions.
Props. Track every object that matters — a phone, a badge, a cup. Props are usually generated per shot, so they drift more than faces. Where a prop is critical, composite it in post rather than asking the model for it.
Backgrounds. For recurring locations, generate a clean plate once and reuse it. Reusing a background image is far more reliable than describing the same room in text repeatedly.
Choosing tools and models: evaluation criteria
There is no single best engine. There is a best engine for a given shot type, and most serious teams route between two or three.
| Criterion | What to test |
|---|---|
| Identity retention | How far into a clip does the face still match the reference? |
| Motion realism | Does fast movement produce warping or ghosting? |
| Prompt adherence | Does it honor camera direction, or ignore it? |
| Control inputs | Does it accept depth, pose, or edge conditioning? |
| Duration per pass | How many seconds per generation, and how stable at the tail? |
| Determinism | Can you reproduce a result with the same seed? |
| Resolution | Native output versus upscaled output |
| Iteration speed | Time from prompt to viewable preview |
Test each candidate on the same three shots: a slow dialogue beat, a fast action beat, and a shot with a recurring prop. The engine that wins on the dialogue beat often loses on the action beat — plan to mix.
Commit to one engine per sequence where possible. Switching engines mid-sequence is the single biggest cause of subtle style discontinuity.
Common mistakes and how to fix them
Paraphrasing the identity block. Fix: keep the identity text in a saved snippet and paste it, never retype it.
Using too many reference images. Fix: cap at three, chosen for distinct angles rather than volume.
Generating long clips in one pass. Fix: build in short increments and chain frames, then assemble in the edit.
Ignoring seeds. Fix: log the seed, model, and prompt for every approved shot. Reproducibility is a production requirement, not a luxury.
Fixing drift in post with face replacement. Fix: regenerate the shot. Post fixes cost more time and rarely match lighting.
Letting the model decide pacing. Fix: cut to a timing plan. AI clips tend to settle into a uniform rhythm that flattens a sequence.
Skipping audio. Fix: lock voice and sound early. Performance timing should follow dialogue, not the other way around.
Quality control checklist before delivery
Run this pass on every sequence before it leaves the edit:
- First and last frame of each shot compared side by side.
- Identity spot-check at three points per shot.
- Wardrobe and prop audit against the continuity sheet.
- Color temperature consistency across cuts.
- Motion cadence reviewed at full speed and at 25% speed.
- Face and hand review at 200% zoom.
- Audio sync verified on all dialogue beats.
- Every approved seed and prompt archived with the project files.
The last item is the one teams skip and later regret. A sequence you cannot reproduce is a sequence you cannot revise.
FAQ
How many reference images do I actually need?
Three is usually enough: a frontal portrait, a three-quarter view, and a full-body shot. Adding more images rarely improves identity and can introduce conflicting lighting cues the model tries to average.
Why does the character change after the third or fourth shot?
Small deviations compound. Each new shot is conditioned on the previous output rather than the original reference, so errors accumulate like a copy of a copy. Re-anchor periodically by feeding a keyframe from the original reference kit back into the chain.
Is image-to-video always better than text-to-video?
For character-driven work, almost always. Text-to-video is stronger for establishing shots, abstract sequences, and environments where no specific identity must persist.
How long should a single generated clip be?
Short enough that drift does not have time to develop, long enough to be useful in the edit. Most teams work in increments of a few seconds and assemble the performance in the timeline rather than asking for one long take.
Can I fix a drifting face in post-production?
You can, but it is usually slower than regenerating the shot. Post fixes also tend to fight the original lighting, which creates a visible seam even when the identity matches.
What single habit improves consistency the most?
Reusing exact text. Verbatim identity blocks, verbatim environment blocks, and identical reference images across every shot in a sequence do more for continuity than any parameter tweak.
