
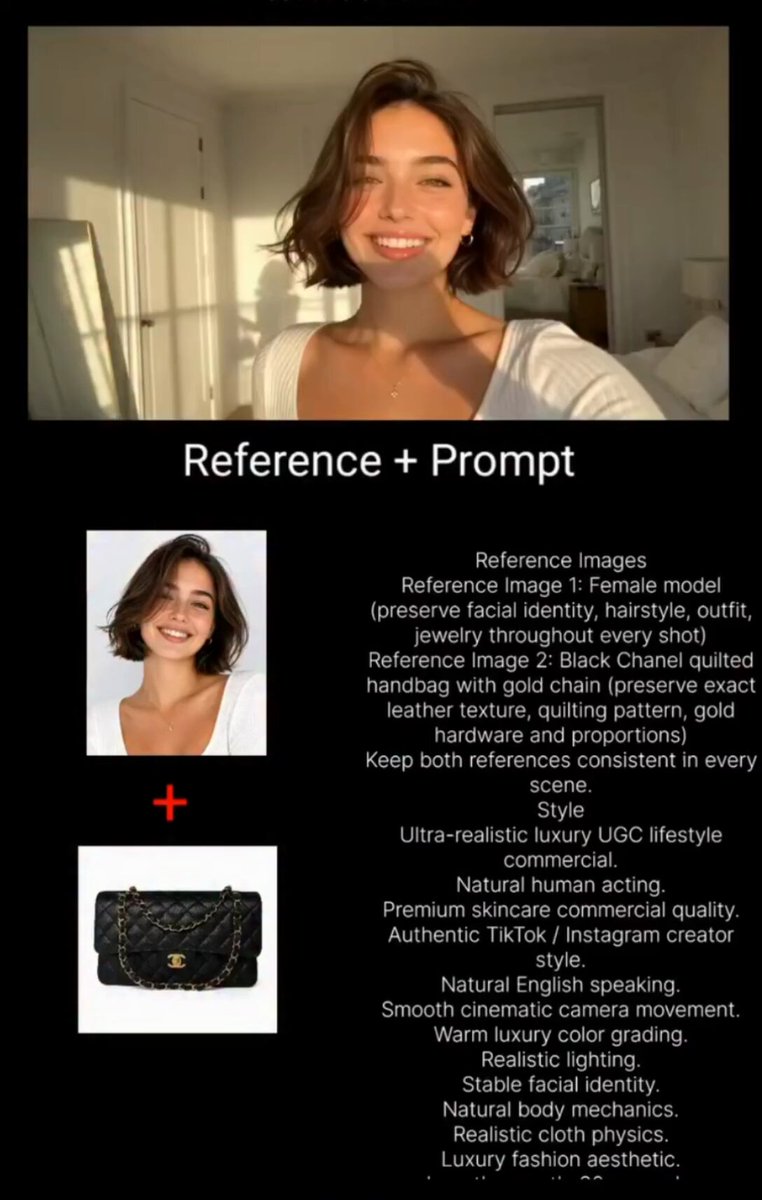
Why Static Images Still Leave Motion on the Table
Almost every creator has a folder of stills that feel like they should be moving: a portrait with wind in the hair, a product shot that deserves a slow push-in, a landscape that begs for drifting clouds. Image-to-video tools promise exactly that, and the first generation of results was impressive enough to be shared widely. The trouble starts on the second attempt. Motion appears where you did not want it, faces warp between frames, and a carefully chosen art style dissolves into flicker the moment the camera moves.
The root cause is not model quality alone. It is that most workflows treat a still image as a single flat object. When the model has no idea which parts of the frame are sky, skin, fabric, or glass, it guesses, and its guesses change from frame to frame. Block-pixel processing takes the opposite approach: it deliberately breaks the image into small, understandable units before any motion is generated. That single design decision explains why some image-to-video pipelines hold together beautifully while others shimmer apart.
This guide walks through the technique, the model choices that support it, and a repeatable workflow you can run on almost any source image. It is written for editors, motion designers, and marketers who care more about predictable output than about chasing the newest demo reel.
What Block-Pixel Processing Actually Does
Block-pixel processing is a decomposition strategy. Instead of feeding a full-resolution photograph into a video model and hoping the latent space understands it, you first reduce the image into a grid of small modular units — think of them as tiles or bricks that carry their own color, texture, and depth information. Each unit can then be animated, restyled, or held static independently.
The reason this matters is control. A flat image gives the model one global instruction: "make this move." A decomposed image gives it hundreds of local instructions: "keep this tile locked, slide that tile two pixels right, fade that tile's texture into a different material." Local instructions survive frame-to-frame; global ones drift.
Semantic Segmentation and Atomic Unit Creation
The first pass is segmentation. The pipeline classifies regions of the image — foreground subject, secondary subject, background plane, sky, reflective surfaces, text, and so on — and assigns each region a label. From there, each region is subdivided into atomic units small enough that the contents are visually homogeneous.
Unit size is the main dial here. Large units (roughly 32 to 64 pixels) preserve texture detail and are fast to process, but they blur the boundary between subject and background. Small units (8 to 16 pixels) give you razor-sharp edges and fine control over hair, foliage, and fabric, at the cost of more computation and more chances for visible seams. A common compromise is adaptive sizing: large units in flat areas like sky or walls, small units around edges and faces.
Good segmentation also produces a depth estimate, even a rough one. Depth lets you decide which layers are allowed to move independently — a subject can push forward while the background drifts backward, which sells parallax far more convincingly than uniform motion.
Latent Motion Vector Embedding
Once units exist, each one receives a motion vector: a direction, a magnitude, and a confidence value. These vectors live in latent space, not pixel space, which means they describe intent rather than exact displacement. A cloud layer might get vectors pointing right with low magnitude and high confidence; a handheld camera shake is better expressed as global noise with low confidence so the model can smooth it.
Because vectors are attached to units rather than to the frame, motion becomes composable. You can animate only the units labeled "hair" and leave everything else frozen for a subtle living-portrait effect. You can apply a looping vector field to water units while the rest of the shot stays still. You can also drive vectors from an external source — optical flow from a reference clip, a hand-drawn trajectory, or a simple sine wave — which is how you get stylized motion that does not look like generic AI drift.
Style Swapping Through Modular Components
Style transfer is where the modular structure pays off most. In a flat pipeline, applying a new style means re-rendering everything and hoping the identity of the subject survives. With discrete units, style becomes a material swap: you apply a painterly material to background units, a soft skin material to face units, and a metallic material to jewelry units, all within the same frame.
This is also how you avoid the classic failure mode where an art style eats the subject. If the style module is only bound to specific unit groups, the subject's silhouette and lighting remain anchored to the original photograph. The result reads as intentional art direction rather than a filter that happened to land on the whole image.
Choosing the Right Model for Image-to-Video Tasks
There is no single best model for every shot. The practical question is what kind of motion you need and how much consistency you can afford to lose.
- Short, subtle motion (1–3 seconds): fast image-to-video models with strong single-frame conditioning work well. Good for portraits, product hero shots, and looping backgrounds.
- Multi-second camera moves: look for models that accept a camera path or trajectory input. Without explicit camera control, long moves tend to introduce parallax errors.
- Multi-reference consistency: if your shot must match a character or product across several clips, choose a model that accepts multiple reference images and locks identity in latent space.
- Stylized output: models with an explicit style or reference-image conditioning channel keep the art direction stable across frames far better than prompt-only styling.
- Local or self-hosted: worth the setup when you need repeatable seeds, batch rendering, or privacy on unreleased assets.
A useful rule: pick the slowest model you can tolerate for your hero shots and the fastest one for exploratory drafts. Spending an hour on a shot that ends up cut is more expensive than spending two minutes previewing it at lower resolution.
A Practical Workflow: From One Photo to a Moving Shot
The workflow below works with most modern image-to-video pipelines. Steps 3 and 4 are where block-pixel decomposition does the heavy lifting; skip them and you are back to gambling.
Step 1: Prepare the Source Image
Start with the highest resolution you have. Upscale before generation, not after — models respond better to detail than to interpolation. Remove compression artifacts, straighten horizons, and crop to your target aspect ratio. If the shot needs a vertical version, crop and prepare it separately rather than letting the pipeline reframe for you.
Clean the edges of your subject with a quick mask. Even a rough mask is a strong signal for the segmentation pass, and it prevents the background from bleeding into hair or fur.
Step 2: Segment and Build the Block Map
Run segmentation and inspect the labels before you generate anything. Most tools let you correct mislabeled regions. Pay attention to three problem areas: semi-transparent objects (glass, smoke, water), thin structures (wires, grass, eyelashes), and anything with motion blur baked into the original photograph.
Set your unit size adaptively. If your tool only supports a global value, start at 16 pixels for portraits and 32 pixels for landscapes and interiors, then adjust.
Step 3: Define Motion Per Layer
Assign motion in layers, from back to front:
- Background plate: tiny global drift or none at all.
- Midground elements: slow parallax, direction consistent with your camera move.
- Subject: primary motion — a head turn, a blink, fabric sway.
- Foreground details: high-frequency motion such as hair, steam, or dust, with low magnitude and high confidence.
Keep total displacement small. A subject that moves 2 percent of frame width over three seconds reads as alive; one that moves 15 percent reads as a jump cut.
Step 4: Apply Style Modules
Bind style per unit group. A reliable starting recipe:
- Background: one style material, applied uniformly, with strong weight.
- Subject: light style weight, or none, if identity matters.
- Foreground accents: heavier style weight, since details are where texture reads.
If the style is meant to be the point — a fully animated look, for example — apply it globally but raise the segmentation quality first. Style amplification magnifies segmentation mistakes.
Step 5: Render in Passes
Render a low-resolution preview for motion timing, then a mid-resolution pass to check consistency, then the final. Between passes, change one variable at a time. If you adjust motion speed, seed, and style weight simultaneously, you will not know which change fixed or broke the shot.
Step 6: Finish and Repair
Almost every shot needs a repair pass. Common fixes: stabilize a jittery region, re-render a single frame range that flickered, or composite the original still back over the first frame so the shot opens on a perfectly clean image. Editing tools with frame-level repair make this far less painful than full re-renders.
Holding Temporal Consistency Across Frames
Temporal consistency is the difference between a shot that feels filmed and a shot that feels generated. Three levers matter most.
Anchor frames. Designate the first frame as an anchor and force the pipeline to match it exactly. If your tool supports multiple anchors, place one at the midpoint too, especially for shots longer than four seconds.
Identity locking. For characters, supply two or three reference images from different angles. This gives the model enough information to hold facial structure when the head rotates. Products benefit from the same treatment with packaging shots.
Motion budget. Total motion accumulates. A three-second clip can absorb a lot; a ten-second clip cannot absorb the same per-second rate without drifting. Either reduce per-second motion for long shots or break the shot into shorter segments and stitch them with a crossfade.
A quick diagnostic: scrub through the clip frame by frame. If a single frame looks wrong in isolation but the motion reads fine in playback, your problem is motion smoothness. If every frame looks fine but the clip feels wrong, your problem is timing or easing.
Style Transfer Fidelity Without the Flicker
Flicker is the signature failure of naive style transfer on video. It happens because the style is applied independently to each frame, and each frame's noise pattern differs slightly. Discretized application solves this by applying style at the unit level with a shared, temporally stable material definition.
Practical tactics:
- Freeze the style seed across the entire clip. Do not let the pipeline resample style noise per frame.
- Apply style to larger units first and refine downward. Coarse-to-fine application is more stable than the reverse.
- Separate style strength from style identity. Strength can vary over time for effect; identity should not.
- Avoid stacking multiple stylistic effects in a single pass. Composite them in an editor instead, where you can control blending per region.
If flicker persists in a specific area — usually high-detail regions like foliage or patterned fabric — reduce unit size there and increase the smoothing weight. High-frequency detail plus high-frequency style equals visible noise.
Scene Composition, Tagging, and Shot Planning
Before you render anything, tag your shots. A lightweight tagging convention saves enormous time once you have twenty clips to manage:
- Subject (person, product, animal, environment)
- Motion type (drift, push-in, pull-back, orbit, ambient)
- Style family (photoreal, painterly, graphic, stylized 3D)
- Aspect ratio and duration
- Anchor frames used
- Model and seed
With tags in place, you can regenerate a consistent set of shots by filtering on style family and subject, which is far faster than opening each project file. It also makes handoffs possible: a colleague can see at a glance which clips share a look and which are outliers.
Shot planning matters too. Image-to-video works best for establishing shots, product hero moments, character beats, and B-roll where motion is atmospheric rather than narrative. If a shot requires a specific performance — a hand picking up an object, a door opening — a still image is usually the wrong starting point. Generate motion you can plausibly infer from a frozen moment, and shoot or animate the rest traditionally.
Common Mistakes and How to Avoid Them
Over-motion. The most common error. Creators ask for dramatic movement because subtle movement is hard to see in a low-resolution preview. Render at final resolution before judging motion magnitude.
Skipping segmentation review. Automated labels are wrong more often than people expect, particularly on transparent and reflective surfaces. Two minutes of correction saves several renders.
Style applied globally. Global style is convenient and destructive. Bind it per unit group whenever identity matters.
Ignoring the first frame. If your clip starts on a generated approximation of the original still, viewers notice instantly in a cut. Composite the real still over frame one.
Rendering long clips in one pass. Break anything over six seconds into segments. Consistency degrades with length, and segmenting gives you repair points.
Chasing model novelty. A new model every week means no repeatable pipeline. Standardize on two: one fast for drafts, one high-fidelity for finals.
Troubleshooting Checklist
When a shot fails, work through the list in order rather than changing everything at once:
- Is the source image clean and high resolution?
- Are segmentation labels correct at edges and transparent regions?
- Is per-second motion within a reasonable budget?
- Is the style seed frozen across frames?
- Are anchor frames set at the start and midpoint?
- Is the model appropriate for the motion type?
- Does the clip hold up frame by frame, or only in playback?
Most failures trace back to steps 1 through 3. If the source is clean, the segmentation accurate, and the motion modest, the remaining variables are usually stylistic preference rather than defects.
FAQ
How long should an image-to-video clip be?
Two to four seconds covers most needs. Longer clips work if motion is ambient and slow, but consistency drops sharply past six seconds without segmentation-based control.
Do I need block-pixel decomposition for every shot?
No. Simple ambient motion on a clean image often works with a plain image-to-video pass. Use decomposition when identity, style stability, or layered motion matter.
What resolution should I generate at?
Match your delivery target. Rendering at 1080p and upscaling to 4K looks better than rendering at 720p and hoping the upscaler invents detail.
Can I use the same still for multiple shots?
Yes, and it is an efficient strategy. Vary the motion vectors and style modules while keeping the anchor frame identical, then cut between the variants.
Why does my subject's face change between frames?
Usually a lack of reference images or an over-aggressive style weight on the subject group. Add angle references and reduce subject style strength.
Is style transfer reversible?
Only if you keep the original unit map. Always archive the segmentation and motion data alongside the render so you can re-style without rebuilding from scratch.
How do I keep a consistent look across a whole project?
Lock the style family, unit-size policy, and seed strategy at the start. Consistency comes from fixed parameters, not from re-tuning each shot.
Where This Fits in a Real Production
Block-pixel decomposition is not a replacement for shooting footage or for traditional animation. It is a control layer that makes generative motion usable in professional work, where the goal is not a single impressive clip but twenty clips that cut together.
The practical payoff is predictability. When you know which units move, how much they move, and which materials they wear, you can plan a sequence the way you would plan a shoot — with shot lists, continuity notes, and repair passes. That is the difference between a tool you experiment with and a tool you build a workflow around.
Start with one still, one layer of motion, and one style module. Get that shot right, archive the data, and scale from there. Consistency compounds faster than complexity.
