
Why Image-to-Video Became the Default Starting Point
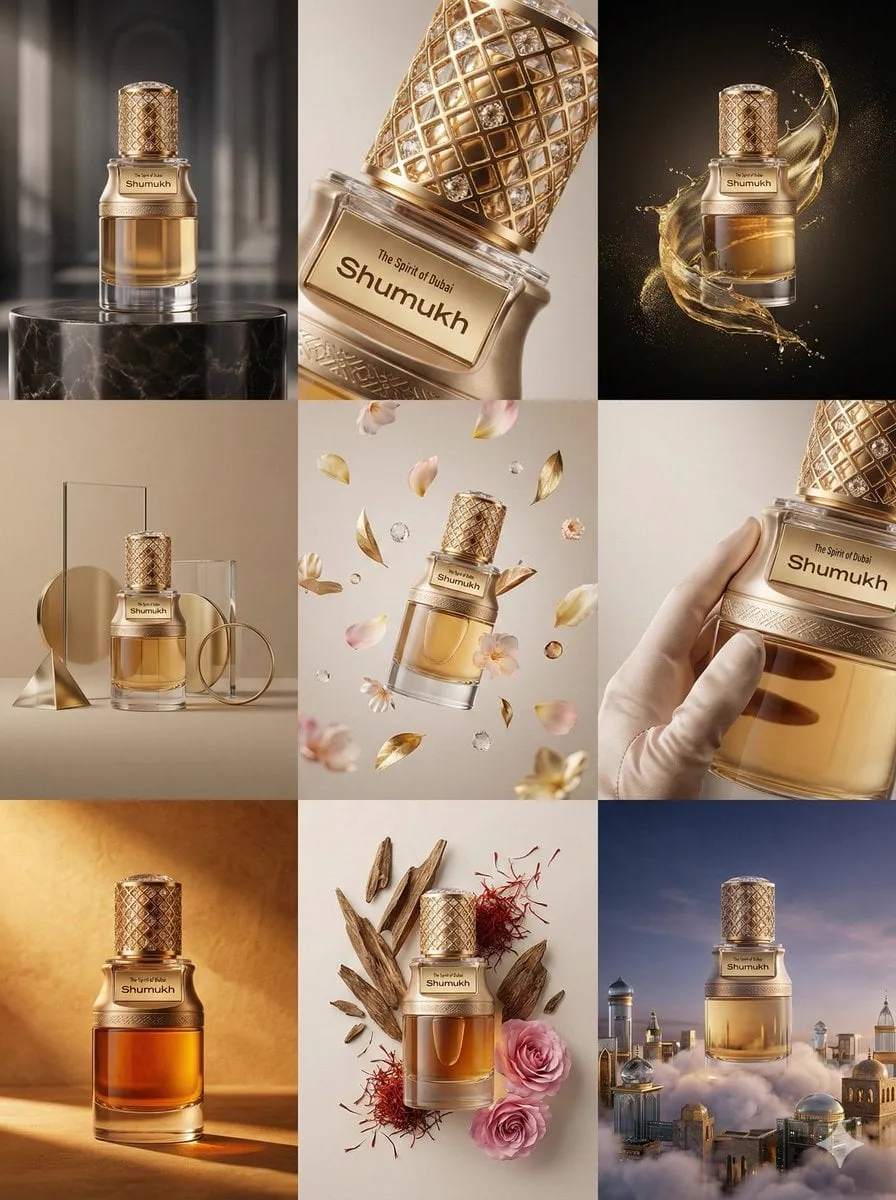
Most AI video work now starts with a picture, not a sentence. That shift happened for a simple reason: stills are cheap to iterate and expensive to get wrong. A single frame costs a few seconds and almost nothing to regenerate, so you can lock composition, wardrobe, lighting, and color before you ever commit to motion. Once the frame is right, animating it is a much more constrained problem.
Text-to-video asks a model to invent everything at once: subject, framing, style, motion, and timing. You get surprises, and most of them are bad in ways you cannot easily fix. Image-to-video gives the model a fixed visual anchor and asks it to solve a narrower question — how does this moment move? The result is more predictable, more brand-safe, and far easier to revise shot by shot.
There is also a practical production reason. Teams already have stills: product photography, character art, storyboard panels, design mockups, archival photos, and last month's campaign imagery. Image-to-video turns that existing library into motion instead of forcing a rebuild from scratch.
The trade-off is that the quality ceiling of your output is set by your input frames. A soft, over-processed, or ambiguously lit source image will produce soft, over-processed, ambiguous motion. Everything in this guide assumes you treat frame preparation as the real work and generation as the finishing step, not the other way around.
What Image-to-Video Actually Does — and What It Doesn't
It helps to be precise about the mechanics, because most disappointment comes from expecting the wrong kind of control.
Motion is inferred, not authored
A model does not know that your character is walking to a door. It knows that the pixels in a region suggest a body, and that bodies in this visual style usually move in certain ways. Your prompt and keyframes bias that inference; they do not direct it like a 3D rig. If you need exact choreography, keyframe control and short clips are your tools. If you need exact blocking, a traditional animation or previz pipeline is still the right answer.
The consistency problem is the whole game
Single clips look great in isolation and terrible in sequence. The moment you cut three generations together, small differences in skin tone, contrast, lens character, and motion speed become obvious. Solving consistency is 80% of the effort in a real project, and it happens through source-frame discipline, fixed settings, and deliberate model choice — not through luck.
Duration is a constraint, not a preference
Most image-to-video models are strongest in the three-to-eight-second range. Longer outputs drift: faces warp, hands mutate, backgrounds crawl. The professional move is to generate short, high-quality beats and extend or cut them together, rather than asking one generation to carry thirty seconds.
Audio is a separate track
Almost all image-to-video output is silent. Plan your sound design, voiceover, and music as an independent pass. Treating audio as an afterthought is the fastest way to make competent visuals feel amateur.
Building Your First Image-to-Video Pipeline
A repeatable pipeline matters more than any single setting. Here is one that scales from a solo creator to a small team.
Step 1: Art-direct the source frames
Prepare frames at the resolution you intend to output, or slightly above. Crop deliberately — a horizon that sits one degree off will visibly tilt when the model adds camera drift. Remove text and logos that will smear. Fix exposure before generation, not after. If a frame contains a face, make sure the face is sharp and well lit; models amplify blur rather than recovering detail.
Step 2: Write motion prompts, not image prompts
Your prompt should describe change over time: "slow push in, coat moving in wind, steam rising from cup." Do not re-describe the image — the model can already see it. Naming a shot type (wide, macro, over-the-shoulder) plus a camera behavior plus one or two subject actions is usually enough.
Step 3: Generate short, then extend
Start with four seconds. Evaluate motion quality and identity stability. If it holds, extend from the last frame with a continuation prompt that repeats the same subject and lighting language. If it fails early, fix the source frame rather than adding prompt words.
Step 4: Assemble and repair
Bring clips into your editor, cut on motion, and check each transition at full speed. Repair the worst frames with a short insert, a cutaway, or a speed ramp rather than regenerating everything.
Step 5: Lock a template
Once a shot type works, save the prompt, model choice, seed, and frame settings as a reusable preset. Consistency across a series comes from reusing settings, not from re-deriving them.
Choosing the Right Model for Each Shot
Model catalogues change constantly, but the decision criteria are stable. Ask these questions before you generate.
Does the shot need realism or style?
Photoreal models handle skin, glass, water, and fabric better. Stylized models handle illustration, anime, painterly, and graphic looks with sharper line integrity. Matching the model family to the source frame's visual language prevents a common failure: a photoreal model rendering an illustrated frame into a waxy hybrid that fits nowhere.
How much motion does the shot need?
Subtle-motion models — ones tuned for parallax, hair movement, drifting light — preserve faces and fine detail. High-motion models handle running, dancing, camera whips, and complex physics, but they are the ones most likely to melt a face at second six. Reserve them for shots where the movement is the point.
What resolution and aspect ratio do you need?
Vertical delivery, square social cutdowns, and widescreen all need generation at the correct aspect ratio. Cropping a widescreen generation into a vertical frame destroys composition and often cuts off the very motion you paid for.
When do you switch models mid-project?
Switch only when the visual requirement changes — for example, a photoreal product insert inside a stylized narrative. Do not switch between models shot to shot in the same scene, because their color science and motion cadence rarely match. If you must mix, generate both versions of a hero shot and use the second as a reference for grading.
Decision criteria in order
- Style match with the source frame.
- Motion amplitude the scene requires.
- Identity stability under that motion.
- Output resolution and aspect ratio.
- Speed and cost at the volume you need.
The first criterion that fails disqualifies the model. Most wasted time comes from optimizing speed before style and motion have been validated on a test clip.
Consistency Techniques That Hold Up Across a Whole Project
These are the techniques that survive contact with a real edit.
Reference frames and character sheets
Build a small reference set: front, three-quarter, profile, and a couple of expression variants on neutral backgrounds. Use the same references across every generation of that character. Reference-driven workflows keep facial structure far more stable than prompt-only descriptions like "dark hair, green eyes," which models interpret loosely.
Keyframe control and first/last frame anchoring
When you know where a shot begins and ends, supply both frames and let the model interpolate. This is the closest thing to directing motion in an image-to-video pipeline, and it is dramatically more reliable than describing the path in words. Use it for reveals, transformations, and any shot with a specific endpoint.
Multi-image fusion for scenes with several subjects
If a scene needs two characters, a product, and a background that all stay on-model, fuse multiple references in a single generation rather than compositing separate clips. Compositing AI clips tends to produce mismatched grain, motion blur, and lighting direction that the eye catches instantly.
Fixed seeds, fixed prompts, fixed order
Record the seed for every approved clip. When you need a variant, change one variable at a time. Changing prompt, seed, and reference set simultaneously makes it impossible to know what caused an improvement.
Keep lighting language constant
Lighting is the single biggest continuity giveaway. Pick a short lighting phrase — "soft overcast daylight, low contrast" or "single warm practical from the left" — and paste it into every prompt in the scene. It is crude, and it works.
Grade across the sequence, not per clip
Once assembled, apply a light unified grade. Matching black levels, saturation, and grain across an entire sequence hides a surprising amount of model-to-model variation.
Prompt Patterns for Motion: A Working Library
Good motion prompts are short, physical, and camera-aware. Here are patterns worth stealing.
Camera moves
- "Slow dolly in, subtle handheld, no zoom."
- "Gentle parallax left, foreground elements pass close to lens."
- "Static locked-off shot, only the subject moves."
- "Low tracking shot moving right at walking pace."
Subject motion
- "Hair and fabric lift in a light breeze, head turns slightly toward camera."
- "Hands lift the product into frame and set it down."
- "Steam rises steadily, liquid surface ripples once."
- "Subject blinks and shifts weight from one foot to the other."
Environment and atmosphere
- "Rain streaks across the window, background lights bloom."
- "Dust motes drift through a shaft of light."
- "Clouds move slowly behind the skyline."
- "Leaves move at the edges of frame, center stays calm."
Negative guidance
State what you do not want: "no morphing faces, no extra limbs, no text, no camera shake, no color shift." Negative guidance is not magic, but it measurably reduces the most common artifacts and takes ten seconds to write.
Duration pairing
Match motion ambition to clip length. A four-second clip can carry one camera move and one subject action. A six-second clip can carry two. Anything more in a short clip produces visual noise rather than motion, and viewers read it as a glitch.
A Realistic Workflow: A 60-Second Short From Twelve Stills
Here is how a full piece comes together in practice.
Preparation. Twelve source frames, all generated or shot at the same aspect ratio, with consistent lighting language and a shared color palette. Roughly two hours of frame work for a practiced creator, and worth every minute.
Beat sheet. Write twelve beats of five seconds each: establishing, product detail, character reaction, transition, payoff. Assign one model to the scene and one motion pattern per beat.
Generation. Generate all twelve at four seconds, evaluate, then extend only the six best to five or six seconds. Expect to discard around a third of first attempts.
Assembly. Cut on motion. Use the last half-second of one clip and the first half-second of the next to hide seams. Insert one or two hard cuts for rhythm — continuous soft motion for sixty seconds is hypnotic in a bad way.
Sound pass. Lay down a music bed with a clear downbeat, add two or three foley accents (whoosh, click, fabric), and record voiceover if needed. Sound is what makes generated motion feel intentional.
Finish. Add captions burned in or as a sidecar file, export at platform-appropriate bitrates, and produce one vertical cutdown from the same frames rather than re-generating for a second aspect ratio.
Budget note: the frame work and assembly dominate the timeline. Generation itself is usually the fastest part of the process.
Common Mistakes and How to Catch Them Early
Overloading a single generation. If your prompt describes a camera move, three actions, and a lighting change, expect mush. Split it into two shots.
Ignoring the source frame's flaws. Anything wrong in the still — a stray object, a distracting highlight, an awkward crop — will be animated and thereby amplified. Fix it in the frame.
Mixing models inside one scene. Different models have different motion cadence. The mismatch reads as a jump in style even when the imagery matches.
Skipping the assembly pass. Reviewing clips individually hides continuity problems. Always watch the full sequence at speed before declaring anything finished.
Chasing realism when style is the goal. If your brand is illustrated, a photoreal generation will feel off-brand no matter how technically impressive it looks.
Neglecting hands, teeth, and text. These are the three artifact magnets. Frame shots to reduce their prominence, or plan a cutaway.
Generating at the wrong aspect ratio. Decide delivery format before the first generation, not after.
Quality Checks, Audio, and Finishing
Run this checklist before publishing.
Visual checks
Watch the sequence once at full speed without pausing. Then watch it muted. Then watch it on a phone screen. The muted pass reveals motion problems; the phone pass reveals composition problems.
Check identity stability frame by frame on any close-up. Check that lighting direction does not flip between shots. Check that color temperature is consistent. Check for background crawl and shimmer in areas of fine detail.
Audio checks
Confirm dialogue and voiceover are intelligible on phone speakers. Confirm music does not mask foley. Confirm there is no clipping at transitions. A simple loudness normalization pass fixes most of it.
Delivery checks
Export with captions. Confirm safe areas for vertical crops. Confirm file size and bitrate against platform guidance. Keep project files organized by scene so revisions are cheap.
The revision habit
Keep a log of which prompts, seeds, and models produced approved shots. When a stakeholder asks for a change three weeks later, that log turns a rebuild into a twenty-minute edit.
FAQ
Is image-to-video better than text-to-video?
For anything with a defined look, yes. Text-to-video is useful for exploring concepts and generating rough ideas; image-to-video is better for controlled production.
How long should my first clip be?
Four seconds. It is long enough to judge motion and short enough that a failure is cheap.
Why do faces warp in longer clips?
Motion accumulates error. The model drifts from the source identity over time. Shorter clips, reference frames, and keyframe anchoring reduce it.
Do I need a different model for each visual style?
Ideally you pick one model family per project and stay inside it. Style consistency across a series matters more than squeezing out a slightly better single clip.
Can I use my own photography?
Yes, and it often produces the best results because the lighting and lens character are already coherent. Ensure you have the rights to animate and publish the material.
How many attempts does a good shot take?
Two to four on a well-prepared frame, more if the motion is complex. If you are past six attempts, the source frame is usually the problem.
Should I generate vertical and horizontal versions?
Generate in your primary format and reframe in the edit. Re-generating for a second aspect ratio doubles cost and often breaks consistency.
What matters most for a polished result?
Frame preparation, short clips, one model per scene, and a real sound pass. Those four habits matter more than any individual setting.
