
Why Image-to-Video Is the Fastest Route to Usable Motion
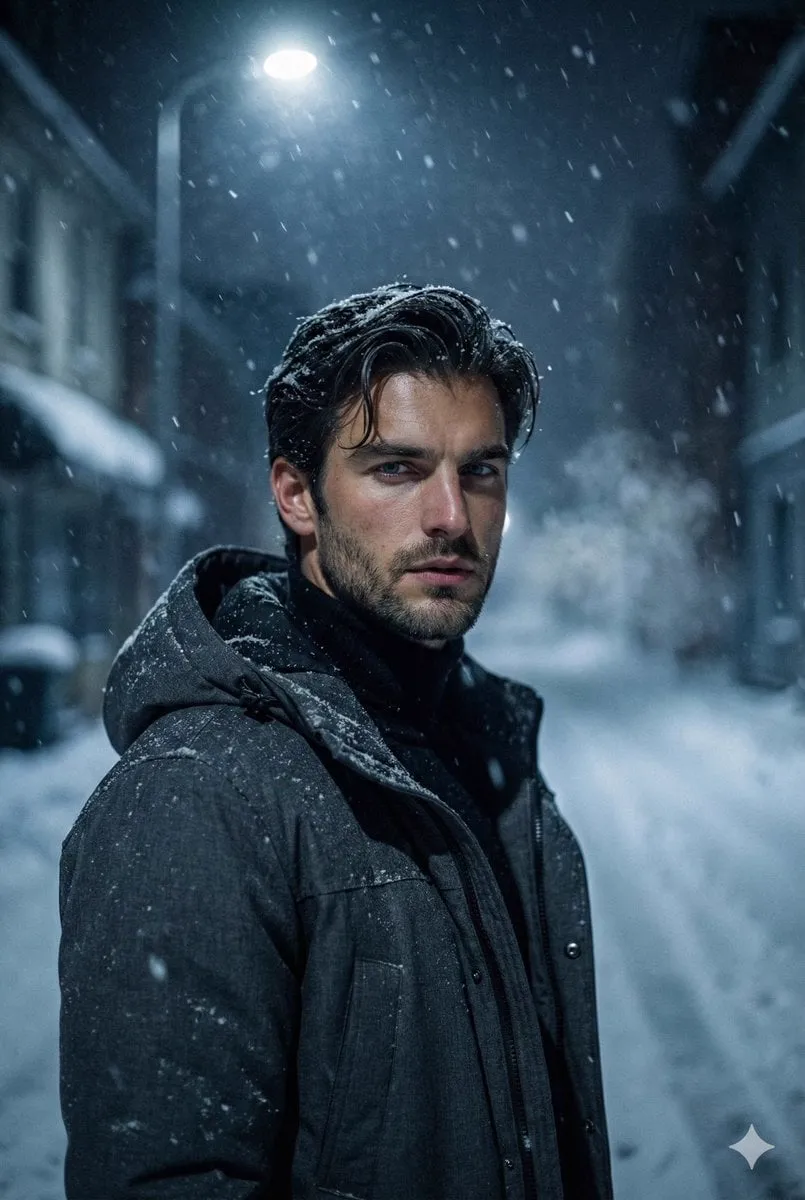
Image-to-video generation has moved from a novelty to the default starting point for a large share of AI-assisted production. The reason is simple: a still image already answers the hardest questions in filmmaking. Composition, framing, lighting direction, subject placement, wardrobe, color palette, and lens character are all decided before the first frame of motion is generated. The model only has to solve one problem — how does this frame change over the next few seconds?
That constraint is enormously useful. Text-to-video asks a model to invent the world, cast it, light it, design it, and animate it simultaneously. The result is often impressive in isolation and unusable in a sequence, because nothing matches from shot to shot. Image-to-video flips that relationship. You become the art department, and the model becomes the animator.
This guide walks through how to build that pipeline in practice: how to prepare a still that animates cleanly, how Flux-class image models fit alongside video models, how to write prompts that describe motion rather than appearance, how to keep a character recognisable across eight shots, and how to troubleshoot the specific failures that show up again and again.
What Each Tool Family Is Actually Good At
The market is no longer one race. Different model families have specialised, and choosing the wrong one for a shot costs more time than any prompt tweak can recover.
Flux-class image models as the foundation layer
Flux-style models are strongest at the front of the pipeline. They generate and edit the source frame: a hero portrait, a product on a seamless backdrop, a stylised environment plate. Their real value in an image-to-video workflow is control. Inpainting lets you remove a stray object before it becomes a morphing artefact. Style and structure references let you hold a visual language across a whole set of frames. Detail-preserving upscaling gives the video model more information to work with, which directly reduces shimmer on faces and thin edges.
Treat these models as your pre-production department, not your animator. A sharp, clean, well-lit source frame is the single biggest quality lever you have.
Runway-style shot control tools
Tools built around director-style controls — motion brushes, camera presets, keyframe endpoints, first-and-last-frame conditioning — are the best choice when you know exactly what the camera should do. If a shot needs a slow push-in that ends on a close-up, a keyframe-driven tool lets you define both endpoints and interpolate the middle. That is far more reliable than describing the move in prose and hoping.
Long-form coherence models
A second category optimises for longer durations and narrative plausibility: characters walking through a scene, objects interacting, physics that mostly holds together. These are the tools to reach for when a shot needs to sustain a performance for eight to fifteen seconds without a cut. The trade-off is usually less precise camera control and slower generation.
Accessible high-throughput models
Kling, Hailuo, and similar platforms compete on iteration speed and price per second rather than maximum fidelity. They are excellent for storyboard-level previews, social cutdowns, and any project with dozens of shots where per-shot cost dominates the budget. Many creators run a two-tier pipeline: preview everything on a fast, inexpensive model, then re-render only the approved shots on a premium one.
Open-weight video models
Self-hosted video models matter for two reasons: privacy and fine-tuning. If your source material cannot leave your infrastructure, local inference is the only option. If you need a very specific look — a particular animation style, a branded character, a niche product category — training a lightweight adapter on 20 to 50 clean clips can outperform any amount of prompt engineering on a general model.
A Repeatable Image-to-Video Workflow, Step by Step
The workflow below assumes a five-to-ten-shot sequence. It scales down to a single clip and up to a full campaign.
Step 1: Build a video-ready still
Not every good image animates well. Before generating, check these properties:
- Resolution. Aim for at least 1080p on the short edge. Video models upscale internally; a low-resolution source gives them less to work with and produces softer motion.
- Sharpness. Baked-in motion blur is confusing to animate. Keep the still crisp.
- Separation. A subject that reads clearly against its background warps less. High-contrast edges help.
- Hands and faces. Clean them with inpainting first. Any defect in the still will be amplified, not hidden, once motion begins.
- Headroom. Leave space in the direction of the intended camera move. A push-in needs room to travel.
- Text and logos. Keep them out of the frame unless you can tolerate them wobbling. Small type almost always degrades.
Step 2: Write a motion prompt, not an image prompt
This is where most beginners lose quality. An image prompt describes what a frame looks like. A video prompt describes what changes. Focus on four channels:
- Subject action — what the person, animal, or object does.
- Camera behaviour — static, push in, dolly out, slow orbit, handheld drift.
- Environmental motion — steam, rain, drifting fabric, moving crowds, swaying foliage.
- Lighting change — a cloud passing, a spotlight sweeping, a warm shift at the end.
A compact example: "Static camera. Woman turns her head slowly toward camera, hair lifting slightly in the breeze. Steam rises from the cup. Warm afternoon light, subtle flicker of light through blinds."
Keep prompts between roughly 15 and 40 words for most models. Longer prompts dilute attention; the model starts averaging instructions instead of following them.
Step 3: Lock aspect ratio and duration before generating
Generate at your delivery aspect ratio. Cropping an animated clip after the fact almost always cuts off the motion you liked. For duration, four to six seconds is the sweet spot for most models — long enough to establish a beat, short enough that drift does not accumulate. Build longer sequences in the edit, not in a single generation.
Step 4: Batch, compare, and select
Generate four to eight variants per shot with slightly different seeds. When reviewing, watch two things before anything else: the first frame (does it match your source?) and the last frame (has the subject drifted into a different person?). If the last frame is unusable, the clip is unusable, no matter how good the middle looks.
Step 5: Finish in an editor
Raw generations are rarely broadcast-ready. A short finishing chain — stabilisation, deflicker, frame interpolation, colour match, sound design — typically contributes more perceived quality than switching to a better model. Cut on motion: place your edit points where the movement already changes direction, so the cut feels motivated rather than imposed.
Prompting for Motion: Patterns That Change the Output
Motion vocabulary is not decoration. Specific verbs produce specific results, and the difference between "camera moves" and "slow dolly in" is measurable.
Camera language that works well: slow push in, dolly out, pan left to right, crane up, low-angle reveal, slow orbit around the subject, locked-off static shot, subtle handheld drift.
Subject language that avoids morphing: turns head, blinks, smiles slightly, shifts weight, lifts an arm, takes a single step, breathes, glances off-camera. Notice the restraint — small, single actions animate far more reliably than complex choreography.
Environment language: steam rises, dust motes drift, water ripples, curtain billows, crowd moves in the background, leaves tremble.
Negative instructions: avoid morphing faces, avoid extra fingers, keep the background static, no text, no camera shake, no zoom.
Two parameters usually matter more than the prompt itself. Motion strength (sometimes called motion amplitude) controls how far the model is allowed to move; lowering it fixes most face distortion. Camera versus subject weighting, where available, tells the model whether the movement should come from the lens or from the subject — a distinction that determines whether your background melts or stays stable.
Consistency Across Shots: Characters, Wardrobe, and Sets
A sequence lives or dies on consistency. Four practices do most of the work.
Build a character sheet first
Generate front, three-quarter, and profile views of the same character with your image model. Keep the seed fixed, and reuse the strongest frame as a reference for every subsequent still. Then reuse that same reference when animating. Two levels of anchoring — image reference plus fixed seed — dramatically reduce drift.
Lock the lens language per scene
Decide a focal length and stick to it. Mixing a wide 24mm look with an 85mm portrait look inside one scene reads as a continuity error even when the character is perfect. Consistency in perspective is often what viewers actually notice.
Fix lighting direction and colour temperature
Note where the key light sits and what its colour bias is, then state it in every prompt. "Key light camera-left, warm 3200K, soft falloff" keeps shots compatible in the edit. Colour mismatches are easier to grade around than lighting direction changes.
Keep a shot bible
A single document listing, per shot: source image, seed, model version, prompt, duration, and notes. Six weeks later you will not remember which prompt produced the shot the client approved. The shot bible is what makes reshoots possible instead of starting over.
Troubleshooting: The Failures You Will Actually See
Face morphing mid-clip. Shorten the duration to three or four seconds, lower motion strength, raise the source resolution, and reduce the number of simultaneous actions. If a character turns and speaks and walks at once, pick one.
Melting background. Usually caused by a camera move the model cannot reconstruct. Add "static background, locked-off camera, only the subject moves" and remove the camera instruction.
Flicker or shimmer. Often inherited from a grainy source. Clean noise before animating, apply a deflicker pass afterwards, and avoid heavy film-grain overlays on the input frame.
Warping text and logos. Keep them out of frame, or generate the graphic separately as a clean overlay in the edit.
Stuttering motion. Generate at 24 or 25 frames per second and interpolate to 50 or 60 only when you want slow motion. Interpolation on top of an already-jittery clip creates smearing.
Colour shift between clips. Grade with a shared reference frame or a colour chart shot. Small shifts compound visibly when clips are cut together.
Cost, Speed, and Quality: How to Choose a Tool for a Shot
Rather than picking one favourite model, route each shot to the right tier.
| Shot type | Priority | Best tier |
|---|---|---|
| Hero shot, 4–6s | Maximum fidelity | Premium model, keyframe control |
| Montage filler, 2–3s | Volume and speed | Fast, low-cost model |
| Dialogue-adjacent performance | Temporal coherence | Long-form capable model |
| Sensitive or private footage | Data control | Local open-weight model |
| Precise camera move | Determinism | Keyframe or motion-brush tool |
Three practical rules keep budgets predictable. First, preview at low resolution and short duration, then re-render approved shots at full quality. Second, cap variants per shot — four to eight is enough; beyond that you are usually solving a prompt problem with volume. Third, batch the same shot type together, because switching between tools costs more attention than it costs money.
Building a Small Production Pipeline
A 30-second product spot with eight shots typically looks like this:
- Pre-production (1 hour). Write the shot list. Decide aspect ratio, duration per shot, and lens language.
- Still generation (2 hours). Produce all eight source frames with the image model. Inpaint defects. Upscale.
- Animation (2–4 hours). Animate in batches of the same shot type. Four variants each, select one per shot.
- Finishing (2 hours). Stabilise, deflicker, interpolate where needed, colour match, assemble.
- Audio (1 hour). Music bed, sound design, and — if dialogue is needed — a separate voice pass with lip-sync handled in a dedicated tool rather than left to the video model.
The lesson from this breakdown is that animation is not the bottleneck. Preparation and finishing are, and both are areas where deliberate process beats model upgrades.
Rights, Disclosure, and Practical Guardrails
Keep a generation log: source of every input image, prompt used, model version, and date. If a client or platform asks how a shot was made, the log answers in seconds.
Use source images you have the right to use. Likeness, trademarks, and property releases apply to AI-generated footage exactly as they do to photographed footage. Avoid prompts that name living artists. Where platforms require AI disclosure labels, disclose — audiences are more forgiving of transparent AI use than of undisclosed AI use discovered later.
FAQ
Do I need Flux specifically?
No. Flux-class image models are popular because of their control features, but any image workflow that gives you inpainting, reference conditioning, and clean upscaling will serve the same role in the pipeline.
How long should an image-to-video clip be?
Four to six seconds for most shots. Anything longer accumulates drift, and you can always extend perceived duration with a cutaway or a slow-motion pass in the edit.
Why does my character stop looking like themselves?
Usually a combination of long duration, high motion strength, and a low-detail source frame. Shorten the clip, reduce motion strength, and anchor with a fixed seed plus a reference image.
Can I run image-to-video locally?
Yes, with open-weight models and a modern consumer GPU, though expect slower iteration and more setup work. The trade-off is worthwhile when privacy or fine-tuning matters more than convenience.
What resolution should I generate at?
Match your delivery target. If you are publishing vertically, generate vertically. If you need a 1080p master, give the model a 1080p or higher source and avoid aggressive crops afterwards.
How do I get convincing slow motion?
Generate at 24 frames per second with a low motion strength so the movement is smooth, then interpolate to 60 frames per second in post. Interpolating an already fast or jittery clip produces artefacts.
How many variants should I generate?
Four to eight per shot. If none of them work, the problem is the source frame or the prompt, not the sample count.
Can I mix different models in one project?
Yes, and most studios do. Consistency comes from your shot bible, lighting notes, and grade — not from using a single tool for every clip.
Key Takeaways
Image-to-video works best when you treat the still as the deliverable that matters most. Invest in a clean, high-resolution, well-lit source frame, then describe change rather than appearance in your prompt. Keep clips short, batch your variants, and finish in an editor instead of chasing perfection in generation. Route shots to the right model tier — premium for heroes, fast and cheap for montage filler, local for sensitive material. Lock your lens language and lighting per scene, and keep a shot bible so that anything can be reproduced on demand. Do those things and the model choice becomes a detail rather than a gamble.
