
Generative video has moved past the novelty stage. Teams now ship episodic shorts, product films, and social campaigns built largely from model output, and the bottleneck has shifted from "can the model render this?" to "can it render this the same way twice?" That is where a Lego Pixel approach earns its place. It is less a single feature than a discipline: you treat reference imagery as a structured grid of pixel blocks, hand that grid to the model as one coherent canvas, and use it to lock identity, wardrobe, lighting, and palette across every shot.
This guide covers the technique end to end — what it is, why consistency breaks without it, the step-by-step workflow, prompt patterns, tool choices, a quality-control checklist, and the mistakes that waste the most render time.
What "Lego Pixel" Means in a Video Pipeline
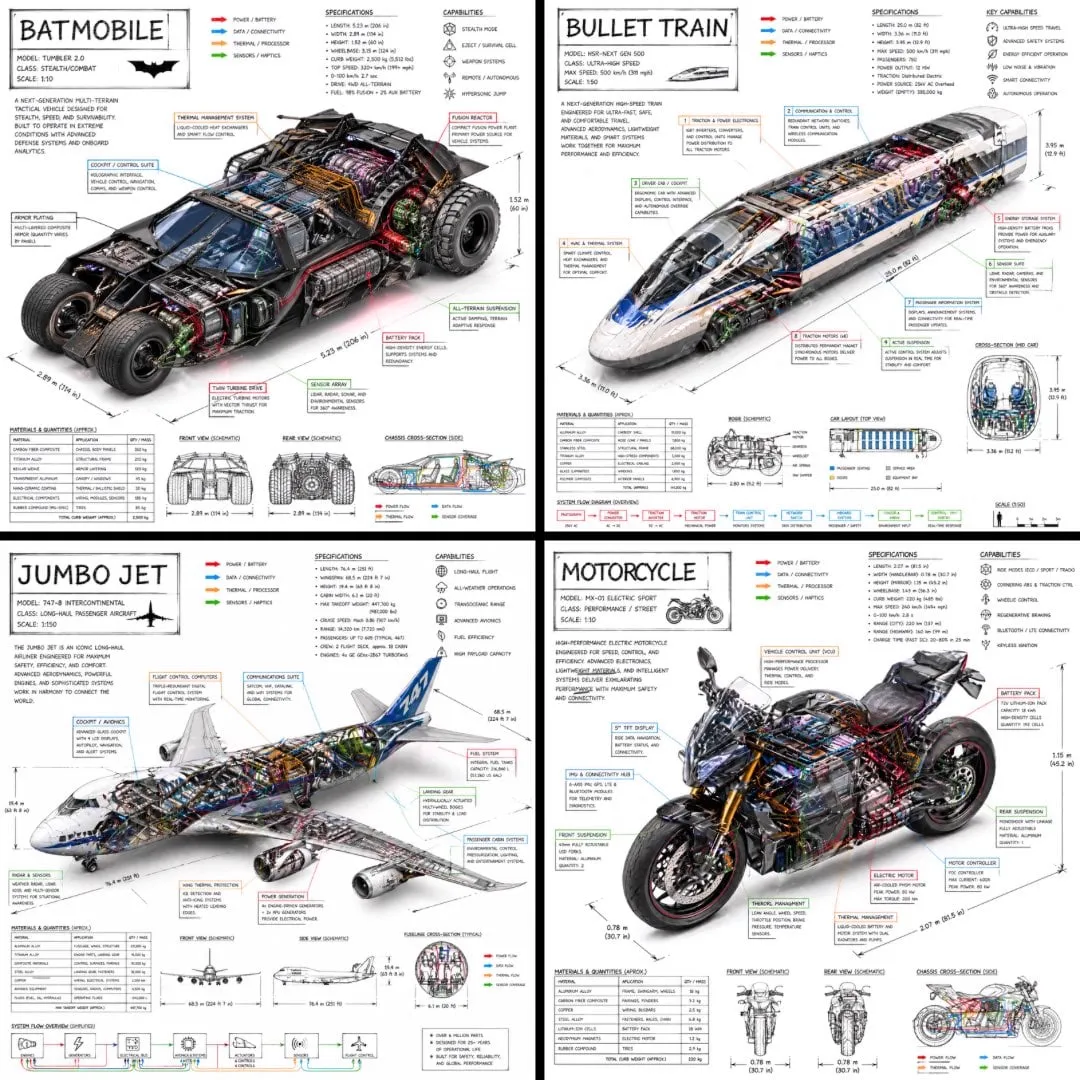
The name comes from the visual metaphor. Imagine snapping small, self-contained image tiles together into one larger picture, the way interlocking bricks form a model. Each tile carries a piece of truth about your scene: a character's face at a three-quarter angle, a costume detail, a prop, a background plate, a color reference. Assembled into a single grid, those tiles become one reference image the model can read in a single pass.
That matters because most generative video models do not treat a pile of separate reference images as a unified specification. They weight them, blend them, and sometimes quietly ignore one. A grid changes the geometry of the problem. The information arrives as one spatial layout, and the model's attention can move across it the way it moves across any composition — comparing the face in the top-left tile to the jacket in the bottom-right one.
There are two distinct ways to use the technique, and it helps to decide which you want before you start:
- Consistency grids. Photoreal or semi-real tiles stitched together purely to constrain identity, wardrobe, and environment. The grid is scaffolding; you never see it in the final frame.
- Stylized mosaic output. The pixel-block look is the aesthetic itself, with chunky color cells, hard edges, and a deliberately low-resolution, toy-like texture. Here the grid logic shapes the finished render rather than hiding behind it.
Most production work starts with the first and occasionally graduates into the second for a title sequence, a transition, or a stylized flashback.
Why Visual Consistency Still Breaks
Every practitioner hits the same wall. Shot one looks perfect. Shot two has a slightly different jawline. Shot five has the right face but the jacket has changed color, and by shot nine the lighting has drifted from warm interior tungsten to something closer to overcast daylight. None of these failures are dramatic on their own. Together they destroy the illusion.
There are four mechanical reasons this happens.
Sampling drift. Video diffusion samples noise across a temporal sequence. Small differences in the seed, the prompt phrasing, or the frame count change where the model lands.
Reference dilution. When you attach many separate references, each one competes for influence. The model averages them instead of selecting the right one for the current shot.
Prompt ambiguity. Phrases like "the same character" mean nothing to a model. It needs something concrete to anchor to — a visual artifact it can compare against.
Context limits. Long prompts get truncated or down-weighted, and the details you spent twenty minutes writing are the first thing to go.
A grid addresses three of the four directly. It compresses identity information into a single visual artifact, it removes competition between separate references, and it lets you replace paragraphs of description with one image plus a short instruction.
The Grid Workflow, Step by Step
The workflow below is tool-agnostic. It works whether you generate frames in a diffusion-based video model, a hosted text-to-video service, or a hybrid pipeline that renders keyframes in an image model and interpolates with a video model.
Step 1: Audit and Normalize Your Source Images
Before you build anything, gather every image that could define your subject. Aim for coverage rather than quantity: front, three-quarter left, three-quarter right, profile and back, plus a close-up of hands or a signature prop. Eight to twelve tiles is usually the sweet spot.
Then normalize. Crop every image to the same aspect ratio, ideally square. Match exposure and white balance so the model is not learning three different lighting setups as if they were the same environment. Remove backgrounds or replace them with a consistent neutral tone. This step feels like busywork, and it is the single highest-leverage twenty minutes in the entire process.
Step 2: Build the Reference Grid
Arrange the normalized tiles into a single canvas. A 3×3 or 4×4 layout is easy for both humans and models to parse. Leave a thin, uniform gutter between tiles — a few pixels of neutral gray — so the model reads them as distinct cells rather than one continuous collage.
Label tiles only if your target model handles text well. Otherwise keep the grid clean and describe tile positions in the prompt instead ("the top-left cell shows…"). Save the grid at a resolution the model actually uses. Sending a 4096-pixel grid to a model that downsamples to 1024 throws away detail and can confuse layout reading.
Step 3: Write the Grid-Aware Prompt
Your prompt now has three jobs: describe the shot, point at the grid, and state the invariants. A workable structure looks like this:
- Shot description — subject, action, camera, duration.
- Grid reference — which cells to consult for identity, wardrobe, and environment.
- Invariants — the specific things that must not change.
- Negative constraints — the specific things that must not appear.
Keep it tight. "Use the top-left and top-center cells as the identity reference for the character. Wardrobe from the bottom-left cell. Environment palette from the right column. Do not alter hair length or jacket color." That last sentence is worth more than three paragraphs of adjectives.
Step 4: Generate Short Beats, Then Assemble
Long single generations are where consistency dies. Instead, generate two- to four-second beats, each anchored to the same grid. Short clips give you more chances to reject a bad sample cheaply and make it easier to cut around a single drifting frame. Assemble in an editor rather than trying to get one long take.
Step 5: Re-Inject the Grid at Every Revision
The moment you re-roll, extend, or interpolate, re-attach the grid. Do not assume the model remembers. If your pipeline supports a persistent reference slot, use it; if not, make re-attaching part of your template so it cannot be forgotten.
Multi-Image Fusion: Characters, Props, and Environments
Grids get more powerful when you separate concerns. Rather than cramming a character, a costume, and a location into one canvas, build three specialized grids and attach them deliberately depending on the shot:
- Identity grid — faces at multiple angles, plus a body-proportion reference.
- Wardrobe and prop grid — flat-lay or worn shots of every costume element that appears more than once.
- Environment grid — wide plates, detail shots, and a color chip strip so palette stays stable.
For shots where a character interacts with a signature object — a phone, a sword, a coffee cup — build a fourth micro-grid showing the object from several angles. Objects drift faster than faces and are easier to fix proactively than in post.
When fusing, set priority rules. If identity and environment disagree about lighting, identity usually wins for a close-up and environment wins for a wide. State that priority in the prompt so the model is not guessing.
Prompt Patterns That Hold Up Across Shots
A few sentence patterns survive contact with real models better than others.
The locked-spec sentence. "The subject's facial structure, hairline, and eye color must match the reference grid exactly." Short, unambiguous, repeated in every shot prompt.
The negative list. Name the failure modes you actually see — extra fingers, a drifting logo, changing fabric sheen, hair growing longer between shots. Negatives work best when they target your previous failures rather than a generic list copied from a forum.
The camera sentence. State lens behavior explicitly: static tripod, slow dolly in, handheld micro-shake. Camera ambiguity produces temporal wobble that reads as identity drift even when the face is fine.
The continuity clause. End every prompt with what carries over: "This shot continues directly from the previous one; the jacket remains unbuttoned and the lighting remains warm indoor."
Keep a running prompt template with these slots pre-filled. The template is the real asset; individual prompts are disposable.
Choosing Tools for a Grid-Based Workflow
You do not need one specific platform. You need a pipeline where each stage is replaceable.
Image generation. Any capable image model for building tiles and keyframes. Prefer one with strong character-reference features.
Grid assembly. A simple canvas tool. Image editors, design apps, or a short script that tiles images into a fixed layout all work. Automate it if you build grids weekly.
Video generation. Diffusion-based video models or image-to-video services. Prioritize ones that accept image references alongside prompts and offer a persistent reference feature.
Interpolation and cleanup. Frame interpolation for smoothing, plus a dedicated upscaler for final delivery. Run upscaling last, and verify it does not shift skin tone.
Assembly and grade. A non-linear editor for cutting beats, matching color, and adding sound. Sound is not optional — it hides micro-jitter better than any filter.
The decision criterion that matters most is reference handling. If a tool ignores your grid or averages it into mush, no amount of prompt craft will save the sequence.
Quality Control: The Checklist Before You Export
Run this list on every sequence. It takes five minutes and catches most of what audiences notice.
- Identity drift — compare the first and last shot side by side at the same scale.
- Wardrobe and prop continuity — buttons, logos, jewelry, handedness.
- Palette stability — skin tones and background walls across shots.
- Motion coherence — hands, hair, and fabric edges during fast movement.
- Edge artifacts — halos or shimmer where subject meets background.
- Grid contamination — confirm no tile boundary or label text leaked into a frame.
- Audio-visual sync — lips, footsteps, impact frames.
- Delivery specs — resolution, frame rate, bitrate, color space.
Keep a rejected-frames folder. Patterns in your rejects tell you what to add to the negative list and what to fix in the grid.
Common Mistakes and How to Fix Them
Overloading a single grid. Twelve tiles of everything means nothing stands out. Split into specialized grids.
Mixing lighting conditions in one grid. The model treats inconsistency as artistic intent. Normalize before assembly.
Writing a novel instead of a prompt. Long prompts dilute. Point at the grid instead.
Generating long clips. Ten-second generations drift far more than three short beats. Cut more, generate less.
Skipping the gutter. Tiles that touch each other merge into one image, and the model invents a hybrid face.
Forgetting to re-inject on extensions. Every extension is a fresh generation. Re-attach, every time.
Upscaling too early. Upscale after the cut is locked, not before, or you will process footage you throw away.
Scaling the Workflow Across a Series
Once the technique works for one shot, systematize it.
Build a bible. One folder per project with grids, prompt templates, seed notes, and a continuity log of wardrobe and prop states per shot.
Version your grids. When a costume changes in episode three, create a new grid rather than editing the original. Old shots stay reproducible.
Name files predictably. Project, sequence, shot, version. It sounds trivial until you have four hundred renders.
Track seeds and set a rejection budget. When a shot works, note the seed and grid version. Then decide in advance how many re-rolls per beat are acceptable — without a budget, consistency work expands to fill all available time.
FAQ
Is this the same as using a character reference feature?
No. A character reference feature is one input. The grid is a method for organizing many references into a single readable artifact. You can use a grid with or without a dedicated reference slot, and the grid usually outperforms a single reference across long sequences.
How many tiles should a grid contain?
Eight to twelve for identity, six to nine for wardrobe, four to six for environments. Beyond that, individual tiles get downsampled into irrelevance.
Can the pixel-block look be the final style instead of just scaffolding?
Yes. Describe the aesthetic explicitly — chunky color cells, hard edges, limited palette, visible grid rhythm — and choose reference tiles that already share a tight palette. The grid then serves double duty as structure and style.
Does this work for animation and stylized 3D?
It works even better. Stylized characters have fewer ambiguous details, so the model has less room to drift.
Do I still need a good prompt if I have a good grid?
Yes, but a shorter one. The grid handles appearance; the prompt handles action, camera, and constraints. Without the grid you write paragraphs. With it, you write sentences.
