
What "Lego Pixel" Actually Means for AI Video
Photorealistic AI video almost never fails because a model cannot draw a convincing texture. It fails because the model draws a different convincing texture in every frame. Skin pores, gravel, fabric weave, and hair strands are high-frequency details, and high-frequency details are exactly what a generative model re-invents from scratch at every timestep. The result is a clip that looks impressive in a still and unstable in motion.
"Lego Pixel" is a useful mental model for fixing that. Instead of treating a frame as one monolithic image, treat it as an assembly of small, individually committed units. A Lego build looks coherent not because it was cast from a single mold, but because thousands of identical bricks obey the same geometry, the same material rules, and the same snapping behavior. Photoreal footage behaves the same way once you break it down: skin, denim, asphalt, glass, brushed metal, foliage, and atmospheric haze are each a "brick class" with its own texture scale, reflectance, and motion signature.
The practical shift is that you stop writing prompts as scene descriptions and start writing them as material and lighting contracts. "A photorealistic woman walking through a rainy market" gives the model enormous freedom. "Medium-coarse denim with visible twill, matte skin with visible pore detail and no smoothing, wet asphalt with broken specular highlights reflecting a single overhead practical light" gives it constraints it can hold across frames. Constraints are what convert a lucky still into a usable shot.
Why Photorealistic AI Video Breaks: The Four Failure Modes
Before adding technique, it helps to know exactly what you are fighting. Nearly every ugly AI video artifact traces back to one of four problems.
1. Temporal flicker and detail boiling
Micro-detail that is re-predicted every frame appears to boil or crawl. Gravel shifts, eyelashes flicker, and fine text on signage morphs. The fix is rarely "more detail in the prompt" — it is reducing the amount of micro-detail the model has to invent per frame. Lock a keyframe that already contains the detail, then let the model interpolate rather than generate. Where interpolation still boils, composite the detail back in during finishing.
2. High-frequency detail collapse
Models trained at lower resolutions tend to average fine structures into mush. A chain-link fence becomes a gray haze; a brick wall becomes a smooth surface with a painted pattern. The workaround is resolution strategy: generate at the largest practical canvas, keep the camera moving slowly enough that the model has time to resolve detail, and treat any 1080p output as a proxy that will be replaced by an upscaled or tiled pass.
3. Lighting that ignores geometry
Light direction is the fastest way to expose a fake. Shadows detach from feet, reflections appear on surfaces that should be matte, and a key light jumps from the left to the right between cuts. Fix this by making light part of the contract: name the source, its direction, its softness, and its color temperature, then keep that description identical across every shot in the scene. If you want a light to move, move it deliberately and show the shadow traveling with it.
4. Identity, wardrobe, and prop drift
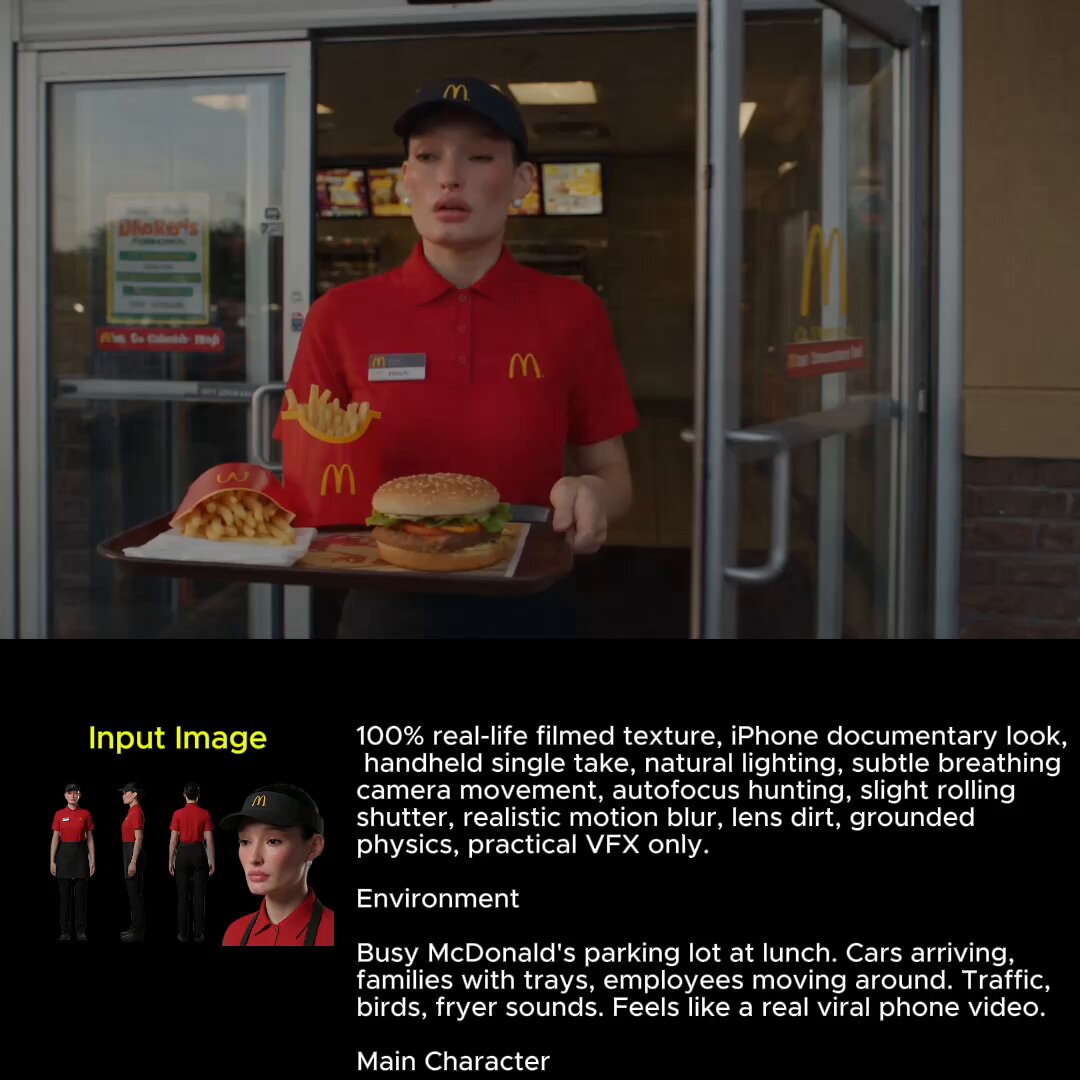
A face that changes structure by five percent per second reads as uncanny even when each frame looks good in isolation. The same is true for a jacket's stitching, a watch's bezel, or a coffee cup's rim. Reference images solve more of this than any adjective. Feeding three to five consistent references — face, wardrobe, environment, light — reduces drift far more reliably than stacking words like "ultra detailed" and "hyperrealistic."
The Lego Pixel Method: Build Frames From Stable Units
Inventory your blocks before you prompt
Write out your visual block classes for the scene: subject skin, hair, primary garment fabric, secondary garment, ground surface, background architecture, foliage or set dressing, atmosphere, practical lights, and lens artifacts. For each one, note three things: texture scale (fine, medium, coarse), reflectance (matte, satin, glossy, wet), and motion behavior (rigid, draping, fluttering, particulate). That inventory becomes your prompt skeleton, and it stays consistent across every shot you generate for the project.
Lock keyframes first, animate second
Treat keyframes as the load-bearing structure of the shot. Generate the opening pose at zero or near-zero motion, inspect it at 200 percent zoom, and only then hand it to an image-to-video pass. If the first frame is wrong, no amount of motion prompting will rescue it. Many disappointing clips are simply the result of animating a mediocre still.
Use reference stacks instead of adjective stacks
Modern video tools accept multiple image inputs, and that is where consistency comes from. A minimum viable stack is four references: the subject's face, the subject's wardrobe, the environment, and a lighting reference. Keep all references in the same aspect ratio and the same color treatment as your target output. Mismatched references fight each other and produce a muddy average.
Work in passes, not in one heroic generation
Think like a compositor. Base pass establishes composition and motion. Detail pass resolves texture on locked frames. Finishing pass handles upscale, stabilization, grain, and color. Attempting everything in a single generation is the most common reason creators burn hours re-rolling the same prompt.
A Step-by-Step Photorealistic Workflow
Step 1: Shot plan and block inventory
Break the sequence into shots no longer than four to six seconds. For each shot, write one line of action and one line of camera behavior. Then attach your block inventory. This document does the heavy lifting later, because every prompt for that shot inherits the same material and lighting language.
Step 2: Generate base keyframes at minimal motion
Use a still-image generator or the video model's text-to-image mode to produce the opening frame. Evaluate against a checklist: is the light direction plausible, are hands and eyes correct, is the texture scale appropriate for the shot size? Fix problems here, where iteration is cheap. Save the seed for every keyframe you approve.
Step 3: Run detail passes on locked frames
Once the keyframe is approved, run a detail or upscale pass before animating. Some pipelines let you refine a still with a low-denoise second pass that adds pore-level texture without changing composition. Lower denoise values preserve structure; higher values start inventing. For faces, stay conservative. For environment plates, you can push harder.
Step 4: Move the camera, not the subject
When you finally animate, favor camera motion over subject motion for the first attempts. Dolly-ins, slow arcs, and gentle parallax keep geometry stable and hide temporal artifacts, because the model is transforming a mostly static scene. Subject motion — a turn of the head, a hand gesture, a walk cycle — is where identity drift and limb weirdness appear. Introduce it one element at a time so you can isolate what breaks.
Step 5: Finish like an editor, not a prompter
Upscale in two modest steps rather than one aggressive step, and add a light film grain pass; grain masks residual boiling and reads as photographic. Stabilize only as much as needed — over-stabilization produces a floating, weightless camera that instantly reads as synthetic. Grade last, and grade to a single reference still so every shot lands in the same color world.
Prompt Patterns That Survive Rendering
The difference between a prompt that holds across 120 frames and one that falls apart is specificity about physical behavior rather than quality adjectives.
| Intent | Weak phrasing | Lego Pixel phrasing |
|---|---|---|
| Skin realism | "hyperrealistic face" | "matte skin with visible pore texture, no smoothing, soft wrap light from the left" |
| Fabric | "detailed clothing" | "medium-coarse twill denim, visible weave and stitching, rigid folds at the hip" |
| Ground | "realistic street" | "wet asphalt with broken speculars, standing water in shallow depressions" |
| Motion | "she walks naturally" | "slow dolly-in, subject weight shifts, fabric settles one beat after each step" |
| Atmosphere | "cinematic mood" | "thin haze catching a single overhead practical, cool ambient fill, no lens flare" |
Notice that none of these rows mention resolution, model names, or quality buzzwords. Physical descriptions are portable across tools; quality adjectives are not.
Tool Selection: What to Look For
Capability differences between video generators matter more than benchmark scores. When evaluating a tool, prioritize these in order:
- Image-to-video strength. Most photoreal work is conditioned on a keyframe. If the model's image conditioning is weak, nothing else saves the shot.
- Reference capacity. How many reference images can you feed, and how does the model weight them? Two to four well-chosen references cover most scenes.
- Camera controls. Explicit dolly, pan, tilt, and zoom parameters make motion reproducible. Free-text camera prompts are less predictable but still useful.
- Maximum output resolution. Higher native resolution means less reliance on upscaling, which is where plastic-looking textures creep in.
- Determinism. Reusable seeds and versioned model checkpoints let you reproduce a shot months later. If a tool silently updates models, archive your outputs.
- Node or API access. If you plan to run multi-pass pipelines, an API or node graph environment such as ComfyUI matters far more than a polished web interface.
A practical stack for most creators is one strong image model for keyframes, one strong video model for motion, and one dedicated upscaling and restoration tool for finishing. Specialists beat generalists in each stage.
Common Mistakes and How to Fix Them
Re-rolling instead of diagnosing. If a shot fails three times, the problem is in the keyframe, the reference stack, or the prompt contract — not luck. Stop, identify which of the four failure modes you are seeing, and change one variable.
Overloading a single prompt. Ten competing instructions produce an average of all of them. Split the work into passes.
Ignoring shot size. Close-ups reward fine detail passes; wide shots reward atmospheric depth and set dressing. Applying the same prompt template to both produces the wrong texture scale.
Animating a frame you have not inspected at full resolution. Subtle hand or eye defects become motion nightmares.
Chasing perfect realism in every element. Photorealism is partly about imperfection: dust, asymmetry, uneven reflections, slight underexposure. Perfectly clean renders read as synthetic.
Forgetting sound and edit rhythm. Even flawless footage feels fake without room tone, footsteps that match the surface, and cuts that respect motion continuity.
Quality Control Checklist Before You Publish
- Play the clip at full speed, then at quarter speed, watching only the hands, eyes, and feet.
- Check the light direction at the first frame and the last frame; confirm they match.
- Scan for texture boiling in high-frequency areas such as gravel, foliage, and fabric pattern.
- Verify that every reflection has a plausible source in frame or just outside it.
- Compare the final grade against your reference still at three brightness levels.
- Watch with sound muted, then listen without the picture, to catch mismatched ambience.
- Confirm the clip still reads as intended on a phone screen — most viewers will see it there.
FAQ
How long should a photorealistic AI shot be?
Four to six seconds is the sweet spot for most pipelines. Shorter clips reduce drift; longer clips usually need to be stitched from multiple generations with matched keyframes.
Do I need a specific model to use Lego Pixel thinking?
No. It is a method, not a feature. Any tool with image conditioning, seed control, and a decent upscaler can support the workflow.
Why does my subject's face change when the camera moves?
The model is re-predicting identity from a changing viewing angle. Reduce motion amplitude, strengthen face references, and keep the first frame as close as possible to the reference pose.
Is it better to generate at high resolution or upscale?
Generate as high as your tool allows, then upscale modestly. Aggressive single-step upscaling invents detail that flickers in motion.
How do I fix plastic-looking skin?
Lower denoise on detail passes, add a reference with visible texture, and introduce a light grain pass. Smoothness is the enemy of realism.
Can I mix tools within one project?
Yes, and most professionals do. Keep your block inventory and light contract constant so outputs from different models still feel like the same scene.
What about audio?
Generated audio is improving, but photoreal work usually benefits from recorded ambience and foley layered underneath. Mismatched audio ruins otherwise convincing footage.
Key Takeaways
Photorealism in AI video is an assembly problem, not a rendering problem. Define your blocks, lock your keyframes, feed real references, animate the camera before the subject, and finish in passes. That discipline — building up from small, stable, well-specified units — is what the Lego Pixel idea is really about, and it works regardless of which generator you happen to prefer this month.
