
What "Lego Pixel" Actually Means in AI Video
The term Lego Pixel describes a way of thinking about generative imagery rather than a single button inside one app. The idea is simple: instead of treating an image or a video frame as one indivisible unit, you treat it as a set of small, controllable visual tiles. Each tile carries local information — a color, an edge, a texture, a lighting direction, a face, a piece of a costume. When you can address those tiles individually, you gain partial control over a generation that would otherwise be all-or-nothing.
The metaphor matters because it maps onto how modern diffusion and transformer-based video models actually work. These systems denoise latent representations that already encode spatial structure in a grid. Conditioning signals such as depth maps, pose skeletons, segmentation masks, and reference embeddings all inject information into that grid. Lego Pixel thinking is the practice of deliberately designing those injections — building a mosaic of constraints so the model has fewer plausible ways to go wrong.
In practice, most creators already use a crude version of this. They upload a reference image of a character and hope the face survives. They paste a style board and hope the color grade holds. The Lego Pixel approach turns that hope into a repeatable process: define the tiles, decide which ones are rigid and which are flexible, and then design a generation pipeline that respects both.
This guide is a workflow-oriented walkthrough. It covers the concepts, the preparation work, the fusion techniques, the consistency strategies, the tool choices, and the quality-control habits that separate a rough experiment from a deliverable that a client will sign off on.
Why Tile-Level Control Matters More Than Prompt Wording
Prompt engineering gets most of the attention, but text is a low-bandwidth channel. A paragraph of description can specify a mood and a subject, yet it cannot reliably specify that a jacket strap sits on the left shoulder in shot three and that the same strap stays on the left shoulder in shot nine. Text describes; tiles constrain.
The consistency problem in generative video
Generative video models hallucinate detail. It is not a bug; it is the mechanism. Every frame is a fresh prediction, and small sampling differences accumulate. Over a thirty-second sequence, the accumulation shows up as costume drift, changing hairline, shifting eye color, morphing background architecture, and lighting that swings between takes.
Editors describe this as the "vibe shift" problem: each shot looks good on its own, but cutting them together reveals that they belong to different films. Fixing it after the fact is expensive. Fixing it before generation is cheap.
How patch-based conditioning changes the outcome
When you supply the model with structured local constraints, you reduce the generative search space. A depth map tells the model where surfaces are. A pose skeleton tells it where limbs go. An instance mask tells it which pixels belong to the protagonist. A tile grid of reference crops tells it which textures and colors are allowed to appear.
The result is not merely more accurate — it is more stable. Constrained regions change less between frames because the model has a consistent anchor to reconcile against. Creators who adopt tile-level control often report that they spend less time re-rolling and more time composing.
Building a Reference Kit Before You Generate
Most failed generations trace back to weak inputs. Before opening any generation tool, assemble a reference kit. Treat it as the raw material for your mosaic.
Choosing reference images that survive encoding
Models compress and resample whatever you feed them. Thin lines, high-frequency textures, and noisy gradients degrade badly. Prefer references with:
- Clean separation between subject and background
- Even, directional lighting rather than flat front flash
- A resolution high enough to survive downscaling but not so high that compression artifacts dominate
- Multiple angles of the same subject if the character appears in more than one shot
If you only have one usable photo, generate a turnaround: front, three-quarter, profile, back. Even imperfect synthetic turnarounds help the model hold identity across camera moves.
Preparing mosaics, grids, and style boards
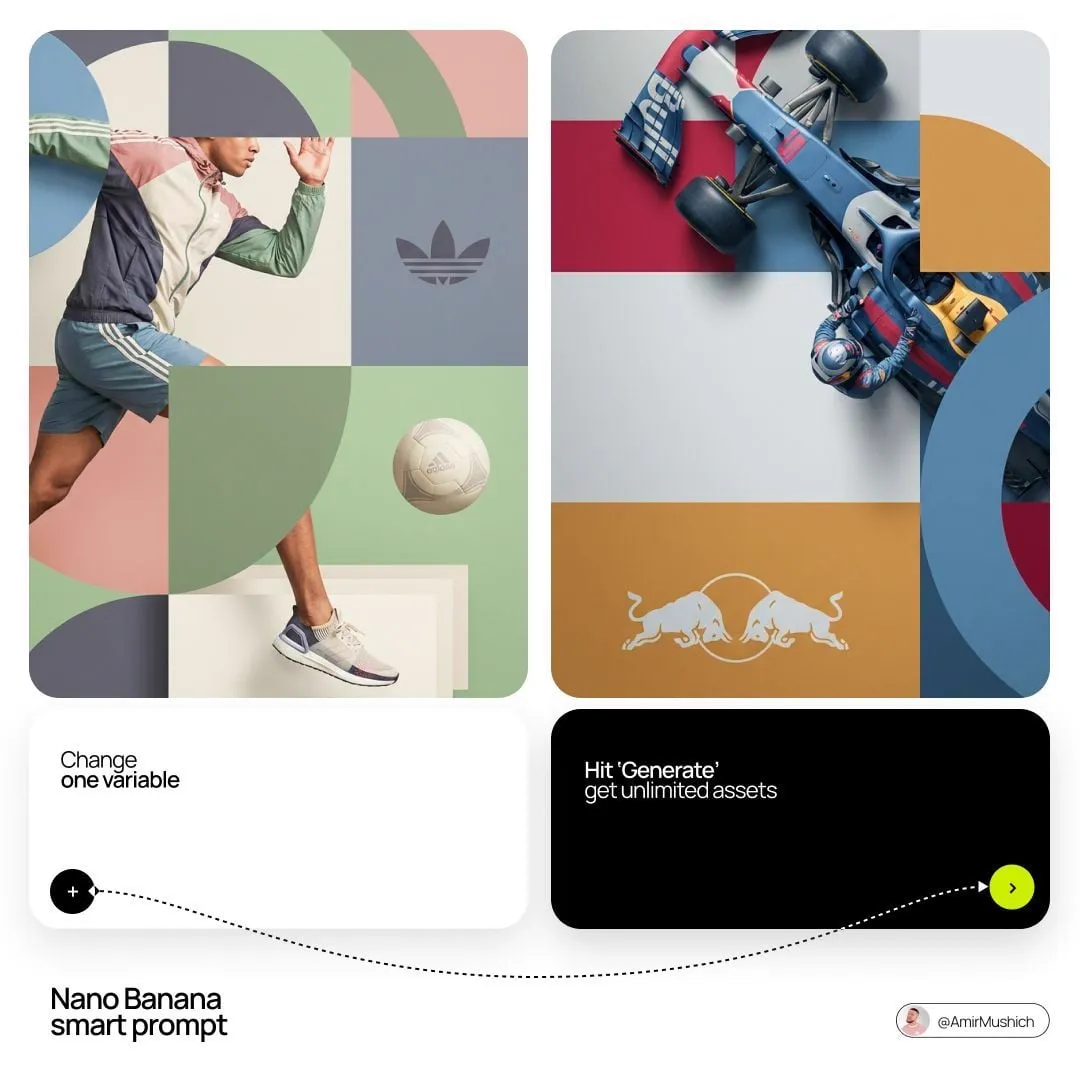
A mosaic is a single image containing several controlled crops. Build one for the character, one for the environment, one for color and lighting, and one for props that must remain continuous. Keep each tile roughly square or consistently proportioned, and leave a neutral gutter between tiles so the model does not bleed information across boundaries.
Label your tiles mentally by role: identity anchor, style anchor, lighting anchor, negative anchor. When a generation drifts, you will know which tile to strengthen and which to soften.
Multi-Image Fusion: Practical Techniques
Fusion is where tile-level control becomes an actual craft. The goal is a coherent image or frame that draws from several sources without looking stitched together.
Layering subject, style, and lighting references
Give each reference a job and only one job. Use the identity reference for the face and body proportions. Use the style board for rendering language — painterly, photographic, cel-shaded, grainy film. Use the lighting reference for direction, contrast ratio, and color temperature.
When one image carries two jobs, results get muddy. A style board that also contains a face will leak that face into your protagonist. A lighting reference shot at golden hour will drag warmth into a scene you wanted cold.
Weighting and blending without muddiness
Weighting is the dial that most creators ignore. If your identity reference is weighted too high, the model reproduces the reference pose instead of the pose you asked for. Too low, and the face drifts within two seconds of motion.
A practical starting point: identity at moderate strength, style at moderate strength, lighting at low strength, and motion or pose driven by structural conditioning rather than by the reference images. Adjust one variable at a time across short test clips — three to five seconds is enough to see drift.
For seamless blends, match your references at the color level before generation. Pull them into the same working color space, neutralize white balance where appropriate, and normalize contrast. The model is far more likely to fuse them gracefully when they already agree on fundamentals.
Keeping Shots Consistent Across a Sequence
Single-frame quality is table stakes. Sequence consistency is where reputations are made.
Locking a visual bible
Write a short visual bible: palette with hex values, lens choices, lighting direction per scene, costume continuity notes, and a shot list with reference tiles attached. This document is the contract between your references and your generations. Any prompt you write should be traceable back to it.
The visual bible also protects you during revision. When a client asks for "warmer," you know exactly which lighting anchor to change and which other shots inherit that change.
Repairing drift with re-anchoring passes
Drift is normal. Plan for it. Reserve a re-anchoring step where you regenerate the tail end of a shot using the last clean frame as the new identity anchor. This technique — sometimes called frame chaining or last-frame seeding — pulls the model back toward continuity without resetting the whole sequence.
If drift is systematic, the cause is usually upstream: your identity tile is too weak, your style tile is fighting your lighting tile, or your motion is too fast for the model to hold detail. Slow the motion, strengthen the anchor, or reduce the number of simultaneous constraints.
A Step-by-Step Workflow for a Short Branded Spot
Here is a concrete pipeline you can adapt to almost any short-form project.
- Lock the intent. One sentence describing the emotional arc. Example: a runner moves from an overcast street into warm light.
- Build the tile kit. Four mosaics: runner identity, street environment, interior environment, and a lighting transition board.
- Block the shots. Six shots, four seconds each. For each shot, decide what must be rigid (face, logo placement, costume) and what can float (background pedestrians, cloud shapes).
- Generate keyframes first. Create one strong still per shot before animating. Approving a still is cheaper than approving eight seconds of video.
- Animate with structural conditioning. Feed pose or depth information to hold the blocking while the diffusion pass handles texture and light.
- Chain and re-anchor. Use the approved last frame of shot one as the seed for shot two's first frame where continuity matters.
- Assemble and normalize. Cut in your editor, apply a single grade across all shots, and add grain or diffusion to mask minor seams.
- Sound and finish. Audio does enormous work for perceived continuity. A consistent ambience bed and a unified music cue make cuts feel intentional.
Notice how little of this involves prompt wording. Prompts still matter, but they operate within a structure that tiles have already defined.
Tool Landscape and When to Use Each
Text-to-video, image-to-video, and video-to-video
Text-to-video is for exploration and mood boards. Image-to-video is for controlled shots where you already have a keyframe. Video-to-video is for restyling existing footage while preserving motion — the most controllable of the three, because the original plates already carry temporal structure.
If your project has continuity requirements, favor image-to-video with strong keyframes and use text-to-video only for inserts that do not touch your protagonist.
Node-based pipelines versus hosted editors
Node-based environments give you explicit control over conditioning stacks, blending weights, and sampling. They are ideal when you need reproducibility across dozens of shots. Hosted editors are faster to start and easier to hand off to a small team, but they tend to hide the weighting controls that make tile-level work effective.
A hybrid approach works well for most studios: prototype in a hosted tool to validate the look, then rebuild the approved look in a node graph for the production run. Keep a written record of every setting — a pipeline you cannot reproduce is a pipeline you do not own.
Common Mistakes That Break Visual Continuity
- Over-constraining the first shot. Stacking five strong references on shot one produces something beautiful and impossible to repeat. Build a look you can sustain for a whole sequence.
- Reusing one reference for every purpose. Identity, style, and lighting tiles should be separate. Combined references leak information.
- Ignoring color management. Mismatched white balance between tiles creates a permanent cast the model cannot resolve.
- Animating unapproved stills. Every second spent animating a frame you will discard is wasted compute and wasted attention.
- Chasing drift instead of preventing it. Ten re-rolls cost more than one well-built anchor tile.
- Forgetting the cut. Some inconsistencies disappear at the cut point. Do not spend hours fixing a defect that never reaches the audience because the shot is 0.4 seconds long.
- No versioning. Name files by shot, take, and date. You will need to roll back, and you will not remember which file was the good one.
Quality Control Checklist Before Delivery
Run the same review every time to build reliable instincts:
- Play the sequence at full speed with sound before reviewing individual frames.
- Watch at 25% speed to catch micro-drift in faces and hands.
- Check the first and last frame of every shot against the adjacent shots for palette jumps.
- Confirm all logos, text, and branding elements are legible and correctly spelled.
- Verify aspect ratios and safe areas for each delivery platform.
- Inspect shadows and contact points — floating feet and sliding objects are the most common tells.
- Confirm the grade holds on both a calibrated display and a phone screen.
If a shot fails two or more checks, regenerate it rather than patching it. Patched footage tends to retain the original problem in a subtler form.
Frequently Asked Questions
Is Lego Pixel a specific software feature?
No. It describes a methodology — controlling generation through small, independently addressable visual tiles and conditioning signals. You can apply it in almost any modern video generation pipeline.
Do I need a node-based tool to use this approach?
It helps, because node graphs expose weighting and blending. But you can get most of the benefit in simpler tools by preparing better mosaics, separating your reference roles, and re-anchoring shots deliberately.
How many reference images should I supply?
Three to five well-chosen, single-purpose references usually outperform a dozen mixed ones. More references increase conflict, not control.
Why does my character's face change when the camera moves?
Camera motion forces the model to synthesize new angles it has never seen. Supply a turnaround or multiple angles in your identity mosaic, and keep fast camera moves to a minimum on close-ups.
What causes a color shift between shots?
Usually mismatched reference tiles, inconsistent lighting descriptions in prompts, or a grade applied per shot instead of across the sequence. Normalize references first, then apply one master grade.
How long should a test clip be before I commit?
Three to five seconds. That is long enough to reveal drift and short enough to iterate cheaply.
Can this workflow handle long-form projects?
Yes, but it scales by discipline rather than by magic. Build the visual bible, keep the tile kit versioned, and treat every scene as a sequence with its own continuity anchors.
What is the single highest-leverage habit?
Approving stills before animating. It converts an expensive, ambiguous revision loop into a cheap, concrete one — and it is the habit most creators skip.
Where to Go From Here
The shift from prompt-led generation to tile-led generation is a shift in mindset. You stop asking a model to invent a world and start assembling that world from controlled pieces. The toolkit changes — mosaics, masks, depth and pose conditioning, weighted references, re-anchoring passes — but the underlying principle stays the same: reduce ambiguity, and consistency follows.
Start small. Take one shot you have already made, break it into its visual constituents, rebuild it with a proper reference kit, and compare the two versions. Then repeat the process across a three-shot sequence and watch how much less time you spend re-rolling. Once that loop feels natural, scale it to a full scene, then to a full piece. The creators who produce reliable generative video are rarely the ones with the most exotic prompts; they are the ones who built the better mosaic before pressing generate.
