
Why Luma Dream Machine Changed the Conversation
Most people meet AI video through a moment of disbelief. They type a sentence, wait a minute, and a moving image appears that looks like it was shot by someone with a camera, a crew, and an opinion about lighting. Luma Dream Machine is one of the tools that produced that reaction at scale, and it remains one of the most useful generative video systems for creators who care about motion quality rather than novelty clips.
The interesting part is not that it can generate video. Plenty of systems can. The interesting part is how it handles motion: how objects travel through a scene, how the camera behaves, how a subject keeps its shape as it turns, and how light stays consistent from the first frame to the last. Those qualities determine whether a generated clip is usable in a real edit or whether it is a curiosity you delete after showing it to three friends.
This guide is a practical walkthrough of how to work with Dream Machine as part of an actual production pipeline. It covers prompt construction, camera language, image-to-video workflows, keyframes, character consistency, comparison criteria for choosing between video models, and the post-production steps that turn raw generations into finished shots. If you have experimented with AI video and felt that the results were impressive but unusable, this is written for you.
What Dream Machine Does Well, and Where It Still Struggles
Before building a workflow around any model, it helps to understand its bias. Every video generation system has one — a set of conditions under which it produces great output, and another set where it falls apart.
Strengths worth designing around
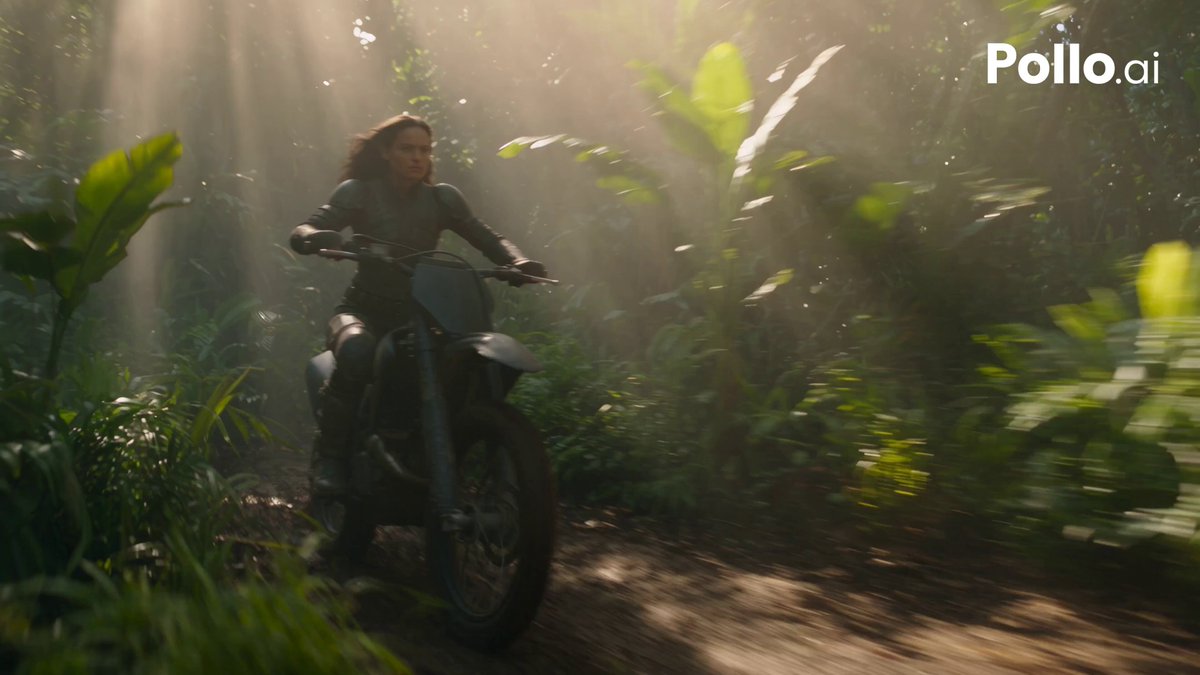
Atmospheric and environmental motion. Fog drifting through trees, waves breaking, dust catching backlight, rain on pavement, crowds moving in a plaza. Dream Machine handles these ambient layers with a naturalism that reads as filmed rather than synthesized. If your shot depends on environment as much as subject, this is a strong fit.
Camera movement. Push-ins, orbits, tracking shots, crane moves, and handheld drift are all achievable through natural language. The model does not need rigid numeric parameters; it interprets phrases like "slow dolly forward" the way a camera operator would.
Image-to-video fidelity. When you start from a still image, the model preserves composition, palette, and subject identity remarkably well. This makes it an excellent animation layer for illustrators, product photographers, and concept artists who already have strong static assets.
Short-form realism. Clips of three to ten seconds with a single clear action tend to be the sweet spot. That maps perfectly onto social formats, b-roll, insert shots, and cinematic transitions.
Where results degrade
Complex hand interactions. Fine motor actions — fingers typing, hands passing objects, someone buttoning a coat — remain a weak point across the entire category. Design shots that keep hands out of close frame or partially obscured.
Long continuous takes. Coherence drifts as duration increases. A character's jacket changes shade, a background building shifts position, or an extra disappears. Treat every clip as a building block, not a scene.
Text and signage. Any legible writing on screen will warp. Add signage in post, not in the prompt.
Precise choreography. If you need a specific sequence of events in a specific order within one clip, you will fight the model. Break the sequence into separate shots and cut them together.
Building a Prompt Framework That Actually Repeats
Random prompt writing produces random results. The fix is a consistent sentence structure that covers the same six variables every time, so that when a clip fails you can isolate which variable caused it.
The six-variable structure
- Subject — who or what, with one or two defining details. "A weathered fisherman in an oilskin coat" beats "a man."
- Action — one verb, present tense. Two actions in one clip usually produces neither.
- Environment — location plus one atmospheric detail. "A stone harbor at low tide, morning mist."
- Camera — shot size plus movement. "Medium shot, slow push in."
- Light — direction and quality. "Raking golden light from camera left, soft shadows."
- Texture — the filmic reference. "Fine grain, shallow depth of field, natural color."
Assembled: A weathered fisherman in an oilskin coat mends a net on a stone harbor at low tide, morning mist drifting, medium shot with a slow push in, raking golden light from camera left, fine grain and shallow depth of field.
That prompt will not generate a masterpiece every time, but it will generate something in the right neighborhood, and you can adjust one variable at a time instead of rewriting everything.
Camera vocabulary that works
Dream Machine responds well to established film language. Useful phrases include: slow push in, pull back, orbit left, arc around subject, handheld tracking, crane up, tilt down, rack focus, static locked-off, drone descend, and dolly zoom. Pair each with a shot size — wide, medium, close-up, extreme close-up — and you have a complete camera instruction in a few words.
Avoid stacking movements. "Orbit while pushing in and tilting up" produces mush. One movement per clip, then cut.
What to leave out
Do not describe what you do not want. "No blur, no distortion, no extra fingers" tends to summon those exact problems. Instead, describe a state where the problem cannot exist: "hands resting at sides," "a single figure on an empty street," "sharp focus on the subject's face."
Also skip emotional adjectives that have no visual translation. "Melancholic" means nothing to a diffusion model. "Overcast light, muted palette, slow movement" means everything.
Image-to-Video and Keyframe Workflows
Text-to-video is the flashy demo. Image-to-video is where real production happens, because it lets you control composition before spending any generation time.
Start from a still you already trust
If you have a storyboard frame, a rendered 3D still, a photograph, or a digital painting, that image is your anchor. The model's job is to add motion and time, not to invent the frame. This dramatically improves consistency across a sequence, because every clip inherits the same palette and design language from its source image.
A practical approach for a product spot: photograph or render six hero angles of the product, then animate each one with a small, controlled movement — a slow orbit, a light sweep, a subtle rack focus. Six clips, cut on the beat, and you have a spot that looks intentional rather than generated.
Use keyframes for transitions
When a model supports start and end frames, you can define both ends of a transition and let it interpolate. This is enormously useful for:
- Match cuts between two locations that share a shape or color
- Transformation shots where one object becomes another
- Reveal shots where a closed frame opens into a wide vista
- Looping clips where the end frame matches the start frame for seamless repetition
The constraint is that both frames must be visually compatible. Jumping from a bright exterior to a dark interior mid-clip usually produces a smeared hybrid. Introduce the change through a cut instead.
Extending and stitching
If you need a shot longer than a single generation, generate the clip, export the final frame, and use it as the starting image for the next segment. Repeat until you have the duration you need. Keep camera instructions consistent across segments or the motion will stutter at the seam. In the edit, hide the join with a cut on action, a whip pan, or a brief dissolve.
Maintaining Character and Style Consistency
Consistency is the hardest problem in AI video and the one that separates hobby output from client-ready work. There is no single button for it, but a combination of techniques gets you close.
Lock the character with reference images
Generate or obtain a clean, well-lit character portrait first. Then use that image as the seed for every shot featuring that character, varying only the pose, environment, and camera angle. Feeding the same reference across a sequence keeps facial structure, hair, and wardrobe stable.
Describe wardrobe in fixed language
Write your character description once and paste it verbatim into every prompt. Do not paraphrase. "Charcoal wool coat with brass buttons" in shot one and "dark grey jacket" in shot five will produce two different garments. Keep a text file with locked descriptors for each character, location, and prop, and copy from it.
Control palette at the project level
Decide on a limited palette before generating anything — three or four dominant colors plus a skin tone. Mention those colors in prompts for environments and wardrobe. Consistent palette makes inconsistent details far less noticeable, which is how real productions cover continuity gaps.
Accept the cut as a tool
Editors solve continuity problems by not showing the problem. If a character's appearance drifts between shots, keep the camera further back, use over-the-shoulder framing, or insert a reaction shot between the two problem clips. Audiences are extremely tolerant of cuts and extremely intolerant of morphing faces.
Assembling a Full Production Pipeline
A repeatable pipeline is what makes AI video sustainable rather than exhausting. Here is a structure that works for commercial work, narrative shorts, and content marketing alike.
Stage one: pre-production
Write a shot list before generating anything. Each row should have: shot number, duration target, subject, action, camera, environment, and audio intent. A ten-shot piece is a reasonable scope for a solo creator. Attach reference images or moodboard frames to each row so you are generating toward a target rather than exploring.
Stage two: generation
Generate three to five variations per shot. Save every output, even the failures — sometimes a rejected clip has one perfect two-second segment. Name files systematically: shot03_take02_camera-push.mp4. You will thank yourself during the edit.
Work in batches by shot, not by project. Generate all variations of shot one, pick the winner, then move on. Switching contexts constantly slows you down and makes it harder to judge which take is genuinely best.
Stage three: selection and assembly
Cut your chosen takes into a rough sequence with no effects. Watch it silent. If the sequence does not read without sound, more generation will not fix it — the shot design is wrong. Fix pacing by trimming, not by regenerating.
Stage four: post-production
Strengthen the weak points of generated footage:
- Stabilization if camera motion wobbles
- Slight speed changes to fix unnatural motion cadence — often 90% or 110% is enough
- Color grading to unify clips from different generations
- Film grain or texture overlays to blend generated shots with real footage
- Sound design — footsteps, room tone, cloth movement, and ambience do more for believability than any visual tweak
- Music that matches the edit rhythm rather than fighting it
Sound is the most underrated step. A mediocre visual with excellent sound reads as professional. A stunning visual with silence reads as a demo.
Choosing Between Video Models: Decision Criteria
Dream Machine is one option among several strong systems, and the right choice depends on the shot rather than brand loyalty.
Choose Dream Machine when you need atmospheric realism, expressive camera movement, strong image-to-video behavior, or fast iteration on short cinematic clips.
Choose a different model when you need long-duration single takes, precise character animation with detailed rigging, stylized 2D animation, or lip-synced dialogue performance.
Practical evaluation checklist for any new model:
- How does it handle a slow push-in on a human face over five seconds?
- Does a light source stay fixed when the camera moves?
- Can it maintain wardrobe across three prompts using the same reference image?
- What happens with two characters interacting?
- How many attempts does a usable clip require?
Track the answer to that last question over time. Attempts per usable clip is the single best productivity metric in AI video, and it improves with prompt discipline far more than with model switching.
Common Mistakes and How to Fix Them
Overstuffed prompts. Five subjects, three actions, and four camera moves. Fix: one subject, one action, one movement.
Chasing realism with adjectives. "Photorealistic, 8K, ultra detailed, hyperreal" adds nothing. Fix: describe light, lens, and texture instead.
Generating without a shot list. You end up with twenty beautiful clips that do not cut together. Fix: plan first, generate second.
Judging clips in isolation. A clip that looks odd alone may be perfect in context. Fix: always review inside a timeline.
Ignoring motion cadence. Real cameras have weight. Generated motion can feel floaty. Fix: slight speed adjustments and stabilization.
Skipping sound. Fix: build a rough sound pass before you refine visuals.
Regenerating instead of trimming. Fix: cut the best two seconds out of a flawed five-second clip.
Frequently Asked Questions
How long should a single generated clip be?
For most work, three to eight seconds. Longer clips drift in coherence, so treat duration as something you build through editing rather than something you ask the model for.
Do I need strong prompt-writing skills?
You need structure, not poetry. The six-variable framework — subject, action, environment, camera, light, texture — covers the vast majority of shots.
Can I use generated clips commercially?
That depends on the terms of the specific platform you use and the laws in your jurisdiction. Read the current terms carefully and keep records of what you generated and when.
How do I stop characters from changing between shots?
Use a fixed reference image, paste identical wardrobe descriptions into every prompt, and limit how much the camera reveals. Consistency improves with restraint.
Is AI video ready for client work?
For b-roll, product inserts, social content, and stylized sequences, yes. For dialogue-driven narrative with complex human interaction, expect to combine generation with traditional shooting.
What is the fastest way to improve my output?
Build a shot list and a locked descriptor file. Most quality gains come from pre-production discipline, not from better prompts.
Should I animate stills or generate from text?
Start from stills when composition matters. Use text-to-video for exploration and mood, then convert the best ideas into reference images.
A Workflow Checklist You Can Reuse
Run this list for every project and the quality gap between attempts narrows fast:
- Define the deliverable: duration, aspect ratio, platform, tone.
- Build a shot list with one action per shot.
- Create or collect reference stills for every shot.
- Write locked descriptors for characters, locations, and props.
- Generate three to five takes per shot, named systematically.
- Select in a timeline, not in a file browser.
- Trim for pacing before regenerating anything.
- Stabilize, speed-adjust, and grade for visual unity.
- Build a full sound pass: ambience, effects, music.
- Watch the final cut on a phone, a laptop, and a large screen.
The tools will keep changing. New models will arrive with better motion, longer durations, and tighter control. What does not change is the underlying craft: plan the shot, control the variables, cut for rhythm, and let sound do the heavy lifting. Learn that discipline with Dream Machine today and it will transfer to whatever generation system you use next.
