
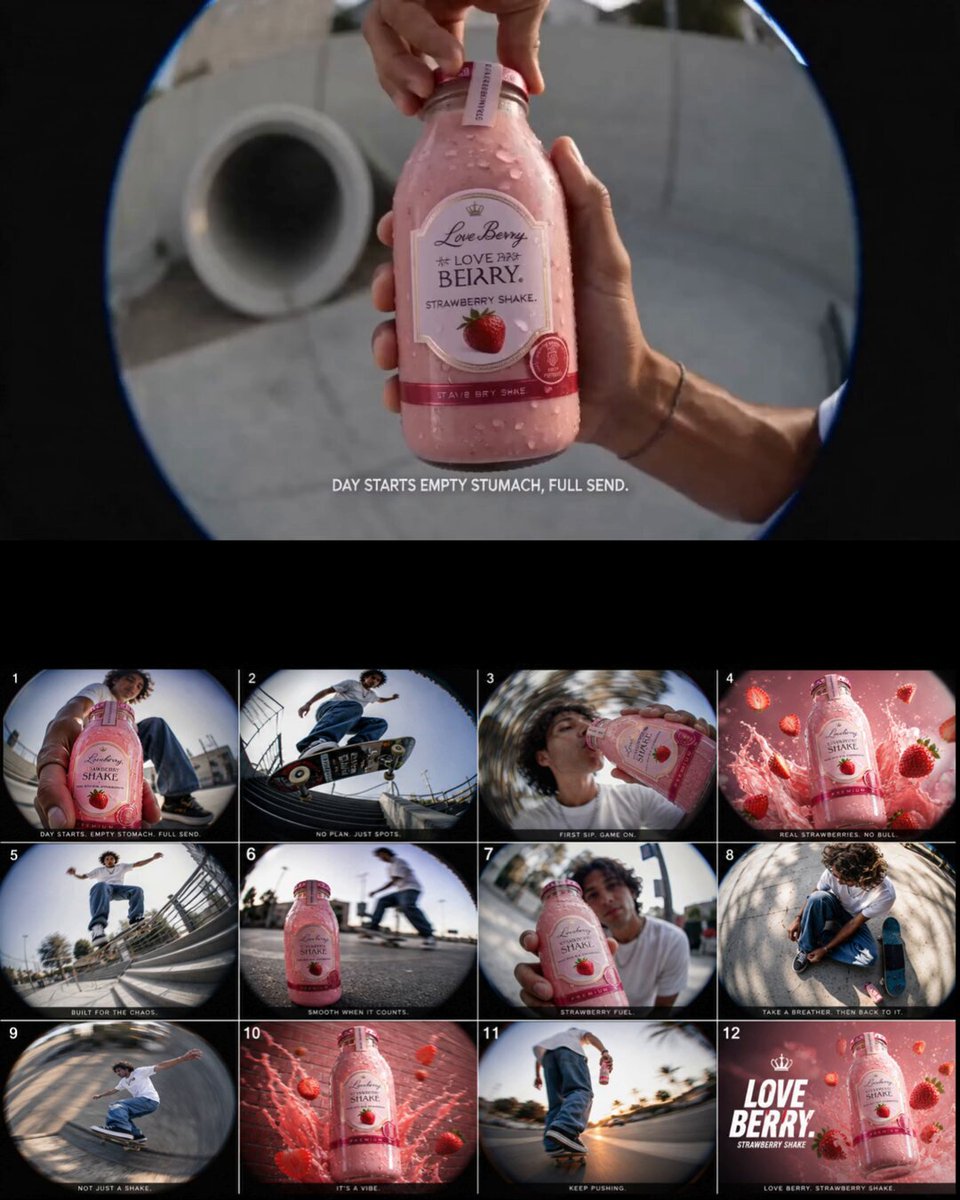
Two people type the same idea into the same video generator and get wildly different results. One gets a drifting, wobbly clip with a face that changes shape halfway through. The other gets a clean four-second shot that looks like it came off a real camera. The difference is almost never luck, and it is rarely the model. It is the prompt.
Video prompting is not writing a caption. It is closer to handing a shot list to a small crew that has never met you, cannot ask questions, and will fill every gap you leave with a generic default. The more gaps you leave, the more the model improvises. The more you define, the closer the output lands to what you pictured.
This guide walks through a complete, repeatable approach: the anatomy of a strong prompt, a template you can reuse, the vocabulary that actually changes what renders, consistency strategy across multiple shots, negative constraints, model-specific adaptation, a full shot-by-shot workflow, and the mistakes that cost people the most re-renders.
Why Prompt Quality Decides Your Output Quality
A video model is a conditional sampler. It takes your text (and any reference images, audio, or control signals) as a condition, then generates the most probable visual sequence that satisfies that condition. Every word narrows the probability space. Vague words barely narrow it at all, which is why generic prompts produce generic footage.
The practical consequence is that prompt quality has an outsized effect on three things:
- Hit rate. A well-constructed prompt often lands usable footage on the first or second attempt. A vague one rarely does, and repeated vague attempts drift in random directions rather than converging.
- Directability. When the prompt specifies where the light comes from and how the camera moves, the result feels intentional. When it does not, motion becomes decorative noise.
- Editability. Shots that obey a consistent style, lens logic, and screen direction cut together. Shots generated in isolation usually do not.
The most useful mental shift is to stop thinking of a prompt as a description and start thinking of it as an instruction set: subject, action, environment, style, light, lens, movement, timing, and exclusions. A description tells someone what something looks like. An instruction set tells someone what to do.
The Anatomy of a Video Prompt That Actually Works
A production-ready video prompt generally has five layers. You do not need all five in every prompt, but you should be able to name which ones you are deliberately leaving out.
Subject and action
Name the subject precisely, then give it something to do. The action is what produces motion, and motion is the thing video models are actually bad at faking.
Weak: a woman in a cafe.
Stronger: a woman in her late thirties, cropped wool coat, sits at a window table and slowly lifts a ceramic cup with both hands, steam rising past her face.
The second version gives the model a clear start state, a clear end state, and a physical relationship between objects. That structure is what keeps hands from melting into cups.
Style and medium anchors
Style language sets the whole rendering regime: documentary realism, 16mm grain, stop-motion, cel animation, analog VHS, architectural visualization, claymation, animation-style shading. Pair a medium with a reference era or technique rather than a brand name. Instead of naming a specific camera package, describe the look: shallow depth of field, slight halation around highlights, cool shadows with warm skin tones.
Lighting and atmosphere
Lighting is the single highest-leverage layer in the whole prompt, and the one most often skipped. Specify direction, quality, color, and motivation:
- Direction: backlit, side-lit from camera left, top-down, underlit from a laptop screen.
- Quality: hard noon sun, soft overcast diffusion, bounced fill, hard bare bulb.
- Color: tungsten warm, blue hour, sodium vapor orange, green fluorescent.
- Atmosphere: haze, dust motes, rain, fog, smoke, blown-out window light.
Motivated light is the term worth stealing from film production. It means the light has an on-screen source, like a lamp, a window, or a screen. Motivated light instantly makes generated footage feel shot rather than synthesized.
Camera, lens, and movement
Be explicit about shot size, angle, and move. Models respond strongly to these because they map to training data that was labeled with real camera language.
- Shot size: extreme close-up, close-up, medium, medium wide, wide, establishing aerial.
- Angle: eye level, low angle, high angle, over-the-shoulder, Dutch tilt (use sparingly).
- Move: locked-off, slow push in, pull back, pan left, tilt up, handheld follow, orbit around subject, crane rise.
- Lens feel: 24mm wide with barrel distortion, 50mm natural, 85mm portrait compression, macro detail, anamorphic flare.
One move per shot. Two moves in one prompt produce mush, because the model tries to satisfy both simultaneously and averages them.
Continuity notes
If the shot belongs to a sequence, say so: same wardrobe as previous shot, same location, same time of day, same color grade, screen direction preserved. These notes cost a few words and save entire re-render cycles.
A Repeatable Prompt Template and Iteration Loop
A template removes decision fatigue and makes your failures diagnosable. Here is a structure that works across most text-to-video and image-to-video systems:
[Shot size] of [subject with 2-3 specific visual details], [action in present tense], in [environment with 1-2 details], [time of day], [lighting: direction + quality + color], [lens and depth of field], [camera move], [style or medium], [grade and mood], [duration or pacing note].
Example: Medium close-up of a bicycle courier in a soaked yellow rain jacket, breathing hard and checking a phone, standing under a concrete overpass at night, lit by a single overhead sodium lamp from above and behind, 50mm with shallow depth of field, slow handheld push in, documentary realism, cool shadows with warm skin tones, unhurried pacing.
The four-step iteration loop
- Draft. Write the full prompt from the template without editing yourself.
- Render a short test. Generate the shortest duration the model allows. You are testing composition and motion logic, not final quality.
- Diagnose against the prompt. Go layer by layer: is the subject right? Is the light coming from the right side? Is the move the one you asked for? Name the specific layer that failed.
- Rewrite only that layer. Change one variable at a time. If you rewrite everything after every bad render, you learn nothing and you cannot reproduce your wins.
Keep a prompt log
Track each attempt with the prompt text, the model settings, and a one-line note about what broke. After twenty shots you will have a personal vocabulary list of phrases that work and phrases that the model ignores. That log is worth more than any generic prompt collection, because it is calibrated to your specific models and your specific look.
Vocabulary That Changes What the Model Renders
Some words are load-bearing and some are decoration. Learn the difference.
High-impact terms:
- Shot size and angle words (close-up, wide, low angle)
- Named camera moves (push in, orbit, dolly, tilt, rack focus)
- Lighting direction and quality (backlit, soft key, hard shadow, rim light)
- Time of day and weather (blue hour, golden hour, overcast, drizzle)
- Material and texture (brushed steel, corduroy, wet asphalt, dusty glass)
- Lens characteristics (macro, anamorphic, telephoto compression, wide distortion)
- Color grade language (bleach bypass, teal and orange, desaturated pastel, high-contrast monochrome)
Low-impact terms that need support:
- Emotional adjectives alone: epic, beautiful, stunning, cinematic. These are meaningless without a physical cause. Cinematic is fine if you immediately define it: shallow focus, motivated practical light, slow movement, wide aspect ratio.
- Abstract concepts: freedom, loneliness, nostalgia. Convert them into visible facts. Loneliness becomes a wide shot of one figure at a table set for six.
- Intensity adverbs: very, extremely, highly. Replace with measurable language: high-contrast, blown highlights, dense fog, 90 percent shadow.
A useful rule: if a word cannot be photographed, replace it with something that can.
Consistency Across Shots: Characters, Wardrobe, and Locations
Single-shot quality is a solved-ish problem. Multi-shot consistency is where most projects fall apart. Faces shift, jackets change color, streets rearrange themselves between cuts.
Four techniques do most of the work:
Build a character sheet
Write a fixed block of text describing your character, and paste that exact block into every prompt that features them. Do not paraphrase it between shots. Small wording changes cascade into visible changes. Include age range, hair, distinguishing features, wardrobe with colors and materials, and posture or gait.
Anchor the environment
Do the same for locations. A location block lists architecture, materials, dominant colors, light sources, and signature details. When a scene needs a new angle, change only the camera layer and keep the environment block byte-for-byte identical.
Use reference images and seeds
Image-to-video and multi-image reference workflows give you far more control than text alone. A single well-chosen still can lock wardrobe, face structure, and color palette. Where the tool exposes a seed value, reuse it to stabilize the underlying noise pattern while you vary the prompt.
Control the color script
Decide the palette for each scene before you generate anything. If scene one is warm amber and scene two is cold cyan, make the grade language explicit in every prompt of each scene. Consistency feels intentional when it is systematic and sloppy when it is accidental.
Negative Prompting and Constraint Writing
Negative prompting is the art of telling the model what not to render. It is most effective against a short list of recurring artifacts:
- Extra fingers, distorted hands, duplicated limbs
- Text and watermarks, garbled signage
- Warping faces during camera movement
- Flickering or strobing exposure
- Morphing background architecture
- Unwanted style bleed, such as cartoon shading in a realistic prompt
- Split screens, letterboxing, or frame borders
Two cautions. First, negatives have diminishing returns: a wall of forty exclusions dilutes the influence of the ones that matter. Keep negatives focused on the three or four problems you actually saw in your last render. Second, avoid negatives that fight your positives. Excluding motion while asking for a push-in creates a conflict the model resolves randomly.
Positive constraints are often more reliable than negatives. Instead of excluding a busy background, specify a clean, empty background. Instead of forbidding text, state that the scene contains no signage and no visible lettering.
Matching Your Prompt to the Model Type
Different generation modes reward different prompt structures. Choosing the right mode is half the battle.
- Text-to-video. Best for establishing shots, abstract sequences, and anything where exact identity does not matter. Prompts must carry all the visual information themselves, so they run long.
- Image-to-video. Best for character work and product shots. The prompt's job shifts: describe motion, camera, and atmosphere, and let the still handle appearance. Overwriting the subject description here often causes the model to fight the reference image.
- Multi-image reference. Best for sequences requiring the same character or location across several shots. Supply several angles, then keep the text prompt minimal and focused on action and camera.
- Video-to-video restyling. Best for changing look while preserving performance. Describe only the target style, grade, and material qualities. Do not re-describe the action; the source footage already defines it.
- Models with native audio. Add sound design to the prompt: room tone, footsteps on gravel, distant traffic, a single sustained note. Audio cues also improve motion realism because the model ties physical events to sound events.
A simple decision rule: the more your shot depends on a specific face, product, or location, the more you should move away from pure text and toward reference-driven modes.
A Shot-by-Shot Workflow for a 30-Second Sequence
Here is a concrete pipeline for a half-minute piece, roughly six shots.
Step 1: Write the beat sheet. Six beats, one sentence each. Example: a courier leaves a doorway, rides through traffic, checks a phone at a stop, arrives at a glass office tower, hands over a package, walks away into rain.
Step 2: Assign a shot size and move to each beat. Vary rhythm deliberately. Wide for context, close for emotion, and never two identical shot sizes back to back unless you want a deliberate match cut.
Step 3: Write the reusable blocks. One character block, one location block per location, one style-and-grade block for the whole film. These are your constants.
Step 4: Write each shot prompt by combining constants with shot-specific layers: size, action, camera move.
Step 5: Generate short tests at minimum duration and review them as a sequence, not individually. Screen direction, grade, and wardrobe consistency only reveal themselves in the cut.
Step 6: Re-render only the failures. Upgrade successful shots to final length and resolution, then lock them.
Step 7: Assemble and grade. Even light color correction and a consistent sound bed will do more for perceived quality than another generation pass. Real productions do not rely on raw footage, and neither should you.
Common Mistakes and How to Fix Them
Stacking multiple camera moves. Fix: one move per shot. If you need a compound move, split it into two shots and cut.
Writing a paragraph of backstory. Fix: models do not render motivation. Convert every emotional intent into a visible action or a lighting choice.
Changing ten things between attempts. Fix: change one layer at a time so you know what worked.
Ignoring aspect ratio and duration. Fix: decide delivery format first. Vertical social cuts need different compositions and much closer shot sizes than widescreen.
Over-describing in image-to-video mode. Fix: describe motion, camera, and atmosphere only. Let the reference still define appearance.
Forgetting negative constraints entirely. Fix: keep a standing negative list of three to five recurring artifacts.
Judging shots in isolation. Fix: review in sequence. Continuity errors are invisible in a single frame and obvious in a cut.
Chasing realism when stylization would be stronger. Fix: pick a medium and commit. Half-realistic footage with inconsistent detail reads as broken, while fully stylized footage reads as a choice.
No prompt log. Fix: keep one. Reproducibility is the difference between a hobby and a workflow.
Rendering at maximum length first. Fix: test short, then extend. Long renders hide composition errors under motion.
Pre-Render Checklist and FAQ
Quick pre-render checklist
- Shot size and angle specified
- Exactly one camera move
- Lighting direction, quality, and color defined
- Motivated light source named
- Character and location blocks copied verbatim
- Style and grade language consistent with neighboring shots
- Three to five targeted negatives
- Duration and aspect ratio set to delivery spec
- Prompt logged with settings
Frequently asked questions
How long should a video prompt be?
Long enough to cover subject, action, environment, light, lens, and camera move, and no longer. In text-to-video mode that often means two to four dense sentences. In reference-driven modes, it can be a single sentence about motion and atmosphere.
Why does the model ignore part of my prompt?
Usually because the prompt contains conflicting instructions or too many competing details. Early words and physically concrete words carry more weight. Put the most important layer first and remove anything the model demonstrably ignores.
Do negative prompts really matter?
Yes, but only as a targeted tool. A short list aimed at artifacts you have actually seen works well. A long generic list mostly wastes prompt space.
How do I keep a character's face consistent?
Use reference images or multi-image workflows wherever available, keep a fixed text description block, reuse seeds, and avoid re-describing the face in different words between shots.
Should I write prompts in one language?
Write in the language your model handles best for the vocabulary you need. Camera and lighting terms are heavily represented in English training data, so mixing English technical terms into another language is common practice.
How many attempts should a shot take?
With a structured prompt, one to three is a healthy target. If you are past six, stop generating and rewrite the prompt from scratch rather than nudging it.
Can I reuse prompts across different models?
The structure transfers; the vocabulary does not. Each model has its own sensitivities. Keep the template and re-calibrate the phrasing for each engine you use.
The through-line across all of this is simple: video prompting rewards specificity, structure, and discipline more than creativity alone. Treat the prompt as a shot list, iterate on one layer at a time, keep your constants locked, and review your output as a sequence rather than a collection of clips. Do that consistently and you will spend your time editing good footage instead of re-rolling bad footage.
