
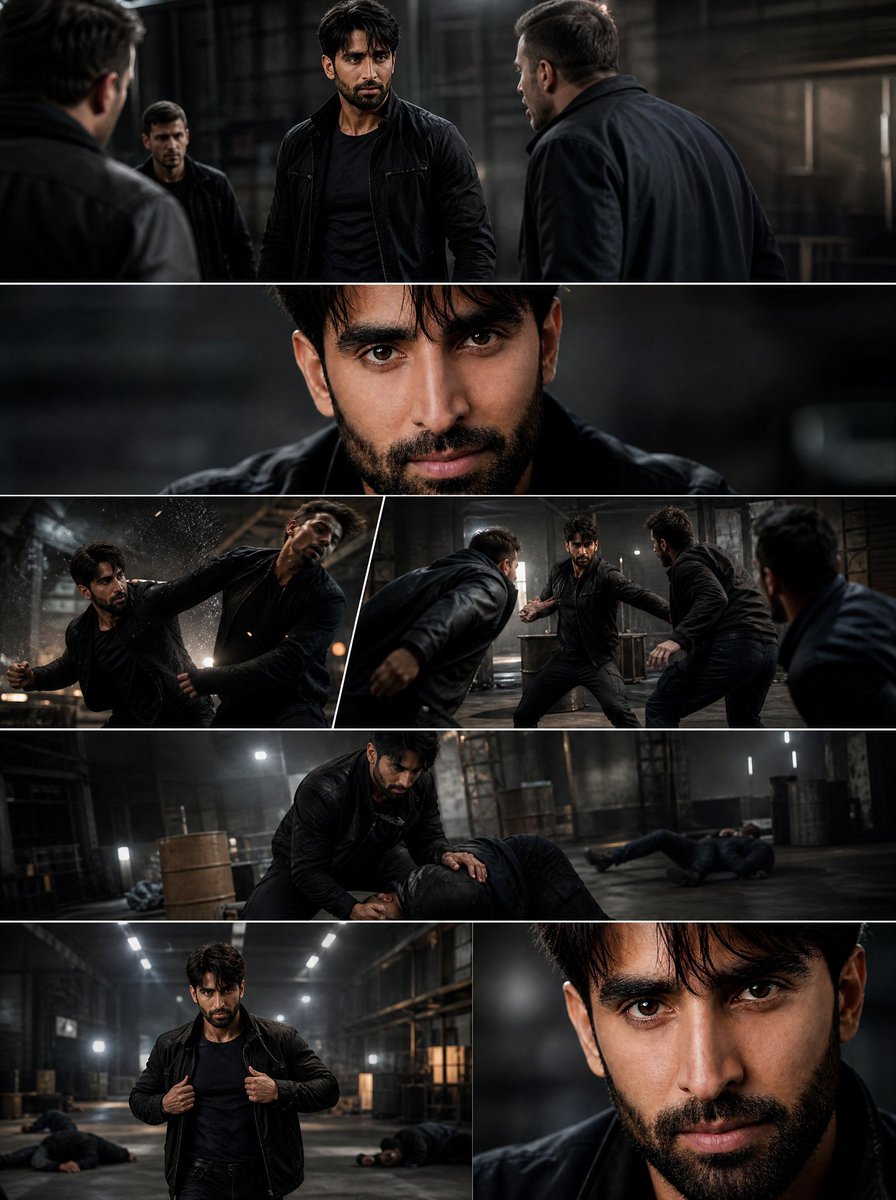
Text-to-image generation has quietly crossed a threshold. What used to be a novelty that produced dreamlike, slightly melted pictures now routinely delivers frames you could place in a product page, a storyboard, or a film pre-visualization deck without apologizing for them. Microsoft's AI image stack sits near the center of that shift, combining large diffusion models with the cloud infrastructure, content-safety layers, and developer tooling that make the technology usable at scale.
This guide is a practical look at how text becomes a photorealistic frame: what the pipeline actually does, how to write prompts that survive contact with reality, how to keep a set of images consistent, and where most teams go wrong.
Why Photorealism Changed the Production Conversation
For years, AI imagery was judged on novelty. The interesting question was whether a machine could draw a bicycle, not whether the bicycle looked like it had been photographed on a real street with believable shadows.
The moment output became genuinely photographic, the economics changed. A marketing team no longer needs a photoshoot for every variant of a hero image. A game studio can block out environments before art production begins. A video team can generate key frames and animatics in hours instead of weeks. The value is not that the images are free — it is that iteration is cheap and fast, which means more exploration before committing to a final direction.
Three technical developments made this possible:
- Latent diffusion moved computation into a compressed representation of the image, so high resolution stopped requiring absurd amounts of processing.
- Better text encoders and conditioning meant prompts were understood semantically, not just as keyword soup.
- Sampling improvements reduced the number of steps needed to reach a clean image, cutting generation time and artifacts simultaneously.
What remains hard is control. Realism is now a baseline expectation; the differentiator is whether you can make the model do exactly what you need, repeatedly, across dozens of frames.
How a Diffusion Pipeline Turns Words Into Photographs
It helps to picture the pipeline as four cooperating parts: the text encoder, the diffusion model, the sampler, and the decoder. Each one has a distinct job, and most prompt frustration traces back to confusing them.
Latent space and why resolution stopped being the bottleneck
The diffusion model does not paint pixels directly. It denoises a compressed latent representation, then a decoder expands that latent into a full-resolution image. Because the heavy math happens in a smaller space, you can generate a 1024-pixel or larger image without the cost scaling linearly. The practical consequence: you can afford to generate several candidates per concept and pick the best one, which is how professional workflows actually operate.
Schedulers, guidance scale, and step count
A scheduler decides how much noise to remove at each step. Fewer steps means faster output but often softer detail; more steps means finer texture with diminishing returns. Guidance scale controls how strictly the model follows your prompt. Push it too low and you get an attractive image that ignores your instructions. Push it too high and you get a brittle, over-contrasted image with odd anatomy and crunchy edges.
A useful starting range for photographic work is a moderate guidance value with a step count that gives the scheduler enough room to resolve texture. If skin looks waxy, lower guidance slightly. If the composition drifts away from your prompt, raise it in small increments.
What the text encoder actually contributes
The text encoder converts your prompt into a numeric representation that conditions the denoising process. It is why word order and specificity matter. "A woman in a red coat on a rainy street" and "a rainy street with a woman, red coat" produce different compositions, because one phrasing foregrounds the subject and the other foregrounds the environment.
The encoder also explains why negation behaves strangely. Models respond better to describing what you want than to listing what you do not want, because the conditioning signal is built from the positive content of your words.
Prompting for Photographic Fidelity
Most disappointing AI images are not model failures. They are under-specified briefs. A photographer would never accept "portrait of a person" as an assignment, and neither should you.
The four-part prompt: subject, light, lens, environment
A reliable photorealistic prompt covers four dimensions:
- Subject — who or what, with enough specificity to constrain age, material, wardrobe, or state.
- Light — the single biggest driver of realism. Name the source, direction, and quality: soft window light from the left, hard midday sun, overcast diffusion, bounce off a white wall.
- Lens and camera behavior — focal length, depth of field, and any optical character you want. "85mm, shallow depth of field" reads very differently from "24mm, deep focus."
- Environment and context — the space, the time of day, the weather, the surface textures.
Example: Editorial portrait of a ceramicist in her fifties, hands dusted with clay, standing at a studio window, soft north-facing daylight from camera left, 85mm lens with shallow depth of field, worn wooden workbench in the background, muted earth tones.
That prompt gives the model a subject, a light, an optic, and a world. The result is far more likely to look photographed than generated.
Negative prompts and hard constraints
Negative prompts are useful, but treat them as a cleanup tool rather than a foundation. Typical entries include distorted hands, extra fingers, text artifacts, watermark, plastic skin, oversaturated colors, and blurry background. Combine a few high-impact negatives with a well-built positive prompt rather than stacking twenty negatives and hoping for the best.
Worked examples across use cases
Product shot: Matte black wireless earbuds on a brushed concrete surface, three-quarter view, single large softbox above and slightly behind, subtle reflection beneath, 100mm macro lens, clean neutral background, commercial catalog photography.
Environmental establishing frame: Fog-covered pine forest at dawn, low ground mist, cold blue ambient light with a faint warm glow on the horizon, 35mm lens, deep focus, muted cinematic color grade, no people.
Character reference: Portrait of a young engineer in a worn canvas jacket, neutral expression, three-quarter angle, soft diffused light from above, visible skin texture and fine facial hair, 50mm lens, plain grey backdrop, documentary photography.
Notice that each prompt names a photographic tradition. Anchoring to a genre — editorial, catalog, documentary, cinematic — gives the model a strong prior for how light and texture should behave.
Semantic Control Beyond the Prompt
Prompts are not the only control surface, and for production work they are often not the best one.
Layout, depth, and composition conditioning
Several generation systems accept structural guidance: a rough depth map, an edge map, a pose skeleton, or a simple blockout of shapes. Instead of describing where things go, you draw it. This is transformative for teams with existing layouts, because you can keep a composition locked while iterating on style, lighting, and material.
A practical pattern: generate a rough composition first, then use it as structural input for a higher-quality pass. You get the layout you designed with the realism of a fresh generation.
Reference images and style transfer without brand drift
Reference conditioning lets you supply an image whose lighting, palette, or texture should influence the output. Two cautions apply. First, a reference influences more than you expect — supplying a photo with a strong color cast will tint everything. Second, keep references in-house or properly licensed; using a competitor's imagery as a style anchor creates legal exposure even when the output is unrecognizable.
Consistency Across a Set: Characters, Products, and Worlds
A single beautiful frame is a demo. Twenty frames that look like they belong to the same production is a deliverable. Consistency is where most workflows break down, and where careful process pays off.
Character consistency depends on locking the variables that define identity: facial structure, hair, wardrobe, and the lighting setup. Write a short "character sheet" prompt block and paste it into every generation, changing only the pose, scene, and camera. If your tool supports it, seed reuse or identity reference features help enormously.
Product consistency is easier because the object is rigid. Keep the same camera angle family, the same light shape, and the same surface treatment. Vary only the context — studio, lifestyle, outdoor — while holding the object's scale and orientation stable.
World consistency means agreeing on a palette, a time of day, and a lens language. A series set in the same city at golden hour will feel coherent even if the subjects change completely.
A simple tracking habit: maintain a document with your locked prompt block, your negative list, your seed values, and the settings that produced approved frames. When a reviewer asks for "the same look but at night," you will have the exact starting point.
An End-to-End Workflow You Can Reuse
This sequence works for marketing assets, storyboards, and video key frames alike.
Step 1 — Write a creative brief, not a prompt. One paragraph describing audience, mood, subject, and intended use. If you cannot summarize the intent in prose, the prompt will be incoherent.
Step 2 — Build a locked style block. Light quality, lens, palette, and genre. This block travels unchanged through the entire set.
Step 3 — Draft at low fidelity. Generate small, fast variations to test composition ideas. Do not chase detail yet.
Step 4 — Select and refine. Pick the two or three strongest compositions. Rewrite the prompt to describe those specific images more precisely, tightening light direction and material detail.
Step 5 — Generate at full resolution. With the composition settled, run the final quality pass. Generate more candidates than you need; the best frame is rarely the first.
Step 6 — Apply structural conditioning if the layout must match an existing asset. Bring in a depth map or blockout so the composition stops drifting.
Step 7 — Repair locally. Small artifacts — a stray finger, a warped logo, a soft corner — are faster to fix with an inpainting pass than with a full regeneration.
Step 8 — Review against the brief. Check lighting logic, anatomy, text rendering, and whether the image would survive scrutiny in its final context. A frame that looks great at thumbnail size can fall apart in a full-bleed layout.
Step 9 — Archive the settings. Approved prompts, seeds, and parameters become your template library.
If you generate video frames, add a tenth step: test the still in motion. Some images that read as photorealistic in isolation reveal impossible geometry the moment the camera moves.
Choosing the Right Generator: Decision Criteria
Tool comparison lists go stale quickly. Better to evaluate against the criteria that actually determine whether a generator fits your work.
- Photorealism ceiling. Generate the same difficult prompt — hands, reflective metal, dense foliage, legible signage — across candidates and compare like for like.
- Control surface. Does it support structural conditioning, inpainting, reference images, and seed reuse? Control matters more than raw quality once you are in production.
- Iteration speed. Faster generation changes how you work, because you explore instead of committing early.
- Text rendering. If your images need legible words, test this explicitly. It is still the weakest area across most systems.
- Safety and policy behavior. Understand what the platform filters and how that affects legitimate commercial work.
- Integration. Can the model be called from your own pipeline, or are you limited to a web interface? Teams producing hundreds of assets need programmatic access.
- Rights and licensing clarity. Know what you can publish and where.
Run this evaluation on your own prompts, not on benchmark galleries. A model that wins on landscape photography may disappoint on studio product work.
Mistakes That Ruin Realism and How to Fix Them
Overstuffed prompts. Twenty descriptors compete for attention and the model averages them into mush. Fix: five to eight high-signal details, organized by the four-part structure.
Ignoring light. Beginners describe objects; professionals describe illumination. Fix: always specify source, direction, and quality of light.
Fighting the model. Repeatedly regenerating the same prompt and hoping is not strategy. Fix: change one variable at a time — guidance, light direction, lens — and observe the effect.
Chasing maximum sharpness. HDR-style over-processing looks synthetic. Fix: allow soft shadows and shallow depth of field; real photographs are not uniformly crisp.
No consistency plan. Every frame reinvents the look. Fix: lock a style block and reuse seeds where supported.
Neglecting the final use case. A square social crop and a widescreen hero image demand different compositions. Fix: generate at the aspect ratio you will actually publish.
Skipping human review. Automated pipelines drift. Fix: a short review gate before anything goes live.
Ethics, Rights, and Production Guardrails
Photorealistic generation raises questions that a workflow guide cannot dodge.
Disclosure. If an image could be mistaken for a photograph of a real event or person, label it. Many platforms and publishers now require this, and audiences increasingly expect it.
Likeness and consent. Do not generate recognizable real people without permission. This applies to public figures and to private individuals whose photos you may have used as references.
Style imitation. Imitating a living artist's signature style is legally murky and reputationally risky. Reference broad genres instead of named individuals.
Provenance. Keep records of prompts and settings for assets you publish. If a question arises later, you will be able to answer it.
Bias and representation. Generated defaults skew in predictable directions. If your audience is diverse, review outputs for representation rather than accepting the first result.
FAQ
Do I need a technical background to get photorealistic results?
No, but you need the vocabulary of photography. Terms like softbox, focal length, depth of field, and color temperature do more for realism than any technical parameter.
Why do hands and text still fail?
Both demand precise structural consistency that statistical generation handles poorly. Fix hands with inpainting or by changing pose and framing. Fix text by adding it in post-production — that is almost always faster and cleaner.
How many generations should I run per concept?
Plan on at least six to ten exploratory frames per concept, then a similar number for the final pass. Treat early generations as sketches.
Can I use generated images commercially?
It depends on the platform's terms and your jurisdiction. Read the license, keep records, and avoid generating recognizable people or protected logos.
What is the fastest way to improve output quality?
Rewrite your prompt around light and lens behavior. Lighting is the highest-leverage variable in photorealistic generation, and it is also the one most beginners omit.
How do I keep a series visually coherent?
Lock a style block of light, lens, palette, and genre, then vary only subject and scene. Reuse seeds when your tool supports it, and keep a written record of approved settings.
Should I generate stills before video?
Yes. Stills are cheaper to iterate, and a strong key frame gives an animator or video model a clear target. Resolve composition and lighting in stills, then move to motion.
Where This Leaves Your Workflow
The interesting frontier is no longer whether AI can produce a photorealistic image. It can. The frontier is control: shaping light deliberately, holding a character steady across a sequence, matching an existing layout, and doing all of it fast enough that exploration stays cheap.
Teams that treat generation as a craft — with briefs, locked style blocks, review gates, and archived settings — consistently outperform teams that treat it as a slot machine. The models will keep improving. The process is what you own.
