
Why the Pixel Stopped Being the Smallest Unit That Matters
For most of the history of digital imagery, the pixel was the atom. You edited pixels, you rendered pixels, you color-graded pixels. Every professional workflow was built on the assumption that the smallest meaningful decision in an image was a single point of light with a fixed color value.
Generative video broke that assumption quietly, and then loudly. When a model invents frames instead of sampling them, a single wrong pixel is no longer just a defect you can clone-stamp away. It is evidence of a missing rule. The model did not know that the jacket button should stay brass, that the wall texture should stay coarse, or that the key light should keep coming from camera left. So it guessed differently in every shot.
That is the gap modular pixel and pattern processing is designed to close. Instead of asking a model to re-derive the visual world from a text description on every generation, you give it a set of small, reusable, semantically meaningful visual units and instruct it to assemble shots from those units. The pixel becomes a brick. The brick has properties. The properties survive across scenes.
The shift matters because the ceiling on AI video quality is no longer resolution or frame rate. It is coherence. Anyone can generate one beautiful four-second clip. Far fewer people can generate twelve clips that look like they came from the same film. The difference between those two outcomes is almost never the model. It is the structure you feed the model.
What Modular Pixel and Pattern Processing Actually Means
Modular pixel processing is a middle layer between your creative intent and the diffusion process. Rather than controlling only the text prompt and the sampling seed, you control the visual vocabulary: a defined palette, a defined edge treatment, a defined texture family, and a defined lighting model, each packaged into small tile units that you reuse deliberately.
Think of it the way a mosaic artist thinks. The mosaicist does not decide the color of the sky from scratch in every square meter of a wall. They mix one batch of blue tesserae and use it everywhere the sky appears. If the sky later needs a lighter gradient, they mix a second batch and blend the two. Consistency is a supply-chain decision, not an inspiration decision.
From photon-level rendering to pattern-level control
Traditional renderers compute light transport per pixel. Generative models do something different: they approximate a probability distribution over plausible images, conditioned on text, reference images, or both. That distribution is enormous. Without constraints, the model will happily sample a different plausible world in every shot, because every shot is a fresh sample.
Modular processing narrows the distribution locally rather than globally. Instead of writing a longer prompt that tries to pin down the whole frame, you constrain small regions with concrete references: this 32x32 block with this palette and this grain, repeated wherever that material appears. The model still has freedom to compose, but its freedom is bounded by materials you chose.
Tile, motif, and scene memory
A practical modular system has three tiers:
- Tile — a small block (typically 16x16 to 64x64 pixels) carrying a palette, an edge behavior (soft, hard, dithered, aliased), and a texture family (fabric, concrete, skin, foliage, metal).
- Motif — a recurring shape or pattern built from tiles: the weave of a coat, the print on a curtain, the grid of a window frame, the freckle pattern of a face.
- Scene memory — the retained set of reference frames and tiles that define a sequence. This is what you hand the model (or your node graph) at the start of every shot.
When people say a generated sequence feels "cinematic," they usually mean scene memory was preserved. When they say it feels like a slideshow of unrelated clips, scene memory was lost.
The Consistency Problem That Breaks Most AI Videos
Before fixing drift, it helps to name the specific kinds of drift you are fighting. They are not the same problem, and they do not have the same fix.
Character drift
Faces shift subtly across shots: the nose widens, the jaw softens, the hairline migrates, the eyes change spacing. This happens because identity is represented as a high-dimensional embedding, and small changes in conditioning inputs move the sample to a neighboring point in identity space. Re-rolling rarely helps. Locking identity references and repeating them in every shot's conditioning does.
Light and shadow drift
This is the most damaging and the least discussed. Shot one has a soft key from the left. Shot two has a hard key from the right. Shot three has no discernible direction at all. Audiences rarely articulate why the sequence feels wrong, but they feel it immediately — it reads as amateur even when the individual frames are gorgeous.
Texture and detail drift
Fabric becomes plastic. Skin becomes wax. Concrete becomes noise. Texture drift is often caused by resolution changes between generations, by upscalers that hallucinate detail, or by mixing models with different latent priors in the same sequence.
A quick diagnostic: the strobe test
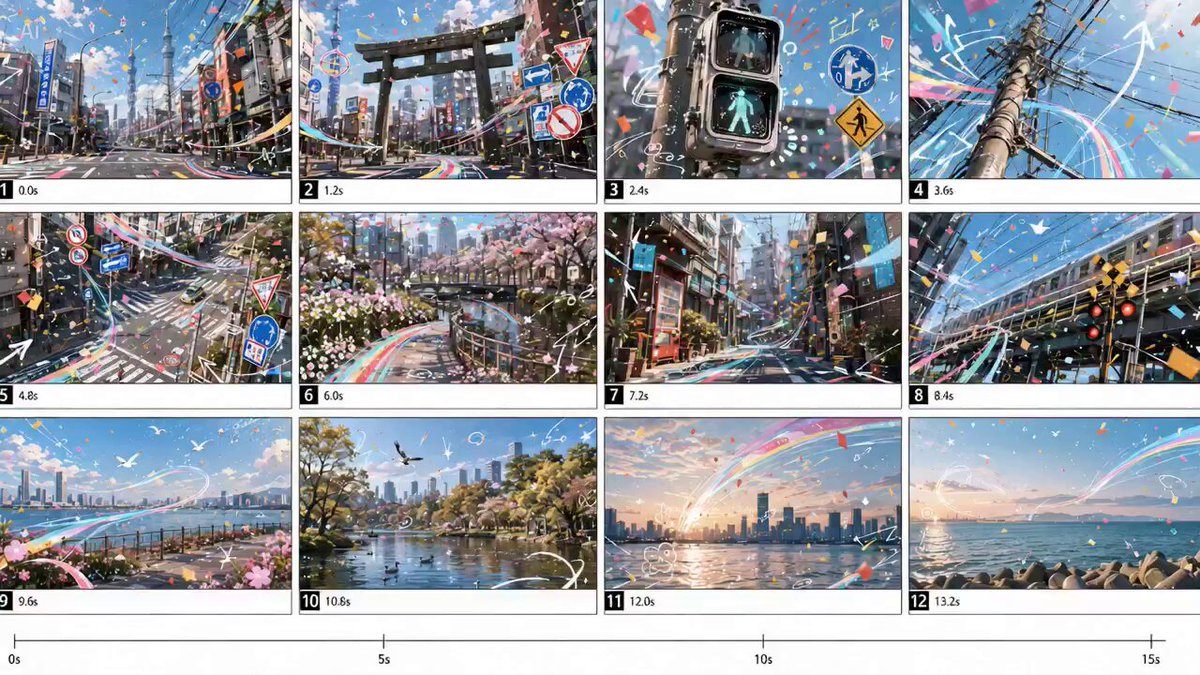
Export frames from the first, middle, and last second of each shot. Put them side by side. Look for three things: light direction, dominant material texture, and silhouette proportion. If any of the three jumps between panels, you have found the drift, and it is almost always cheaper to fix the rule than to fix the frame.
A Step-by-Step Modular Pixel Workflow
This workflow assumes you are producing a multi-shot sequence of roughly 20 to 90 seconds. It works whether you generate with hosted text-to-video models, image-to-video pipelines, or a node-based local setup.
Step 1: Write a one-page visual grammar
Before you generate anything, write down five decisions: the palette (four to six dominant colors), the edge treatment (crisp or soft), the grain level, the contrast curve, and the material vocabulary. One page, plain language, no ambiguity. This document is what you consult when a shot looks wrong and you cannot say why.
Example entry: "Palette: desaturated teal, warm sand, bone white, charcoal. Edges: slightly soft, no chromatic fringing. Grain: fine, visible in midtones. Materials: brushed steel, worn canvas, raw plaster, matte skin with visible pores."
Step 2: Build a tile library
Create 20 to 40 tiles covering the materials your sequence actually needs. Do not over-produce. A common beginner mistake is building 200 tiles, which guarantees that no tile appears often enough to establish a rule.
Name tiles by function, not by look: metal_brushed_dark, canvas_worn_sand, plaster_raw_light, skin_matte_mid. Functional names keep you honest about reuse. If two tiles serve the same function, delete one.
Step 3: Lock three reference frames per scene
Generate or paint three keyframes per scene: an establishing frame, a mid-action frame, and a close-up. These become the conditioning anchors. Every generated shot in that scene should reference at least one of them, preferably two.
Step 4: Generate in short shots, not one long pass
Generate three to five seconds at a time. Long single passes almost always drift internally, and repairing them is expensive. Short shots with a half-second overlap cost slightly more generation time but give you clean handoff points.
Step 5: Repair locally instead of re-rolling globally
When one region fails — a hand, a shadow edge, a fabric fold — mask that region and regenerate it with the same tiles and reference frames. Re-rolling the entire shot resets everything, including the parts that were correct. Local repair preserves accumulated consistency.
Step 6: Assemble, then unify in post
Cut your shots together, then apply a single unifying pass: one grain layer, one contrast curve, one slight color cast, one motion-blur treatment. This final pass is what converts twelve good clips into one film. It is also the step most people skip, and it is why their output still looks assembled rather than directed.
Working Across Multiple Video Models
Different models have different latent priors, which means the same tile library will render slightly differently in each. That is manageable if you plan for it and dangerous if you do not.
Text-to-video versus image-to-video
Text-to-video models are strong at motion and composition but weak at fidelity to a specific look. Image-to-video models inherit the look of the source frame but tend to produce more conservative motion. The reliable pattern is to establish the look with an image pipeline, then hand those frames to an image-to-video model with a motion-focused prompt.
Mixing models without breaking the look
If you must use two or three models in one sequence, follow four rules:
- Assign one model to one job. Model A handles establishing shots, Model B handles character close-ups, Model C handles inserts. Never mix roles within a shot.
- Match resolution and aspect ratio across models. Latent-space behavior changes with resolution, and texture drift often starts there.
- Keep conditioning identical. Same tiles, same reference frames, same seed family, same negative constraints.
- Normalize in post. Color-match every shot to a single hero frame before you judge consistency.
When to switch models versus when to fix the input
Switch models when the failure is structural: the model cannot hold a face for three seconds, or its motion vocabulary does not match your genre. Fix the input when the failure is stylistic: the light drifted, the texture changed, the palette shifted. Most drift is an input problem wearing a model problem's clothes.
Lighting, Shadow, and Material: The Hardest Wins
If you optimize one thing, optimize light. Human vision is exquisitely tuned to inconsistencies in illumination, far more than to inconsistencies in detail. A sequence with slightly mismatched facial details will pass. A sequence with flipping light direction will not.
Create a lighting card for your project and treat it as law:
- Key direction — clock position relative to camera (for example, 10 o'clock, slightly above eye level).
- Key-to-fill ratio — soft (2:1) or hard (8:1).
- Shadow softness — penumbra width described qualitatively (tight, medium, diffuse).
- Practical sources — where in-frame lights sit and what color temperature they emit.
- Ambient color — the overall bounce color, which is often the single biggest cause of shot-to-shot mismatch.
Then encode these into your tiles. A metal tile should specify how it reflects a 10 o'clock key, not just what color it is. A plaster tile should state how much it scatters. When tiles carry lighting behavior, shadow direction stops being a per-shot lottery.
Material realism follows the same logic. Specify roughness, specularity, and micro-detail at the tile level, and vary them only deliberately. The moment a canvas tile and a plastic tile are both available for the same object, the model will pick the wrong one somewhere in your sequence.
Tools That Fit This Workflow
You do not need exotic software. You need the right categories of tool, wired together honestly.
- Tile creation: any raster editor with indexed palettes and pixel-grid snapping — Aseprite, Krita, Photoshop, or Affinity Photo. Export tiles as PNG with alpha and a documented palette.
- Node-based generation: ComfyUI or similar graph tools, where tiles, reference frames, masks, and seeds can be wired as explicit inputs rather than pasted into prompts.
- Reference conditioning: IP-Adapter-style image conditioning, ControlNet-style structural guidance, and pose or depth passes to lock geometry.
- Repair: inpainting and outpainting workflows with tight masks, always driven by the existing tile library.
- Upscaling: conservative models that preserve grain. Aggressive upscalers invent detail, and invented detail is drift.
- Post: any competent NLE or compositor — DaVinci Resolve, Premiere Pro, After Effects, Fusion, or a scripting pipeline with FFmpeg for batch normalization.
- Asset management: a simple naming convention plus a contact sheet. If you cannot see all your tiles and reference frames on one screen, you will not use them consistently.
Hosted video models and local diffusion pipelines both fit this workflow. What matters is that the modular layer lives with you, outside any single model, so you can move between tools without rebuilding your visual language.
Common Mistakes and How to Avoid Them
| Mistake | Why it hurts | Fix |
|---|---|---|
| Building too many tiles | No tile repeats enough to become a rule | Cap at 20–40 tiles, each with a clear function |
| Tiles that are visually identical to each other | The model picks arbitrarily and results flicker | Merge duplicates, keep only distinct materials |
| Long single-shot generations | Internal drift that cannot be repaired cheaply | Generate 3–5 seconds, overlap 0.5 seconds |
| Changing prompt vocabulary mid-sequence | New words activate new visual priors | Freeze your prompt template after shot one |
| Fixing frames instead of rules | The same failure reappears in the next shot | Ask what rule was missing, then add a tile or constraint |
| Ignoring color space | Tiles look correct in the editor, wrong in output | Normalize gamma and color space across every tool |
| Judging shots individually | Local beauty hides global inconsistency | Always review in a timeline, never in isolation |
| Skipping the final unifying pass | The sequence reads as assembled clips | Apply one grain, one grade, one blur treatment |
A useful discipline: whenever a shot fails, write one sentence describing the missing rule. After ten shots, reread those sentences. They usually reveal a single systemic gap — often lighting direction or material roughness — rather than ten separate problems.
Frequently Asked Questions
Do I need pixel-art aesthetics for this to work?
No. The "modular" part refers to how you structure visual information, not to a retro style. Photorealistic sequences benefit just as much, because photoreal drift is what audiences notice fastest.
Is this the same as using style references?
It is a superset. A style reference gives the model a global impression. A tile library gives it local, reusable rules about specific materials, palettes, and lighting behavior. Global references drift; local rules hold.
How many reference frames do I really need?
Three per scene is the practical minimum: establishing, mid-action, and close-up. Fewer and the model interpolates too freely; more and you start adding contradicting information.
Why does my sequence look consistent in stills but wrong when played?
Because motion reveals drift that stills hide. Temporal flicker in grain, shadow edges, and fine texture is invisible frame by frame and obvious at 24 frames per second. Always evaluate in motion.
What is the single highest-leverage change I can make?
Lock your key light direction and reflect it in your tile definitions. Nothing else improves perceived quality as quickly.
Can I reuse one tile library across projects?
Yes, and you should. A studio's tile library is its visual signature. Build it once, extend it deliberately, and version it so you know which projects used which revision.
How do I handle a model that ignores my tiles?
Lower the model's creative freedom: reduce motion amplitude, increase reference-frame weight, shorten shot length, and simplify the prompt so the tiles carry the visual load.
A Pre-Render Checklist
Run this list before you generate a full sequence. It takes ten minutes and saves hours.
- Visual grammar document written and unambiguous.
- Tile library between 20 and 40 tiles, named by function, no duplicates.
- Three reference frames locked per scene.
- Lighting card complete, including key direction, ratio, and ambient color.
- Prompt template frozen and reused verbatim across shots.
- Resolution and aspect ratio identical across every model in the pipeline.
- Color space and gamma normalized between editor, generator, and post.
- Repair workflow tested on one bad region before batch generation.
- Timeline review planned, with a strobe test at every scene boundary.
- Final unifying pass scheduled: grain, grade, motion blur.
The larger point is that generative video is no longer a slot-machine discipline. The people producing work that holds up are not the ones with the best prompts. They are the ones who decided, in advance, what their world is made of — and then refused to let the model re-decide it shot by shot. Modular pixel and pattern processing is simply the most practical way to make that decision stick.
