
Why Character Consistency Is the Hardest Problem in AI Video
Ask anyone who has tried to build a narrative with generative video what broke first, and the answer is almost never the render quality. It is the face. A character walks out of frame in shot one and returns in shot three with a slightly different jawline, a different eye color, and a hairstyle that has quietly migrated half a centimeter to the left. Audiences may not consciously catalog those differences, but they feel them. The moment a viewer notices that the hero looks like a different person, the illusion collapses and the video reads as a collage rather than a story.
The root cause is that most video models do not store a character. They store a prompt. Every time you generate a shot, the model samples a new interpretation of your description, and small variations compound. Seed locking helps, but it only works within one model, one aspect ratio, and often one style preset. Change the framing from a close-up to a wide shot, or move from a daylight scene to a night scene, and the seed loses its grip.
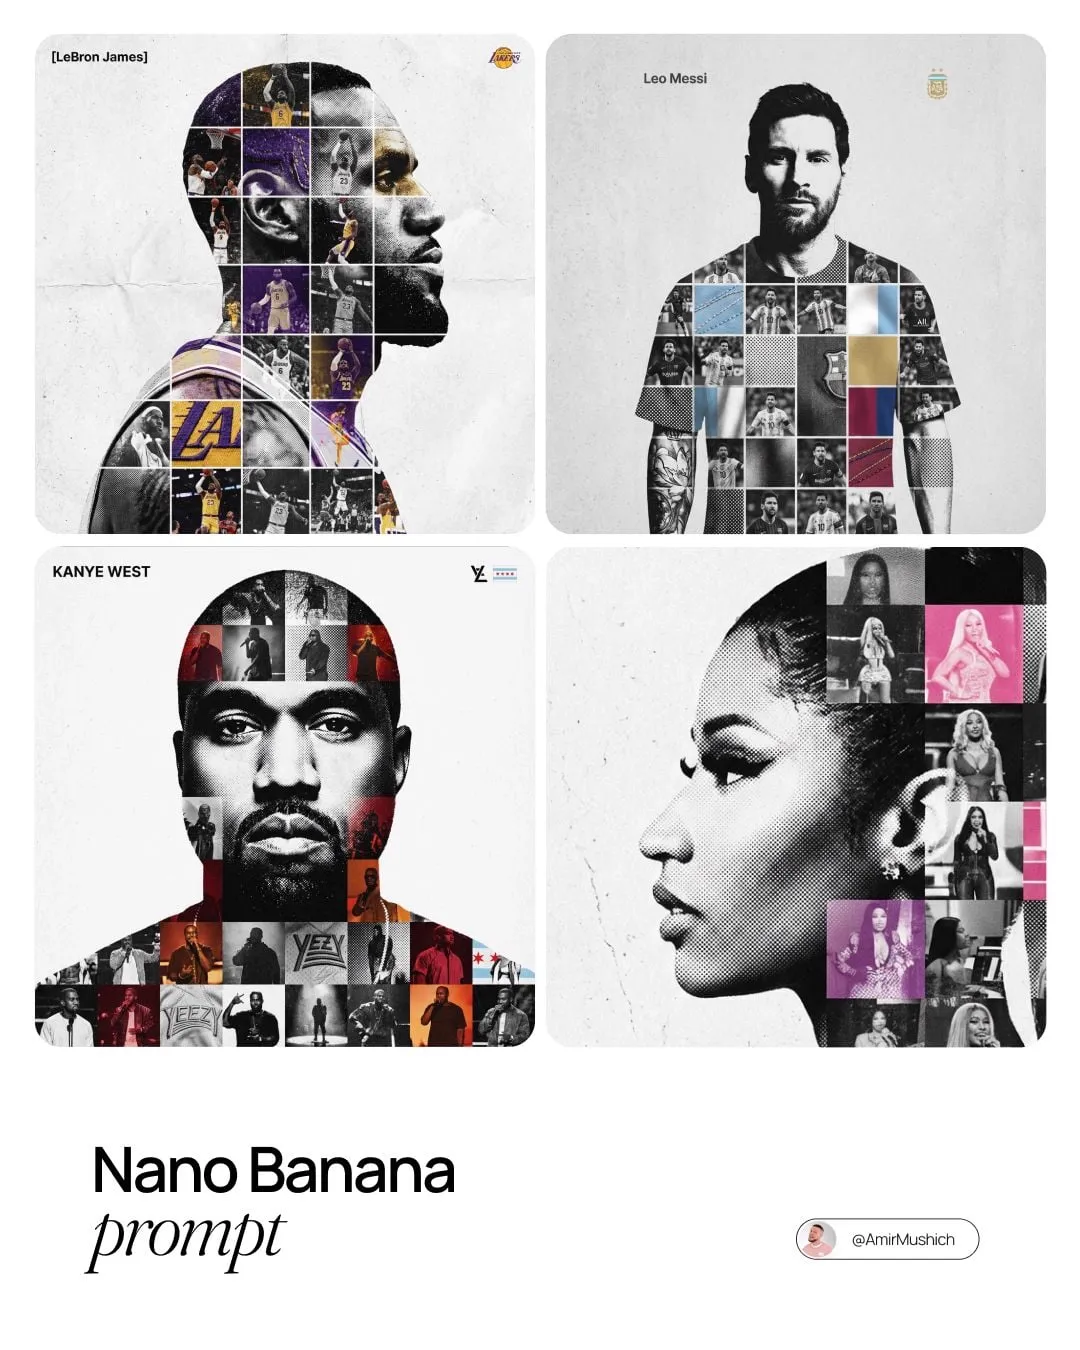
That is why the multi-image approach matters. Instead of describing a character in words and hoping the model converges on the same person, you supply several images that already show the character from different angles, in different lighting, and at different distances. The model stops guessing and starts interpolating. Consistency becomes a data problem rather than a luck problem, and the rest of your production pipeline can finally be built on something stable.
This guide walks through the entire workflow: how fusion of multiple references actually behaves, how to build a reference pack that survives scrutiny, how to select models per shot, how to change style without changing identity, and how to catch the small failures before they reach the edit.
How Multi-Image Reference Fusion Behaves in Practice
Fusion is an umbrella term for several techniques that are frequently mixed together. Understanding which one you are using prevents a lot of wasted effort.
Reference conditioning versus identity embedding
Reference conditioning passes your images alongside the text prompt as additional context. The model attends to them but is not bound by them, which means it captures broad traits like clothing color and silhouette while improvising details like the exact shape of the nose.
Identity embedding trains or extracts a compact representation of a face, then injects it into every generation. This holds facial structure much more tightly, but it is less flexible: dramatic expressions, extreme angles, and heavy stylization can push the output away from the reference and produce an uncanny result.
Most professional pipelines combine both. You use an embedding or identity adapter for the face and reference conditioning for wardrobe, props, and overall palette.
Why more references are not automatically better
A common mistake is to throw fifteen images at the model and expect the strongest lock. In practice, ten to twelve well-chosen references outperform thirty random ones. Redundant images add noise: if six of your references show the same three-quarter angle, the model over-weights that view and produces flat, frontal-looking results.
Aim for coverage, not volume:
- Three to four clean frontal shots at slightly different angles
- Two profiles, one per side, so the model learns the skull shape
- One or two three-quarter views, which are the most common cinematic angle
- Two full-body shots for proportion and wardrobe
- One or two expression references, ideally with an extreme emotion
- Optional: one back-of-head shot if the story includes turns or reveals
Resolution, lighting, and background hygiene
References should be sharp, evenly lit, and free of clutter. A perfectly usable 1024-pixel face with soft, neutral light beats a 4K face shot with a hard side light and a busy background. The model does not distinguish between your character's features and environmental noise, so every stray detail becomes something it may try to reproduce.
If your reference has dramatic cinematic lighting, expect the output to inherit that lighting even when your prompt asks for an overcast morning. Either neutralize references or lean into the look deliberately.
Building a Character Reference Sheet That Survives Every Shot
Treat the reference sheet as a deliverable, not a byproduct. Producing it properly takes an hour and saves entire days later.
Start with a locked base design
Generate your character once in a controlled setup: neutral pose, neutral background, straight-on camera, soft light. Iterate until you would be comfortable with this face appearing in a hundred shots. Then generate the other angles from that base rather than starting fresh each time. Consistency in the source material is what makes consistency in the output possible.
Write a character bible in words too
The images do the heavy lifting, but a short written spec resolves ambiguity when the model has to improvise. Keep it to five or six lines: approximate age, build, hair length and texture, distinguishing marks, default wardrobe, and posture. Avoid poetic descriptors. "Early thirties, lean, shoulder-length wavy black hair, thin scar over left brow, charcoal wool coat" gives the model far more usable signal than "a mysterious wanderer with a haunted past."
Version the sheet
Save each iteration as its own folder with a date and a short note about what changed. When a series runs for months, you will need to know exactly which reference set produced which episode. This is the single most common source of continuity chaos in long-running projects.
Test before you commit
The acceptance test for a reference sheet is a stress reel. Generate six shots with it: close-up, medium, wide, profile, back turn, and a strong emotion. If any of those six fails, fix the sheet before you build a storyboard around it.
A Step-by-Step Workflow: From Reference Pack to Finished Sequence
Here is a repeatable process that works whether you are making a thirty-second short or a ten-episode series.
Step 1: Define the shot list before generating anything
Write down every shot with framing, action, and duration. This is tedious and it is the difference between a coherent sequence and an expensive collection of pretty clips. Video generations are slow and costly in every tool; knowing that you need four close-ups and one wide shot prevents you from generating twelve medium shots you will never use.
Step 2: Group shots by visual conditions
Sort your shot list into buckets that share lighting, location, and style. Then generate each bucket in a single session with the same reference pack, the same model, and the same style settings. Session-level consistency is much easier to achieve than cross-session consistency.
Step 3: Lock a first frame for each shot
Generate the opening frame as a still image first, using the reference pack. Only when the still looks right do you send it into a video model as the starting frame with motion instructions. This image-to-video path is dramatically more stable than text-to-video for character work, because the identity is already fixed in the pixels.
Step 4: Generate short, controlled motion
Keep clips in the three-to-five-second range for character-heavy scenes. Longer generations drift progressively as the model accumulates error. Two short clips cut together usually beat one long clip with a melting face at the end.
Step 5: QC every clip against the reference sheet
Play each clip at reduced speed and compare it side by side with your reference images. Check five things: eye color and spacing, hairline, jaw and chin shape, hand anatomy, and wardrobe details. Note failures in a running log.
Step 6: Regenerate only what failed
Resist the urge to redo everything. Regenerate failed shots with a tightened prompt, a slightly different starting frame, or a different model. Keeping the successful shots untouched preserves the continuity you already earned.
Step 7: Assemble with continuity in mind
In the edit, avoid cutting directly from one framing to a near-identical framing if the two clips have slightly different facial geometry; the comparison makes drift visible. Cut through a different angle, an insert, or a transition. Editors have hidden continuity problems this way for a century.
Choosing the Right Model for Each Shot
No single model wins every shot. A practical approach is to assign models to jobs based on what they handle best.
| Shot type | What matters most | Model traits to look for |
|---|---|---|
| Portrait close-up | Facial fidelity, skin texture | Strong identity conditioning, high still-image quality |
| Action medium shot | Motion coherence | Good temporal stability, physics awareness |
| Wide establishing | Environment and scale | Strong scene comprehension, consistent palette |
| Stylized sequence | Style fidelity | Robust style reference support |
| Dialogue beat | Micro-expression | Smooth interpolation, low flicker |
Decision criteria worth weighing:
- Identity lock strength. If the model reshapes faces between frames, it is unusable for character work regardless of its cinematic polish.
- Reference input count. Some tools accept one reference; others accept several. For a character, several is a hard requirement.
- Duration limits. A model limited to four seconds can still build a sequence if it is stable across that window.
- Style range. If you need animation and photorealism in the same project, you may need two models and a careful grade to unify them.
- Iteration speed. A fast, mediocre model is often better for blocking than a slow, excellent one. Use the fast model to find the composition, then move the winning frame to the premium model.
A useful rule: use still-image generation for identity and composition, image-to-video for motion, and a dedicated upscaling or interpolation pass at the end. Trying to solve identity inside the video step is the hardest possible route.
Style Transfer Without Losing the Face
Switching a character from live-action realism to painterly illustration is where most pipelines visibly break. The features survive the first few frames and then dissolve into generic anime geometry.
A few techniques help:
Transfer in stages. First change lighting and color grade, then change rendering style. Doing both at once asks the model to solve two problems at the same time and it usually solves neither.
Keep one anchor element identical. If the wardrobe, silhouette, or a signature prop stays constant across the style change, viewers track identity through that anchor even when the face softens.
Reduce the prompt's style intensity. Instead of "oil painting," try "painterly rendering with visible brushwork, natural skin tones." The second phrasing preserves structure.
Rebuild the reference sheet in the new style. If the whole project moves to a new look, generate a stylized reference sheet and treat it as a new character version. Trying to drag the photoreal sheet across a hard style boundary rarely works.
Accept a controlled amount of change. A style shift is a visual break. Frame it as an intentional transition — a memory, a dream, a different era — rather than pretending nothing changed.
Common Mistakes and How to Fix Them
Mistake: inconsistent reference lighting. Fix by normalizing exposure and white balance across the pack before you start.
Mistake: prompt bloat. Adding twenty lines of description dilutes the images. Fix by keeping prompts short and letting references do the work.
Mistake: changing seed, model, and style at the same time. When a shot fails, change one variable. Otherwise you learn nothing.
Mistake: ignoring hands. Facial consistency can be perfect while hands morph. Fix by keeping hands out of frame or generating a dedicated hand reference.
Mistake: judging on a still frame. Motion artifacts appear when played back. Always review clips at full speed and at half speed.
Mistake: no naming convention. Files named final_v2_really.mp4 destroy traceability. Fix with a strict scheme like episode_shot_take.
Mistake: generating before storyboarding. The most expensive error, because it wastes both time and budget on shots that get cut.
Shot Planning, Continuity, and Editing Discipline
Consistency is partly a post-production skill. A few editing habits make drift nearly invisible:
- Cover transitions. When cutting between two clips with subtly different faces, insert a two-frame insert shot, a rack focus, or a whip pan.
- Favor motion. A character walking through frame hides small geometry differences better than a static talking head.
- Use depth of field. Shallow focus on a face with a blurred background makes minor structural differences less comparable.
- Color grade as glue. A unified grade across an episode does more for perceived continuity than any single generation fix.
- Score and sound design. Audio continuity strongly influences how continuous the image feels. It is not a trick; it is how perception works.
- Keep a continuity bible. A single document listing wardrobe, props, and hair state per scene prevents the classic error of a character changing clothes mid-conversation.
Scaling to Series and Episodes
Once a single character works, the temptation is to add three more. Add them one at a time and finish a complete short scene with each before expanding. A character that works in isolation often fails in interaction: two characters in one frame stress the model differently, and occlusion, scale, and eyeline matching all become new problems.
When you do scale, build a reusable library:
- A reference pack per character, versioned and documented
- A prompt template per shot type, with only the variable parts edited
- A style preset that all episodes share
- A QC checklist you actually run
- An asset naming convention that survives hundreds of files
This library is the real product of the work. Render settings change, models improve, but a well-built reference pack and shot system remain useful across every generation tool you adopt.
FAQ
How many reference images do I actually need?
Eight to twelve well-chosen images covering multiple angles and distances. Coverage matters more than count, and redundant angles actively hurt.
Can I get consistency from text prompts alone?
Within a single short clip, sometimes. Across multiple shots, rarely. Text describes traits; images define identity.
Why does my character look right in stills but wrong in video?
Video models add temporal sampling on top of identity conditioning. Generate a still first, confirm it, then use it as the starting frame for motion.
Should I train a custom model or use reference conditioning?
Training gives tighter identity lock for a character used across hundreds of shots. If you need flexibility across styles and scenes, reference conditioning with a good pack is usually faster to set up.
How do I handle a character who ages or changes costume?
Maintain separate reference packs per state and treat the transition as an intentional story beat. Blending two states in one pack confuses the model.
What is the fastest fix for facial drift mid-clip?
Shorten the clip. Most drift accumulates over time, so a three-second clip with a slightly different expression beats a ten-second clip with a changing face.
Can I mix models within one project?
Yes, and most studios do. The cost is a unified color grade and a careful continuity pass, which is cheaper than accepting a model's weakness in every shot.
How do I keep quality high without endless regeneration?
Lock your reference pack, lock your shot list, change one variable per retry, and accept a defined threshold of imperfection. Perfectionism in character rendering has diminishing returns; audiences forgive small differences far more than they forgive a broken take.
The workflow itself is the asset. Refine the reference sheet, keep shots short and controlled, and let editing carry the continuity that generation cannot.
