
Why Character Drift Still Breaks AI Video Projects
Ask anyone who has tried to build a narrative sequence with generative video what the hardest problem is, and you will rarely hear "image quality." Modern text-to-video models produce remarkably detailed frames. The recurring failure is simpler and more damaging: the same character does not look like the same person from shot to shot.
The face narrows slightly in shot two. The hairline shifts in shot five. A scar appears in one frame and vanishes in the next. Skin tone warms under a sunset and cools into something unrecognizable in the following close-up. This is character drift, and it is the single largest obstacle between a promising AI demo and a deliverable that a client, a brand team, or an audience will accept.
The technical reason is straightforward. A video model generates each shot independently. It has no persistent memory of who your protagonist is, only the tokens in your prompt and whatever visual conditioning you supply. When the prompt changes — new location, new lens, new action — the model redistributes probability mass across the whole frame, and facial geometry moves with it. Seeded randomness helps a little, but seeds do not survive changes in camera angle, lighting direction, or motion intensity.
The common workarounds all fail in predictable ways. Repeating the same prompt produces near-identical shots and no storytelling variety. Describing the character in ever more elaborate language produces generic-looking people. Generating dozens of takes and cherry-picking works for a fifteen-second clip and collapses the moment you need twenty shots.
Multi-image fusion exists to solve exactly this problem. It is not a single button; it is a workflow with specific inputs, specific failure modes, and a discipline that separates projects that ship from projects that stall.
What Multi-Image Fusion Actually Does
Multi-image fusion takes several reference images of the same subject — different angles, different lighting, different expressions — and compresses them into a compact mathematical representation of that subject's identity. Every generated frame is then conditioned on that representation in addition to your text prompt.
The practical difference between one reference image and eight is significant. A single reference gives the model one look at the character and no way to distinguish essential features from incidental ones. A reference set lets the model triangulate: if the nose looks the same in a front view, a three-quarter view, and a profile, the nose is structural and must be preserved. If the lighting changes dramatically across references but the bone structure does not, the model learns that lighting is a variable and identity is not.
Identity embeddings in plain terms
Think of an identity embedding as a numerical fingerprint. The system analyzes your references and extracts weighted features: interocular distance, jaw width, brow shape, nose bridge height, lip fullness, hair silhouette, skin tone range, and any signature accessories or marks that appear consistently. Structural features get heavy weight. Transient features — the exact shade of a jacket under tungsten light, a stray curl from wind — get light weight or none at all.
The quality of that fingerprint determines everything downstream. A fingerprint built from eight clean, well-lit, varied references will hold through extreme close-ups, fast motion, and dramatic lighting changes. A fingerprint built from three near-identical selfies will hold for exactly one shot.
How fusion compares to fine-tuning and LoRA training
There are three broad approaches to character consistency, and they trade off differently.
| Approach | Setup effort | Identity durability | Style flexibility | Best for |
|---|---|---|---|---|
| Prompt-only description | Minutes | Very low | High | Abstract or generic characters |
| Multi-image fusion | Under an hour | Medium to high | High | Most narrative and commercial work |
| LoRA or fine-tuning | Hours to days | Very high | Medium | Recurring series, long-form franchises |
Prompt-only work costs nothing but delivers the weakest identity lock. Fine-tuning a small adapter on 20 to 40 images produces the strongest identity, but it bakes the character into a specific aesthetic and can drag your style along with it. Multi-image fusion sits in the productive middle: fast to set up, re-usable across projects, and flexible enough that you can change art direction without retraining anything.
For most teams, fusion is the right first move. Only escalate to training when a character will appear across many episodes and must survive model upgrades and style shifts over a long production cycle.
Building a Reference Set That Survives Every Shot
The reference set is where projects are won or lost. Skimp here and no amount of prompt engineering will save the sequence.
The five-angle minimum
Start with five views: straight-on front, three-quarter left, three-quarter right, full profile, and one slightly low angle. The low angle matters more than people expect, because it reveals jaw and chin structure that a head-on shot hides. If your character will ever be seen from behind, add a back-of-head reference for hair silhouette.
If you can only produce four references, prioritize front, three-quarter left, three-quarter right, and profile. Those four cover the overwhelming majority of cinematic shots.
Lighting, expression, and wardrobe sheets
Identity references should be lit neutrally — soft, even, no harsh color casts — so the model reads structure rather than mood. But a set of exclusively neutral references will produce flat lighting in every generated shot, because the model treats your average as the target.
Add two references with strong directional lighting and keep everything else consistent. This teaches the model that lighting varies while identity does not. Do the same for expression: include neutral, a genuine smile, concern, and surprise. Four expressions is usually enough to unlock a full emotional range later.
For wardrobe, decide what is permanent and what is scene-specific. A leather jacket, a wedding ring, a distinctive pendant, or a pair of round glasses might be tier-one identity markers that must appear in every shot. Everything else — shirts, coats, outer layers — is tier two and can change freely. Write this distinction down before you generate anything.
Cleaning and standardizing inputs
Reference hygiene is unglamorous and decisive.
- Minimum 1024 pixels on the short side. Larger is better up to about 2048.
- Consistent crop framing, with the head occupying a similar portion of the frame in every reference.
- Neutral or simple backgrounds. Cluttered backgrounds bleed into generated scenes.
- No sunglasses, heavy filters, motion blur, watermarks, or compression artifacts.
- No other people in the frame. The model will average them in.
- Consistent color grading. If one reference is warm and another is cool, the identity embedding absorbs the inconsistency.
If your only available references are compressed social media images, run them through an upscaler, then evaluate at 100 percent zoom. Blurry references produce blurry characters, and no downstream step fully repairs that.
A Repeatable Workflow: From Stills to a Consistent Scene
The following sequence works for short brand films, animated series pilots, and social campaigns. It front-loads the cheap work and defers the expensive work until identity is proven.
Step 1 — Write the character bible
Before generating anything, write one page of plain text. Include: apparent age range, build, hair length and texture, eye color, distinctive marks, tier-one wardrobe items, and a short list of personality traits. This document becomes your prompt source of truth and your QA reference. Teams that skip it end up with a character who is described differently in every prompt and therefore looks different in every shot.
Step 2 — Lock the keyframe set
Generate 12 to 20 candidate stills of the character in a single image model with a stable style. Review them as a contact sheet and select 8 to 10 finalists. You are selecting for three things simultaneously: sharpness, on-model consistency, and variation across angle and expression. A set of eight near-identical front views is worse than a set of five genuinely varied ones.
Step 3 — Fuse, then run a stress test
Apply fusion to the finalist set and immediately generate three deliberately difficult shots:
- An extreme close-up, where facial geometry is magnified.
- A fast-motion or running shot, where models tend to simplify faces.
- A backlit or silhouette shot, where tonal information is stripped away.
If identity holds through all three, you have a working character. If it fails, diagnose specifically: a failing profile suggests you need more side-angle references; a failing close-up suggests higher-resolution inputs; a failing backlit shot suggests adding one dramatic side-lit reference.
Step 4 — Expand to new scenes
Generate stills for each new scene before animating anything. Approve the still, then animate it. This keeps your iteration cost low, because a rejected still costs a fraction of a rejected video clip, and it gives you a versioned visual record of the character across the whole sequence.
Step 5 — Run a frame-by-frame QA pass
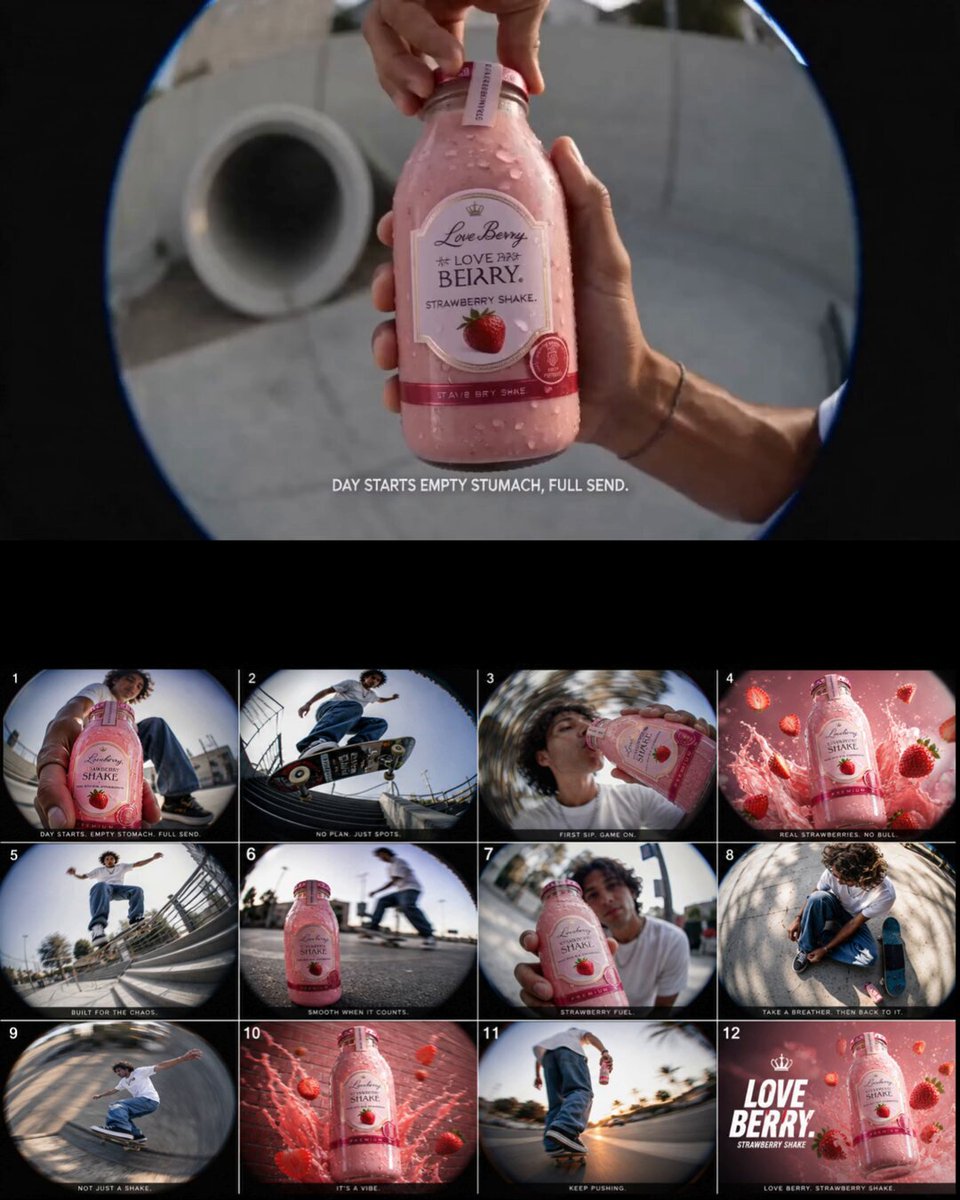
Assemble every generated shot into a single contact sheet grid. Scan for four things in this order: face structure, hairline and hair length, tier-one wardrobe items, and skin tone. Anything that shifts needs to be flagged with a timecode and regenerated with the same fused identity but adjusted camera or lighting language.
Choosing Tools and Models for Consistency
Not every model handles multi-reference conditioning equally well, and the differences matter more than benchmark scores suggest.
Reference capacity. How many images can you supply, and does the model weight them equally or let you set priorities? Six properly weighted references outperform twenty unweighted ones.
Identity and style separation. The best implementations let you keep a subject fixed while changing visual style — photorealism to stylized animation, for example. If style and identity are entangled, every art-direction change forces you to rebuild the reference set.
Temporal stability. Watch for shimmer and identity pulsing across frames within a single shot, not just between shots. A model that holds identity across cuts but wobbles within a take is unusable for close-ups.
Motion controllability. Camera path, subject motion, and speed control let you shoot coverage of the same scene without reintroducing drift.
Output resolution and duration. Short takes at decent resolution usually serve narrative work better than long, low-detail generations, because you can cut around weak frames.
Repeatability. Can you save a fused character and reuse it next month? Persistent characters are what turn a one-off experiment into a production pipeline.
On the image side, diffusion models with strong prompt adherence and consistent lighting behavior give you better reference sets. On the video side, models with subject-reference conditioning and reliable camera control handle fusion best. Test two or three before committing an entire project to one.
Common Mistakes and How to Fix Them
Too few references. Three images is not a set. Fix: expand to at least five angles plus two lighting and four expression variations.
Inconsistent references. If your references look like different people, the fused identity will be a blurry average. Fix: regenerate the reference set from a single base image using a consistent prompt.
Over-weighting style. If your references all share a heavy cinematic grade, that grade will be glued to your character in every shot, including bright daylight scenes. Fix: include two neutrally graded references.
Letting the prompt fight the reference. Describing hair color or facial features in the prompt when fusion already handles them creates conflict and instability. Fix: strip identity descriptors from the prompt and keep only action, framing, lighting, and mood.
Mixing models mid-sequence. A model swap mid-project almost always shifts facial structure. Fix: either stay in one model per character or rebuild and re-test the fused identity before switching.
Ignoring lens and framing changes. A wide shot flatters identity; a 24mm-feeling close-up exposes every flaw. Fix: stress-test at the tightest framing you actually plan to use.
Skipping the contact sheet. Without a side-by-side review, drift accumulates invisibly. Fix: build the grid after every batch, not at the end of the project.
Advanced Techniques: Emotion, Aging, and Wardrobe Changes
Once baseline identity is stable, you can push the technique further.
Emotional range without identity loss. Use expression references rather than descriptive adjectives. "Sad" produces generic sadness; a reference image of this specific character looking sad produces the right face. Combine a subtle instruction in the prompt with a strong expression reference.
Age changes. For flashbacks, supply references of the character at a younger age alongside the present-day set, and specify age in the prompt. Keep bone structure constant — the model can handle skin texture and hair color shifts if jaw and nose remain anchored.
Multi-character scenes. Two fused characters in one frame compete for control of the same pixels. Generate each separately to confirm stability, then compose the scene with clear spatial separation, distinct silhouettes, and non-overlapping wardrobes. Occlusion — one character partially in front of another — is the hardest case, so test it early.
Continuity across episodes. Save the fused identity, the reference set, and the prompt templates together. Reproducing a character six weeks later depends on all three being available, not just the images.
Production Checklist Before You Render a Full Sequence
- Character bible written and version-controlled.
- Eight to ten references selected, covering five angles, two lighting conditions, and four expressions.
- References cleaned, upscaled, and color-consistent.
- Fused identity saved with a clear naming convention.
- Stress test passed: close-up, fast motion, backlit.
- Style and identity weights tuned and documented.
- All stills for the first scene approved before any video generation.
- Contact sheet QA pass scheduled at defined milestones, not only at the end.
- Tier-one wardrobe list printed and checked shot by shot.
- Fallback model identified in case of mid-production failure.
FAQ
How many reference images do I actually need?
Five is the practical floor for a character who appears in varied shots. Eight to ten is the productive range. Beyond roughly fifteen, returns diminish sharply unless you are deliberately covering unusual angles or wardrobe states.
Can I fix an existing sequence with bad drift, or do I need to start over?
You can often salvage it. Build a proper reference set from the best two or three frames you already have, fuse it, and regenerate only the failing shots. In most cases fewer than a third of shots need to be redone.
Should I describe the character's face in my prompt?
No. Once fusion is active, facial descriptions compete with the visual reference and introduce instability. Describe action, camera, lighting, and mood. Let the reference set handle identity.
Why does identity hold in wide shots but break in close-ups?
Close-ups magnify facial geometry, so any imprecision in the identity embedding becomes visible. The fix is higher-resolution references and at least one tight, well-lit portrait in the reference set.
Does this work for stylized or animated characters?
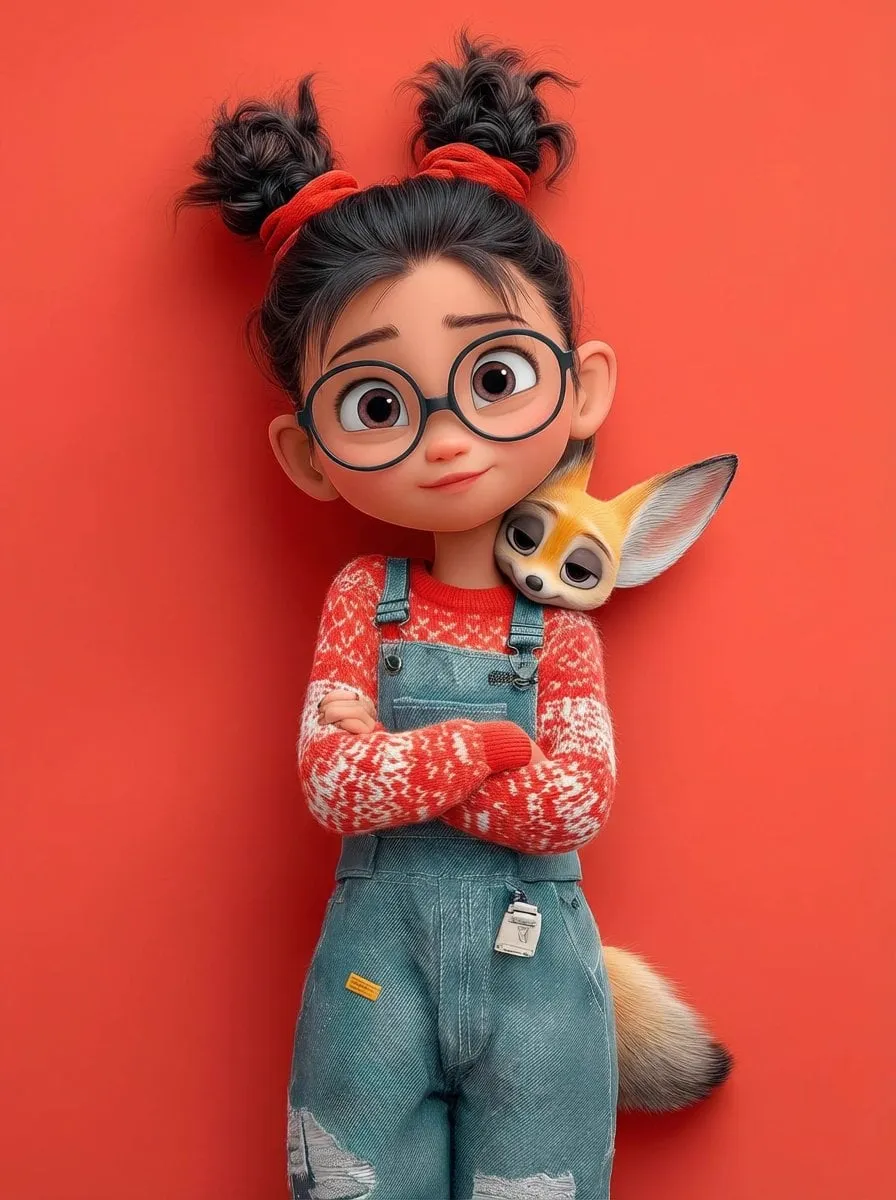
Yes, and often better than for photoreal humans. Stylized characters have stronger silhouette signatures — distinctive hair shapes, clothing outlines, exaggerated proportions — that are easier to lock than subtle variations in real faces.
How do I handle a character who changes outfits frequently?
Split identity into two layers: permanent markers and variable wardrobe. Keep permanent markers in every reference, then supply one reference per outfit variation. The fused identity preserves the face and body; the wardrobe reference localizes the clothing change to specific shots.
What is the biggest single cause of failure?
Reference inconsistency. If your input images disagree with each other about what the character looks like, the model has no choice but to average them, and an average of five people is nobody.
The technology is not the bottleneck anymore. Models can render faces at a fidelity that was unimaginable a few years ago. What separates a usable sequence from a discarded experiment is preparation: a clean reference set, a documented character bible, a stress test before committing to a full render, and a disciplined QA pass that catches drift before an audience does. Master that workflow and character consistency stops being a gamble and becomes a repeatable part of your production process.
