
Why character consistency is the hardest part of AI video
Every generative video model samples from a probability distribution, not from a fixed 3D asset. When you prompt a shot in isolation, the model has no obligation to reproduce the same nose, hairline, or jacket it drew three shots ago. The result is character drift: a face that shifts subtly between cuts, a jawline that softens, eye color that warms or cools, wardrobe details that mutate. In a five-second clip the drift is invisible. Across a ninety-second narrative it becomes the first thing an audience notices, even if they cannot articulate why.
Drift comes from four places. First, the text encoder interprets the same sentence slightly differently depending on the random seed and on the surrounding scene description, so the identity signal is diluted by scene noise. Second, diffusion denoising is stochastic, and tiny numerical differences compound frame by frame. Third, a change of camera angle forces the model to invent geometry it has never been shown: the back of a head, a true profile, a hand at rest. Fourth, lighting changes the pixel statistics the model uses as shortcuts for identity, so a character lit warmly in one shot and coldly in the next reads as a different person.
The practical consequence is blunt. If you condition a generation on a single reference image, you are asking the model to hallucinate most of the character. Multi-image fusion exists to close that gap by giving the model several views instead of one guess.
How multi-image fusion actually works
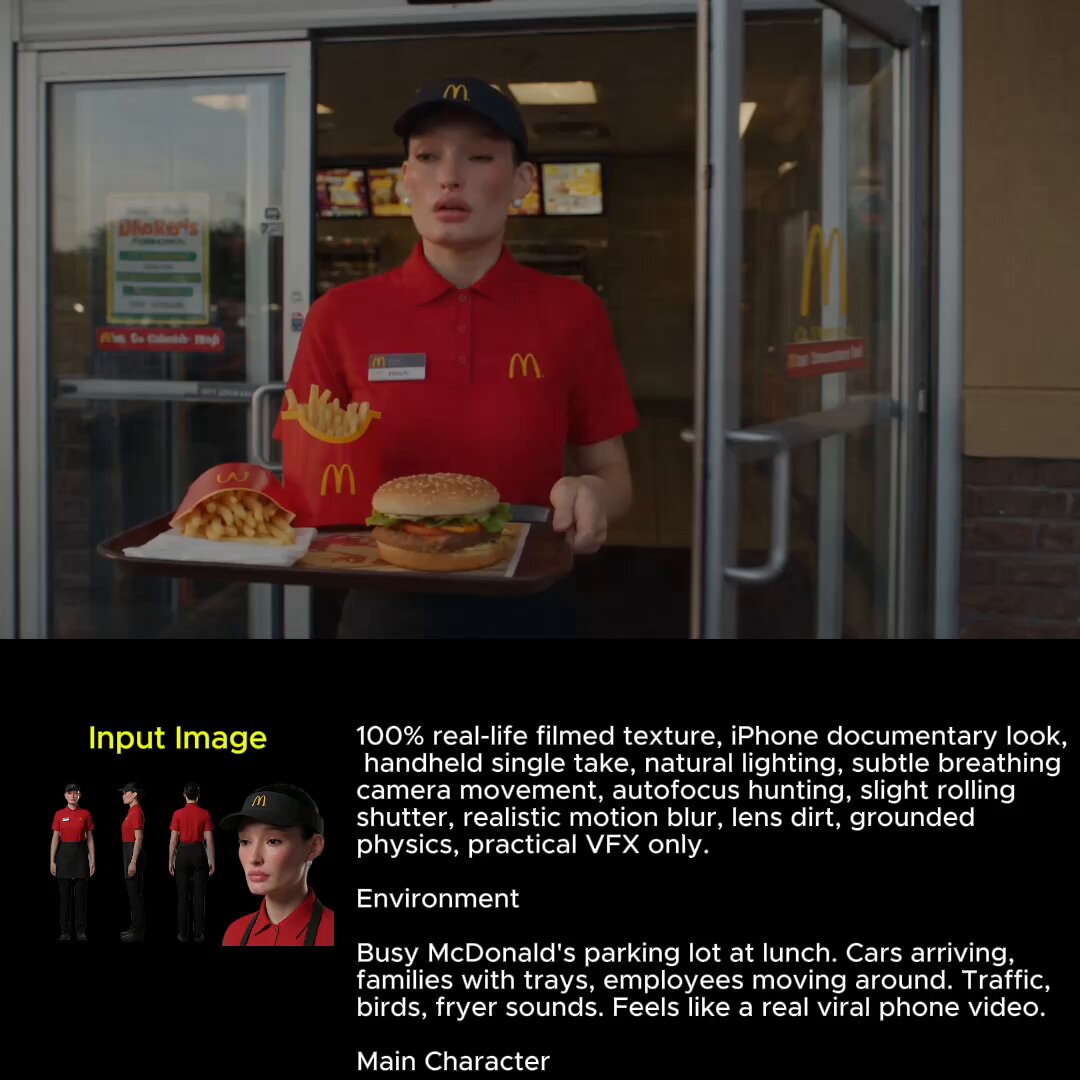
Multi-image fusion means conditioning a generation on several reference images of the same subject at once, rather than on one hero portrait. Instead of a single identity embedding, the model receives a small cluster of views and cross-attends across all of them during denoising. Each reference contributes partial information, and the attention layers reconcile the overlaps.
Reference conditioning versus single-image anchoring
Single-image anchoring gives the model one snapshot: one angle, one expression, one lighting setup. Anything outside that narrow envelope is guesswork, which is why a character built from one photo looks perfect in the shot that matches that photo and falls apart everywhere else. Fusion gives the model several anchors, so it can triangulate facial geometry from more than one direction and stabilize skin tone across more than one light condition.
What fusion fixes and what it cannot
Fusion reliably improves facial structure, hairline, hair texture, skin tone, and costume continuity across cuts. It does not fix a badly structured scene, physics the model has never learned such as complex hand interactions with objects, or a reference set where every photo was shot under a different white balance. Fusion narrows variance; it does not eliminate it. Plan on regenerating a few shots, and budget time for it.
Building a reference set the model can trust
The quality of your reference set sets the ceiling for everything downstream. No prompt, keyframe trick, or model swap can recover from references that contradict each other.
A minimum viable set
Five to eight images is the sweet spot for most image-to-video and video models. Aim to include one neutral frontal portrait with a relaxed expression, one three-quarter view, one near-profile, one with the mouth open or mid-expression, one waist-up or full-body shot that shows posture and silhouette, and one captured under lighting close to your target scene. Going past ten references rarely helps and often hurts, because conflicting images dilute the identity embedding and the model averages them into a vaguer face.
Consistency rules for the set
Keep the same person in the same wardrobe when identity is the goal, and move costume changes into the shot prompt instead. Avoid images with heavy beauty filters, wide-angle distortion, motion blur, sunglasses, or hair falling across the face. Match resolution and aspect ratio where you can, because one soft, low-resolution reference drags the entire embedding down. If your subject is a real performer, shoot a deliberate reference session in even, diffuse light with a fixed lens, then reuse those frames for every project that features them. That single afternoon of photography will save dozens of regeneration cycles later.
Mistakes that quietly ruin fusion
Repeating five near-identical photos from the same angle adds no information. Mixing two different people, or one person at two very different ages, produces an averaged stranger. Including a stylized illustration beside a photograph pulls the output toward a plastic, half-painted look. Cropping the top of the head removes the hairline cue the model relies on most. And letting the expression swing wildly between references causes the model to average expressions, which usually reads as a blank, slightly absent stare in motion.
Writing prompts inside a fused identity
Separate the identity block from the scene block
Write every prompt in two mental halves. The identity block names what must not change: apparent age, hair color and texture, facial features, wardrobe, distinguishing marks. The scene block describes what should change: action, environment, camera, lens, light, mood. Keep the identity block word-for-word identical across every shot in a sequence. Any paraphrase is a new instruction, and new instructions invite a new face.
Camera and motion language that helps
Describe camera movement in one short clause and keep it simple: slow push in, static medium shot, handheld follow. Multi-part camera instructions compete with the identity tokens for attention, so the model satisfies the movement and neglects the face. For motion, name the action verb and the beat: she turns her head toward the window and stops. Ambiguous motion gives the sampler room to improvise, and improvisation is exactly where faces slide.
Drift triggers to avoid
Negatives matter as much as positives. Exclude face morphing, multiple people, duplicate limbs, changing eye color, and plastic skin. Avoid contradictions as well: a close-up wide shot, or soft daylight with harsh sunset, forces the sampler to split the difference, and that compromise often surfaces as a subtly different person. If you must describe two light sources, describe their relationship rather than stacking incompatible moods.
Keyframes and physical continuity
From beat sheet to keyframe plan
Break the scene into beats before you touch a generator. Each beat becomes one keyframe: a still that locks pose, framing, wardrobe state, and light direction. Generate and approve stills first, then animate. It is far faster to regenerate an image than to regenerate eight seconds of video that drifts halfway through. This ordering is the single highest-leverage habit in the whole workflow.
Matching keyframes across shots
When a character moves from shot A to shot B, carry over three things: light direction, wardrobe state such as jacket on or sleeve rolled, and the final pose. If the previous shot ends with the head turned right, the next keyframe should not begin facing left unless the cut explicitly motivates it. Track this in a plain continuity list — one line per shot. It takes two minutes and prevents most jarring transitions.
Physical coherence beyond the face
Watch hands, feet, and props. Fusion stabilizes faces; it does not stabilize a coffee cup that changes size between cuts or a doorway that changes height. Lock important props with their own reference image or keep them out of frame. Also watch scale: a character walking through a doorway should read as the same height in both shots, which means keeping lens choice consistent within a scene.
Choosing a model for each shot
Model choice is a trade-off between realism, stylistic control, speed, and cost per second of finished footage. There is no universal best option, only a best option per shot.
Decision criteria
Ask four questions before generating. How much facial detail does the shot need? Is the target style photoreal or illustrative? How long is the shot? How many attempts can you afford before the deadline? A talking-head close-up rewards a model with strong face fidelity and clean micro-expression. A wide landscape with a small figure rewards a model with excellent temporal stability. A stylized anime sequence rewards a stylized model even if its photoreal output is mediocre.
Matching model strengths to shot types
A reliable pattern is to use a high-fidelity image-to-video model for hero close-ups, a faster and lighter model for inserts, cutaways, and B-roll, and a still-image model with strong identity controls to produce keyframes. Resist the temptation to standardize on one model for the entire project; mixed pipelines consistently look better than single-model pipelines when a story has varied shot sizes.
Test before you commit
Run a three-second test of the same keyframe and prompt across two or three models. Compare face stability, hand artifacts, and how faithfully the motion matched your description. Record the winner per shot type in a short note. After two projects that note becomes your default setup and removes most decision fatigue.
A repeatable end-to-end workflow
- Write the scene as beats. Six to twelve beats is a comfortable scene. Each beat must contain one clear action and one clear camera idea.
- Build or refresh the reference set. Five to eight consistent images, matched lighting, same wardrobe, faces unobstructed.
- Generate keyframes as stills and approve them before animating anything. Reject any frame with a wrong hairline or costume detail now, while it is cheap to fix.
- Lock the identity block text. Paste the same block into every prompt in the sequence, and change only the scene block.
- Animate one shot at a time. Start with a three-second test, review it at full size and at thumbnail size, then extend to the full duration once the test holds.
- Run the continuity check between shots: face, hair, wardrobe, light direction, prop state, apparent height.
- Regenerate only the failing shots. Where the tool supports it, reuse the seed and a slightly adjusted prompt rather than randomizing everything.
- Assemble, then apply a light unifying grade. Small color differences between shots disappear under a subtle curve, and the audience reads the sequence as one scene rather than a patchwork.
- Archive the reference set, prompt blocks, keyframes, and the winning model note together, named by character and project, so the next episode starts from a known-good baseline.
Quality control: reviewing output like an editor
Review each generated clip at three scales: full screen, half size, and thumbnail. Full screen reveals micro-expression and skin texture problems. Half size reveals proportion and silhouette drift. Thumbnail reveals whether the character reads as the same person at a glance, which is how most viewers will actually experience your video on a phone.
Score each clip on a simple five-point list: face identity, hair, wardrobe, lighting continuity, and motion quality. Anything scoring low on more than one item gets regenerated rather than salvaged. Editing around a drifting shot usually costs more time than re-rendering it, because drift pulls attention and viewers will remember the one wrong frame.
Finally, watch the sequence with sound off, then with sound on. Muted playback exposes visual continuity errors, and audio often masks small inconsistencies that would otherwise be obvious.
Troubleshooting common failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Face changes on camera turns | Reference set is one-angle only | Add profile and three-quarter references |
| Skin tone shifts between shots | Mixed white balance in references | Rebuild references under one lighting setup |
| Character looks younger or older | References span different ages | Keep one age range and state it in the identity block |
| Hands degrade while the face holds | Identity tokens dominate attention | Shorten the shot, hide hands, or use a wider frame |
| Wardrobe details mutate | Costume described differently each prompt | Freeze the wardrobe sentence verbatim |
| Output looks plastic and over-smoothed | Stylized reference mixed with photos | Remove illustrations and heavy filters |
| Motion ignores the prompt | Prompt conflicts with keyframe pose | Align the keyframe with the intended first action |
Most of these failures come from the reference set rather than from the model. When a shot misbehaves, check the references before switching models. Model switching is a much bigger change than most creators expect, and it resets your hard-won continuity assumptions.
Frequently asked questions
How many reference images do I actually need?
Five to eight high-quality, mutually consistent images cover the vast majority of shots. Below four, drift becomes very likely on any camera angle that is not front-on. Above ten, conflicting details start diluting the identity signal and you often get a generic, less recognizable face.
Can I use this approach for a real actor or only fictional characters?
It works for both, though real people require care around consent, contracts, and platform policies. The technical workflow is identical. The difference is that a real performer can sit for a controlled reference shoot, which produces a much stronger set than anything scraped from existing footage.
Why does the face change specifically when the camera turns?
Because the model was never shown that side of the head. Turning the camera requires the model to invent geometry, and it invents differently in every denoising pass. Adding profile and three-quarter references is the direct fix; reducing the number of large angle changes per shot is the practical workaround.
Do I need a new reference set for every project?
Not for every project, but for every distinct look. If the character wears different wardrobes in two series, keep identity references constant and let the wardrobe live in the prompt block, or build two sets that share the same frontal and profile frames.
How long should each generated clip be?
Shorter is safer. Three to five seconds per generation keeps drift low and makes regeneration cheap. Long, complex takes tend to lose identity somewhere in the second half, and fixing them usually means re-rendering the whole clip anyway.
Is multi-image fusion the same as training a custom character model?
No. Fusion conditions an existing model at generation time using reference images. Training a custom character model bakes the identity into weights, which can be stronger and faster at run time but requires a dataset, time, and a training budget. Fusion is the practical first step and often good enough for episodic short-form work.
What is the fastest way to improve results today?
Cap your shot length, freeze the identity block word-for-word, and add one profile reference to whatever set you already have. Those three changes typically produce a visible jump in consistency without any new tools or a new model.
Putting it together
Character consistency in AI video is not a single setting you enable. It is a chain of small decisions: a clean reference set, a frozen identity block, keyframes approved as stills before animation, continuity checks between shots, and a quality-control pass that regenerates rather than salvages. Multi-image fusion strengthens the weakest link in that chain by giving the model several views of the same person instead of one guess.
Start with a reference session, not with a prompt. Build a set of five to eight consistent images, write two prompt blocks and reuse them, generate stills first, and test every model on a three-second clip before committing to a sequence. Track results in a one-page note per shot type, and archive references and prompts with each finished project.
None of this is exotic. It is the same discipline a live-action crew applies with continuity photos, wardrobe notes, and script supervisors — translated into a generative pipeline where the model, not a costume department, needs the reminder.
