
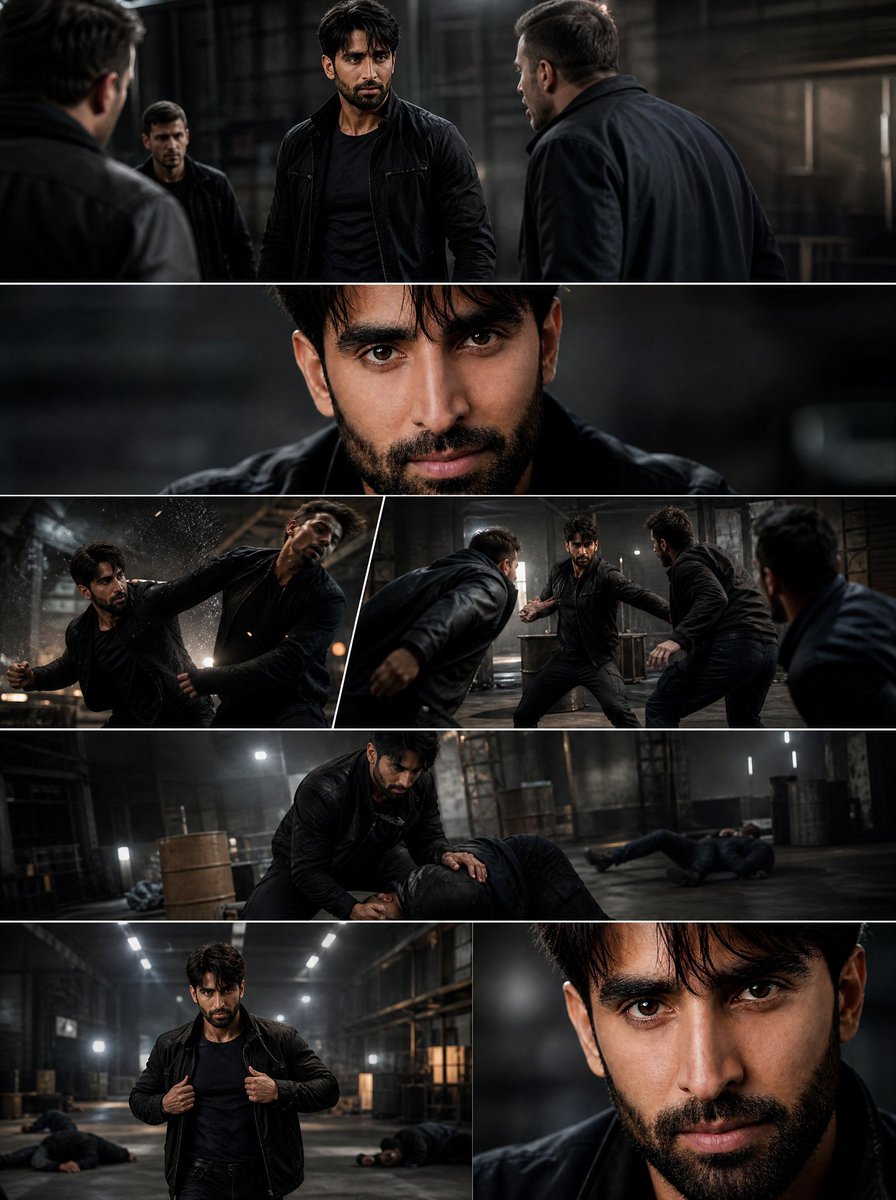
Character drift is the single most common reason an AI video project stalls halfway through. You generate a beautiful hero shot, then spend the next two hours trying to recreate the same face from a slightly different angle — and failing. Multi-image fusion is the technique that solves most of this problem, but it works far better when you treat it as a pipeline discipline rather than a single button press.
This guide walks through how fusion actually behaves under the hood, how to build reference packs that hold up across an entire sequence, how to run a repeatable generation loop, how to pick between generator families, and how to diagnose the failures that still slip through.
Why AI Characters Drift Between Shots
Every modern video generator — whether diffusion-based or transformer-based — is sampling from a probability distribution. When you write "a woman in her thirties with short auburn hair," the model resolves that phrase against an enormous space of possible faces. Each new generation lands on a slightly different point in that space. That is drift.
Text alone cannot fix it, because language is a low-bandwidth channel. "Short auburn hair" does not specify the curl pattern, the exact shade, the hairline, the part, the density at the temples, or how the hair catches light. The prompt leaves hundreds of free variables, and the model fills each one independently per shot.
Three practical consequences follow:
- Identity is under-specified by language. Even very long prompts leave facial geometry largely free.
- Randomness compounds. A seed change plus a camera-angle change plus a lighting change moves the face three times at once.
- Style bleeds into identity. When you describe a mood ("cinematic, moody, teal shadows"), the model often shifts the face to match the mood.
Multi-image fusion addresses all three by supplying visual evidence instead of verbal description. Instead of asking the model to imagine a face, you hand it several views of an existing face and ask it to preserve that geometry while changing everything else.
What Multi-Image Fusion Actually Does
Fusion is the process of conditioning a generation on more than one reference image at a time. Rather than a single anchor image, you provide a set: front view, three-quarter view, profile, a neutral expression, a smiling expression, a full-body shot for proportions, and a detail crop for eyes or hands.
The generator encodes each reference into an embedding, then blends those embeddings into a shared identity representation that influences every denoising step of the new frame. Practically speaking, the model is being told: here is what this person looks like from several directions; now render them in a new pose, new lighting, and new environment without changing who they are.
Reference images as anchors
The first reference usually carries the most weight — it defines the canonical face. The remaining references act as constraints: they narrow the space of acceptable faces and prevent the model from drifting toward a generic archetype.
Embedding blending and weight balance
When you supply five references, the model has to decide which one wins on any given detail. If three references show a rounder jaw and two show a sharper jaw, you will get a jaw somewhere between the two. That is why mixed reference packs produce inconsistent results: contradictory inputs produce averaged outputs.
What fusion cannot solve
Fusion preserves identity. It does not preserve continuity of wardrobe, props, or set geometry unless those are also represented in the references or locked in the prompt. If your character wears a red jacket in shot one and a blue one in shot four, that is a continuity problem, not a fusion problem.
Building a Reference Pack That Survives Every Shot
The quality of your references sets the ceiling for everything downstream. A mediocre fusion of great references beats a great fusion of mediocre references every time.
Choose angles deliberately
A well-rounded pack usually contains:
- Front-facing neutral — the canonical anchor.
- Three-quarter left — reveals cheekbone and nose structure.
- Three-quarter right — the mirrored information helps the model triangulate.
- Full profile — critical for jawline and ear placement.
- Expression variant — one smiling or speaking frame so the model does not lock a deadpan face.
- Body reference — full-length, so height and build are not reinvented.
- Detail crops — eyes, mouth, hands, and any distinctive feature such as a scar or tattoo.
Seven references is a comfortable working number. Going far beyond that often dilutes the signal, because the model starts averaging more aggressively.
Keep lighting and grade roughly consistent
If one reference is lit with warm tungsten and another with cool daylight, the model may interpret the color difference as a skin-tone difference. Normalize your references to a similar white balance before using them.
Clean up before you fuse
Remove background clutter. Crop tightly but leave a little headroom. Upscale soft or low-resolution references so facial detail is legible. If a reference has heavy compression artifacts, the model will faithfully reproduce the artifacts as texture on the face.
Write a one-paragraph character bible
Alongside the images, keep a short written spec: age range, build, hair color and texture, eye color, default wardrobe, distinguishing features, and any continuity rules. This document becomes your prompt scaffolding and prevents you from describing the same character differently across sessions.
A Step-by-Step Fusion Workflow
This is the loop that produces reliable results across a full sequence. It is deliberately front-loaded: most of the work happens before you generate a single video clip.
Step 1: Lock the character sheet
Generate or select one canonical image. This is your ground truth. Do not move forward until you genuinely like this face, because every subsequent shot inherits its flaws and amplifies them.
Step 2: Generate a keyframe test
Before running a full sequence, fuse the character into three hard test frames: a wide shot, a tight close-up, and a profile turned away from camera. These are the three conditions that break weak reference packs. If the character holds in all three, the pack is ready.
Step 3: Fuse for the hero frame
Start each new shot by generating a still, not a clip. Stills are faster to iterate and cheaper to evaluate. Once the still matches your character sheet, animate it.
Step 4: Propagate across shots
When you move to the next shot, feed forward the best frame from the previous shot as an additional reference. This creates a visual chain: every shot is anchored both to the original character pack and to the most recent approved frame. Chaining reduces drift dramatically over long sequences.
Step 5: Review against a checklist
Run every generated shot through the same short review: facial geometry, hairline, eye color, skin tone, wardrobe, and prop continuity. Reject on any mismatch rather than hoping the next shot will fix it — drift compounds forward, not backward.
Step 6: Correct and re-fuse
When a shot fails, change one variable at a time. Adjust the reference weighting, swap a contradictory reference out of the pack, or simplify the prompt. Changing three things at once makes it impossible to learn what actually worked.
Choosing a Generator Model for Fusion Work
Different model families handle multi-reference conditioning differently. There is no universally best choice — only a best choice for the current shot.
Prioritize fidelity when identity matters
For close-ups, dialogue shots, and anything where the audience will study the face, choose the model that shows the strongest reference adherence, even if it renders more slowly. Fidelity models tend to preserve fine detail like eyelashes, iris texture, and skin pores.
Prioritize motion and speed for wide shots
For establishing shots, crowd scenes, and fast camera moves, a faster model with looser reference adherence is often fine. The face occupies a small portion of the frame, and motion smoothness matters more than pore-level detail.
Test systematically, not by vibes
Run the same five-shot test sequence through two or three candidate models and compare them side by side on the same checklist. Keep a simple log: shot number, model used, reference count, prompt variant, pass or fail. After twenty entries you will have a clear picture of which model suits which shot type in your project.
A rough decision guide:
- Tight close-up, emotional beat → highest-fidelity fusion model, maximum references.
- Medium dialogue shot → balanced model, standard pack plus previous-frame chaining.
- Wide or action shot → fastest model, lean pack, motion prioritized.
- Stylized or animated look → model with strong style conditioning, since the style shift can otherwise distort identity.
Prompt Patterns That Protect Identity
Good fusion still benefits from good prompting. The goal is to describe everything except the face, so the model has nothing to invent about identity.
- Describe scene, action, and camera — not appearance. Say "medium shot, she turns toward the window, soft side light" rather than restating hair and eye color.
- Name the wardrobe explicitly. Clothing is a common drift vector. If it matters, spell it out.
- Avoid identity adjectives that fight the references. Words like "striking" or "ethereal" push the model toward idealized archetypes and away from your specific face.
- Keep negative prompts focused. Excess negative terms can flatten expressions and make characters look rigid.
- Use consistent phrasing across shots. Varying your wording per shot adds unnecessary variation.
Common Mistakes and How to Fix Them
The averaged face. Two references disagree on bone structure, so the result is a blend. Fix: remove the outlier reference.
The melted background. Too many references with busy backgrounds bleed scenery into the new frame. Fix: crop and clean references before fusing.
The frozen expression. A pack composed entirely of neutral shots produces a character who never emotes. Fix: include at least one expressive reference.
The age shift. Soft references cause the model to guess at age. Fix: use higher-resolution, well-lit references with clear skin detail.
The costume reset. Fusion preserves the face, not the outfit. Fix: describe wardrobe in the prompt every single shot.
The style override. A strongly stylized scene forces the character into that style's typical face. Fix: reduce style intensity or add the previous frame as a reference.
Scaling Consistency Across a Full Project
Single shots are easy. Sequences are where discipline pays off.
Maintain a project folder with a locked character pack, an approved-frames folder, and a rejected-frames folder. When a new shot is approved, move it into the approved set and consider adding it to the reference pack for that character's later scenes.
Build in a small amount of redundancy. If a shot is critical, generate three versions and pick the best. The cost of an extra generation is trivial compared to the cost of a reshoot.
Finally, define an identity tolerance early. Some projects need frame-perfect consistency; others can accept minor variation because the camera is rarely still. Knowing your tolerance prevents you from over-polishing shots that will never be examined closely.
FAQ
How many reference images is ideal?
Four to eight well-chosen references usually outperform twenty mediocre ones. Quality and consistency matter more than count.
Can I use a single reference and still get consistency?
Yes, for short sequences and simple camera work. Accuracy drops sharply as soon as you leave the reference's original angle.
Does fusion work for stylized or animated characters?
Yes, and it often works better, because stylized geometry is easier to define precisely than photoreal facial detail.
What causes a character to look like a sibling rather than the same person?
Usually blended references or a prompt that adds generic identity adjectives. Remove contradictory references and strip appearance language from the prompt.
Should I reuse the same seed across shots?
Reusing a seed reduces variation but can also lock in unwanted artifacts. Prefer reference chaining over seed locking for identity work.
How do I handle a character who changes costume mid-story?
Keep the same facial reference pack and change only wardrobe description in the prompt. Build a second pack only if the character's age or body changes.
A Practical Checklist Before You Generate
- Character sheet locked and approved.
- Reference pack normalized for lighting and resolution.
- Backgrounds cleaned and cropped.
- Written character bible with wardrobe and distinguishing features.
- Three keyframe tests passed: wide, close-up, profile.
- Model selected for the shot type, with a fidelity-first fallback.
- Prompt describes scene and action, not facial appearance.
- Previous approved frame ready for chaining.
- Review checklist printed or pinned for every generated shot.
Multi-image fusion is not a shortcut around craft. It is a way of encoding your decisions so they survive the randomness of generation. The teams that get consistent characters are rarely using secret settings — they are simply preparing references carefully, testing on hard frames early, and changing one variable at a time until the face they see on screen is the face they designed.
