
Why Character Consistency Is the Hardest Problem in AI Video
Ask anyone who has shipped a multi-scene AI video what broke first, and the answer is almost always the same: the face. Scene one delivers a convincing protagonist. Scene four delivers a cousin — same wardrobe, different bone structure. Viewers may not articulate what is wrong, but they feel it, and the illusion collapses.
The cause is structural rather than bad luck. Most generative video models do not carry a persistent memory of your character between generations. Each shot is a fresh sample from a probability distribution conditioned on your text prompt and whatever reference images you supply. Tiny variations in that conditioning compound across a sequence: hair length shifts half an inch, the jaw softens, skin tone warms, the nose shortens. Over twenty shots you get twenty near-misses.
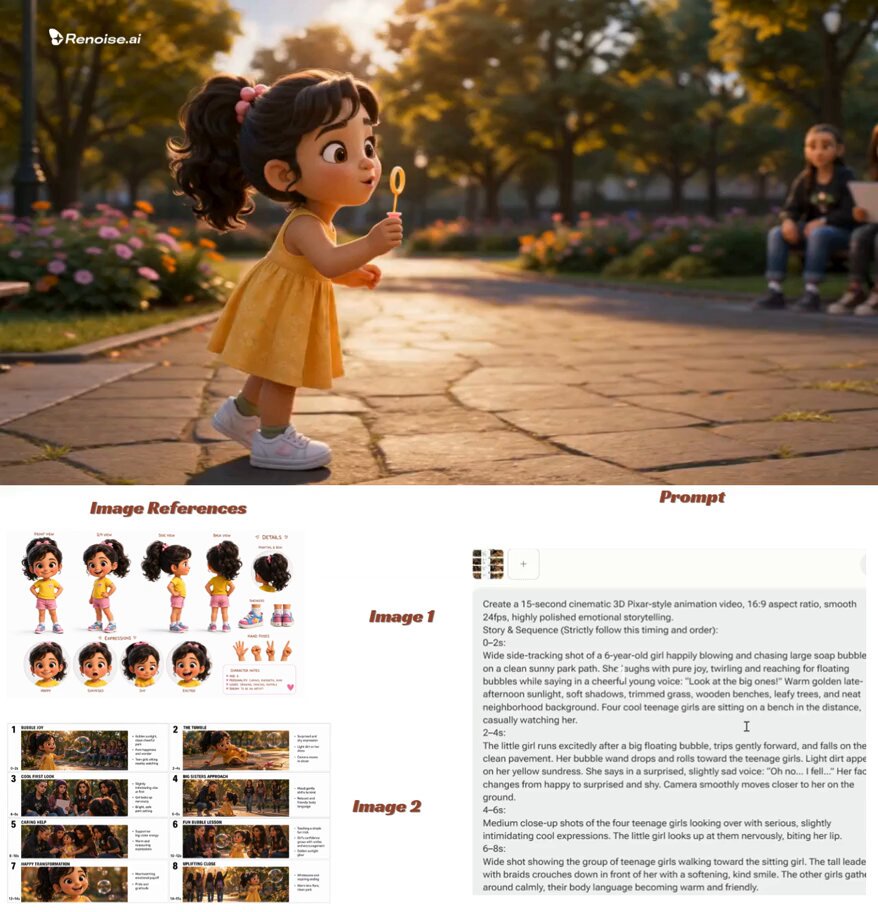
Multi-image fusion is the practical answer. Instead of describing a character in words alone, or handing the model a single portrait, you build a small reference library and let the model fuse those images into a stable identity representation. That representation then anchors every shot, whether the character is walking through rain, sitting in a cafe, or standing in a wide establishing shot where the face is twelve pixels tall.
This guide walks through the full workflow: how fusion actually works, how to build a reference set that survives every scene, how to prompt for identity, how to catch drift before you commit to a render, and what to do when consistency still fails.
What Multi-Image Fusion Actually Does
Multi-image fusion (MIF) means conditioning a generation on several images of the same subject simultaneously, rather than one. The model encodes each reference into an embedding — a numerical summary of identity — and then combines those embeddings into a single conditioning signal.
Semantic and geometric cues
References carry two kinds of information, and good reference sets supply both.
- Geometric cues describe shape: the distance between the eyes, the width of the jaw, the slope of the shoulders, the volume of the hair. These are what make a face recognizable at a glance.
- Semantic cues describe meaning and surface: skin texture, clothing material, colour palette, age impression, styling. These keep the character feeling like the same person rather than a 3D-printed mannequin.
A single frontal portrait is geometric but semantically thin. A single candid photo is semantically rich but geometrically ambiguous. Fusion works best when the set spans both.
Where fusion sits in the render pipeline
Depending on your tool, fusion operates at one of three stages:
- Still generation — you produce your character with a text-to-image model using a fused reference set or a trained adapter.
- Image-to-video — a locked still becomes the first frame, and the video model animates from it. Identity is inherited from the still, which makes this the most reliable route for strict continuity.
- Direct video conditioning — the video model accepts multiple references and fuses them internally while generating motion. More flexible, less predictable, and more sensitive to reference quality.
Most professional-looking sequences use a hybrid: fusion for stills, image-to-video for motion, and a final consistency pass.
Building a Reference Set That Survives Every Scene
The reference set is the single highest-leverage asset in the entire workflow. A weak set guarantees drift no matter how good your prompt is. Aim for eight to twelve images per character.
What to include
- A clean neutral portrait in even, diffuse lighting — your identity anchor.
- Three-quarter and profile angles. These teach the model how the face behaves in three dimensions. A set made entirely of frontals produces characters who turn into strangers at 45 degrees.
- A full-body shot so proportions, height impression, and build are captured.
- A wardrobe plate showing the outfit without occlusion, ideally on a plain background.
- Two or three expression variations — a smile, a serious look, a mid-speech frame.
- A lighting variation with directional light, which helps the model separate identity from illumination.
What to exclude
- Heavy filters, beauty smoothing, or strong colour grading — the model will bake those into identity.
- Sunglasses, hands over the face, or hair covering the features.
- Watermarks, logos, or visible text.
- Near-duplicate frames. Twelve near-identical shots add no information and can actually dilute the averaged embedding.
- Mixed lighting temperatures, unless you specifically want that baked in.
Organize the set as a project asset
Name files so they sort meaningfully: char_ava_face_front_01.png, char_ava_body_full_01.png, char_ava_wardrobe_plate_01.png. Keep one folder per character and one folder per outfit variation. Six months later, when you need a sequel, the set is still usable and you will not be reconstructing it from memory.
The Shot-by-Shot Production Workflow
Consistency is a process, not a button. Here is a sequence that holds up across a ten- to thirty-shot piece.
Step 1: Lock the character sheet
Generate or select one hero image and treat it as canon. Everything downstream references it. Write down the exact references used, the seed if the tool exposes it, the prompt, and the model version. Model updates change output distributions, so a sequence generated across a version change will drift even with identical inputs.
Step 2: Generate in waves, not one at a time
Generate four to six candidate frames per shot in a single batch, then review them side by side. Batch review makes drift obvious — your eye catches the outlier instantly when frames are adjacent. Sequential one-off generation hides drift until it is expensive to fix.
Step 3: Keep a continuity ledger
A simple table prevents 80% of continuity errors:
| Field | Example |
|---|---|
| Shot ID | S07 |
| Outfit | Grey coat, red scarf |
| Hair state | Wet, pushed back |
| Time of day | Late afternoon |
| Key light direction | Camera left, low |
| Props | Leather satchel, left hand |
| References used | face_front_01, body_full_02 |
| Seed | 4471932 |
| Notes | Continues from S06 |
When shot twelve suddenly shows the scarf on the wrong shoulder, the ledger tells you whether that is a generation error or your own scripted change.
Step 4: Animate from locked stills
For any shot where the character is clearly visible, generate the still first, approve it, then animate using image-to-video. This converts an identity problem into an approval problem, and approval is something you can actually solve.
Step 5: Reserve wide shots for relief
Wide and rear-facing shots are more forgiving. Use them to break up the sequence and to hide transitions where a slight identity shift is least visible. A cut from a close-up to a wide back shot buys you a scene change with no continuity cost.
Prompt Patterns That Preserve Identity
Text prompts still matter, even with strong references. The trick is to treat identity clauses as constants and everything else as variables.
Write an identity block once and reuse it verbatim
Create a short block — for example: "woman in her early thirties, oval face, dark brown hair to the collarbone, straight eyebrows, warm mid-tone skin, athletic build." Paste it into every prompt unchanged. Rewriting it each time, even with synonyms, shifts the conditioning.
Order the prompt consistently
A reliable order is: subject and identity block, action, environment, camera and lens, lighting, style. Keeping the order stable across shots reduces unexplained variation.
Change one variable at a time
If you need the character to be in a kitchen instead of a park, change the environment clause only. Do not simultaneously rephrase the hair, the lens, and the mood. When something breaks, you need to know which change caused it.
Use negative prompts against known failure modes
Maintain a standing negative list targeting the drift you actually observe: mismatched facial features between sequences, changing hair length, extra fingers, distorted hands, warped background text, identity blending between two characters. Update it as new failure modes appear.
Be careful with style adjectives
Stacking descriptors like "cinematic, hyperreal, film grain, moody" in one shot and "clean, bright, editorial" in the next pulls the render in different directions, and identity often rides along. Pick one style signature for the whole sequence and repeat it exactly.
Handling Expression, Micro-Movement, and Style Drift
Identity is not only bone structure. Performance matters too, and it is where fusion gets tested.
Neutral baseline plus delta
Ask for expressions as deltas from your neutral reference: "slight smile, eyes open, head tilted five degrees." Broad emotional instructions like "ecstatic" or "furious" push the model to reshape the face, because extreme expressions in training data come with different facial geometry.
Keep head pose close to reference
Large pose changes force the model to hallucinate unseen angles. When a shot calls for a strong turn, generate an intermediate frame at a milder angle first and use it as the anchor for the next one. Chaining three or four intermediate angles produces far more reliable rotation than jumping straight to profile.
Separate style from identity
If you want a painterly or animated look, apply the style consistently across the whole sequence rather than per shot. Better still, generate the stills in your target style using fused references, so identity and style are baked together once. Style drift is most visible when the character's rendering changes between consecutive cuts.
Control micro-movement
Micro-movement — breathing, blinking, small hand gestures — is where video models improvise most. Keep motion instructions modest: "subtle head turn, slight blink, minimal body movement." Overly dynamic prompts increase the chance the model regenerates facial features to support the motion.
Quality Control Before You Commit
Run a structured review pass before spending time on a long render or an edit session.
- Face similarity: crop the head from each shot and place them side by side. Rate each from 1 to 5 against the hero frame. Anything below 3 gets regenerated.
- Silhouette check: squint at the sequence. Even blurred, the body shape and posture should read as one person.
- Wardrobe continuity: scarf, collar, buttons, sleeve lengths, jewellery, and any asymmetry between left and right.
- Lighting continuity: key light direction should not flip between adjacent shots unless a cut motivates it.
- Artifact sweep: hands, teeth, ears, background text, and edges where hair meets background.
- Motion sanity: watch at half speed. Warping around the jaw and eyes is where identity failure usually shows first.
Log every rejection with the reason. Patterns emerge quickly — three rejected shots with the same cause usually point to a fixable reference or prompt problem rather than bad luck.
Common Mistakes and How to Fix Them
Too many conflicting references. Mixing photos with different hairstyles or ages averages into a character who resembles none of them. Prune to the set that matches your script.
All references from one angle. Add three-quarter and full-body plates. Frontal-only sets fail the moment the character turns.
Rewriting the prompt every shot. Identity clauses should be copied and pasted, not paraphrased.
Switching tools mid-sequence. Different models interpret the same reference differently. Lock your stack for the project.
Ignoring aspect ratio. Changing the frame shape changes the composition and often the crop of the face, which changes how the model resolves identity.
Overspecifying the performance. No model can hold a face perfectly through a sprint, a spin, and a shout. Design the shot list around what the technology does reliably, and use cuts, wides, and inserts to cover the gaps.
Choosing the Right Stack for the Job
Different routes suit different levels of identity strictness.
- Text-to-video with reference conditioning: fastest, most flexible, least consistent. Good for mood pieces and abstract content.
- Image-to-video from approved stills: the workhorse for narrative sequences. Consistency comes from the still, so quality depends on your image pipeline.
- Trained character adapters: when identity must be exact across dozens of shots, train a small adapter on twenty to thirty curated images. It takes preparation, but the payoff is a character who holds up across angles, lighting, and outfits.
- Hosted all-in-one platforms: convenient, with reference and character-lock features built in. Trade-off is less control over sampling and less portability of your assets.
- Node-based local pipelines: maximum control and reuse, higher setup cost.
A practical default for most projects: generate stills with a fused reference set, train a light adapter if the sequence exceeds twenty shots, animate with image-to-video, and reserve direct video conditioning for shots where the face is not the focus.
Scaling to Multi-Scene Productions
Once a single sequence works, repeatability becomes the challenge.
Keep an asset library with versioned character sheets, wardrobe variants, and style plates. Use a shot naming convention that includes sequence, shot, and version. Insert review gates — nothing moves to animation until the still passes the face similarity check. Assign continuity ownership to one person, even on a small team, so the ledger has a single author.
Build a reusable prompt library with your identity blocks, negative lists, and style signatures stored as templates. The second project then costs a fraction of the first, because the hard part — a stable identity — is already solved.
Frequently Asked Questions
How many reference images do I actually need?
Eight to twelve well-chosen images cover most cases. Below five, the model lacks enough geometric information. Above fifteen, conflicting details start averaging together.
Can I keep a character consistent without any references?
Only for very short sequences. Detailed, repeated identity text gets you a few shots before visible drift. Multi-image fusion is the reliable path.
Why does the character look right in stills but change when animated?
Video models re-synthesize frames rather than tracking them. Motion-heavy prompts and large pose changes increase the risk. Reduce motion ambition, animate from approved stills, and keep head pose near the reference angle.
Do I need to retrain anything if I switch models?
Usually yes. References and adapters are model-specific in how they are interpreted. Test with the new model before migrating a whole project.
What is the fastest fix for a drifting sequence?
Re-anchor to the hero shot. Regenerate the offending shots with the exact reference set and prompt used for the hero frame, changing only the environment clause.
Should I generate all stills first, or interleave stills and video?
Generate all stills first. Approving a complete image sequence reveals continuity problems while they are still cheap to fix, rather than after twenty video renders.
How do I handle two characters in one shot?
Keep reference sets strictly separated, describe each character in a distinct clause, and avoid prompts that let the model blend features. Two-character shots are the highest-risk frames in any sequence — generate extra candidates and expect to reject more of them.
Consistent characters are not the result of one clever setting. They come from a disciplined pipeline: a curated reference set, verbatim identity prompts, batched review, a continuity ledger, and honest quality control. Build that once and multi-scene AI video stops feeling like a gamble.
