
Multi-image fusion is the difference between an AI video that looks promising in isolated frames and one that holds together as a finished piece. Most teams discover the problem the same way: a character looks perfect in shot one, slightly off in shot four, and like a different person by shot nine. Lighting drifts, wardrobe mutates, and the camera seems to forget what the room looked like two seconds ago.
Multi-image fusion — feeding several reference images into a generative video model so it blends them into one coherent target — is the most practical answer available today. Instead of describing a person with words and hoping the model lands in the same place twice, you hand it visual anchors and let it carry that information forward.
This guide covers how fusion actually works, how to build reference packs that models can read, a shot-by-shot workflow, prompt patterns, failure modes, and a quality checklist you can reuse on every project.
Why Character and Scene Consistency Breaks AI Video
Generative video models are trained to produce plausible motion, not to remember your story. When you generate shots independently, each one is a fresh roll of the dice. The model has no memory of the previous shot unless you give it one.
Three forces push shots apart:
Identity drift. Faces, hair, and proportions shift gradually. A single frame rarely looks wrong, but a sequence exposes the drift immediately. This is the failure that audiences notice fastest, because humans are extraordinarily sensitive to faces.
Environment drift. A room's wall color, window position, and furniture layout change between angles. Even small inconsistencies break the illusion of a single physical space.
Lighting and grade drift. Shot A is warm and soft; shot B is cool and contrasty. Individually both look good, but cut together they feel like two different productions.
Text-only prompts handle all three poorly because language is a lossy way to describe appearance. Words like “young woman with dark hair” cover millions of possible faces. Reference images collapse that ambiguity in a way that no adjective can.
A useful mental model: think of fusion as casting plus continuity in one step. You are not just telling the model what to draw; you are showing it who is on set, what they are wearing, and where they are standing.
What Multi-Image Fusion Actually Does
Fusion is the process of conditioning a generation on multiple visual inputs at once. Different systems implement it differently, but the practical behaviour is similar: the model extracts features from each reference and uses them to constrain the output.
The three reference roles
Almost every productive reference pack maps to three roles:
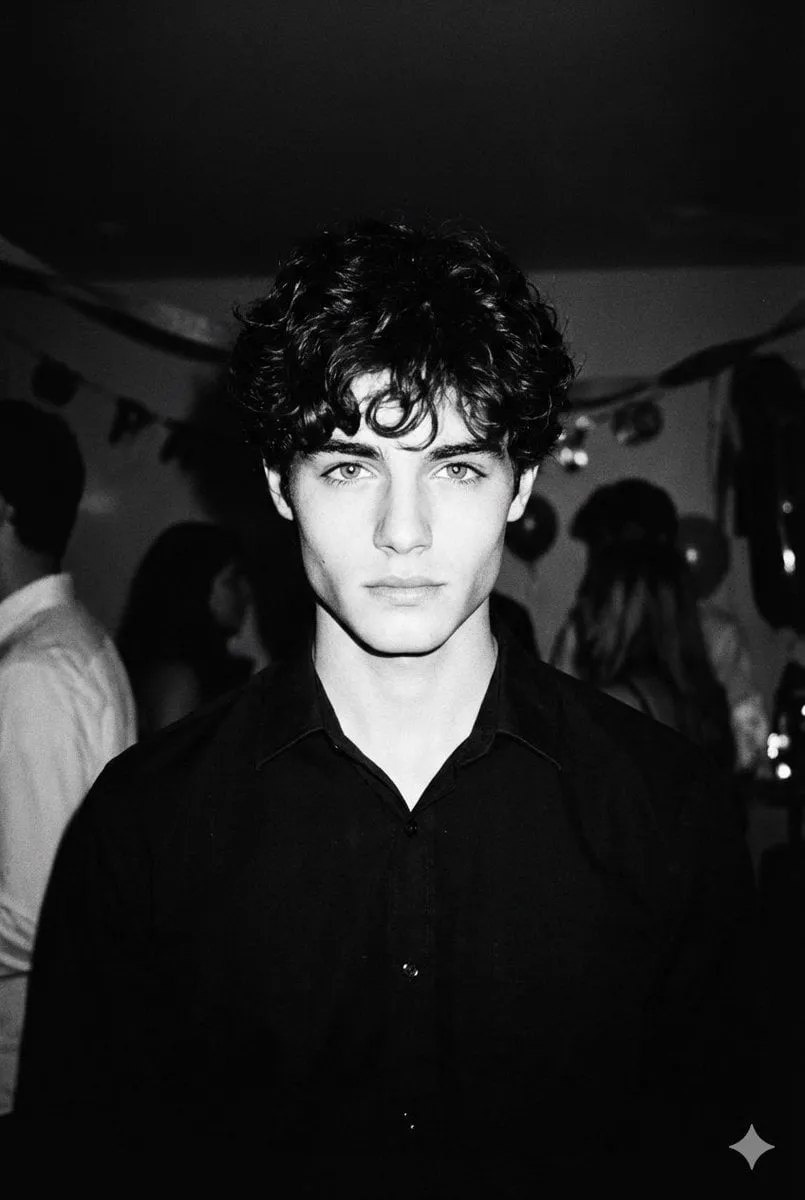
- Identity references — close, well-lit images of the subject's face and body at neutral angles. These carry who the subject is.
- Style references — frames that define palette, contrast, film grain, lens character, and rendering look. These carry how the footage should feel.
- Context references — plates of the location, props, or wardrobe. These carry where the scene lives and what belongs in it.
Mixing roles is the single most common setup mistake. If your only reference image is a heavily stylised low-angle shot, you are asking the model to learn identity from a bad identity source.
How blending usually happens
Most production pipelines combine references in one of three ways:
- Concatenated conditioning, where all images are attached to a single generation pass. Fast, but references compete; a strong style image can overwhelm a weak identity image.
- Sequential conditioning, where you generate an anchor frame with identity references, then use that approved frame as the reference for subsequent shots. Slower, but far more stable across a long sequence.
- Hybrid approaches, where identity comes from a face reference, style from an approved keyframe, and layout from a depth or pose hint. This is the most controllable option for scripted content.
For anything longer than a few shots, sequential conditioning with an approved anchor frame is almost always worth the extra render time.
What fusion does not fix
Fusion cannot rescue a bad plan. If your shot list has an unmotivated camera move, a jump in time with no visual bridge, or a costume change that is never explained, a consistent render will simply make those problems clearer. Fix the edit logic first.
Building a Reference Pack That Models Can Read
Quality of input beats quantity. Ten mediocre references are worse than four excellent ones, because contradictory signals force the model to average them.
How many images to use
A practical starting point:
- 2–4 identity images for a recurring character: roughly frontal, three-quarter, and profile, all in similar lighting.
- 1–2 style frames that match the target look. More than three style frames usually muddies the grade.
- 1–3 context images per location, ideally including one wide shot that shows the full layout.
If a character appears in a new costume, build a separate reference set for that costume rather than adding more images to the original set.
Preparing images properly
Small preparation steps have outsized effects:
- Crop tight but keep context. A face reference should be mostly face; a wardrobe reference should show the full outfit.
- Match lighting direction across identity references. Mixing a hard side-light with flat frontal light teaches the model two incompatible faces.
- Normalise colour. If one reference has a heavy teal grade and another is neutral, the output will oscillate.
- Remove clutter. Backgrounds full of unrelated detail leak into generations. Mask or crop where you can.
- Keep resolution high but not enormous. Over-compressed references produce soft faces no matter how strong the model is.
Avoiding conflicting signals
Write down what each reference is responsible for before you start generating. If two images disagree about hair length, eye colour, or jacket style, decide which one wins and delete the other. Ambiguity in the pack becomes randomness in the output.
A Shot-by-Shot Multi-Image Fusion Workflow
This sequence works for narrative spots, product films, explainers, and social series alike.
Step 1: Write the shot bible
Before generating anything, record for each shot: subject, action, camera angle, lens feel, lighting condition, background, and duration. Keep it in a table. This document becomes your quality reference and your brief if another editor picks up the project.
Step 2: Approve a character sheet
Generate still images first. Test the identity references until you have a face and silhouette you are happy with from at least three angles. Only then move to video. Approving identity in stills is dramatically cheaper and faster than discovering drift after rendering motion.
Step 3: Fuse references per shot
The most reliable pattern is to generate shot one as your anchor, approve it, then use the approved frame plus the identity references for shot two, and so on. Each new shot inherits from an already-verified predecessor, so errors cannot compound silently.
Step 4: Iterate on motion, not identity
Once identity is locked, change only one variable per attempt: camera move, action timing, or performance intensity. If you change the reference pack and the prompt simultaneously, you will not know which change produced the improvement.
Step 5: Assemble and check continuity
Cut the shots together early, before polishing. Play the sequence at normal speed with sound. Drift is easy to miss in a timeline of thumbnails and obvious in playback. Fix the offending shot, regenerate, and re-cut.
Step 6: Finish with grade and sound
Multi-image fusion gets you a consistent base, not a final look. A unified grade pass, consistent grain, and a deliberate sound design pass do more for perceived quality than another round of generation.
Prompt Patterns That Keep Fusion Stable
Prompts and references work together. The reference says who and what; the prompt says what is happening and how the camera behaves.
Describe motion, not appearance. “She turns toward the window, hair catching the light” is useful. “Dark-haired woman in a beige coat” duplicates a job the reference already does and can override it.
State the camera explicitly. “Slow push-in, 50mm, shoulder height” gives the model a physical frame of reference that reduces wild motion.
Repeat the scene conditions every shot. If the scene is “interior, late afternoon, soft window light,” include it in every prompt of that scene. Consistency in text reinforces consistency in image.
Keep negative instructions short. Long lists of exclusions tend to introduce the very artefacts they name. Two or three targeted negatives are usually enough.
Version your prompts. Store each prompt beside the reference set and the approved output. When a later shot drifts, you can compare and spot which parameter changed.
A simple prompt skeleton that works well across tools:
[Shot type and camera move], [subject action], [wardrobe or prop detail],
[lighting condition], [location], [style and lens reference],
[continuity note referencing previous shot]
The continuity note is the underused part. A short phrase such as “same wardrobe and lighting as previous shot” helps both human collaborators and automated pipelines keep the thread.
Where Multi-Image Fusion Fits in Your Toolchain
Fusion is a stage, not a product. Treat it as a step between pre-production and post-production.
Concept and script. Traditional writing tools. Nothing about fusion changes the need for a clear story.
Reference assembly. Image editing or a DAM. Build, crop, colour-normalise, and label your reference packs here.
Stills approval. Image generation with identity references. This is where casting happens.
Fusion generation. Video generation with identity, style, and context references combined.
Continuity review. Editing software with playback at speed.
Post. Grade, grain, sound, titles, and delivery encoding.
Decision criteria for tool choice come down to four questions: Does it accept multiple references in one pass or only one? Can you reuse an approved frame as a reference? How much control do you have over motion and camera? And does the export quality hold up at delivery resolution? A tool that is weak on the first two will cost you more time in regeneration than it saves anywhere else.
Common Failure Modes and Fixes
Face morphing mid-shot. Usually caused by identity references with conflicting lighting or by an overly stylised style reference. Fix: rebuild the identity set with consistent lighting and reduce style references to one.
Wardrobe changes between cuts. The context references are ambiguous. Fix: create a dedicated wardrobe plate and include it in every shot of that scene.
Background flicker. Too much unrelated detail in reference images. Fix: crop references closer to the subject, or generate against a simpler plate and composite the environment later.
Motion that ignores the prompt. The reference set is dominating. Fix: strengthen the action description and simplify the pack. Fewer references often produce more obedient motion.
Colour shifts scene to scene. Style references are inconsistent or absent. Fix: pick one approved keyframe per scene and use it as the style anchor for every shot in that scene.
Over-smoothed, plastic faces. Typically a resolution or compression issue in the references. Fix: use higher-quality source images and avoid re-compressing repeatedly.
Good frames, bad sequence. A rhythm problem, not a fusion problem. Fix: cut to the beat, vary shot length, and accept that some beautiful shots do not belong in the edit.
Quality Control Checklist Before Final Render
Run this before committing to a full-resolution render:
- Identity holds across every shot the character appears in, checked at speed.
- Wardrobe, hair, and key props are consistent per scene.
- Lighting direction and colour temperature are stable within a scene.
- Camera height and lens feel do not jump arbitrarily.
- Screen direction and eyelines are preserved across cuts.
- No morphing, warping, or limb distortions at shot boundaries.
- Background details remain static where the camera is static.
- Reference packs, prompts, and approved frames are archived with the project.
That last point matters more than it sounds. When a client asks for a revision three weeks later, an archived reference pack plus prompt history turns a rebuild into a quick regeneration.
Turning Fusion Into a Repeatable Studio Process
Teams that ship consistently treat fusion as infrastructure rather than improvisation. Three habits separate them from teams that restart from scratch each project.
Standardise the reference pack format. Same number of images, same naming convention, same folder structure. New team members should be able to open a project and immediately see what each image is for.
Approve at the cheapest stage. Never approve identity in video if you can approve it in a still. Never approve a full render if a low-resolution pass would reveal the problem.
Log what changed. One line per generation attempt: references used, prompt variation, result. After twenty shots, this log is the only thing that tells you why shot eleven worked.
FAQ: Multi-Image Fusion in Practice
How many reference images is too many? Once references disagree with each other, more images make results worse. For most characters, two to four identity images plus one style frame is the sweet spot. Add context images only when the environment genuinely needs to be reproduced.
Can I use fusion for a full-length narrative? Yes, but manage it in scenes. Lock identity and style per scene, generate the scene, review at speed, then move on. Trying to hold a single reference pack across an entire runtime invites slow drift.
Does fusion replace a prompt? No. References control appearance and continuity; prompts control action, camera, and timing. Weak prompts produce static, lifeless shots even with perfect references.
What if my subject is a product rather than a person? The same logic applies. Use clean studio plates for shape and finish, one lifestyle or hero frame for style, and context images for the setting. Products are often easier because they do not move facial features.
Should I generate at final resolution immediately? No. Approve at lower resolution, then render the approved shots at delivery quality. Iterating at full resolution burns time without improving decisions.
How do I handle a character who ages or changes costume? Build a separate reference set per state and treat the transition as its own shot. A deliberate, well-lit transition shot reads as intentional; a gradual morph reads as an error.
Can I mix footage and generated shots? Yes, and it often improves the result. Real plates give you accurate lighting and perspective references. Match the generated shots to the plate's grade rather than the other way around.
What is the biggest mistake beginners make? Using one beautiful, highly stylised image as the entire reference for a character. It looks great in isolation and produces drift immediately in motion.
The Bottom Line
Multi-image fusion is not a magic consistency button; it is a discipline. You decide what each reference image is responsible for, approve identity in stills, generate in sequence from verified frames, and check the result at playback speed rather than as isolated stills. Do that, and the technology stops being a source of unpredictable surprises and starts behaving like a controllable production tool.
The teams getting the most out of it are not using the most references or the most exotic settings. They are the ones with a clear shot list, a tidy reference folder, and a habit of approving early and cheaply. Everything else is refinement.
