
AI video generation has moved past the point where a single sentence can produce one beautiful five-second clip. The hard part now is making the tenth clip look like it belongs to the same film as the first. Multi-image keyframing is the technique that closes that gap: instead of describing a shot and hoping, you place anchor frames at defined moments in a timeline and let the model synthesize the motion between them.
This guide covers what multi-image keyframing is, which model families handle it well, how to design keyframe sets that survive interpolation, and how to run the whole process as a repeatable production workflow rather than a series of lucky renders.
Why Text-Only Prompts Stall on Longer Sequences
Text-to-video models are trained to satisfy a prompt, not to obey a plan. Give a model the prompt "a woman in a red coat walks through a rain-soaked market" and you get a convincing few seconds. Stretch that idea into eight shots across ninety seconds and the seams appear: the coat drifts from crimson to burgundy, the market stalls rearrange themselves, the light jumps from overcast to golden hour, and the face slowly becomes a different person.
Three forces cause this drift.
Sampling variance. Every generation starts from a different noise seed. Small differences compound across shots, and nothing in a text prompt pins them down.
Context limits. Even engines with long temporal windows compress earlier frames into a lossy summary. The further a frame sits from the prompt tokens, the weaker the constraint becomes.
Semantic ambiguity. "Red coat" spans thousands of valid fabrics, silhouettes and shades. Nothing in the prompt says which one is correct for your story.
Keyframing attacks all three at once. It converts a language problem into a geometry problem: instead of describing what should happen, you show the model two or more states and ask it to travel between them.
What Multi-Image Keyframing Actually Changes
Multi-image keyframing is the practice of supplying several reference images at known positions in a timeline — typically a first frame, one or more middle frames, and sometimes a final frame — and letting the model synthesize the motion that connects them. The output is not a slideshow crossfade. A capable engine generates genuinely new in-between frames with plausible physics, occlusion and camera movement while respecting the supplied anchors.
The anatomy of a keyframe set
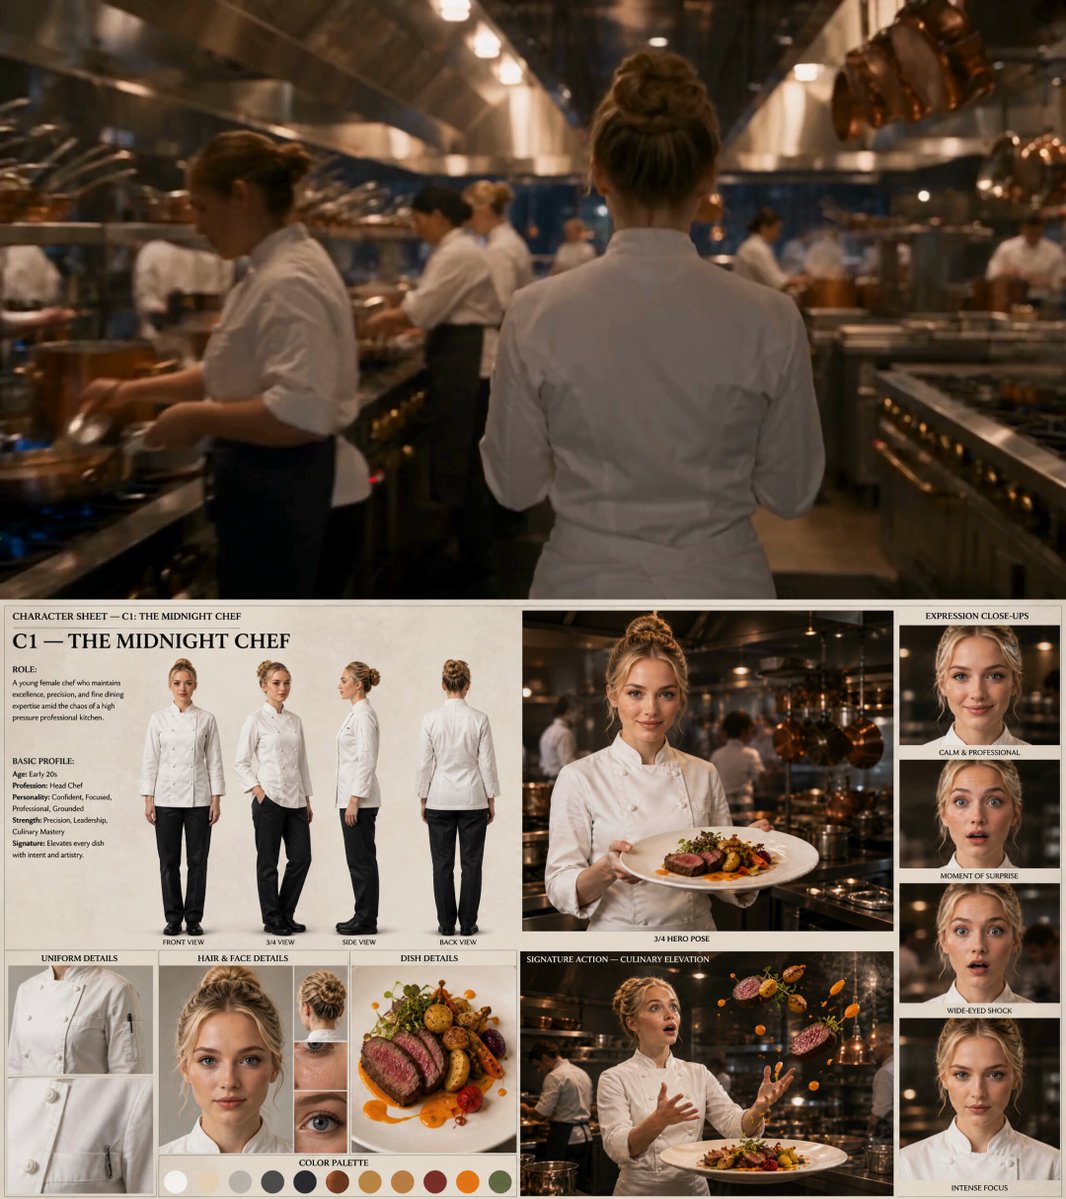
A typical set for one shot contains:
- Start frame: full subject, correct wardrobe, correct lens, correct light direction.
- Mid frame: the subject has moved through roughly half the action, and the camera may have pushed in.
- End frame: the final pose and framing, composed so it cuts cleanly into the next shot.
- Optional control plates: depth maps, pose skeletons or segmentation masks that pin down body mechanics when the action is complex.
The set works as a contract. Everything visible in every anchor is treated as fixed; everything between anchors is the model's job.
Interpolation versus morphing
Two techniques get confused constantly. Interpolation synthesizes new content: a character turns their head and the model invents the cheek, ear and hair that appear mid-rotation. Morphing warps existing pixels: the two anchors blend, producing the melting-face artefact everyone has seen online.
Interpolation is what you want for people, animals and anything with a hidden side that must be revealed. Morphing is acceptable for abstract transitions, texture loops and background plates where geometry barely changes. The practical test is simple — if the midpoint requires information that exists in neither anchor, you need an interpolating model, more keyframes, or both.
How Keyframing Compares to Other Control Methods
Keyframing is one of several ways to steer a generative video model. Knowing when each method earns its place saves more render time than any prompt trick.
| Method | Control over identity | Control over motion | Best for |
|---|---|---|---|
| Text only | Low | Low | Exploratory mood clips, backgrounds |
| Single image to video | Medium | Low | Product spins, subtle idle motion |
| Multi-image keyframing | High | High | Character-driven narrative shots |
| Video-to-video restyle | High | Preserved from source | Stylization of existing footage |
| Motion brush or trajectory tools | Medium | Medium | Simple directional moves, particles |
A useful rule: use text prompts to discover a look, single-image conditioning to test a subject, and multi-image keyframing to shoot the sequence you have already designed. Restyling works when you already own live-action footage and want a different surface treatment without re-staging the scene.
Most professional pipelines combine at least two of these. A shot might be discovered through prompts, designed as anchors, generated through keyframing, and finished with a light restyle pass for texture.
Matching Models to Keyframe Jobs
Not every engine handles keyframes the same way. Some accept three images and hold identity beautifully but produce cautious, slow motion. Others move with flair and lose a face within a second. Treat model choice as casting, not as a single leaderboard.
Photoreal engines: identity and micro-texture
Photoreal pipelines excel when wardrobe, skin and lens character must survive a cut. They respond well to dense keyframing with tight spacing — anchors every half-second or less — because their strength is fidelity, not invention. If the engine supports multi-reference conditioning, supply a face reference, a costume reference and a lighting reference separately. Stacking them into one composite image usually degrades all three.
Watch for the "beautiful but static" failure. These models often reduce motion amplitude to protect identity. If your character barely moves, widen the gap between anchors and re-run rather than adding more frames.
Stylized engines: line and palette holds
Anime and illustration-oriented models are far less tolerant of soft references. Line weight, cel shading and a fixed palette must be shown, not merely described. Anchor frames should come from the same illustration pipeline, at the same resolution, with clean edges and no compression halos. A JPEG-artefacted reference will generate wobbling outlines that no prompt can repair.
The compensating advantage is speed. Stylized shots often render quickly enough that you can iterate on spacing rather than guessing, which makes them ideal for prototyping a workflow before applying it to expensive photoreal sequences.
Hybrid pipelines: mixing engines mid-sequence
Real productions mix. A common pattern is to generate hero shots on a high-fidelity engine, produce environment plates and crowd fillers on a faster model, and cut them together. The risk is tonal mismatch: different models have different motion signatures and contrast curves. Fix it in post with a shared grade, a subtle grain layer and matched motion blur, and keep the same keyframe references across engines so the composition at least rhymes.
Designing a Keyframe Set a Model Can Read
Keyframe quality determines output quality far more than prompt wording. Four variables matter most.
Spacing and easing
Spacing controls speed. Two anchors one second apart imply fast action; the same two anchors placed four seconds apart imply a slow drift, and the model will invent intermediate motion to fill the gap. Where you need acceleration, use uneven spacing — anchors clustered near the fast section, spread out during the slow section — because that rhythm communicates easing better than any adjective.
A practical default for dialogue and moderate action is an anchor every 0.7 to 1.5 seconds, with extra anchors at every direction change.
Lighting and lens continuity
Every anchor in a shot should share a light direction, colour temperature and focal length. If the start frame is a wide with soft window light and the end frame is a tight close-up with a hard key, the model receives contradictory instructions and produces a warped push-in. Lock lens and light per shot, then change them between shots where the story allows.
Reference hygiene
Checklist before an image becomes an anchor:
- Native resolution, never upscaled from a thumbnail
- Aspect ratio identical to the target output
- No watermark, caption text or interface overlays
- Clean silhouette against the background wherever possible
- Consistent colour space across the entire set
Small constants do heavy lifting too. Give the model the same distinguishing features in every anchor — a scar on the left cheek, a specific belt buckle, a chipped tooth. These act as anchors within anchors and measurably improve identity retention across interpolation.
Prompt syntax that supports rather than fights the anchors
Prompts still matter, but their role shifts from describing content to constraining behaviour. Keep them short and structural:
- State the camera: "slow dolly in, 35mm, eye level"
- State the motion verb: "turns", "reaches", "steps forward"
- State what must not change: "wardrobe, hairstyle and background unchanged"
- Avoid restating subject details already visible in the anchors
Contradictions between prompt and image cause warping. If the anchor shows a blue jacket, do not write "red jacket" because you plan to change it later — regenerate the anchor instead.
Where the engine supports them, add control layers: depth maps to hold spatial layout, pose skeletons to hold body mechanics, optical flow hints to hold direction of travel. One control layer that matches your anchors is worth more than three that fight them.
A Practical Workflow: From Storyboard to Locked Sequence
This is the loop that holds up under deadline pressure.
Break the shot down and set a keyframe budget
Write one sentence per shot describing action, camera and duration. Then decide how many anchors each shot needs. A locked-off interview needs two. A walking-and-turning shot needs four to six. Budget generously at first: you can always drop anchors later, while a missing anchor is far harder to diagnose than an extra one.
Generate and approve anchor frames
Create anchors as stills before touching video. Approve them as a contact sheet — lay the whole sequence side by side and check continuity across shots, not one image at a time. Most continuity errors are obvious in a contact sheet and invisible when you review clips in isolation.
Run interpolation passes and compare
Generate the shot with all approved anchors, then run a second pass using only the start and end anchors. Compare the two. If they diverge dramatically, your middle anchors are underspecified or contradictory. If they match closely, the shot is stable and safe to keep.
Verify with a flicker check
Play the clip at reduced speed and watch one region at a time: first the face, then the hands, then the background. Full-speed playback hides micro-flicker; slow, region-by-region review exposes it before an audience does.
Repair locally instead of regenerating everything
When one segment breaks, regenerate only the two anchors surrounding it at higher resolution, or patch it with a short interpolated insert. Full regeneration resets every seed and usually introduces new errors elsewhere in the shot.
Plan compute before you render long sequences
Draft at low resolution and short duration first, confirm motion and composition, then re-render the approved version at final quality. Cache your anchor images and control maps so iterations do not require regenerating references. Schedule long renders overnight, and keep a render log with model, prompt, seed and keyframe timings so any successful shot can be reproduced later.
Failure Modes and How to Fix Them
Face morphing mid-turn. Usually caused by anchors that show two different people, or by a turn so large that no anchor covers the profile. Add a three-quarter anchor and check that the nose and jawline match across frames.
Texture boiling or shimmering. Often a resolution mismatch: anchors at different pixel dimensions force the model to rescale internally. Normalize every anchor to identical dimensions and re-run.
Camera drifting off axis. Caused by anchors with inconsistent perspective. If the start frame is level and the end frame is tilted, the model will interpolate a roll. Fix the frames, not the prompt.
Colour shift between shots. Almost always a lighting continuity issue rather than a model issue. Match key light direction and colour temperature across anchors, then apply one grade across the finished sequence.
Hand and finger artefacts. Fingers moving across the body are the classic weak point. Add an anchor at the moment of contact with an object, keep hands visible in the frame, and prefer motions that avoid complex finger articulation where the story allows.
Motion slowdown or freeze. Photoreal engines protecting identity tend to dampen movement. Widen anchor spacing, simplify the action, or accept a slower performance and cut around it.
Warped geometry around the edges. Often triggered by control maps that contradict the anchors, such as a depth map drawn for a different framing. Rebuild the control plate from the current anchors.
Quality Control Checklist Before Export
Run this list on every locked shot:
- Face, hairline and eye colour identical in first and last frames
- Wardrobe colour sampled at three points across the shot, values within a narrow range
- Background elements unchanged in position and count
- No flicker on high-contrast edges such as railings or window frames
- Hands anatomically plausible in every frame where they are visible
- Camera path smooth, with no unintended roll or zoom
- Light direction consistent with the established scene
- Shot length matches the edit, with handles on both ends
- Framing composes into the following shot without a jump
- Render settings and seed recorded in the production log
Scaling Keyframing Across a Series or Campaign
Once a single sequence works, the temptation is to reuse the same anchors everywhere. Resist it for faces, embrace it for everything else.
Build a small library of locked references per production: hero character references, costume variations, vehicle plates, recurring locations. Store them with the exact prompts and control maps that produced them. This turns consistency from a creative struggle into an asset-management task.
Standardise three things across a series: output resolution, anchor spacing defaults, and one finishing grade. Sequences that differ only in content read as a coherent body of work; sequences that differ in resolution and colour feel assembled from different projects even when the storytelling is strong.
Finally, assign roles. One person approves anchors, one runs generation, one does continuity review. In small teams a single person can hold two roles, but never all three on the same shot — self-review is where continuity errors survive into the final cut.
FAQ
Does keyframing replace prompt writing? No. It reduces the burden on prompts, shifting them from describing content to constraining camera and motion behaviour. You still write prompts for every shot; they are just shorter and more structural.
How many keyframes is too many? More anchors are not automatically better. Past roughly one anchor per half-second, you constrain the model so tightly that motion becomes mechanical. Start sparse, add anchors only where continuity breaks.
Can I keyframe a talking head? Yes, and it is one of the easiest wins. Anchor the start pose, a mid-blink or small head turn, and the end pose. Avoid large head rotations, which force the model to invent too much facial geometry.
Why does the face change between anchors? Usually because the anchors themselves are inconsistent, or because the face occupies too few pixels. Increase the framing size of the face in the anchors, unify lighting, and add a dedicated face reference if the engine supports it.
Do I need expensive hardware? Not necessarily. Hosted engines handle rendering remotely. Local work becomes attractive when you iterate heavily on control maps and want full parameter access, in which case a mid-range GPU with ample VRAM is the practical floor.
Can I keyframe camera moves as well as subjects? Yes, and it is often more reliable than keyframing acting. Camera moves are geometric, so anchors that show a clear push-in or arc give the model a strong, unambiguous constraint.
How do I keyframe an action scene? Break the action into beats: wind-up, contact, follow-through. Anchor each beat rather than trying to describe the whole fight in one gap. Short gaps with clear poses beat long gaps with dramatic adjectives every time.
What about audio sync? Generate video first, then edit to the audio. If lip sync matters, keep anchors on phonetically neutral mouth shapes and use a dedicated sync pass rather than expecting the video model to match a waveform.
Is keyframing slower than prompt-only generation? Per shot, yes — you spend time producing and approving anchors. Across a sequence, it is usually faster, because you stop burning iterations on shots that drift and you can reproduce a successful setup instead of rediscovering it.
The workflow rewards planning over improvisation. Approve your anchors as a set, keep spacing rhythmic, lock light and lens per shot, and treat every generated clip as something to verify rather than something to hope for. Do that consistently and multi-image keyframing stops being a novelty control and becomes the backbone of a reliable generative video pipeline.
