
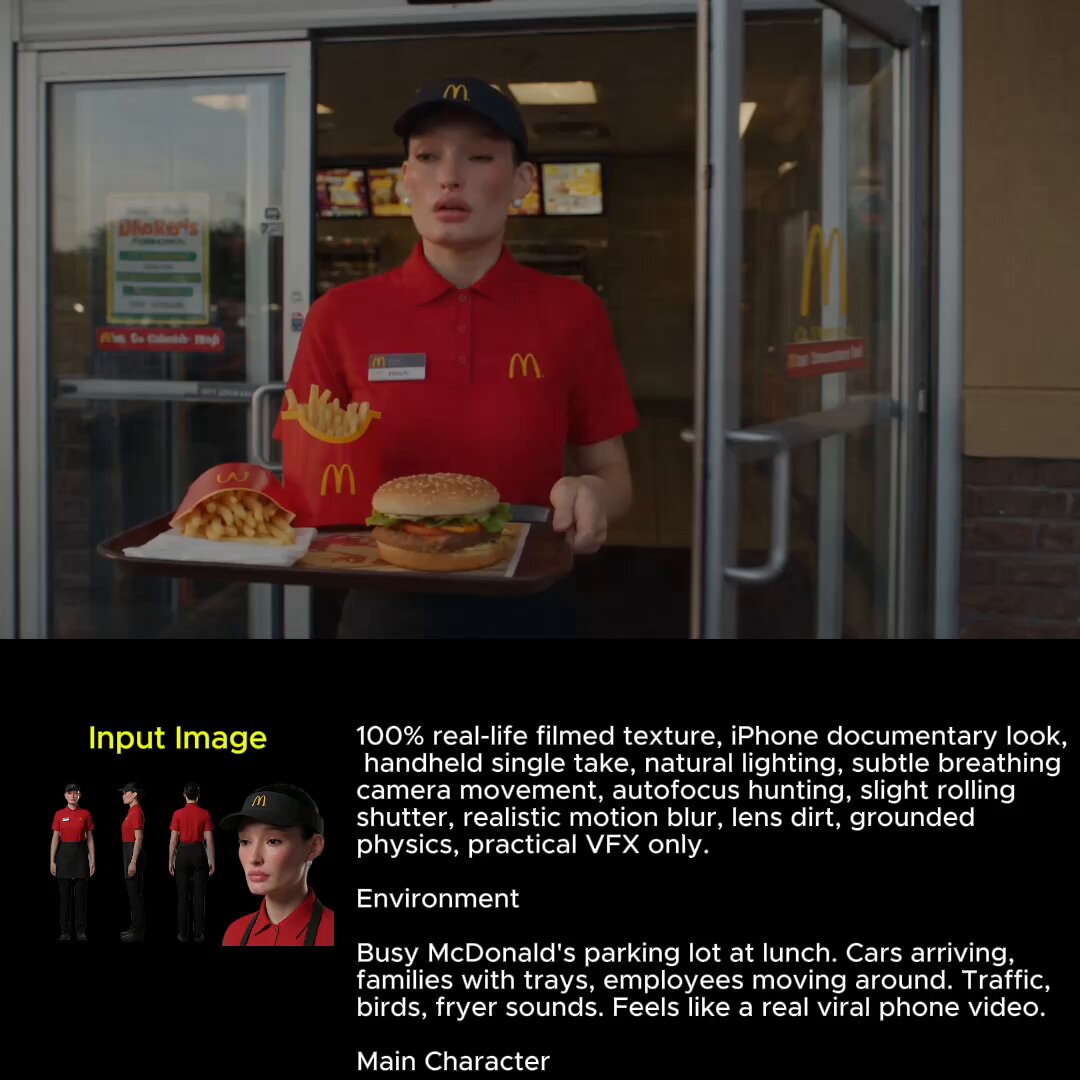
Character consistency is the difference between a short film that feels intentional and a slideshow of near-strangers wearing the same jacket. Anyone who has generated more than a handful of AI video clips has met the same wall: shot one is perfect, shot two has a wider jaw, shot three is suddenly lit from the opposite side, and shot four has a completely different nose. Multi-image referencing exists to solve exactly that problem. Instead of describing a person in words and hoping the model lands in the same neighborhood twice, you hand the model several photographs of the same person and let it treat identity as a visual constraint rather than a verbal suggestion.
This guide covers the whole workflow: how reference conditioning works under the hood, how to build a reference pack that survives motion, how to write prompts that do not fight your images, where to trade motion for stability, and how to catch drift before it reaches the edit. It is written for people making recurring-character content — narrative shorts, serialized social video, explainer series, branded spokespeople — where the same face has to appear in dozens of shots and still look like one person.
Why AI Video Characters Drift Between Shots
Most video models generate each clip as an independent sample. Even when you keep the same seed and prompt, small numerical differences in the starting noise, the motion schedule, and the frame count push the output toward slightly different points in the model's latent space. Those differences are invisible in a single frame but obvious across a cut. A model that has never seen your character before has to reconstruct a face from a text description, and text is a remarkably low-bandwidth channel for identity. "Woman in her thirties with dark wavy hair" describes a few million people.
The three kinds of drift you will actually notice
It helps to separate drift into categories, because each one has a different fix.
- Identity drift affects bone structure: eye spacing, jaw width, nose shape, hairline, ear position, skin tone. It is the most damaging and the most visible, and it is almost always fixed with better references rather than better prompts.
- Wardrobe and prop drift affects clothing, glasses, jewelry, bags, tools, and anything the character carries. It usually comes from prompts that describe the outfit differently across shots, or from reference images that show several outfits at once.
- Environmental continuity drift affects lighting direction, color grade, lens character, and background. A character with a stable face can still look wrong if the key light flips from screen-left to screen-right between shots, because viewers read that as a different location or a different time of day.
Why adding more description does not fix it
When the face is wrong, the instinct is to add adjectives: sharper cheekbones, smaller eyes, thinner lips, freckles. This usually makes things worse. Descriptors compete with the reference images for influence over the output, and the model resolves that competition unpredictably. Long identity paragraphs also tend to leak into motion and lighting, producing stiff, over-posed clips. The rule that saves the most time is simple: identity belongs in images, intent belongs in text.
How Multi-Image Reference Systems Actually Work
Reference conditioning injects your images into the generation pipeline as extra visual tokens alongside the text tokens, or as a separate identity embedding that is blended into the denoising process. Different tools wire this up differently — some use an adapter trained specifically for identity preservation, some use a reference-only control signal, some pass reference frames as extra context to a video transformer — but the practical behavior is similar: the model gets pixel-level evidence about what the person looks like, and it tries to reconcile that evidence with your prompt and your motion.
What the model sees when you upload three images
Your images are not treated as three separate characters. They are treated as samples of one distribution. If all three show the same person in the same clothes under the same light, the model tightens its estimate of that person and produces strong consistency. If one image is a studio headshot, one is a candid at golden hour, and one shows a different hairstyle, the model averages them — and the average is a face that resembles nobody. This is the single most common reason people conclude that multi-image referencing "does not work."
Identity, style, and lighting references are different jobs
Modern pipelines let you attach a role to each reference. Keep them explicit:
- Identity references should be clean, neutral, and well lit. They carry face structure and skin tone.
- Style references carry the look — film stock, palette, lens treatment, illustration style. They should not be portraits of your character if you can avoid it.
- Pose or structure references carry body position and composition, usually through depth or edge conditioning rather than appearance.
Mixing roles in a single image is possible, but it makes debugging nearly impossible. If your character looks right but the grade is wrong, you want to know which input to change.
The angle budget matters more than the image count
Five near-identical front-facing selfies are worth less than three images that actually bracket the head. A reference pack that covers front, three-quarter, and profile gives the model enough geometric information to rotate a face; a pack of five frontal shots leaves it guessing every time the camera moves. Depth information enters the model through variation, not repetition.
Building a Character Reference Pack
A reference pack is a small, curated set of images that describes one person completely. Treat it as an asset, version it, and reuse it across every project that features the character. Once it works, it becomes the most valuable file in your production folder.
The six-shot minimum
For a character who will appear in dialogue, close-ups, and full-body shots, aim for at least these six:
- Neutral front, chest-up. Even light, no harsh shadows, eyes to camera, relaxed expression.
- Three-quarter left. Turns the head about 45 degrees and reveals cheekbone and jaw structure.
- Three-quarter right. The mirror of the previous shot; symmetry errors are a common failure mode.
- Profile. Essential for any sequence with a head turn.
- Slight low angle. Shows the jaw and neck relationship, which models tend to invent when unguided.
- Full body, neutral pose. Locks proportions, height, and wardrobe silhouette.
If the character speaks on camera, add a seventh: mouth slightly open, mid-speech. Lip-sync pipelines behave better when the reference set includes an open-mouth frame.
Keep the pack internally consistent
Every image in the pack should share framing conventions, wardrobe, lighting temperature, and color grade. Shoot or generate the pack in one session if you can. The moment you mix a warm indoor shot with a cool outdoor shot, you are asking the model to decide which skin tone is correct — and it will decide differently on different runs.
File preparation rules that save hours
- Use square or 4:5 crops for identity references, 1024 to 2048 pixels on the long edge.
- Avoid heavy beauty filters, skin smoothing, or strong vignettes; these are read as identity features.
- Do not include other people, pets, or busy backgrounds in an identity reference.
- Keep lighting flat and even. Dramatic lighting in a reference becomes a permanent feature of the character.
- Crop tight enough that the face occupies a meaningful share of the frame; a full-body photo downscaled to a face is nearly useless as an identity reference.
Writing Prompts That Hold an Identity Steady
Once the reference pack is solid, the prompt has one job: describe what changes. Everything that stays the same should stay out of the text.
Use a locked descriptor block
Write a short block — three to five clauses — that describes the character in neutral terms, and paste it verbatim into every shot prompt. Something like: "Character A: woman, late thirties, straight dark hair to the collarbone, olive skin, thin gold necklace, charcoal blazer." The block is not there to teach the model what the character looks like; it is there to stop the model from inventing contradictions. Consistency in wording reduces variance between runs, and it gives you a single place to edit when the character changes.
Change exactly one variable per shot
Each prompt should introduce a camera change, a motion change, or an environment change — not all three at once. When a shot fails, you want to know which variable caused it. A shot list that reads "shot 12: three-quarter, slow push in, same cafe, same light" is a shot list you can actually debug.
What to leave out
Remove emotion words that conflict with your reference expressions, style words that fight your style reference, and any adjective that describes the face. If the render is too flat, fix it with a lighting clause, not with "more beautiful." If the character looks too young, adjust the age in the descriptor block rather than adding "mature features," which models interpret unpredictably.
A Step-by-Step Workflow From Reference Pack to Finished Scene
- Lock the descriptor block. Write it once, save it in a text file, and stop editing it mid-project.
- Assemble the reference pack. Six images minimum, same wardrobe, same light, no other people.
- Test at low resolution. Generate one four-second shot with the pack. Do not start a sequence until a single shot holds.
- Grade against a checklist. Face structure, hairline, skin tone, wardrobe, lighting direction, lens feel. Note which item fails.
- Lock your seed and motion settings. Keep the seed constant for the character's first appearance, then vary it deliberately when the environment changes significantly.
- Build the sequence shot by shot. Generate in narrative order, so you can compare each new shot to the previous one rather than to an abstract ideal.
- Make a contact sheet. Pull one frame from each clip and lay them side by side. Drift that is invisible in motion becomes obvious in a grid.
- Repair locally, not globally. If one shot drifts, re-render that shot with a stronger identity reference weight rather than regenerating the whole scene.
- Finish in the edit. Cuts, sound, and pacing hide minor inconsistencies; a hard cut on a moving frame hides more than a slow dissolve on a static one.
Motion Control Versus Identity Stability
Identity strength and motion strength pull against each other. The more you constrain the model to match a reference, the less freedom it has to move, and the stiffer the clip looks. The more motion you request, the more the model relies on its own priors, and the more the face drifts.
| Shot type | Identity weight | Motion setting | Why |
|---|---|---|---|
| Talking head close-up | High | Low | Face fills the frame; drift is instantly visible |
| Walking medium shot | Medium | Medium | Body motion carries the shot, face is smaller |
| Action or chase | Low to medium | High | Speed and blur mask detail; prioritize energy |
| Establishing wide shot | Low | High | Character is a silhouette; environment matters more |
The practical technique is to render the same shot twice at different identity weights and compare. Most pipelines let you adjust how strongly references influence the output; a value too low produces a stranger, a value too high produces a mannequin with a locked stare. The sweet spot is usually the lowest value that still reads as your character.
Comparing Approaches: Single Image, Multi-Image, and Trained Adapters
Single reference image
Fast and cheap for one-off clips, but it gives the model a single sample of the person, which means every change in angle or lighting is an interpolation it has no evidence for. Fine for a five-second social clip, unreliable across a ten-shot narrative.
Multi-image referencing
The default choice for series work. It requires preparation — a real reference pack, consistent wardrobe, controlled lighting — but it needs no training and adapts instantly when you change the character's outfit. It is also the most forgiving when you switch models, because your asset is images rather than a weight file.
A trained adapter or custom identity model
Training a small adapter on twenty to forty images of one character produces the strongest identity lock available, and it is worth the effort if the character will anchor an entire series or a client brand. The tradeoff is setup cost, brittleness across base-model updates, and a tendency to bake in the reference lighting.
Post-production face replacement
Swapping a stable face onto generated footage in post is a legitimate fallback for short shots, but it struggles with extreme angles, heavy motion blur, and occlusion. Use it as a repair tool for a handful of failed shots, not as the backbone of a workflow.
Decision criteria in one line: one clip, use a single image; a scene or series, use multi-image referencing; a franchise or a paid client deliverable, invest in a trained adapter.
Troubleshooting the Most Common Failures
The face changes at every cut. Your reference pack is probably inconsistent, or your descriptor block keeps changing. Freeze the wardrobe and lighting in the pack, and paste the same block into every prompt.
Wardrobe morphs mid-clip. Dense fabric detail plus strong motion is a hard combination. Simplify the garment, reduce motion, or add a wardrobe reference image that shows the full outfit.
Lighting flips between shots. This is environmental drift, not identity drift. Add a lighting clause to every prompt — key light from screen left, soft, 4300K — and reject any shot that breaks it, no matter how good the face is.
The character looks plastic or over-smoothed. Overly strong identity weight combined with a reference set full of retouched images. Add one unretouched, slightly imperfect reference and lower the identity weight.
Background texture leaks onto the face. Your identity reference has a busy background. Crop or cut out the subject before using the image as a reference.
Motion stutters or freezes. You have over-constrained the model. Reduce identity weight, shorten the clip, or split the action into two shots.
The character reads as younger or older than intended. Age is heavily influenced by lighting and lens choice. A wide lens close to the face exaggerates features; a longer lens flattens them. Adjust the camera before editing the descriptor block.
Quality Control: Catching Drift Before the Edit
Review discipline is what separates a channel that looks professional from one that looks like a test folder. Build three habits.
The first is the contact sheet. Export one frame per shot, place them in a grid, and look at them together. Your eye picks up a shifted hairline or a changed jaw far faster in a grid than in sequence.
The second is the double-speed pass. Watch the whole sequence at 2x with audio muted. Drift that hides in slow playback reads as a flicker or a sudden change in face shape at speed. Then watch again at normal speed and check whether the cut points feel like the same person moving through a continuous space.
The third is a written log. Note the seed, identity weight, reference pack version, and prompt block for every shot you keep. When a shot three days later does not match, you will know exactly which variable to reproduce. A simple spreadsheet beats memory every time.
FAQ
How many reference images do I actually need? Three good, varied images beat ten redundant ones, but six to eight covering front, both three-quarters, profile, low angle, and full body gives you real robustness. More than twelve usually adds inconsistency rather than detail.
Can I mix real photos and AI-generated images in one pack? Yes, as long as they are visually consistent in lighting, wardrobe, and grade. If your generated images have a distinct look, they will pull the character toward that look.
Do I need a different pack for each outfit? No. Keep one core identity pack and add a wardrobe-specific reference for scenes where the outfit matters. Identity lives in the face pack; the outfit is a separate constraint.
Why does my character look great in stills but wrong in motion? Stills let you cherry-pick the best frame. Motion exposes decisions the model makes over time. Test any new pack with a four-second clip, not a still image.
Should I keep the same seed across a whole project? Keep it for consecutive shots in the same location, then vary it when the scene changes. A constant seed across wildly different environments can lock in an unwanted lighting bias.
What is the fastest fix when one shot drifts? Re-render that single shot with a slightly higher identity weight and a simplified prompt. Regenerating everything else costs time and risks introducing new drift in shots that were already fine.
Does multi-image referencing work for stylized or animated characters? Yes, and it often works better than for photoreal humans, because illustrated characters have fewer noisy details. Use art in one consistent style, and avoid mixing sketch, painterly, and 3D renders in the same pack.
The core principle is worth repeating once more: images carry identity, text carries intent, and consistency comes from changing one thing at a time. A creator who builds a proper reference pack, locks a descriptor block, and reviews with a contact sheet will out-produce someone with better prompts and worse assets every single time.
