
Why a Single Model Rarely Carries a Whole Video
Ask any working director what they actually want from generative video and you will hear the same three things: control, repeatability, and speed. No single model delivers all three across an entire project. That is not a flaw in any particular tool — it is the nature of the field. Each model is trained on different data, tuned with different objectives, and optimized for different kinds of motion. One produces gorgeous landscapes but melts faces during dialogue. Another nails lip sync but renders camera moves like a slideshow. A third generates beautiful anime interiors but refuses to hold a consistent character across cuts.
The practical answer is not to wait for a mythical universal model. It is to treat generative video the way a post house treats color, sound, and VFX: as a set of specialized stages, each handled by the tool best suited to it. A multi-model workflow is simply an assembly line built from models instead of departments.
This guide walks through the whole process: how to map model strengths to production roles, how to prepare a project before you generate a single frame, how to solve the consistency problem that sinks most AI videos, how to handle audio, and how to troubleshoot the failure modes you will inevitably hit.
Mapping Model Strengths to Production Roles
The four lanes
A useful way to organize a model library is by lane, not by brand or release order. Four lanes cover almost every production need:
Hero lane. Models that deliver cinematic realism, believable physics, and fine camera control. These are your money shots: the slow push-in on a character's face, the sweeping establishing shot, the product rotation that has to look like it came off a real camera. Typical candidates include high-fidelity text-to-video and image-to-video systems such as Runway's Gen family, Luma Ray, Kling, Veo, and Sora-class models. They are slower and more expensive per second, so you use them sparingly and deliberately.
Motion lane. Models tuned for bodies in motion — running, dancing, fighting, driving. These tend to handle limb articulation and momentum better than generalist systems, often at the cost of background detail. If your scene is essentially choreography, this lane matters more than photoreal skin texture.
Style lane. Models with a strong aesthetic bias: illustration, anime, graphic novel, painterly, retro film emulation. Wan, Hailuo, and various diffusion-based image-to-video pipelines live here. Their bias is a feature. Instead of fighting a realistic model into a stylized look, you pick a model that already thinks in that visual language.
Utility lane. Everything that repairs, extends, or enhances footage rather than generating it: upscalers, frame interpolators, rotoscoping and matting tools, relighting, face restoration, lip sync, background removal, and video-to-video restyling. Utility tools are force multipliers. A mediocre generation can become usable after a careful pass through this lane.
A selection matrix you can reuse
When you evaluate a candidate model for a specific scene, score it on these axes rather than on demo reels:
| Criteria | What to test |
|---|---|
| Prompt adherence | Does a 40-word prompt land every element, or does it quietly drop objects? |
| Temporal coherence | Do textures, hair, and fabric stay stable across the full clip? |
| Motion realism | Do limbs move with weight, or do they drift and smear? |
| Camera control | Can you specify dolly, pan, crane, and handheld with predictable results? |
| Image-to-video fidelity | How faithfully does it preserve a supplied reference frame? |
| Duration and aspect ratio | Does it support the runtime and frame you actually need? |
| Determinism | Does the same seed and prompt produce a comparable result twice? |
| Iteration latency | How long until you see a rough take you can judge? |
| Cost per usable second | Not cost per generation — cost per second that survives the edit. |
That last row is the one people forget. A cheap model that produces one usable second in ten is more expensive than a premium model that produces eight in ten. Track usable output, not raw output.
Pre-Production Before You Generate a Single Frame
Shot list and duration budget
Generative video punishes improvisation. Before you open any tool, write a shot list with a target duration for each shot. Be brutal about it: five seconds is often enough for a cut, and asking a model for twelve seconds of coherent action is how you get melting backgrounds.
A workable shot list includes, per row: shot number, description, duration, camera move, subject action, dialogue or VO, and which lane the shot belongs to. This single spreadsheet prevents the most common project failure — generating beautiful clips that do not cut together.
The prompt bible
A prompt bible is a living document containing your reusable descriptions: character appearance (age, build, hair, wardrobe, distinguishing marks), environment descriptions, lighting setups, lens and film stock language, and color palette. Every prompt in the project is assembled from these blocks plus shot-specific action.
Why bother? Because consistency across models depends far more on consistent language than on consistent tools. If your protagonist is described as "a wiry man in his late forties, salt-and-pepper stubble, charcoal wool coat, faint scar over the left brow" in every prompt, three different models will produce three recognizably related people. If you describe him differently each time, even a single model will drift.
The reference kit
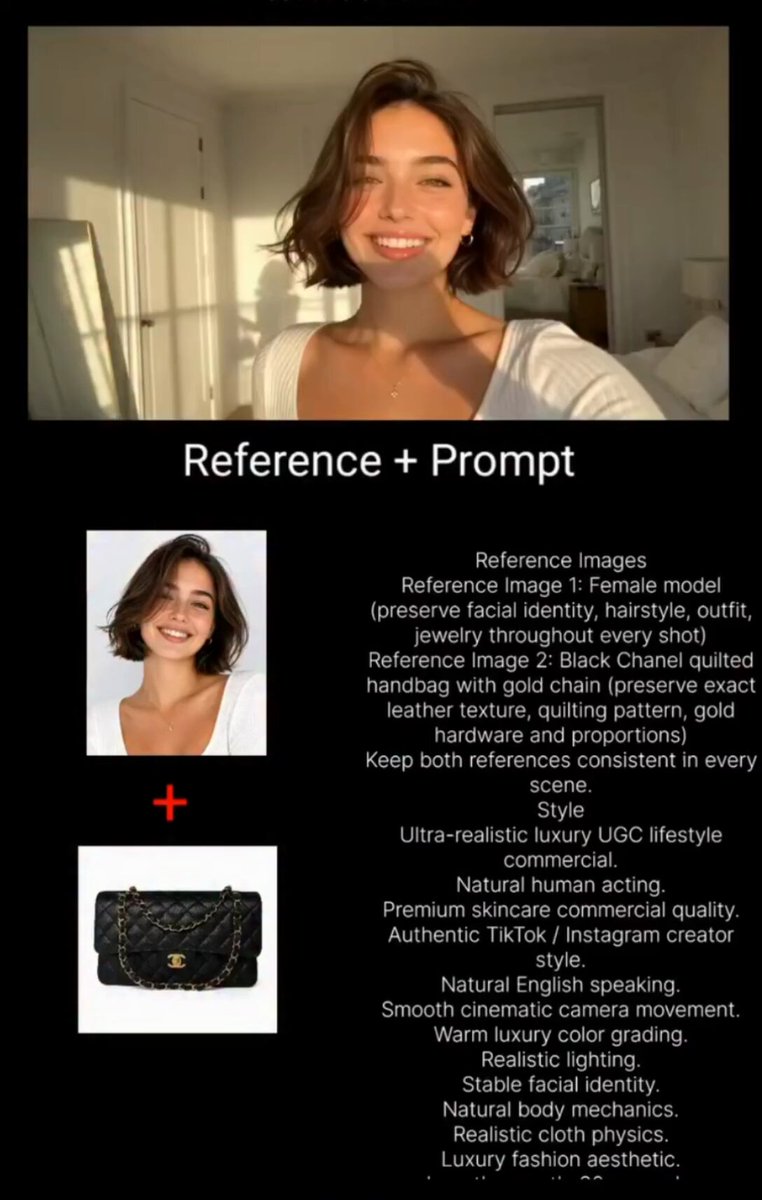
Collect stills before you generate motion. A strong reference kit contains character sheets (front, three-quarter, profile), style frames, a lighting reference, a motion reference (a short video of the camera move you want), and a color palette. Image-to-video models respond dramatically better to a reference frame than text-to-video models respond to description alone. Feeding a locked character image into a motion model is the single highest-leverage consistency trick available.
Consistency Is the Real Bottleneck
Character continuity tactics
Character drift happens because each generation reinterprets the description. Counter it with these tactics, roughly in order of effectiveness:
- Lock a character portrait and use image-to-video for every shot the character appears in.
- Reuse identical description blocks, word for word, across prompts.
- Keep wardrobe and hair dead simple. Patterns, jewelry, and complex hairstyles drift fastest.
- Generate dialogue coverage from a single master shot where possible, then cut between angles of the same take rather than generating multiple independent performances.
- Let faces be small. Wide and medium shots hide identity drift that close-ups expose.
- Reserve the best model in your library for the two or three shots where the face is the point.
Style lock and color language
Style drift is subtler than character drift and more damaging, because audiences read it as amateurism. Attack it three ways. First, add a style anchor phrase to every prompt — the same phrase, in the same position, every time. Second, generate a style frame and use it as the first frame reference for stylized scenes. Third, unify in post: a single color grade, film grain pass, and lens vignette applied to every shot will make footage from four different models feel like one film.
Space, scale, and camera vocabulary
Models interpret camera language inconsistently. "Dolly in" in one tool reads as a zoom, in another as a push. Build a private glossary: for each model, note the exact phrasing that produces a slow push, a whip pan, a crane up, a handheld drift. Keep a short test clip for each. After a few projects you will have a translation table that saves hours.
The Pipeline in Practice: From Script to First Assembly
Pass one — boarding and cheap tests
Generate low-cost, short tests to validate look, framing, and character. Do not chase polish. The goal is confidence that the scene reads. Typical spend: a few seconds per shot, lowest-fidelity settings, thumbnails only.
Pass two — hero generation
For approved boards, generate hero shots in the premium lane. Expect three to eight attempts per shot. Save every seed and prompt that produced a usable take; reproducibility is worth more than you think when a client asks for a one-second change later.
Pass three — coverage and inserts
Generate the connective tissue: hands on objects, footsteps, doors closing, environmental cutaways. These are cheap, fast, and they buy enormous flexibility in the edit. Coverage is where the motion lane and utility lane earn their keep.
Pass four — assembly and repair
Bring everything into your editor. Cut for rhythm first, ignoring imperfections. Then list the defects — flicker, warped hands, mismatched color, a face that turns strange on frame 40 — and route each defect to a specific fix: regenerate, crop, replace with a cutaway, retime, or repair in the utility lane. Not every flaw needs a new generation.
Audio Changes Everything
Silent AI footage tests beautifully and dies in public. Three audio layers matter:
Voice. Record real voice-over wherever possible. Synthesized voice can work for narration and internal monologue, but for character dialogue, a human performance gives you timing, breath, and subtext that no model currently supplies. If you must synthesize, generate several takes and cut between them like a real performance.
Lip sync. Match mouth movement to audio in a dedicated lip-sync pass rather than hoping a video model gets it right in the first generation. This is a utility-lane job.
Music and sound design. Ambience and foley are what make generated footage feel shot rather than rendered. Add room tone to every scene, layer footsteps and cloth movement under dialogue, and use music to cover hard cuts between shots generated by different models. A well-placed transition and a sound effect will hide a continuity error that no amount of regeneration would fix.
Troubleshooting: Common Failure Modes
| Symptom | Likely cause | Fix |
|---|---|---|
| Faces morph mid-clip | Long duration, high motion, weak reference | Shorten the shot, use image-to-video, cut before the morph |
| Texture flicker | Temporal instability in the model | Interpolate frames, add grain, regenerate at lower motion intensity |
| Limbs smear or duplicate | Complex action in a generalist model | Switch to the motion lane or reduce action complexity |
| Camera move ignored | Model-specific vocabulary mismatch | Rewrite using your glossary phrasing, or move the camera in post |
| Everything looks plastic | Over-smoothing in generation or upscale | Add grain, reduce upscale strength, grade with film emulation |
| Prompt elements missing | Prompt too long or too abstract | Cut to 30–40 words, lead with subject and action, drop adjectives |
| Shots do not cut together | Inconsistent lens, palette, or pace | Regrade everything, standardize shot durations, unify transitions |
| Text and signage garbled | Known limitation in most models | Avoid legible text on screen; add it in post |
Time, Team, and Effort Tiers
Solo creator tier
One or two models, one utility stack. Choose a strong image-to-video model for anything with a character, and a fast cheap model for scenery and B-roll. Keep shots under five seconds, avoid dialogue, and lean on music and narration. Realistic output: a two-minute piece in a working week.
Small studio tier
Three to five models across all four lanes, plus a dedicated post pass. You can attempt dialogue scenes, recurring characters, and stylized sequences. Build a prompt bible and a reference library, and assign one person to own consistency. Realistic output: a five-minute narrative in three to five weeks.
Agency and broadcast tier
A curated model library, documented testing, and a formal QC checklist. Every shot is logged with model, seed, prompt, and post steps. Deliverables are graded, mixed, and archived. This tier is less about generation skill and more about process discipline.
Delivery, Versioning, and Archive
Name every file with the same convention: project, sequence, shot, version, and a short descriptor. Keep the raw generation alongside the graded result. Store the prompt and seed for every accepted shot in a shot log — when a client requests a small change six weeks later, that log is the difference between a two-hour fix and a two-day rebuild.
Deliver in the format the destination requires, but archive a high-bitrate master plus a textless version. The textless master is invaluable for re-editing, localization, and social cuts at different aspect ratios. If your project is destined for several platforms, generate in the widest frame you need and protect the center of the composition so vertical crops remain viable.
FAQ
How many models do I actually need?
Fewer than you think. Most working creators settle on two generators — one premium, one fast — plus a small utility stack for upscaling, interpolation, and lip sync. Add a third generator only when you repeatedly hit a limitation the first two cannot solve.
Is text-to-video or image-to-video better?
Image-to-video is more controllable and far more consistent, at the cost of preparing reference frames. Use it for anything involving characters, products, or recurring locations. Use text-to-video for establishing scenery, abstract sequences, and fast ideation.
How do I keep a character's face stable across shots?
Lock a portrait, feed it into every generation, repeat the same appearance description verbatim, keep the character in medium or wide shots, and save your best model for the close-ups. Expect to regenerate more than you would like.
What resolution should I generate at?
Generate at the native resolution where the model performs best rather than the largest number it advertises. Upscale in a dedicated pass afterwards. Generating at an overextended resolution usually produces softer results than generating small and upscaling well.
How do I handle dialogue scenes?
Keep coverage minimal: one master, one or two singles. Generate silent, sync audio in post, use a lip-sync pass for close-ups, and cut away during the most complex mouth movement. Audiences forgive a lot when the performance is good.
Can AI-generated footage pass quality control for distribution?
Yes, with process. The blockers are usually aliasing, frame-rate inconsistency, audio mismatches, and unstable textures — all fixable with interpolation, a proper grade, and a careful audio mix. Build a QC checklist and run every deliverable through it, not just the showcase shots.
Where This Leaves You
The multi-model approach is not a workaround for immature technology. It is the design pattern that mature generative production actually requires: specialize the tools, standardize the language, integrate at the edit, and finish in post. The creators producing convincing AI video today are not the ones with the longest model list. They are the ones with a shot list, a prompt bible, a reference kit, a shot log, and the discipline to route every problem to the cheapest stage that can solve it. Build that system once, and the next project gets dramatically faster.
